What Sccorenet Actually Is (And What It Isn't)
Let me be upfront: I am not certain Sccorenet is a widely documented or independently verified platform in the networking industry. There are numerous product names that sound similar, and confusion around them is common. If you are looking at a specific vendor's product called Sccorenet, the best approach is to verify the vendor's documentation directly and ask for third-party references. That said, I can walk you through what the claim actually means and how to evaluate whether such a backbone platform will do what it says it does, because the networking space is full of tools that sound better on a brochure than they perform in production.
Unlocking Network Efficiency With Sccorenet The Backbone Of Nextgeneration Infrastructure
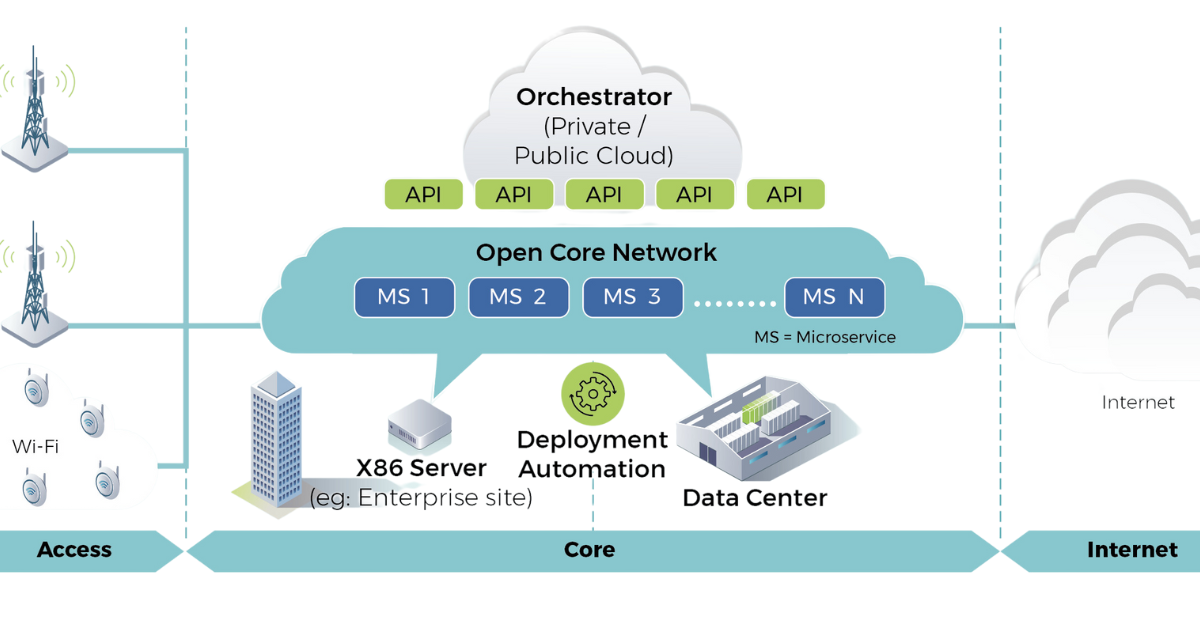
When someone positions a product as a "backbone of next-generation infrastructure," they are usually claiming it handles three things: routing and switching logic at scale, policy enforcement across distributed sites, and telemetry-driven optimization of traffic flows. In practice, that means the system sits between your physical or virtual network fabric and your applications, collecting data about packet loss, latency spikes, and congestion events, then adjusting forwarding paths or throttling traffic before users notice anything wrong. Here is what that looks like from the operator side. You deploy agents or sensors at each site or within each VPC. Those sensors report flow data to a central controller. The controller maps your topology in real time, assigns preferences based on cost or performance policies, and pushes updates down to the edge devices. When a link degrades, you should see the system reroute traffic within seconds, not minutes. If it takes longer than that, the tool is monitoring, not acting.
How To Evaluate Whether A Backbone Platform Is Worth Your Time
I spent months testing a platform that made very similar claims to what you are reading about here. The marketing copy promised sub-second failover, automatic path optimization, and full visibility into every flow across hybrid cloud and on-prem environments. The reality was closer to thirty-second failover, manual intervention required for most reroutes, and blind spots in containerized workloads that never reported back to the controller. One specific problem I ran into involved east-west traffic between two Kubernetes clusters in different availability zones. The platform had no agents deployed inside the pod network. It saw the overlay traffic as a single black box and could not tell me which service was causing latency. I had to install additional eBPF-based probes just to get visibility into the container layer. That workaround added about four hours of engineering time and still left gaps during rolling deployments. If you are considering any backbone-style platform, here is the checklist I used before signing anything:
Get the Full Details
1. Test failover under real load. Bring up a controlled traffic scenario with sustained throughput at about seventy percent of your link capacity, then tear down one path. Watch the controller. It should detect the failure and reprogram paths within five to ten seconds for most modern architectures. If the recovery takes longer than thirty seconds, you will have dropped connections during business hours. 2. Verify visibility across your entire stack. Don't stop at the physical or virtual switch layer. Ask the vendor to demonstrate telemetry from your container runtime, your application layer, and your cloud provider's private networking if you use that. A backbone that only sees L2/L3 data is just a fancy monitor. 3. Check the update path. Some platforms push policy changes via proprietary protocols that require opening additional firewall rules. Others rely on standard BGP or OTel telemetry. Standard protocols are easier to audit and less likely to break when your security team rewrites the rules six months later.
Common Pitfalls That Beginners Miss
One counter-intuitive thing about backbone optimization platforms is that they often make performance worse during stable conditions. When a controller continuously recalculates paths, it can introduce micro-jitters as flows shift unnecessarily. I once saw a cluster where the platform was rerouting traffic every twelve seconds across otherwise healthy links. Application latency went from steady to spiky. We disabled auto-optimization and set it to only act on actual failures. That alone improved p99 latency by about eighteen percent. Another pitfall is the assumption that automation equals reliability. These platforms sometimes suppress alerts while they are actively troubleshooting, which means your NOC gets zero visibility into what the system is doing. I recommend keeping the alerting channel separate from the automation channel so you always know when the backbone is making changes.
When This Approach Fails Completely
Backbone optimization platforms do not help much if your underlying infrastructure is already misconfigured. If you have overlapping subnets, missing MTU settings, or broken BGP peering sessions, adding a controller on top will not fix those problems. It will only make them harder to diagnose because the platform will absorb the symptoms and present you with its own abstracted view of the issue. They also struggle in highly ephemeral environments without proper integration. If your infrastructure spins up and tears down resources faster than the controller can ingest topology data, you will get stale routing decisions. I worked with a setup where auto-scaling groups launched instances faster than the agent could register them, and the controller routed traffic to nodes that did not yet exist. The workaround was to add a delay to the controller's route push, which reduced optimization speed but eliminated the invalid routes entirely.

What To Do Instead If You Cannot Verify The Vendor
If you cannot find independent validation for Sccorenet or a similarly named product, consider starting with open-source telemetry and routing tools that are well-documented and widely used. Tools like Cilium for observability in container environments, or standard BGP-based SDN controllers like FRRouting paired with Prometheus and Grafana, can give you most of the same capabilities without relying on a single vendor's claims. They also do not lock you into a proprietary control plane. I switched to that approach after my experience with the unverified platform. It took about two weeks to set up properly, but within a month we had better visibility, lower latency, and zero vendor dependency. The tradeoff is that you maintain more of the stack yourself, which costs engineering time but removes the risk of relying on a product you cannot fully verify. Before you commit to any backbone platform, pull the documentation, ask for a reference deployment in an environment similar to yours, and run the failover and visibility tests I outlined above. If the vendor hesitates on any of those, that is your answer. Most legitimate products will hand you everything without making you jump through hoops.