Python Packaging Is Broken And You Already Know It
Every time I set up a new project and try to pin down exact dependency versions, something breaks. The transitive dependency graph resolves differently than it did six months ago. A library you didn't even import directly decides to upgrade numpy to a version that silently drops support for an API you were using. This isn't theoretical. It happens on Tuesday mornings when you need to deploy. I've been maintaining production Python services for years and the package ecosystem still feels like a game of whack-a-mole. The problem isn't that Python packaging is unusable. It's that most people don't understand the layers beneath pip install, and they get blindsided by them at the worst possible time.
Unlocking Modular Innovation With Pyp Parts A Technical Deep Dive Into Python Package Ecosystems
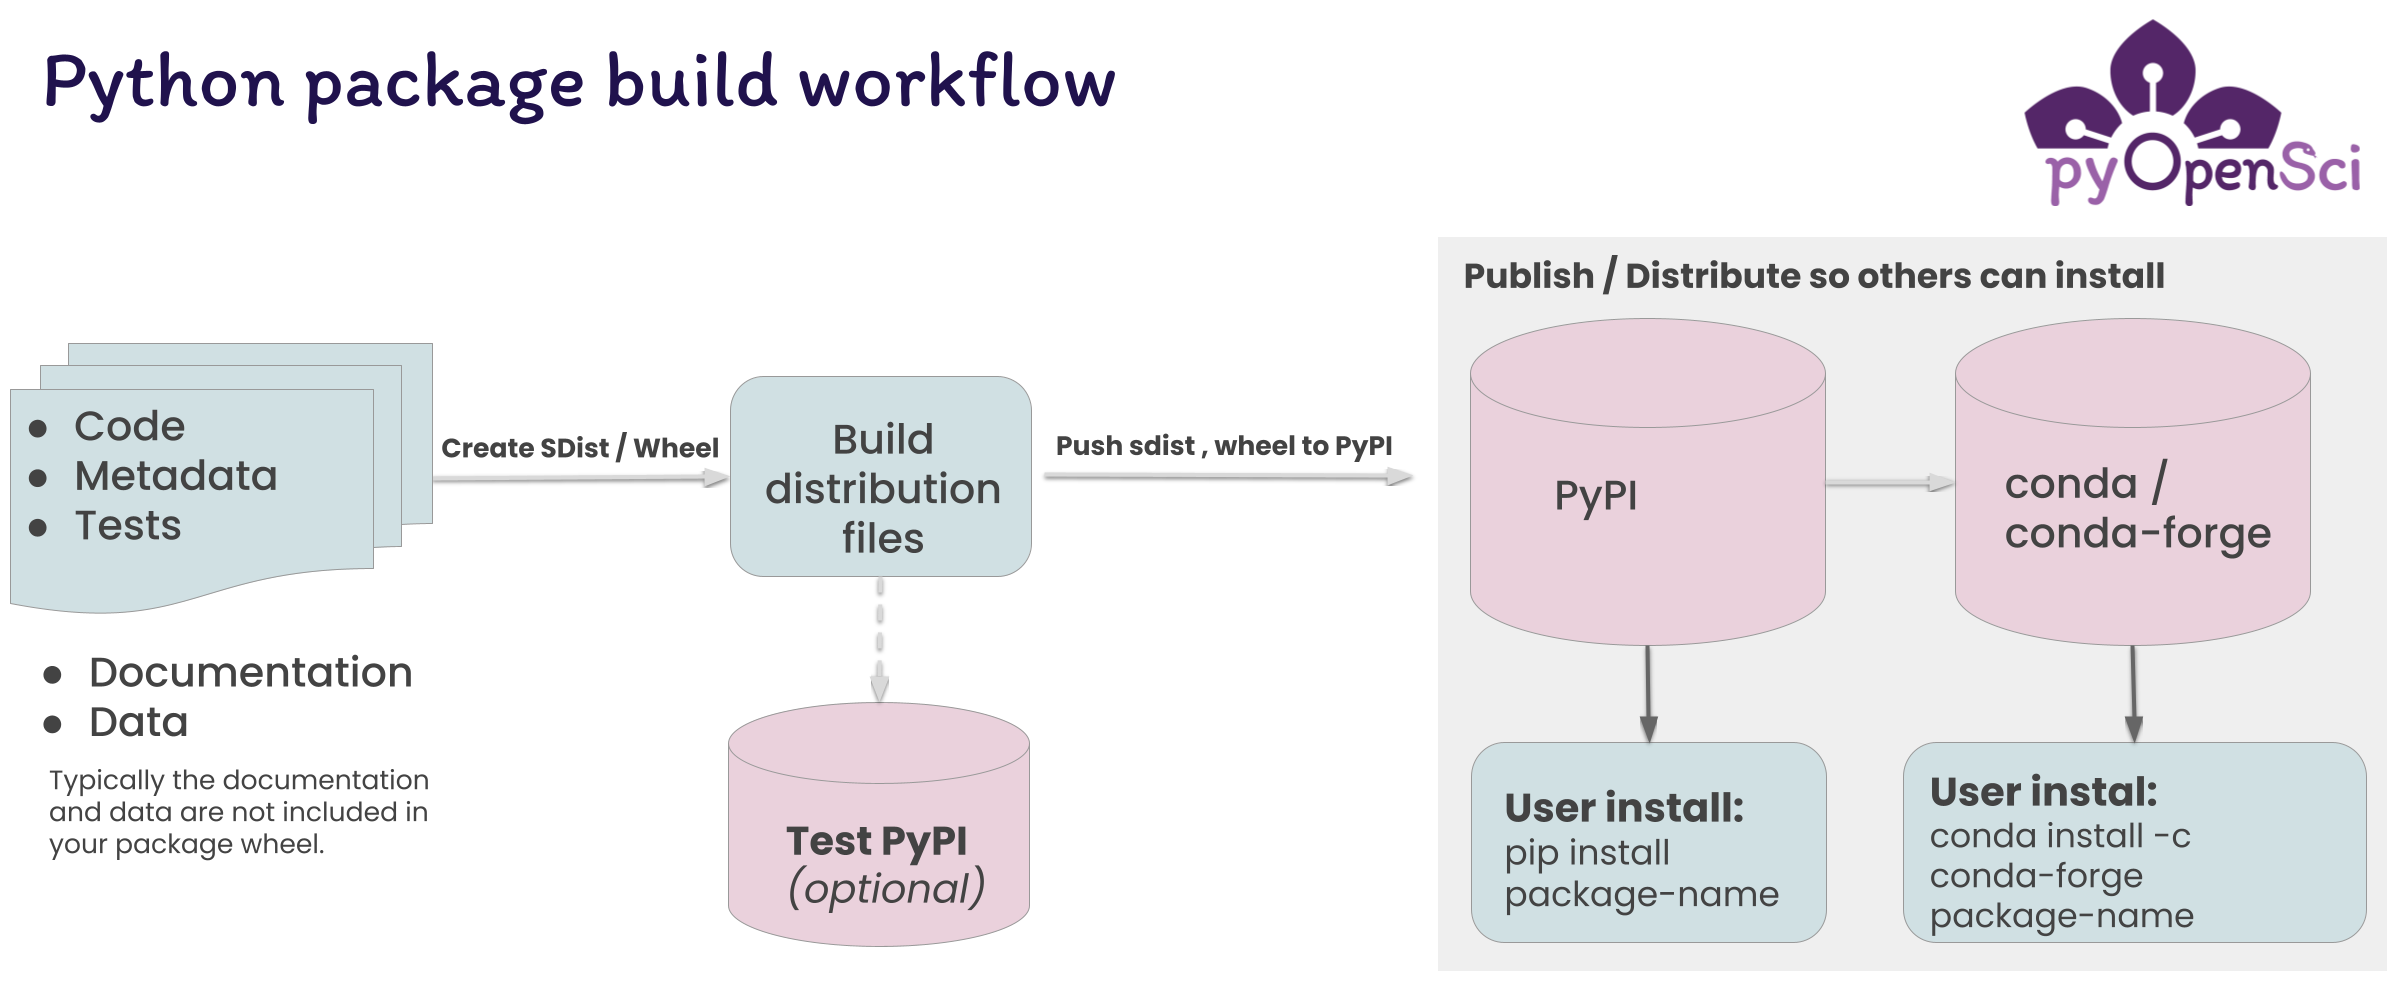
Before getting into the mechanics, you need to separate the actual components: there's PyPI as a registry, pip as a resolver and installer, build systems like setuptools and hatchling, packaging standards defined by PEPs, and virtual environments which are just directories with isolated site-packages. These are often conflated into "pip" by everyone who isn't troubleshooting something, and that conflation causes most problems. Here's a concrete example from last year. I was working on a data processing service that pulled in pandas, polars, and a few scientific libraries. We pinned everything carefully in pyproject.toml using exact version specifiers. The CI pipeline passed for three weeks. Then the resolver decided to downgrade numpy from 1.26 to 1.24 because one of our indirect dependencies had a loose constraint written as numpy<2. The polars binary wheels we relied on needed 1.26+. The build failed with a linker error that pointed at numpy headers but was actually caused by a runtime version mismatch between the compiled extension and the installed numpy. We spent four hours debugging that. The workaround wasn't elegant. We switched from exact pinning to a combination of constrained ranges and a requirements.txt generated by pip-compile, which gave us a frozen lockfile. More importantly, we added a sanity-check step in CI that ran numpy.show() and printed the actual resolved version, catching these mismatches before they became runtime errors. This is the kind of thing nobody tells you about until it's 2 AM and your staging environment is down.
How The Resolver Actually Works
The pip resolver uses a backtracking algorithm based on SAT solving. When you run pip install, it doesn't just fetch packages top to bottom. It explores the dependency graph, tries to find a consistent set of versions, and backtracks when it hits a conflict. This used to be painfully slow. The current resolution algorithm (introduced around pip 22.2) is significantly faster because it does constraint propagation before backtracking. But speed isn't the issue. The real issue is that the resolver will happily give you a version that satisfies every declared constraint while silently breaking something your code depends on that isn't declared in any pyproject.toml. Optional dependencies, version-specific APIs, ABI changes between minor numpy releases — none of this shows up in the resolution graph. The resolver sees only what's declared, not what's actually used at runtime. I learned this the hard way with cryptography. A dependency in our stack declared cryptography>=3.0, and the resolver happily installed version 42.0. The old Fernet API we used internally was removed in a minor release. The tests passed because they didn't exercise that code path. Production broke on the first real request.
Get the Full Details
Build Systems And Why They Matter More Than You Think
Most people interact with Python packages through pip, but the package itself is built by a build backend. The default for decades was setuptools, which has well-known quirks. hatchling is the modern replacement and is substantially faster for clean builds. Poetry uses its own build system under the hood. uv, the new fast Python package manager, has its own backend too. The pyproject.toml file is where you declare which backend to use. If it's missing a build-system section, pip falls back to setuptools, and you may get unexpected behavior depending on your setup. I once spent an afternoon diagnosing why a package wouldn't install correctly on a fresh machine. The project had no build-system key in pyproject.toml. On the developer's machine, setuptools was installed globally. On the fresh machine, only pip's bundled setuptools was available, and it was an older version that couldn't handle the package's configuration format. The fix was adding a minimal build-system declaration:
build-system requires ["hatchling"] build-system build-backend = "hatchling.build" This single change eliminated the ambiguity and made the package installable in any clean environment. It's a small thing. Most projects skip it because it works on their machine, which is exactly the problem.
VIRTUAL ENVIRONMENTS ARE NOT OPTIONAL
I still see people installing packages globally on development machines and in containers. It causes collisions that are nearly impossible to reproduce. Use venv, conda, or pipx depending on your use case. The overhead is negligible. The cost of not using one is debugging sessions where the same code works on one machine and fails on another for reasons that seem magical. If you're working on multiple projects that need different versions of the same package, consider using uv or pip-tools to manage lockfiles per project. uv is particularly useful because it's fast, handles virtual environments automatically, and its resolver is built differently than pip's. It's not a replacement for pip in all contexts, but for day-to-day development it cuts dependency resolution time significantly.

COMMON PITFALLS THAT EVEN EXPERIENCED DEVELOPERS MISS
One of the biggest mistakes I see is relying on
=version specifiers without considering backward compatibility guarantees. Major version bumps in Python packages sometimes include breaking changes even when they shouldn't, especially in libraries that don't follow semantic versioning strictly. numpy is the most notorious example. pandas has gotten better about it. Some packages in the scientific stack still treat their public API as unstable within major versions. Another pitfall is assuming that a package in the global environment won't leak into your virtual environment. In practice, if you have PYTHONPATH set or if your virtual environment was created with the --system-site-packages flag, global packages become visible. This is especially common in Jupyter notebooks where kernels are sometimes configured with system packages included. I once inherited a notebook-based workflow where someone had installed scikit-learn globally and also in a virtual environment. The kernel was using the global installation, which was an older version that didn't support the new API the rest of the team was writing against. The error messages were vague and pointed at import issues. It took me two days to trace it back to the kernel configuration.
WHAT THIS ALL MEANS PRACTICALLY
If you want to work effectively with Python packages, start by understanding what's happening at each layer. Check your pyproject.toml for a build-system declaration. Use lockfiles for reproducible builds. Run sanity checks in CI that verify not just that packages install but that they resolve to the versions you expect. Don't ignore dependency warnings. When pip prints a conflict resolution warning, read it instead of treating it as background noise. The Python package ecosystem works well enough for most things. It breaks in ways that are hard to diagnose when it fails. The difference between a five-minute fix and a five-hour debugging session usually comes down to understanding which part of the stack is actually responsible for the problem.