Working With UKG Dimensions in Kroger's Workforce Environment
Most people trying to pull dimensions from UKG for workforce management end up running into the same wall. The platform doesn't hand you clean export files. It hands you XML, sometimes CSV if you're lucky, and more often it hands you errors because a dimension hasn't been mapped in the target system yet. I've spent years untangling this stuff at scale, and I'll tell you what actually works without the marketing fluff. Start by understanding what UKG dimensions are before you try to extract or push them anywhere. They are the building blocks the scheduling, timekeeping, and analytics engines use to tag every employee action. Department, job code, location, shift type, cost center, labor category — these are all dimensions. When someone clocks in at a store, the system attaches a set of these tags to that event. That tagging is what makes reporting possible. It's also what makes integration a nightmare if even one tag is missing or misaligned. The problem isn't that UKG lacks dimensions. The problem is that Kroger's implementation has dozens of custom dimensions layered on top of standard ones, and they don't always line up across modules. I remember working on a project where the scheduling module and the timekeeping module both used a "store segment" dimension, but one called it SEGMENT_CODE and the other called it STORE_GROUP. Both referenced the same business concept, but any automated process pulling from both would break or silently misattribute hours. The fix was mapping both field names to a single canonical dimension value in the middleware layer. Simple in theory. Getting both sides to agree took about three weeks of back and forth with the data governance team.
Where to Find and Export Dimension Data
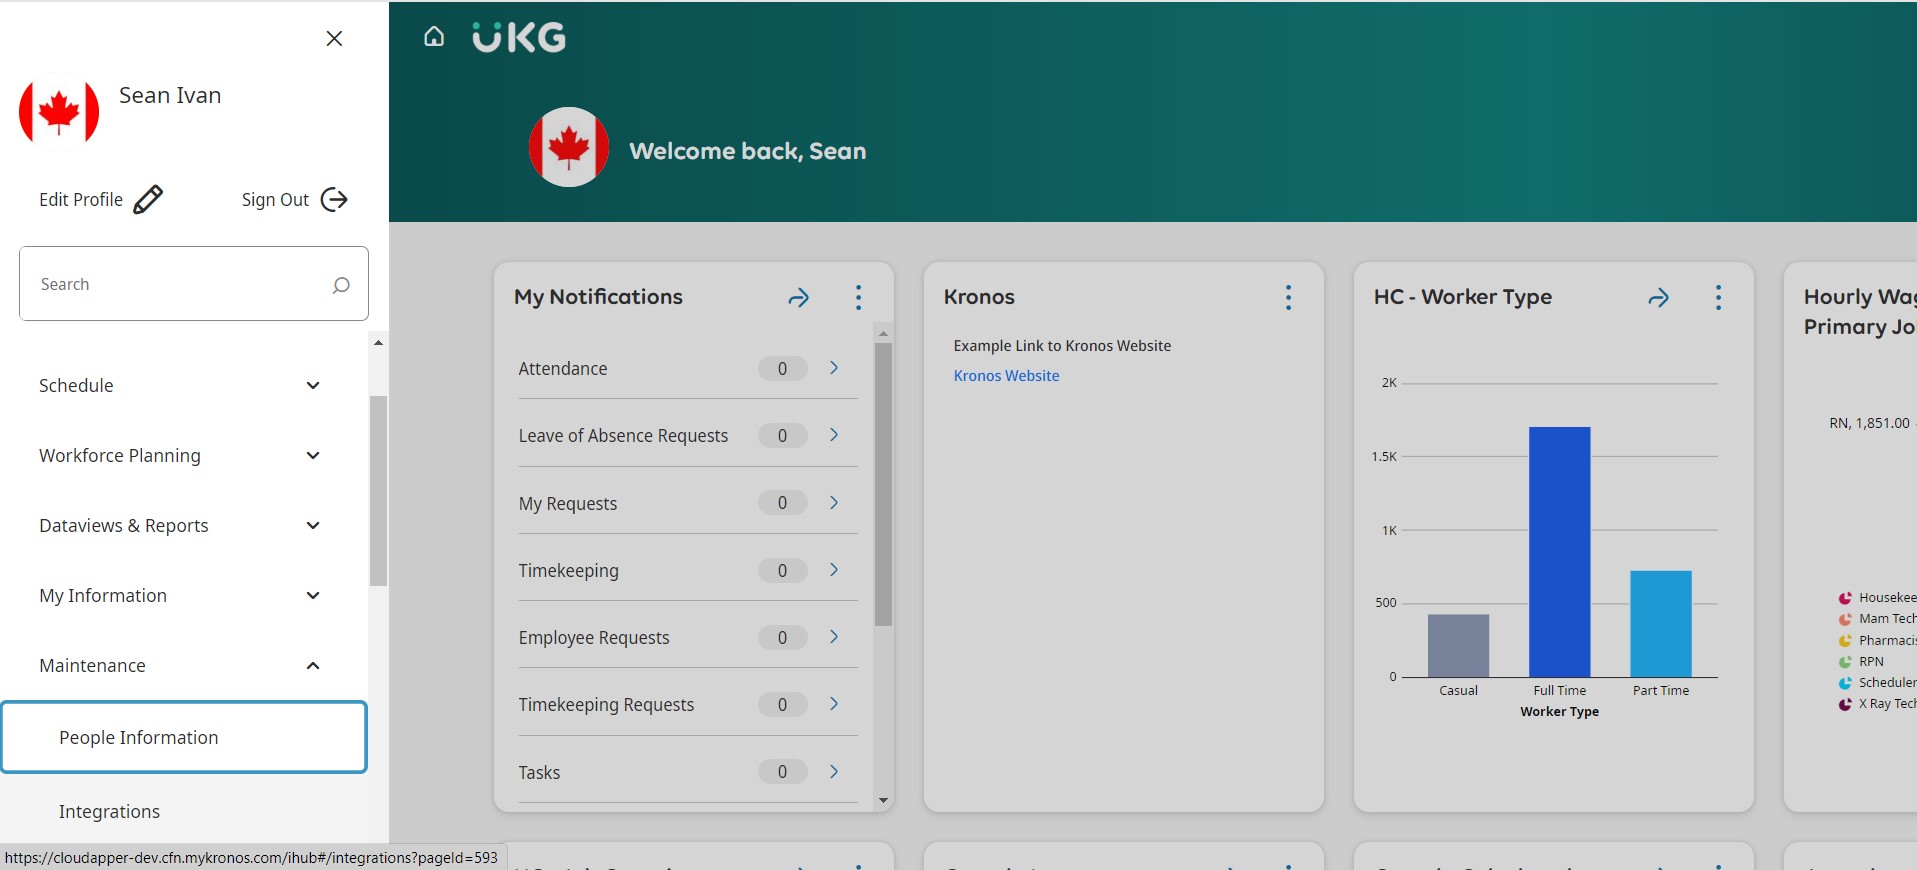
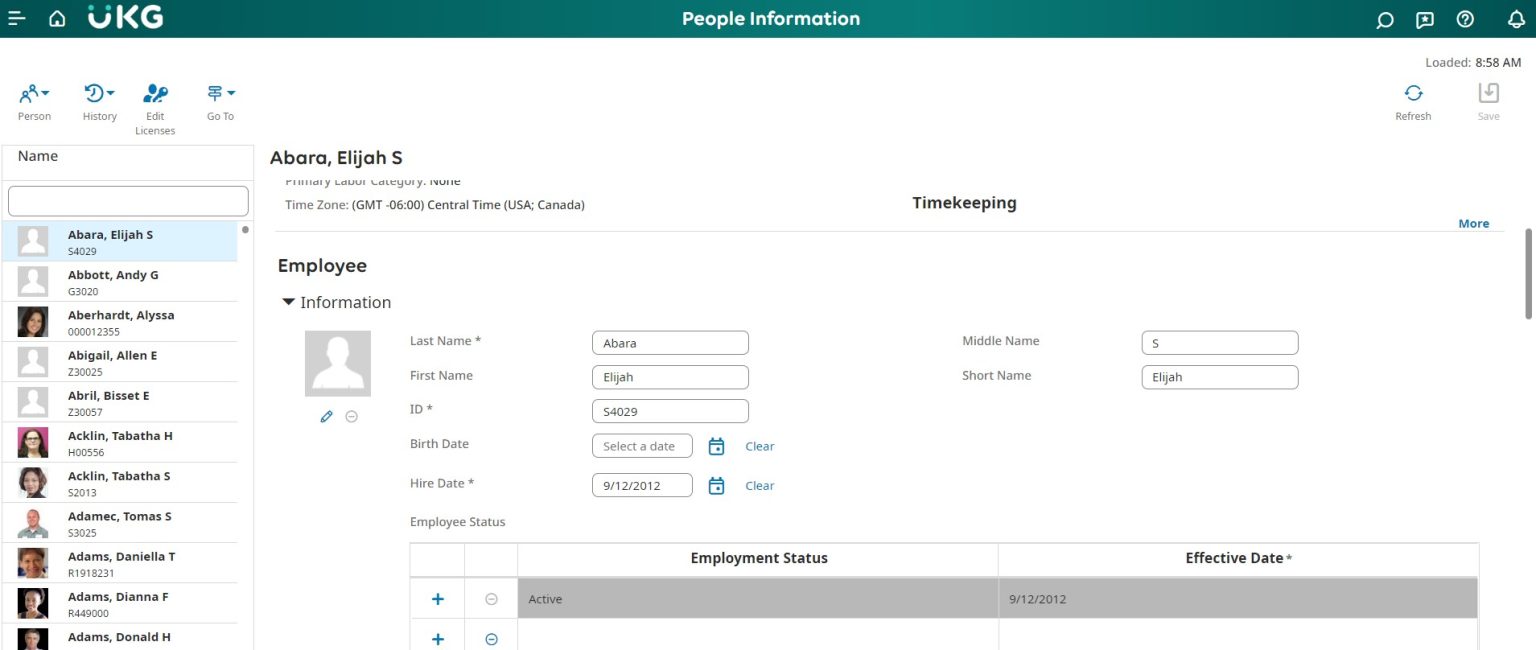
UGK stores dimension definitions in its metadata repository, accessible through the designer tool. You'll need proper credentials, typically granted by your internal IT or workforce systems group. From there, navigate to the Dimensions section under the relevant application module. In Kroger's setup, the primary modules you'll deal with are Kronos Workforce Central, now rebranded as UKG Ready, and the associated reporting tools. Once you locate the dimensions you need, exporting them is straightforward. Right-click or use the export function in the dimension viewer. This gives you a flat file with dimension ID, name, parent relationships, and active status. It's not a lot of data, maybe a few thousand rows for a company the size of Kroger, but it's the foundation. Without this baseline, you can't validate whether the data flowing into your downstream systems is complete. Here's the part most guides skip. After you export the definitions, cross-reference them against your target system. If you're pushing data to a data warehouse, a BI tool, or another HR platform, you need to verify each dimension exists on the receiving end. Mismatches are common. I've seen cases where a newly added cost allocation dimension in UKG had no corresponding field in the analytics platform, meaning all hours tagged with that dimension just dropped off the reports. Nobody noticed for months because the total hours still summed correctly, just without the granular breakdown leadership expected.
Building the Integration Layer
Integration usually happens through an ETL process or a real-time API feed, depending on your use case. For batch reporting, nightly extracts work fine. For real-time labor visibility, you need continuous sync, which adds complexity around error handling and data consistency. The critical step is creating a dimension mapping table. This is a reference file that lists every UKG dimension alongside its equivalent in your downstream systems. Include field names, data types, default values, and any transformation logic. For example, UKG might store department as a numeric code while your ERP expects a text string. Your mapping table documents that conversion so anyone maintaining the pipeline knows what to expect. I once inherited a pipeline where the mapping table had been maintained for years but nobody validated it. We discovered that twelve dimensions were either orphaned or pointed to deprecated codes. Rebuilding the mapping from scratch took about two days, but the real issue was that stale mappings had been sending erroneous data to the executive dashboard for over a year. Fixed it, and the first clean report came through the next morning. Leadership was not happy about the previous year's numbers but appreciated the fix.
Get the Full Details
Common Pitfalls and How to Avoid Them
The biggest mistake people make is assuming dimensions are static. They aren't. Kroger adds, retires, and repurposes dimensions regularly. A dimension that worked last quarter might be decommissioned this month. You need a change management process that tracks dimension lifecycle events. Subscribe to UKG release notes, monitor your internal dimension registry updates, and audit your mappings quarterly at minimum. Another issue is dimension hierarchy depth. UKG supports multi-level hierarchies for certain dimensions, like region divided into district divided into store cluster. When exporting, you need to decide whether to flatten the hierarchy or preserve it. Flattening makes downstream processing easier but loses contextual relationship data. Preserving it gives richer analysis but requires more complex modeling. There's no universal right answer. It depends on what your reports and dashboards actually need. I recommend starting flat and adding hierarchy support only where it drives measurable decision-making value. Data volume is also a factor. UKG dimensions can generate massive detail at scale. Kroger operates thousands of stores with multiple locations, shifts, and cost allocations per store. Daily transaction volumes can reach millions of dimension-tagged records. Your integration pipeline needs to handle that load without lagging or timing out. I've seen batch jobs fail because they tried to process a full month of dimension records in a single run. Breaking the extract into daily or weekly chunks resolved the issue and made debugging easier when something went wrong.
Validation and Ongoing Maintenance
After you build the integration, validation is non-negotiable. Compare total hours, headcount, and cost allocations between UKG and your downstream system on a regular basis. A simple reconciliation script that runs weekly or monthly will catch drift before it becomes a reporting crisis. I built a basic Python script that queries both systems and flags any dimension value present in UKG but missing in the target, or vice versa. It runs overnight and emails a summary. Took me half a day to write, saved me from countless headaches since. Documentation matters too. Every mapping, every transformation rule, every known exception should be recorded in a shared repository. When the person who built the original pipeline leaves, as they inevitably do, the next person shouldn't have to reverse-engineer everything from scratch. I've inherited poorly documented integrations that took weeks to understand. Don't be that person. Leave clear notes for whoever comes after you. There's no perfect solution here. UKG dimensions are powerful but unforgiving. They require constant attention, regular validation, and a willingness to adapt when the platform changes. But when done right, they give you visibility into labor operations that most companies never achieve. The effort is real. The payoff is worth it if you're patient and methodical about it.
 Interview Questions.png "Top 30 Kronos UKG Workforce Management (Dimensions) Interview 2026")