.jpg)
Google Translate Is A Tool, Not A Solution
Google Translate has been around long enough that people have either learned to use it properly or they've given up entirely. The professionals who still get value from it tend to be the ones who understand exactly where the tool breaks down. I spent years working with localized product documentation for a European manufacturing company, and the first time I tried to run an entire 300-page PDF through the free tier of Google Translate, it choked on the tables and the formatting collapsed in ways that took me half a day to repair. Not because the translation was bad, but because the structure got mangled. The difference between getting useful output and wasting your time comes down to understanding what the engine is actually doing under the hood. It is not a bilingual word-matching system anymore. It runs on transformer-based neural architectures trained on massive multilingual corpora. That means it predicts likely translations based on context windows, not individual words. This is important because it changes how you approach everything from terminology management to post-editing workflows.
Unlocking Global Business The Definitive Guide To Google Translate For Professionals
Start by using the right interface for your workload. The plain web interface at translate.google.com works fine for quick one-offs, but if you are processing more than a handful of documents per week, the API is the only option that does not make your life unnecessarily difficult. The free tier gives you 500,000 characters per month at no cost, which sounds generous until you realize that a mid-length technical manual in English runs roughly 80,000 to 120,000 characters. That is maybe four or five documents before you are paying for overage or hitting a wall. The API endpoint is straightforward to integrate. You send a JSON payload with your text, the source language code, and the target language code. The response comes back with the translated string, plus some metadata like estimated character counts and detected language probabilities. The real advantage is programmatic control over parameters like glossary injection, which lets you force certain terms to translate consistently across a batch. Without a glossary, Google Translate will render "server" as "mesa" in Spanish when the context is clearly about computing hardware. With a glossary specifying server equals servidor, the output stays accurate. Here is where most people go wrong. They treat the raw output as usable deliverable and send it directly to a client or publish it on a localized site. Neural machine translation has improved dramatically, but it still produces systematic errors in low-resource language pairs and highly technical domains. A German engineering document translated into Mandarin through a single pass will often misrender compound nouns, drop modal particles that change meaning, and misalign units of measurement because the model did not encounter enough parallel corpus matching your specific industry phrasing.
I learned this the hard way with a set of assembly instructions for industrial pumps. The Spanish translation produced by Google Translate read perfectly fine at surface level. But the verb forms for imperative instructions used the wrong person conjugation throughout, making sentences that should have read like "Install the gasket here" come out as something closer to "The gasket would be installed here by you." A native Spanish speaker could follow it, but it sounded alien and unprofessional. I spent the afternoon manually correcting the imperative forms while keeping the rest of the translation intact. That cut my turnaround time from about two hours of full re-translation down to roughly twenty minutes of targeted post-editing.
Get the Full Details
Practical Workflow For Professional Use
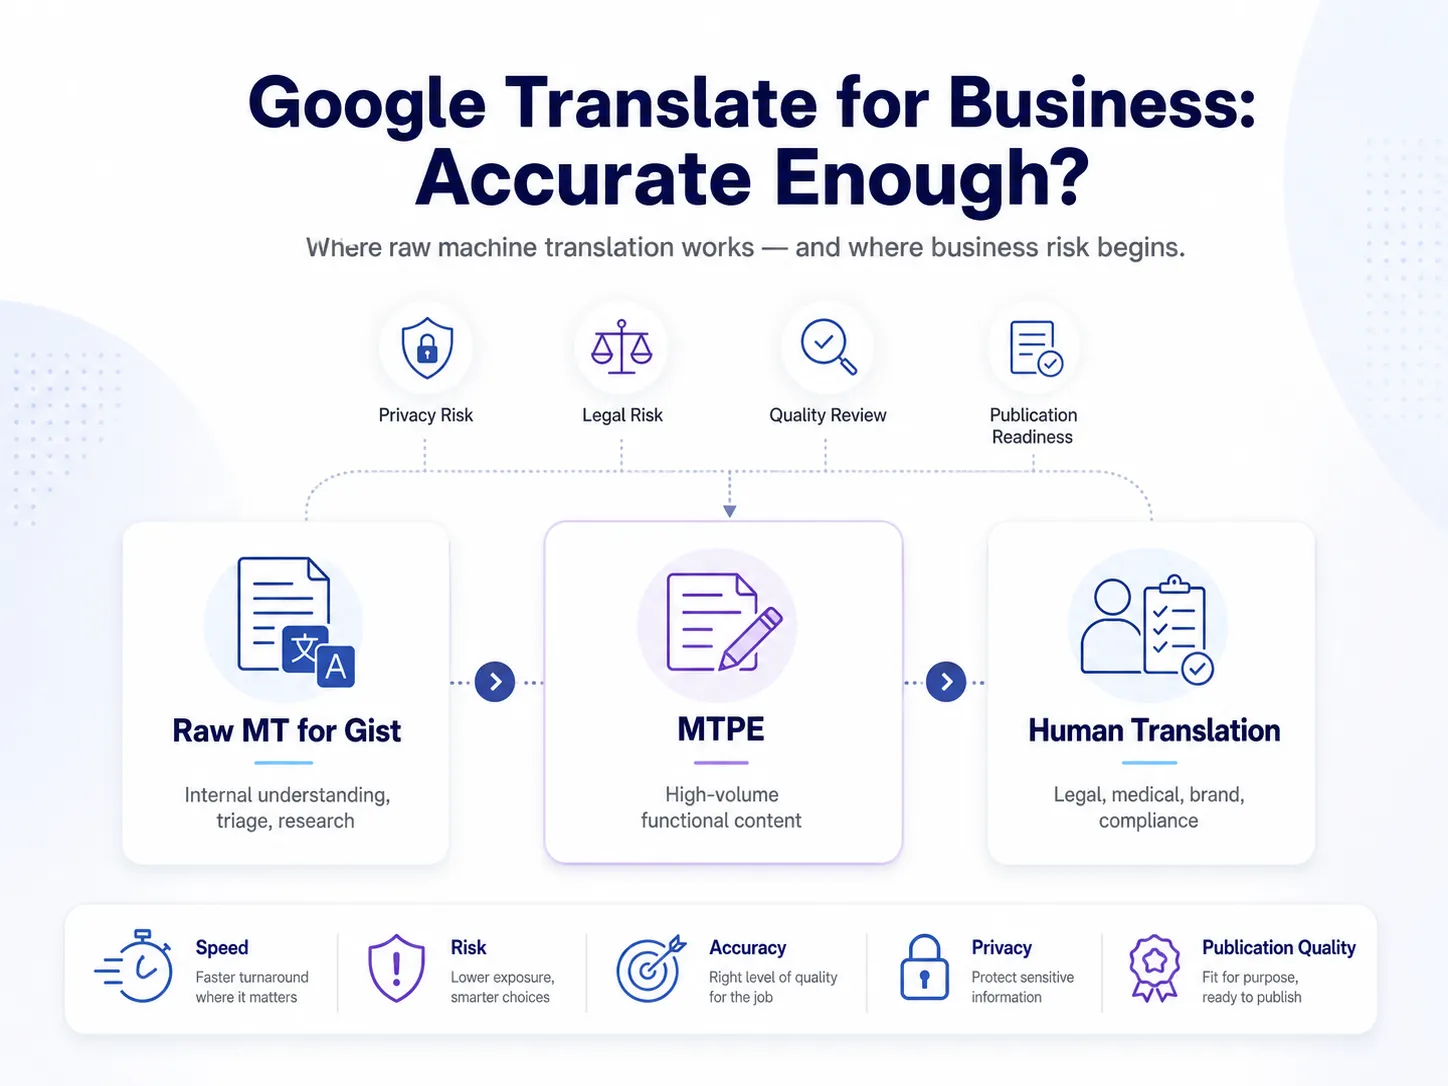
The most efficient setup I have found involves three stages: pre-processing, translation, and post-editing. Pre-processing means breaking your source text into manageable segments, usually by sentence or paragraph, stripping out formatting codes, and extracting any terms that need special handling into a glossary file. The glossary should be a simple CSV with source term, target term, and part of speech if relevant. Google Translate's glossary feature supports this natively through the API. During the translation stage, batch your requests rather than sending single queries. The API supports batch translation up to 32,000 characters per request, and grouping your text into those chunks reduces latency significantly compared to sending everything individually. I usually group content by section header so that if one batch fails or produces garbage, I can isolate the problem without retrying the entire document. Post-editing is where the actual value comes in. There are two approaches: light post-editing, which fixes only critical errors that change meaning or cause confusion, and full post-editing, which aims for publication-quality fluency. Light post-editing typically takes about one-third to one-half the time of translating from scratch, while full post-editing approaches the time cost of a fresh translation. The difference matters when you are working against deadlines.
A counter-intuitive thing about Google Translate is that it sometimes performs better on shorter inputs. Longer passages give the model more context, yes, but they also amplify any systematic bias in the training data. A well-constructed paragraph about quality control standards might translate decently, but stretch that same content across multiple paragraphs with slight variations in terminology and you will start seeing inconsistency creep in. The model resolves each segment somewhat independently, so identical technical terms can end up with different translations depending on surrounding context. Running a consistency check with a tool like MultiTerm or even a simple spreadsheet filter comparing repeated terminology across the output catches most of these cases. The biggest limitation to keep in mind is that Google Translate has no domain-specific fine-tuning available on the standard API. Unlike specialized MT engines such as DeepL or proprietary solutions from companies like Welocalize or RWS, Google does not offer a way to fine-tune the model on your own parallel corpus unless you are using the Enterprise tier, which requires a contract and minimum spend commitments. For small teams or individual professionals, this means you are working with a general-purpose model applied to specialized content. The gap becomes most visible in legal, medical, and financial texts where precise terminology is non-negotiable. If you are working in one of those domains, I would recommend using Google Translate as a draft generation tool and then running the output through a human reviewer who understands both the source and target language plus the domain. The review should focus on terminology consistency, register appropriateness, and cultural adaptation rather than basic accuracy, since the model gets the basics right more often than most people expect. The real damage comes from subtle issues: a word that is technically correct but carries the wrong connotation, or a phrasing choice that signals amateur translation to a native reader even though nothing is strictly wrong.
Another thing worth noting is that character counting includes whitespace and punctuation, so a densely formatted document will burn through your free quota faster than a plain text version of the same content. Stripping unnecessary whitespace before sending to the API can extend your monthly allowance by a meaningful margin without changing the actual translation output.