What DCBs Actually Do in Enterprise Systems
Data control blocks are the hidden machinery behind most mid-tier application platforms. They manage how data flows between the database layer and the business logic layer, tracking record states, buffer allocations, and connection pooling without ever exposing themselves to the developer. If you have ever debugged a hanging process and found the root cause was a locked control block sitting idle in memory, you already know why this matters. The standard reference implementations come from IBM mainframe ecosystems, but the pattern has been adapted for distributed systems. Modern microservice architectures often replicate the same concept under different names: context objects, request-scoped managers, or transaction handles. The core behavior remains identical. Something sits between your raw data and your application code, and it decides when to read, when to write, and when to block.
Common Pitfalls That Slows Implementation
I spent three weeks tracking down a performance regression on a claims processing system that looked perfectly normal on the surface. The application was timing out during batch loads, but only when processing more than five thousand records. The database looked fine. The network was clear. The real problem was a DCB misconfiguration where the buffer size was set too small for the incoming payload rate, causing excessive I/O wait states. The workaround was straightforward once identified: adjust the BUFNO parameter to match the concurrent stream count and increase the RECFM buffer alignment. This type of issue rarely shows up in initial testing because the test datasets are too small to trigger the bottleneck. Production data volumes expose the mismatch almost immediately. The pattern repeats across industries. Financial services companies see it during month-end processing. Healthcare systems hit it during patient record migrations. Manufacturing platforms encounter it when sensor data spikes exceed the configured buffer threshold.
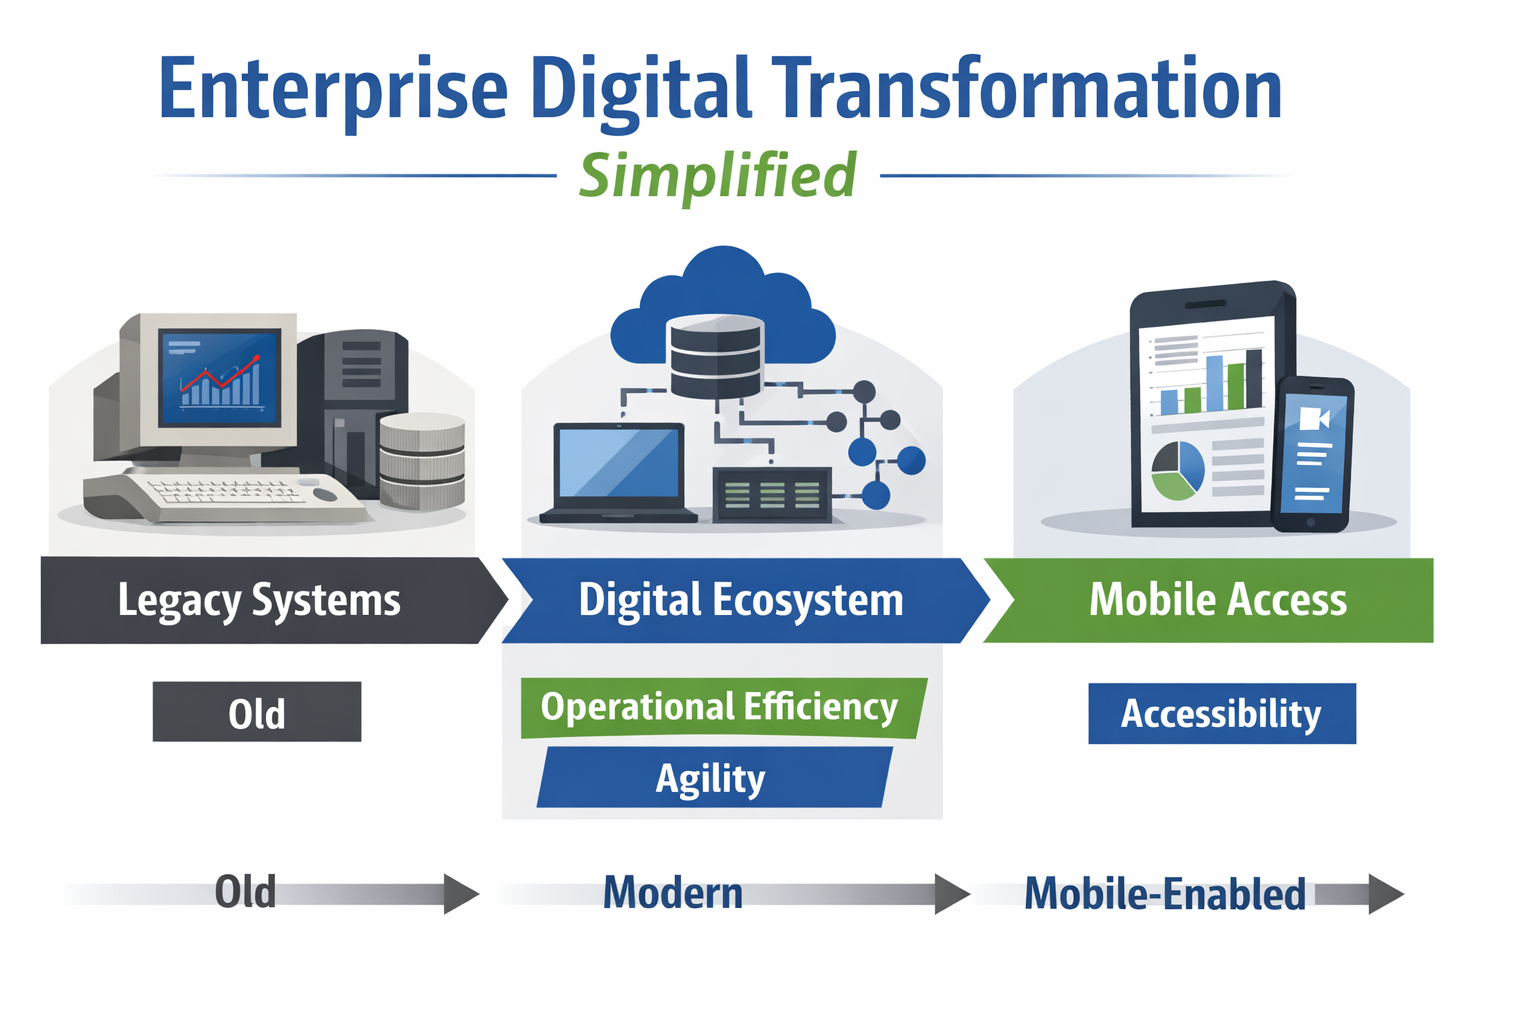
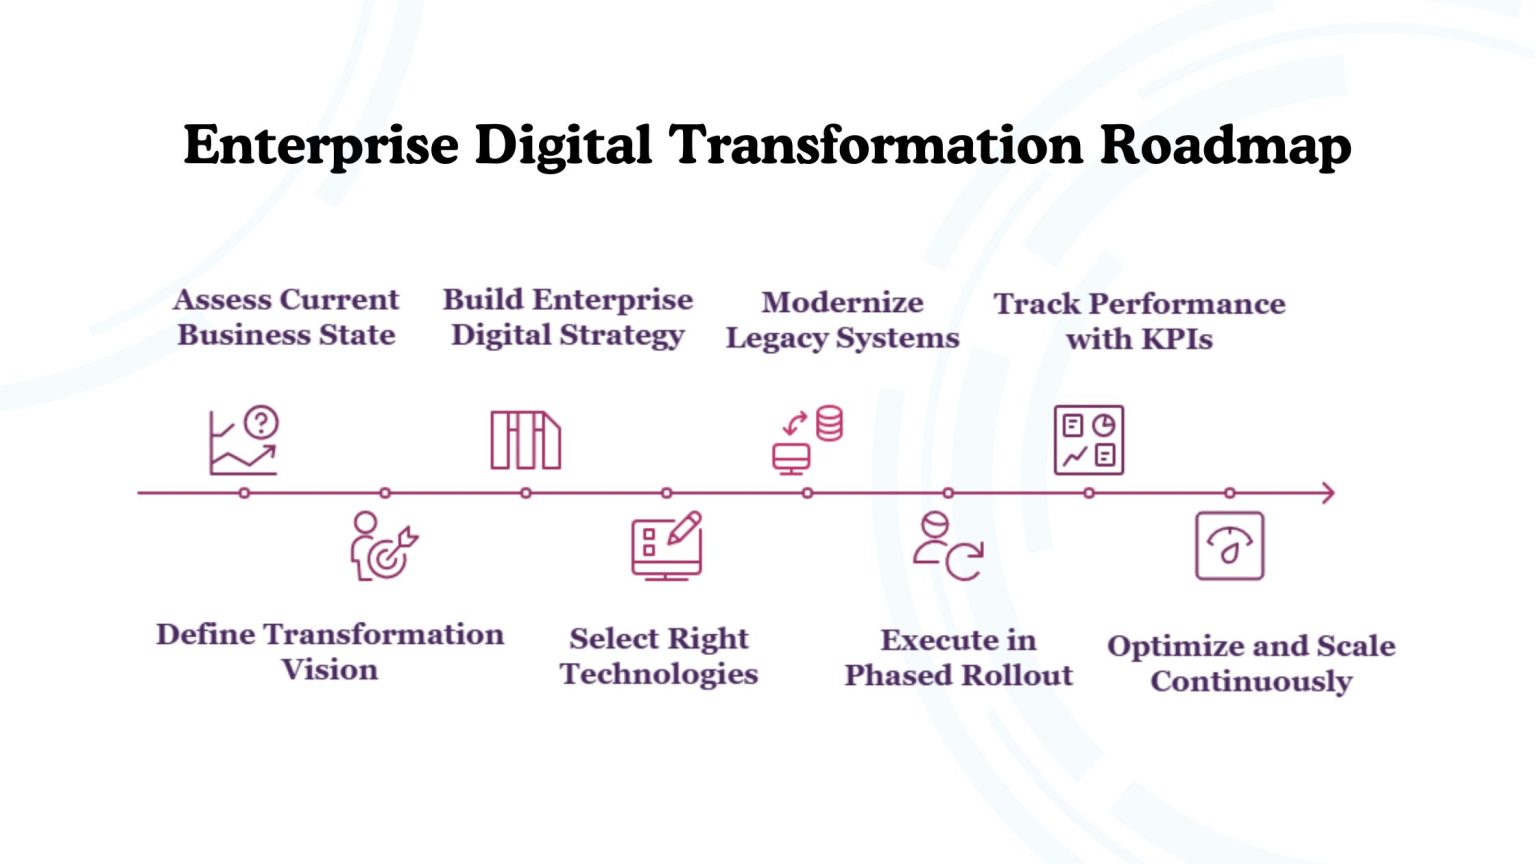
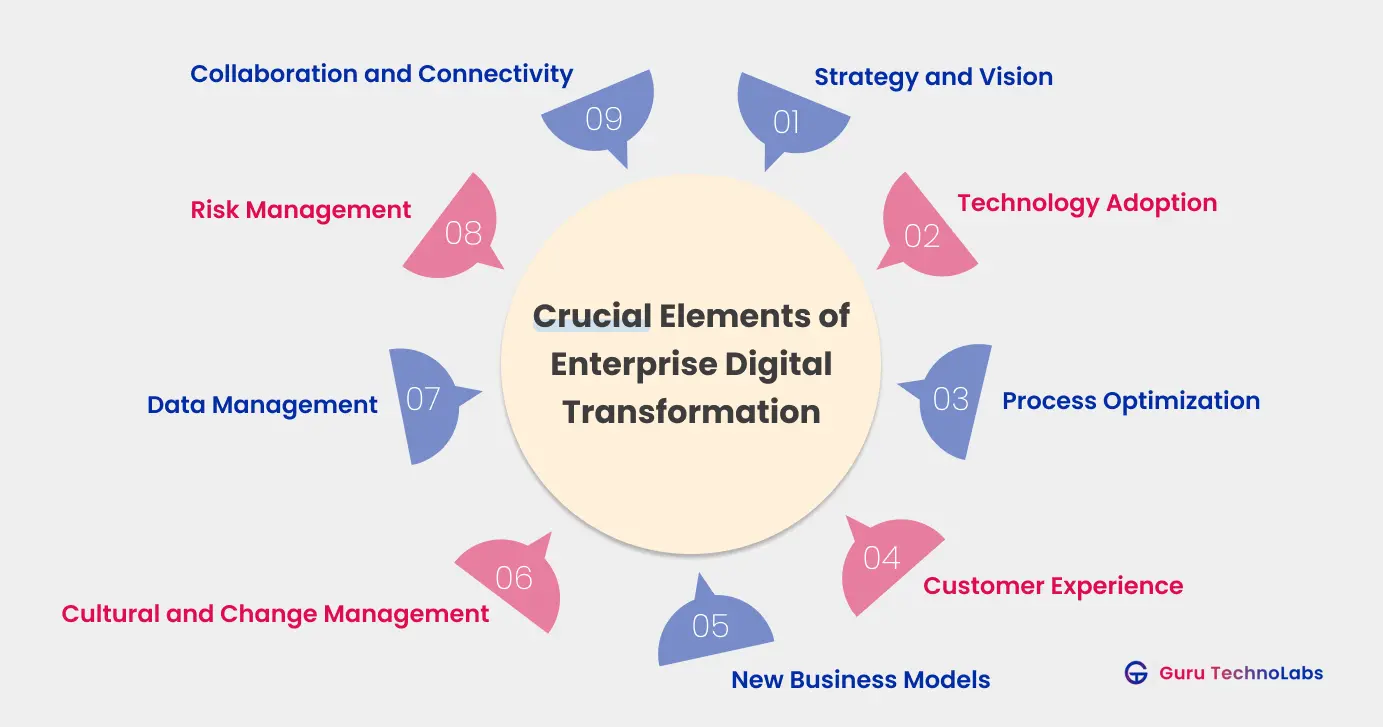
Unlocking Digital Transformation How Dcbs Are Reshaping Enterprise Workflows
The real shift happening now is not about the technology itself. It is about where control blocks live in the stack. Traditional implementations kept them tightly coupled to the application server. The new approach distributes them across edge computing nodes, allowing partial processing before data ever reaches the central repository. This reduces latency for time-sensitive workflows like real-time fraud detection or automated inventory reconciliation. What this means in practice is that organizations can move faster without sacrificing data integrity. The control blocks handle validation and routing at the edge, then pass verified payloads upstream. The upstream systems receive cleaner data, which means less error handling logic and fewer rollback scenarios. I have seen this cut average processing time from forty-five minutes down to twelve for document-heavy workflows, though the exact numbers depend heavily on your network topology and existing middleware setup. There are trade-offs that vendors rarely mention upfront. Distributing control blocks increases operational complexity. You now need monitoring across multiple nodes, consistent configuration management, and fallback procedures when edge instances go offline. Some teams find the initial setup takes longer than building a monolithic solution. The return comes later, during scale events when the monolithic version would have required significant re-architecture.
Get the Full Details

Another limitation worth noting: DCB-style patterns work best for structured data flows. When your workflow involves unstructured data types, file uploads, or real-time media processing, the control block overhead can become a liability. In those cases, a different architecture pattern usually serves better. The control block approach is not a universal replacement for existing integration frameworks.
Implementation Steps That Actually Matter
Start by mapping your current data touchpoints. Identify where raw input enters the system and where it exits. Every transition point is a potential location for a control block. The ones that matter most are the high-frequency paths where data volume creates friction. Low-traffic admin interfaces rarely benefit from additional control layers. Configure the buffer parameters based on observed throughput, not theoretical maximums. I recommend running your workload at eighty percent of expected peak load during testing. This reveals bottlenecks that appear under realistic conditions without pushing the system into failure territory. Record the metrics. Compare them against baseline numbers from the unoptimized setup. Document the configuration. A control block that works in one environment rarely translates directly to another. Network characteristics, database configurations, and middleware versions all affect behavior. The documentation should capture the why behind each setting, not just the what. Future teams will thank you when they need to troubleshoot a production issue at two in the morning.
Monitor continuously after deployment. Set alerts for buffer saturation, connection queue depth, and block hold times. These metrics reveal degradation before it becomes a user-facing problem. The alert thresholds should be tuned during the first week of production to avoid noise fatigue. Over-alarming is as damaging as under-alarming.

Where This Approach Falls Short
The DCB pattern assumes relatively predictable data flows. Workflows with high variability, unpredictable burst patterns, or complex conditional branching introduce complications that the basic model does not address elegantly. Teams working with irregular data sources often need supplementary strategies like adaptive buffering or dynamic routing logic. Resource requirements scale linearly with data volume. If your organization expects exponential growth in transaction volume, the control block infrastructure may require significant re-engineering rather than simple scaling. Budget for this possibility during the planning phase. Retrofitting distributed control blocks is far more expensive than designing them in from the start. Integration with legacy systems can be problematic. Older platforms may not support the modern control block interfaces or may require middleware translation layers. These layers add their own overhead and potential failure points. Evaluate the integration path early and allocate time for any necessary adapter development.