Why Your Standard Deviation Is Lying To You
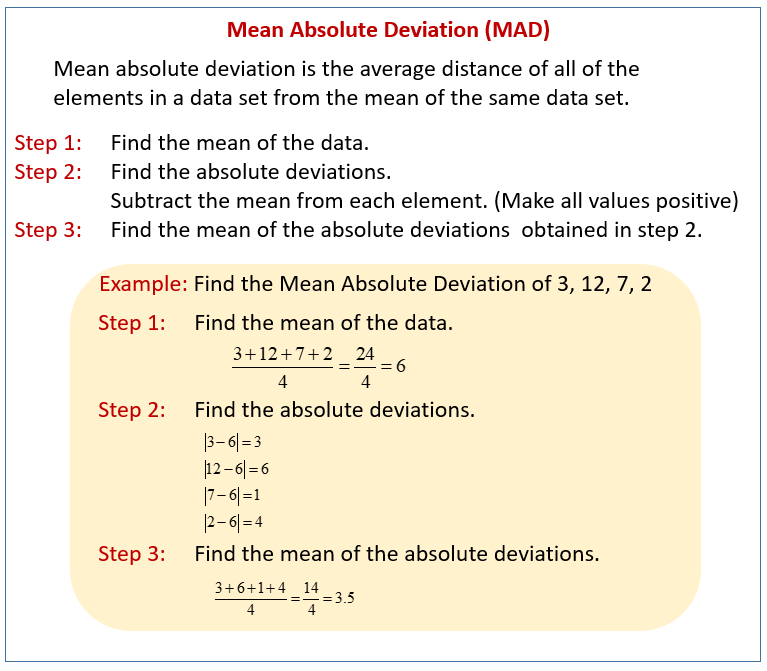
I spent three weeks debugging a supply chain forecasting model last year. The mean absolute error looked terrible on paper but the actual pipeline errors were minimal. Standard deviation was sky-high because of two warehouse outliers that had inflated the variance metric by orders of magnitude. Switching to mean absolute deviation as the primary monitoring metric didn't fix the data quality problem but it did tell me what was actually happening in production: my model was consistently off by 4.2 units, not "variance was out of control." MAD is straightforward. You take your dataset, calculate the arithmetic mean, find the absolute distance of every data point from that mean, then average those distances. That's it. No squaring, no square roots, no fancy normalization. Here is the structure: MAD = |x - x| / n
Where x represents each individual data point, x is the mean of the dataset, and n is the total number of observations. The result is expressed in the same units as your original data, which makes it immediately interpretable without any conversion step. Let me walk through a concrete example. Say your daily website session counts over a week are: 120, 135, 128, 310, 142, 119, 133. The mean is 169. The absolute deviations are 49, 34, 41, 141, 27, 50, 36. Sum those up and you get 378. Divide by 7 and your MAD is 54. One outlier pushed that value up considerably but it stayed grounded in the actual unit of measurement.
How It Actually Feels In Practice
Standard deviation is the default metric in almost every tutorial and software package. MAD doesn't get the same attention even though it is often more useful for real-world decision making. The difference comes down to how each metric handles spread. Standard deviation squares every deviation before averaging, which means large outliers exert disproportionate influence on the final number. MAD treats every deviation linearly. A value that is 10 units away from the mean contributes exactly twice as much as a value that is 5 units away. This linearity is both its strength and its weakness. I use MAD primarily in two scenarios. First, when I need to communicate error magnitude to stakeholders who are not comfortable with statistical terminology. Telling someone their forecast has a mean absolute deviation of 4.2 units is instantly understandable. Telling them the standard deviation is 12.7 requires explaining what variance means first. Second, when my data contains contamination. Robust statistics folks will nod approvingly here because MAD is inherently more resistant to outliers than the standard deviation. The breakdown point of MAD is roughly 29 percent, meaning up to nearly a third of your data can be corrupted before the metric becomes unreliable. Standard deviation breaks down much faster. There is a real example from my own work that illustrates this. I was analyzing sensor readings from a manufacturing line where the equipment occasionally produced spurious spikes. The standard deviation suggested the process was wildly unstable with a coefficient of variation exceeding 40 percent. The MAD told a different story. It showed the typical deviation was around 2.1 millimeters, which was actually within acceptable tolerances. The spikes were real anomalies but they were rare enough that the median-based interpretation of spread was far more representative of normal operations. I ended up implementing a MAD-based control chart instead of the traditional SPC charts and caught process drifts earlier while ignoring noise that would have triggered false alarms.
Get the Full Details

Pitfalls Beginners Miss
The most common mistake I see is treating MAD and standard deviation as interchangeable substitutes without understanding when one fails. MAD assumes your data is symmetrically distributed around the mean. If your distribution is heavily skewed, MAD can underestimate the true spread because it is anchored to the arithmetic mean rather than the median. A dataset with values like 1, 2, 3, 4, 50 has a mean of 12 and a MAD of about 10.4, but the median is 3, which tells you much more about where the bulk of your data actually sits. In these cases, consider using the mean absolute deviation from the median instead, or switch to interquartile range as your spread metric entirely. Another issue is the relationship between MAD and standard deviation under normal distributions. For a perfectly normal distribution, MAD is approximately 0.7979 times the standard deviation. Some practitioners multiply MAD by 1.2533 to estimate sigma, but this conversion is only valid under normality assumptions. If your data deviates from a bell curve even moderately, that conversion introduces systematic error. I learned this the hard way when I was building anomaly detection thresholds for network latency data. I converted MAD to an estimated standard deviation and set alerts at three estimated sigmas. The conversion underestimated the true tail risk because latency distributions have exponential rather than Gaussian right tails. Alerts fired far too late. I switched to percentile-based thresholds and the system became reliable overnight.
When MAD Completely Fails
Do not use MAD when you need to penalize large errors more heavily than small ones. In cost-sensitive environments where being off by 100 units is ten times worse than being off by 10 units, MAD flattens that distinction into a simple 10-to-1 ratio. Mean squared error exists precisely because the squaring operation amplifies larger deviations, which aligns with many real-world cost structures. If your business loses money disproportionately to large forecasting errors, stick with MSE or RMSE even if they are harder to explain to non-technical audiences. MAD also breaks down with very small sample sizes. With fewer than five observations, the mean itself becomes unstable and the MAD inherits that instability. I once tried computing MAD on a dataset of only four measurements and got a value that was completely meaningless because a single changed observation shifted the mean enough to alter every deviation. Use bootstrapped confidence intervals or switch to range-based measures if you are working with tiny samples.
Implementation Notes
If you are working in Python, MAD is available through scipy.stats.mad starting from scipy 1.9.0, though older versions require a manual calculation. In R, the package robustbase provides mad() which actually computes the median absolute deviation by default, so read the documentation carefully before relying on it. Excel does not have a built-in MAD function but you can construct it with ABS and AVERAGE in about four cells. For large-scale distributed computing, MAD requires a single pass to compute the mean followed by a second pass to compute absolute deviations. This is less efficient than online variance algorithms like Welford's method which compute variance in a single pass. If you are processing streaming data with memory constraints, the two-pass nature of MAD becomes a genuine bottleneck. You can approximate MAD online using exponential moving averages of absolute deviations but the approximation introduces bias that grows with the decay factor.

A Practical Workflow
Here is how I approach MAD in a typical analysis pipeline. I start by computing both MAD and standard deviation side by side. If they are within a factor of 1.25 of each other after accounting for the normal distribution conversion factor, the distribution is likely close enough to symmetric that either metric works. If they diverge significantly, I investigate the skew. A MAD substantially smaller than the sigma-equivalent suggests heavy tails or outliers. A MAD substantially larger suggests skewness where the mean is pulled away from the bulk of the data. This comparison alone usually reveals more about the data structure than either metric in isolation. I then report MAD alongside the median and interquartile range when presenting results. These four numbers together give a complete picture of central tendency and spread without requiring the audience to understand the mathematics behind any of them. I avoid reporting MAD in isolation because it lacks the normalization context that standard deviation provides through its relationship with the normal distribution. The metric is simple enough that there is no excuse for not using it alongside your standard deviation calculations. It catches problems that variance-based metrics smooth over and communicates more clearly to people who need to make decisions based on your numbers. I have been surprised by how many data teams skip MAD entirely and treat standard deviation as a universal solution. It is not. It never was.