Getting NWChem to Actually Work on Your Cluster
NWChem is one of those programs that exists in two realities. In the documentation, it runs seamlessly on 128 cores and gives you CCSD(T) results for a medium-sized organic molecule in a few hours. In practice, it crashes during the integral generation step because your MPI library is threaded wrong, or it silently gives you garbage energies because you forgot to specify the basis set properly for the d-orbitals on a transition metal. I spent three days debugging a geometry optimization on a Fe-S cluster last year. The calculation converged beautifully, the output looked reasonable, and then I compared it to a known crystal structure and the Fe-S bond lengths were off by nearly 0.2 angstroms. Turned out I'd used the default ECP settings for the iron instead of explicitly calling for a specific one. The program never complained. It just ran with whatever was in the input file, which was nothing for that particular block.
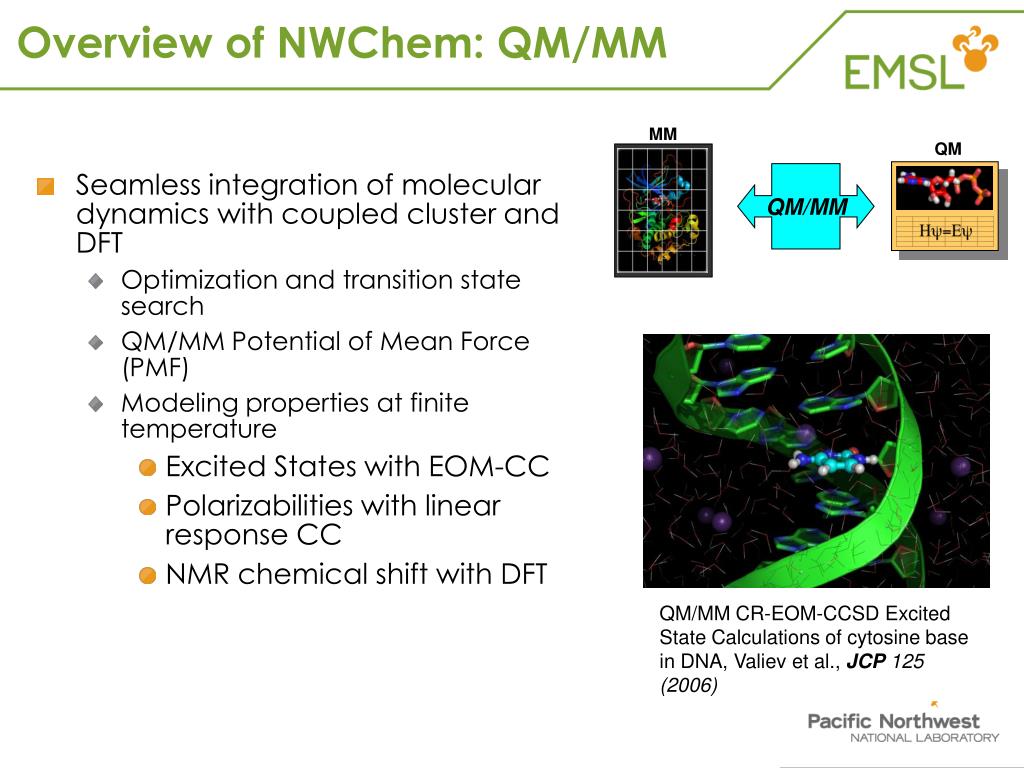
Unlocking Computational Chemistry How Nwchem Delivers Breakthrough Simulations
The basic workflow starts with an input file. NWChem uses its own format, which is more verbose than Gaussian's but actually more explicit about what you're asking for. Here is a minimal example that does a DFT geometry optimization: The key thing people miss is that task must be declared after the sections it depends on. If you put task geopt at the top and then define your dft block below it, older versions of NWChem will just ignore the dft parameters and run with defaults. This happened to me on a shared cluster running an older build. The output log said it was using B3LYP but it was actually running HF with a broken basis set. I caught it because the total energy was completely wrong compared to a test calculation I'd run locally. For parallel runs, you need to set up the environment correctly. On most HPC clusters you load modules for openmpi or intel mpi, then run with mpirun. The number of cores you specify has to match your actual allocation.NWChem does not gracefully degrade when you ask for more processes than you have. It will either segfault immediately or allocate tasks in a way that creates communication bottlenecks and makes the calculation slower than a single core would have been.
I once ran a job on 64 cores that took 18 hours. A colleague ran the same job on 16 cores and it finished in 4. The problem was the system had two NUMA nodes and all 64 ranks were pinned to one socket. The inter-socket bandwidth became the bottleneck. We fixed it by setting OMP_NUM_THREADS=2 and letting MPI handle the rest across both sockets, which cut the wall time to about 3 hours. When it comes to actual breakthrough-level simulations, NWChem's strength is in the methods that are not available elsewhere in open source. The Coupled Cluster module supports up to CCSD(T) for single reference systems, and the MP2 implementation scales well on distributed memory. For excited states, the TD-DFT and EOM-CCSD modules are genuinely useful. I used the EOM-CCSD module to compute vertical excitation energies for a porphyrin derivative where TD-DFT kept giving me negative oscillator strengths that made no physical sense. CCSD gave me results that matched the experimental absorption spectrum within 0.15 eV, which for a system that size is remarkable. The weakness is that these high-level methods are expensive and not always robust. CCSD(T) on a system larger than about 30 atoms with a triple-zeta basis set will eat through your memory allocation and probably exhaust your disk space from the intermediate integrals. I learned this the hard way when a 48-atom organometallic complex filled a 2 terabyte scratch partition during the integral transformation step. The job did not crash, it just hung there writing garbage to disk until the scheduler killed it. Nothing in the output log indicated the problem was disk space.
Get the Full Details
For larger systems where wavefunction methods are impossible, the DFT implementation is solid but you need to watch your grid settings. The default integration grid is adequate for most ground state properties but breaks down for transition metals with near-degenerate d-states. I switched to grid5 in a recent vanadium complex study and the orbital occupations stabilized properly. With the default grid, the self-consistent field cycle oscillated between two solutions for 200 steps before the program gave up. Getting the program itself can vary depending on your platform. Pre-built binaries exist for Linux on x86_64, and source builds work on macOS and various HPC environments. The official site is nwchem-src.github.io. If you are building from source, the configuration step is where most people hit trouble. You need to point it at your MPI installation, your BLAS/LAPACK libraries, and optionally GCC or Intel compilers. The build script is not forgiving about missing dependencies. If it cannot find a proper SCALAPACK library, it will fall back to a sequential implementation and your parallel job will perform like a serial one. A practical tip for anyone doing high-throughput screening with NWChem is to write a wrapper script that checks the output after every job. The program sometimes exits with a non-zero return code for warnings that are not fatal, and if you are running 200 calculations in a queue system you do not want to discover three days later that 40 of them produced corrupted output files. I write a quick grep for ERROR and WARNING in the output log and flag any job that contains more than five WARNING lines for manual inspection.
The learning curve is real. The documentation is comprehensive but scattered across multiple pages and not always consistent between releases. The manual for version 6.8 differs in important ways from 7.0, particularly around how you specify relativistic effects and ECPs. If you are copying input files from old papers or forum posts, verify the syntax against your specific version. A missing keyword or a misplaced end statement will not always produce a clear error message. Sometimes it just produces the wrong chemistry. For benchmarking purposes, NWChem produces reliable results when the input is correct and the computational resources are adequate. It is not the most user-friendly package available. Gaussian and ORCA have cleaner input formats and better error reporting. But if you need CCSD(T) on a cluster without a license, or you are doing large-scale DFT studies where cost matters, NWChem delivers where others cannot run at all. The main bottleneck remains system size. Beyond roughly 100 atoms with a moderate basis set, even DFT becomes expensive, and post-Hartree-Fock methods are essentially out of reach without significant computational infrastructure. If your system is larger than that, you are better off with fragment-based methods or switching to a linear-scaling package. NWChem does have some linear-scaling DFT options but they are not as mature as the standard implementations.
I have been running these calculations for long enough to know that the program will not save you from your own mistakes. It will run your input exactly as you write it, whether that input describes a stable molecule or a physical impossibility. The outputs are numbers until you understand what they mean, and that part requires actual chemistry knowledge, not just software proficiency.