Working With Chicago Zip Codes to Map the City
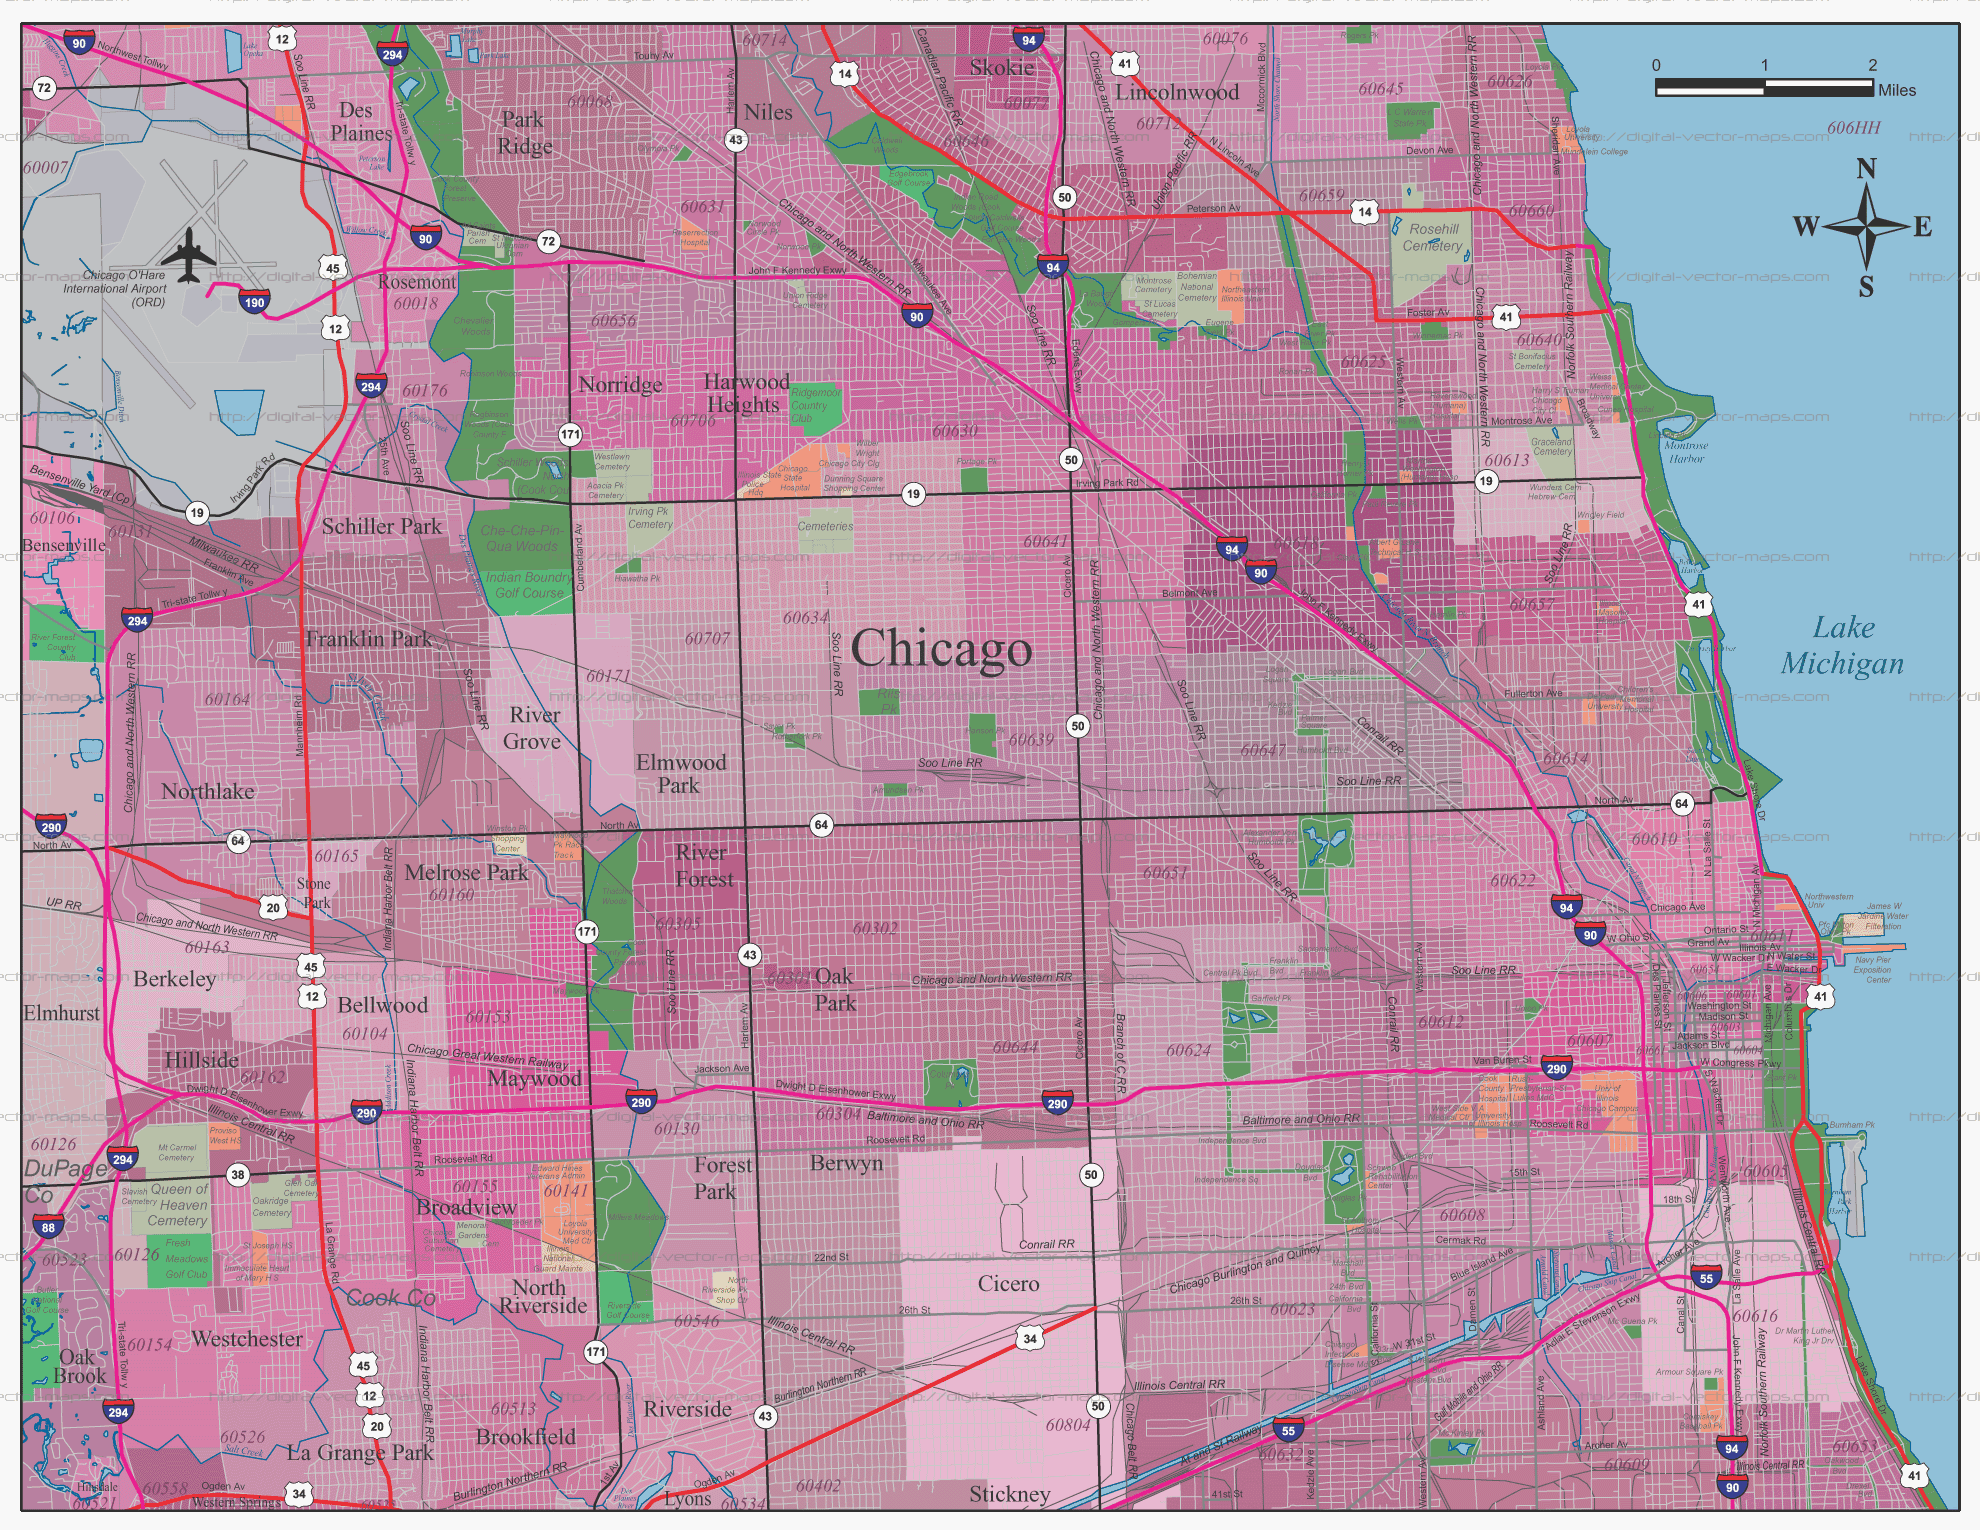
Chicago has 77 official community areas that mostly follow zip code boundaries, but the mapping isn't clean. You can pull zip code data from USPS delivery records or Census blocks and layer it against income, education, and demographic stats to see where the divides actually sit. The trick is knowing which dataset to use and when to stop trusting it. I spent a few years building custom maps of Chicago neighborhoods using zip code tabulation areas from the Census Bureau. It sounds straightforward until you hit the edges where a single zip code covers parts of three different neighborhoods. That happens enough that your analysis will look wrong if you don't check the boundaries against the actual city map first. The American Community Survey is the standard source for block-level economic data. You can get per capita income, poverty rates, educational attainment, and household composition down to the tract level. Most people stop at the zip code tabulation area and treat it like a neighborhood. It isn't. A lot of Chicago zips contain economically mixed areas that smooth out when you look closer.
Where The Data Actually Shows The Divides
South Side and West Side zips consistently show different patterns than North Side zips when you look at median household income. But the gap isn't as stark as general narratives suggest. There are pockets on the South and West Sides with median incomes above $75,000 and sections of the North Side below $40,000. The overall divide is real but it gets oversimplified when you only look at city-wide averages grouped by compass direction. One thing I noticed that doesn't come up in most reports is the role of industrial buffer zones. Areas near the rail corridors and the river tend to have lower property values regardless of which side of town they're on. If you're correlating zip codes with economic health, you need to control for proximity to industrial land. Otherwise you'll misattribute depressed values to neighborhood dynamics when it's really a zoning and transportation factor.
Cultural Markers In The Data
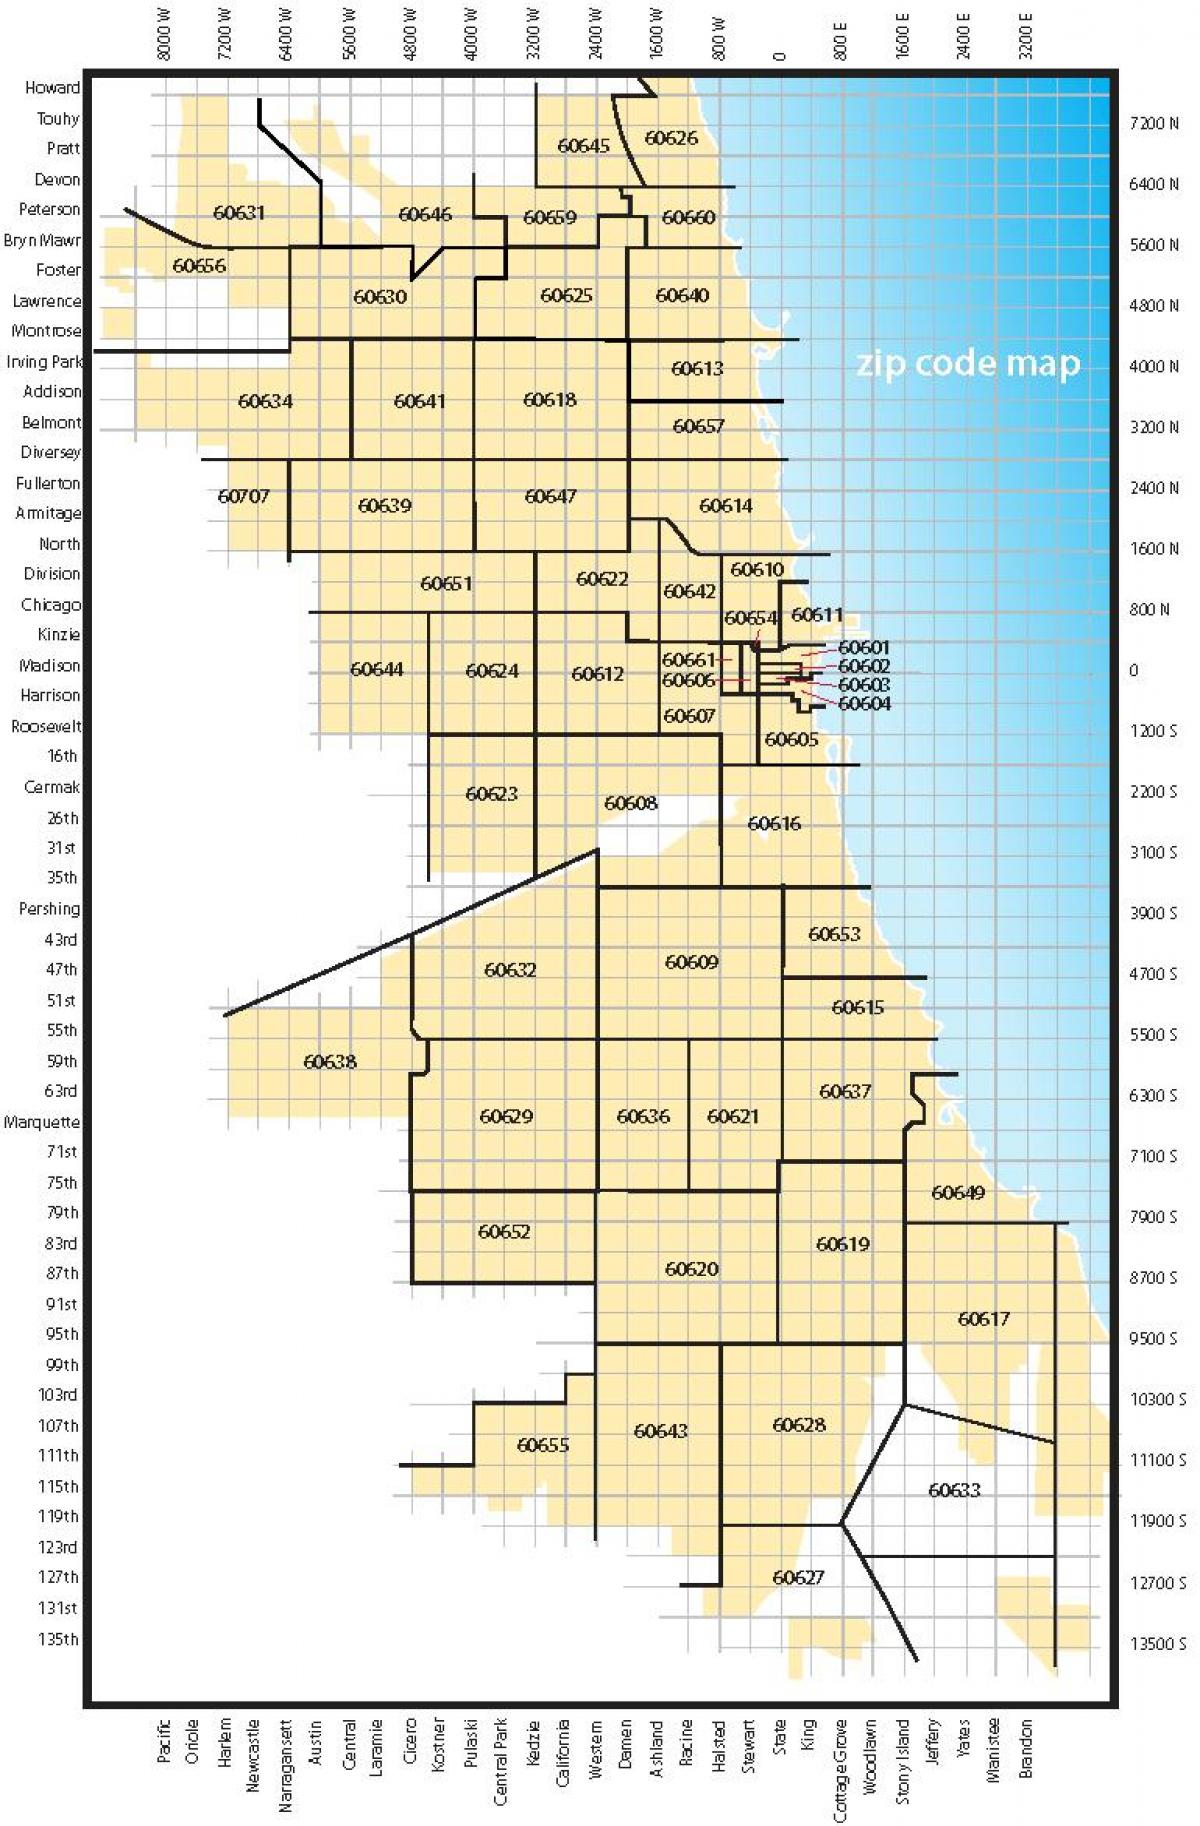
Beyond income, you can look at language isolation, foreign-born population share, and household composition to get a sense of cultural makeup. These aren't perfect proxies but they're the best publicly available indicators. Pulling the numbers for individual zips shows clear clustering along migration patterns from Latin America, South Asia, and Eastern Europe. The clusters don't always line up with what locals would call distinct neighborhoods because the Census boundaries and cultural boundaries are different things. For example, zip code 60632 covers a wide area on the Southwest Side. The data will average everything together. You'd see one median income number and one language isolation percentage for the whole zip. But drive through it and the differences between distinct blocks are obvious. That's why tract-level or block-group-level data matters if you can get it. The Census releases that level of detail and it's downloadable directly from data.census.gov without needing a special account.
Get the Full Details

Getting The Data
You don't need paid software for this. The Census Bureau's data platform is free. The Chicago Data Portal also has pre-packaged datasets on neighborhood demographics and economic indicators that are easier to work with than raw Census files. I usually start with the Data Portal for quick checks and then move to the Census API for custom selections. If you want to build actual maps, QGIS handles shapefiles and tabular joins without costing anything. ArcGIS is overkill unless your organization already pays for it. The learning curve on QGIS is about two weeks of part-time work to get comfortable with it.
Common Mistakes
People often treat zip codes as static. They aren't. USPS redraws boundaries periodically based on mail delivery routes. The changes are usually minor but they can shift a street from one zip to another. If you're comparing data across years, you need to verify the boundaries used in each Census release match up. The Census Bureau provides historical boundary files but they're not automatic. You have to download the right year's shapefile for each time period you're analyzing. Another issue is edge effects at city limits. Some zips extend into suburban municipalities like Evanston, Oak Park, or Cicero. If you filter by city of Chicago in your data query, you'll drop those portions. If you don't, you'll accidentally include suburban data in your Chicago analysis. Either choice changes the numbers enough to matter depending on what you're studying.
What This Approach Can't Do
Zip code analysis won't tell you about gentrification pressure in real time. It reflects past and present conditions but the lag in Census data release means you're often looking at information that's two to four years old by the time it's published. For tracking rapid change, you'd need to supplement with real estate transaction data or permit records from the city. It also can't capture informal economic activity. Cash-based work, under-the-table employment, and informal housing arrangements don't show up in survey data. Neighborhoods with large informal economies will appear poorer than they might actually be in aggregate, or the opposite depending on the type of activity. The data has blind spots that no amount of careful analysis will fully fill. The divide between North and South is real. The data confirms it. But the nuance is in the details between zips and within them, and that's where the actual work happens.