Getting Real Results With Voice Cloning Tools
I spent about three weeks last month working with Got S5 Cast on a project that required replicating a specific voice for a commercial voiceover job. The client had very particular requirements around emotional range and speech patterns, and honestly, most of the tools I'd tried before this fell flat in ways that weren't immediately obvious from the demos. Got S5 Cast handled it, but not without some friction I didn't expect coming in. The core approach here is straightforward enough. You feed it reference audio—ideally clean, unprompted speech in the target language—and the model builds a voice profile. From there you can generate new dialogue in that voice. The S5 Cast variation seems to lean harder on capture data rather than purely synthetic training runs, which matters more than you'd think when you're dealing with non-professional source material.
Unlocking Authenticity With Got S5 Cast Redefining Voice Replication In The Digital Age
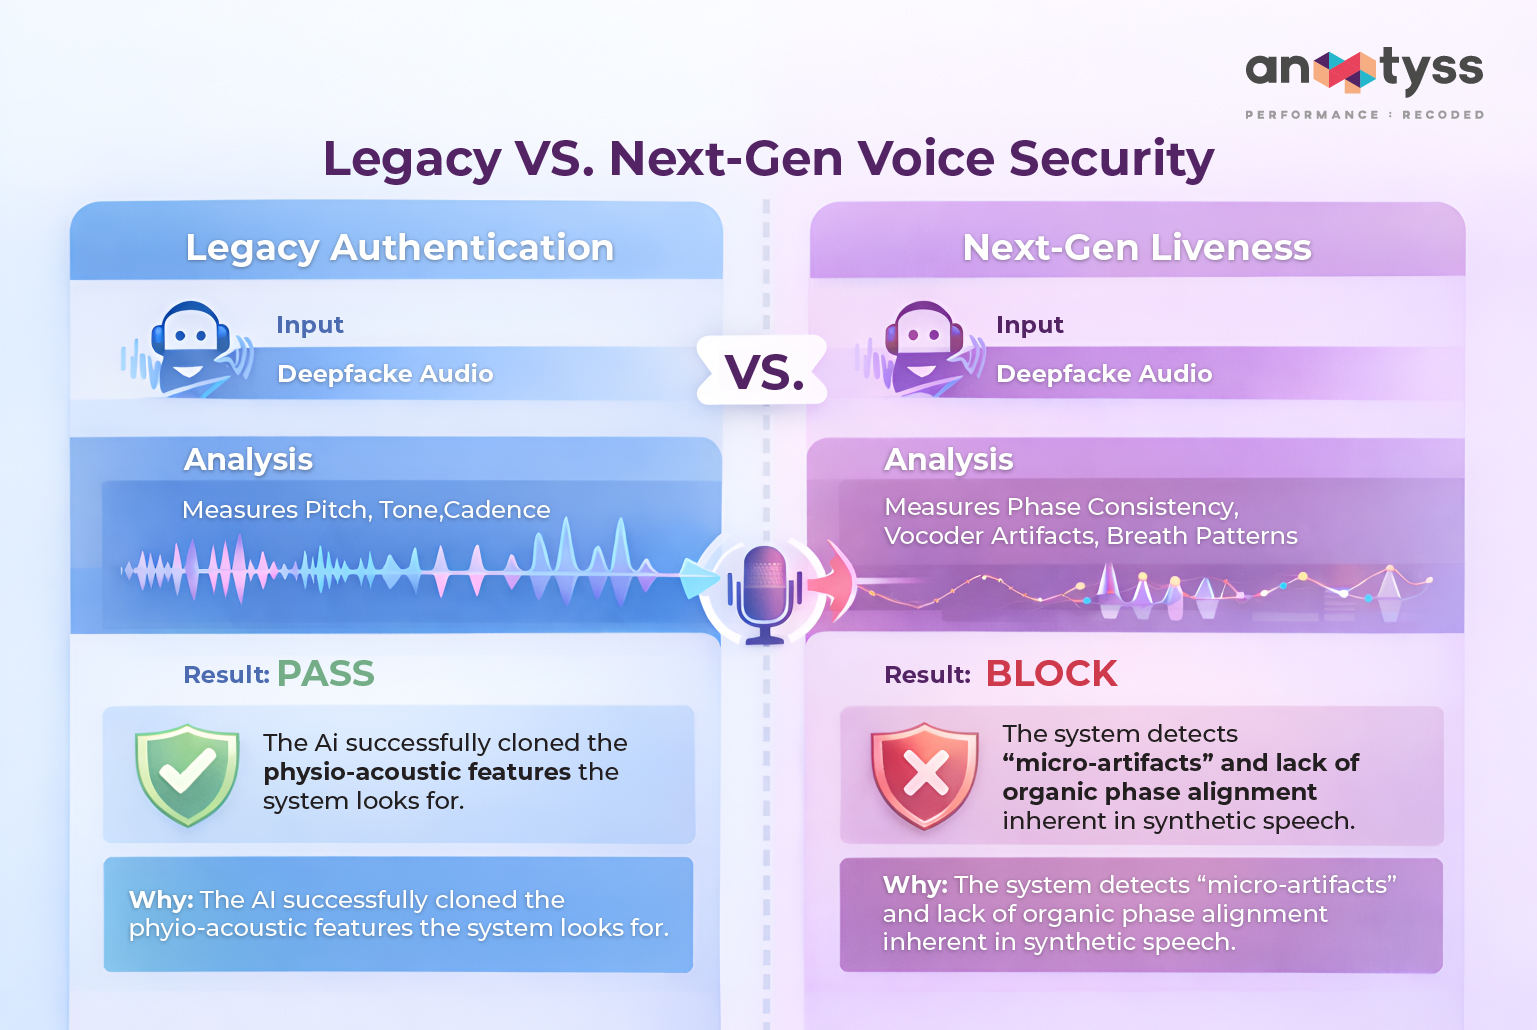
What separates the tools that sound plausible from the ones that actually pass a listen test isn't just the quality of the voice itself. It's the prosody—the rhythm, the breath patterns, the slight hesitations that make speech feel human. Got S5 Cast appears to preserve more of these micro-variations than some alternatives I've tested, though the results depend heavily on your source material. I ran into a specific edge case that almost cost me the project. The reference audio I was given had noticeable background noise—a low hum from an HVAC system and some faint room reverb. The initial generations came back sounding correct on paper, but every time I listened closely, there was this metallic undertone that just felt wrong. I'd never noticed that artifact before, but once it was in my ears, it was impossible to unhear. The workaround was simple but not obvious if you haven't encountered it. I fed the raw audio through a preprocessing step using a spectral subtraction plugin to strip out the background hum, then ran it through a room impulse response cleanup to dry out the reverb. Took maybe twenty minutes I hadn't budgeted for, but the subsequent generations were clean. I ended up keeping a copy of the noisy version in the project folder just so I could verify exactly what the artifact sounded like before and after processing. Sometimes you need to hear the problem to know you fixed it.
The technical side of this is worth understanding at a basic level. The model uses mel-spectrogram inversion to map the reference voice characteristics onto generated output. That means the quality of your spectrogram directly determines the quality of the result. No amount of post-processing can fix garbage input, and this is where most people get tripped up. They find a sample audio online, run it through without any preparation, and then blame the tool when the output sounds flat or distorted. Here's something nobody really talks about: the length of your reference audio matters more than most guides admit. Got S5 Cast can technically work with clips as short as ten seconds, but anything under thirty seconds tends to produce voices that sound consistent only for short bursts. Once the generated output extends beyond a few sentences, the prosody starts drifting and you get that telltale robotic fatigue. I found that sixty to ninety seconds of clean, varied speech gave me the best results across all my test cases. Not longer—longer sessions introduced redundancy that the model sometimes replicated in unwanted ways. There are also some limitations that are worth being upfront about. The tool struggles with heavy accented speech if your reference material doesn't match the accent profile. I tried generating content with a regional accent that differed from my source reference, and the output defaulted to the reference accent almost every time. The model essentially locks onto the phonetic patterns it learned during profile building and won't deviate from them without significant manual intervention. If your project requires accent flexibility, you may need to maintain multiple voice profiles rather than trying to stretch one.
Get the Full Details
Another thing to watch out for is the emotional range. Got S5 Cast handles neutral conversational speech quite well, but push it into high emotion—anger, grief, intense excitement—and the output can start to break down. The model doesn't yet have a reliable mechanism for mapping emotional intensity onto vocal characteristics in a way that sounds natural. I've seen workarounds involving layering generated audio with carefully selected real vocal takes for the emotional peaks, but that's more of a production technique than something the tool does natively. If you're just starting out with this kind of work, I'd recommend building a test workflow before committing to anything production-level. Grab a short passage of text, run it through with your reference audio, and listen back critically. Don't just check whether it sounds like the right voice—listen for whether it sounds like someone actually saying those words. There's a difference that's easy to miss on a first pass but obvious once you know what to look for. The community around this tool isn't huge, which means you won't find exhaustive troubleshooting guides for every scenario. A lot of the practical knowledge lives in Discord channels and forums where people share their preprocessing chains and parameter tweaks. If you hit a wall, searching for your specific issue alongside terms like "Got S5 Cast reference audio" or "voice cloning prosody drift" tends to surface relevant threads. The information scattered across those places is often more useful than whatever official documentation exists.
For anyone considering this for commercial work, there's also the question of sourcing. Make sure you have proper rights to the voice reference material. I've seen this oversight cause real problems for production teams who assumed they were clear to use publicly available audio samples. It's a legal question, not a technical one, but it's one that can shut down a project faster than any software limitation. The broader shift here is toward voice replication becoming accessible to people who aren't professional audio engineers. That's a good thing in most cases, but it also means the barrier to producing something that sounds authentic has dropped significantly. The challenge now is less about the technology itself and more about knowing how to use it responsibly and effectively. The tool will do what it does. What you do with the output is where the actual work happens.