Getting Started With the OpenAI ChatGPT API
Reading the official documentation is necessary but not enough. The docs cover what the API does, not what actually happens when you try to integrate it into a production system at 2 AM. I spent about three weeks debugging a deployment that worked perfectly in the sandbox and broke immediately in production. The problem wasn't the model, the prompt, or the authentication. It was streaming responses not being handled correctly across our load balancer. We were treating the API like a synchronous HTTP call when it was actually a server-sent events stream. That mismatch caused silent failures that looked like model issues but were purely infrastructure. If you are just starting out, go to platform.openai.com and create an account. Generate an API key from the dashboard. Install the official SDK with pip install openai if you are using Python. The documentation is at platform.openai.com/docs. The URL alone is boring but accurate. Everything else builds from there.
Unlocking AI Integration Master The ChatGPT API Documentation For Developers
The core concept most people miss is the difference between chat completion and fine-tuning. The chat endpoint handles conversational context through message arrays. You send a list of messages with roles like system, user, and assistant. The model maintains that context window and responds. That is the basic flow. Fine-tuning is separate. You upload training data, wait for the job to complete, then reference the resulting model ID in your requests. They are not interchangeable. A common mistake is trying to use a fine-tuned model for tasks that require broad general knowledge. The fine-tuned model will be better at your specific output format but weaker on things outside its training distribution. Here is a minimal example that actually works: import openai
client = openai.OpenAI(api_key="your-key")
response = client.chat.completions.create(
model="gpt-4o-mini",
messages=[
{"role": "system", "content": "You are a technical support agent."},
{"role": "user", "content": "My printer won't connect to Wi-Fi."}
]
)
print(response.choices[0].message.content)
This returns a JSON object. The content is in response.choices[0].message.content. That field can be null if the model refuses to answer or hits a safety filter. Always check for that before calling .strip() or anything similar. I have seen production code crash on null values because nobody thought to handle refusal cases explicitly. Pricing is per token. Input tokens cost less than output tokens on most models. GPT-4o mini is around $0.15 per million input tokens and $0.60 per million output tokens as of my last check. The math matters more than you think. A simple script that generates 500 words per request and runs ten times an hour will burn through budget fast if you do not track usage. Enable usage dashboards and set spending limits in the billing section before you integrate. It takes two minutes and prevents a surprise bill. Rate limits are another area where people get blindsided. The free tier allows roughly three requests per minute. Paid tiers scale up but still have per-minute and per-day caps depending on your account level and usage history. If you hit the limit, the API returns a 429 error with a Retry-After header. You should implement exponential backoff on retries. A simple retry loop with a base delay of two seconds, doubling on each attempt, and capping at thirty seconds handles most cases. I once wrote a script that hit the limit during a batch process and just kept failing silently for forty minutes because there was no retry logic. The data eventually came through but I lost almost an entire day debugging what I thought was a model issue.
Get the Full Details

Streaming responses cut perceived latency significantly. Instead of waiting for the entire completion, you receive tokens as they are generated. This is useful for chat interfaces and tools where users benefit from seeing output in real time. Here is how it looks in practice: stream = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Explain quantum computing."}],
stream=True
)
for chunk in stream:
delta = chunk.choices[0].delta.content
if delta:
print(delta, end="", flush=True) The key detail here is that each chunk does not guarantee a complete word. You might get partial tokens. If you are building a display that shows output character by character this is fine. If you need to parse structured output from a stream, do not attempt it. Buffer the full response first, parse it, then display. Parsing mid-stream is unreliable and creates more bugs than it solves.
Temperature controls randomness. A value of zero produces deterministic output. One increases variation. The documentation recommends 0.7 for creative tasks and lower values for factual queries. This is correct but incomplete. Temperature interacts with top_p, which controls nucleus sampling. Setting both too high creates inconsistent outputs that drift from your intended format. If you need JSON output or structured responses, set temperature to 0 and use response_format with a JSON schema. The model is significantly more reliable at following formatting constraints when randomness is removed. System messages are not instructions the model reads once and forgets. They are part of every request. They shape behavior across the entire conversation. A poorly written system prompt can cause the model to ignore user constraints entirely. I had a case where a system prompt told the model to be concise and the user kept getting paragraphs. Changing the system message to specify a maximum sentence count fixed it. Specificity in system prompts matters more than length. Five precise sentences beat fifty vague ones every time. Function calling is one of the more powerful features and the one most developers underutilize or misuse. You define tools with JSON schemas and the model decides when and how to call them. It returns a function call object instead of plain text. You execute the function on your side and pass the result back. The model then generates a final response using that result. This turns the API into an orchestration layer rather than just a text generator. The documentation covers this well. The tricky part is handling errors from your own functions. If your tool raises an exception, catch it and send the error message back as a tool response. The model can work with error information and adjust its next step accordingly. Skipping this step means the conversation breaks and you lose the context.
Token counting is essential for cost control. The openai library includes a tiktoken module for this. The quickratio tokenizer approximates token counts for most GPT models. Use it before sending requests to estimate costs. A rough rule: 100 tokens is about 75 words. Long documents balloon quickly when you include the system message, conversation history, and output tokens all together. I usually cap my context windows at 8,000 tokens for standard tasks. Anything larger requires rethinking the architecture, not just bumping the model size. There are scenarios where the ChatGPT API is the wrong tool. If you need low-latency inference under 200 milliseconds, the API adds network overhead that makes it unsuitable. Local models or edge deployment are better there. If your use case involves highly regulated data that cannot leave your infrastructure, cloud APIs are a compliance risk regardless of their security posture. Fine-tuned open-source models running on your own hardware solve both problems but require maintenance that most teams underestimate. Know when to walk away from the API. The documentation updates frequently. New models appear, old ones get deprecated, and parameters change. Check the release notes page before integrating anything time-sensitive. I integrated a feature using a parameter that was labeled as stable in the docs and got deprecated two weeks later. It required a code update and a redeploy. Not catastrophic but avoidable.
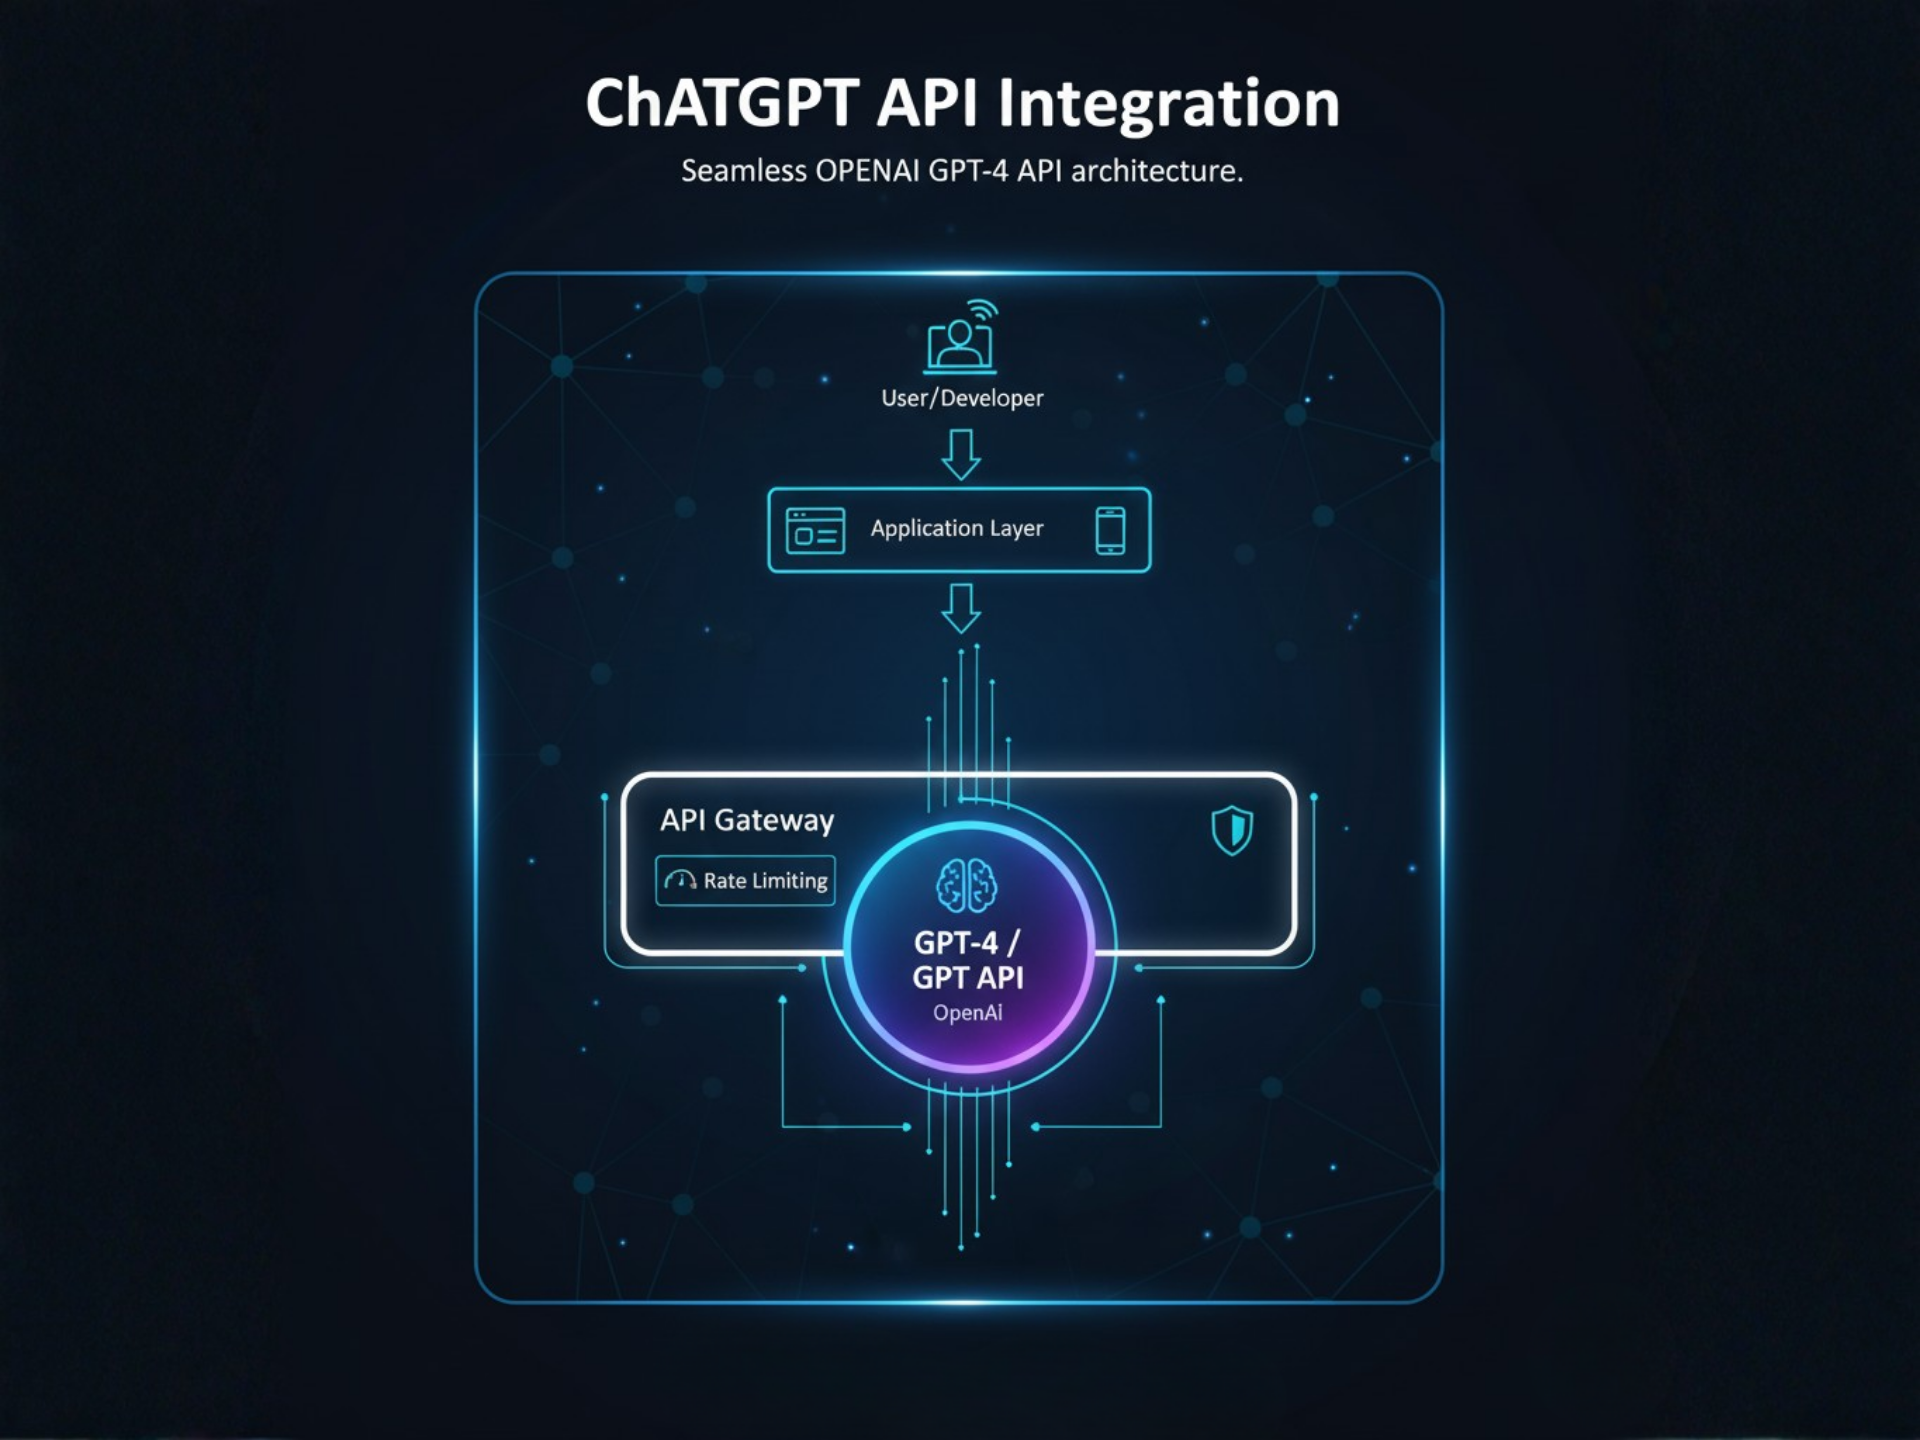
Authentication uses bearer tokens in the Authorization header. Never embed API keys in client-side code. Frontend applications should route requests through a backend service that holds the key. There are workarounds using proxy servers but they add complexity and attack surface. Keep the key server-side. Rotate keys periodically through the dashboard. Revoke any that look suspicious. The dashboard shows recent key usage including IP addresses and user agents, which helps detect leaks quickly. Logging should capture request metadata without storing sensitive content. Record the model used, token counts, latency, and error codes. Do not log the actual messages or responses unless you have explicit user consent and proper data handling policies. Storing prompt data creates privacy and compliance obligations you may not want. Error handling deserves more attention than it gets. The API returns standard HTTP status codes alongside OpenAI-specific error types. A 400 means bad request, usually malformed JSON or missing required fields. A 401 means authentication failure, often a revoked or expired key. A 429 means rate limit exceeded. A 500 means the server had an internal issue. Map each code to an appropriate action. Retries for 429 and 500. User notifications for 400. Key rotation prompts for 401. Most errors resolve themselves on retry. The few that do not need user intervention.
The learning curve is shallow for basic integration. The steep part comes from understanding context management, cost optimization, error recovery, and when the API fits your architecture versus when it does not. Read the docs. Build something small. Break it intentionally to see what fails. Then scale from there.