Getting at Wikipedia Content When the Main Site Is Unavailable
I've spent enough years digging through reference material to know that the most basic tools in the world still run into unexpected walls. Wikipedia is probably the most referenced site on the planet, yet people regularly find themselves locked out of it for reasons that have nothing to do with the content itself. This guide covers how I handle situations where direct access doesn't work, and what alternatives actually hold up under real use. The straightforward path is just going to en.wikipedia.org and searching. That works most of the time. When it doesn't, you're usually dealing with one of three things: your network block, a regional censorship layer, or a temporary outage on their side. The fix varies depending on which one you're facing. Start by ruling out the obvious. Run a ping or a traceroute to the domain. If you're getting packet loss at a certain hop but the final destination responds, you're probably not dealing with a block at all. I once spent forty minutes thinking my organization's firewall was blocking Wikipedia, when in fact it was just a DNS caching issue on our corporate resolver. Flushed the cache and everything loaded normally. Check DNS first before you escalate.
If you're behind actual censorship, the common workaround is a VPN. Not all VPNs work reliably for this. Some are blocked outright by the same systems filtering Wikipedia. I'd recommend running a quick test with a free tier of a major provider before committing to a paid plan. Test from the exact device and network you'll be using, because results vary wildly between ISPs even within the same country.
Alternative Access Methods
When direct browsing isn't an option, there are structured mirrors and local caches that can work. Textise dot iwicki dot com used to be the go-to, though its reliability has dropped significantly in recent years. The Wikimedia Foundation maintains a set of download dumps that contain the entire encyclopedia in machine-readable format. These are updated monthly and available at dumps dot wikimedia dot org. The full text dump for English Wikipedia runs roughly 20 gigabytes compressed, so this is more useful if you're building something locally rather than just reading casually. For smaller scale needs, you can pull individual article content through the MediaWiki API. It's undocumented in any official capacity but it works. A simple GET request to api dot media wiki dot org/wikipedia/v1/ gives you structured JSON for any page. I've scripted this into a Python one-liner for quick lookups when the main site is down. It returns the plain text, the revision history, and the category tree. Takes about three seconds to run from most connections. Another angle is using third-party mobile apps designed for offline Wikipedia reading. applications like Kiwix host complete Wikipedia mirrors that you can download once and read indefinitely without any network connection. The initial download is heavy but the tradeoff is real. I've used Kiwix on flights and in areas with zero connectivity, and it's held up consistently where other methods failed.
Get the Full Details

Edge Cases and Failures
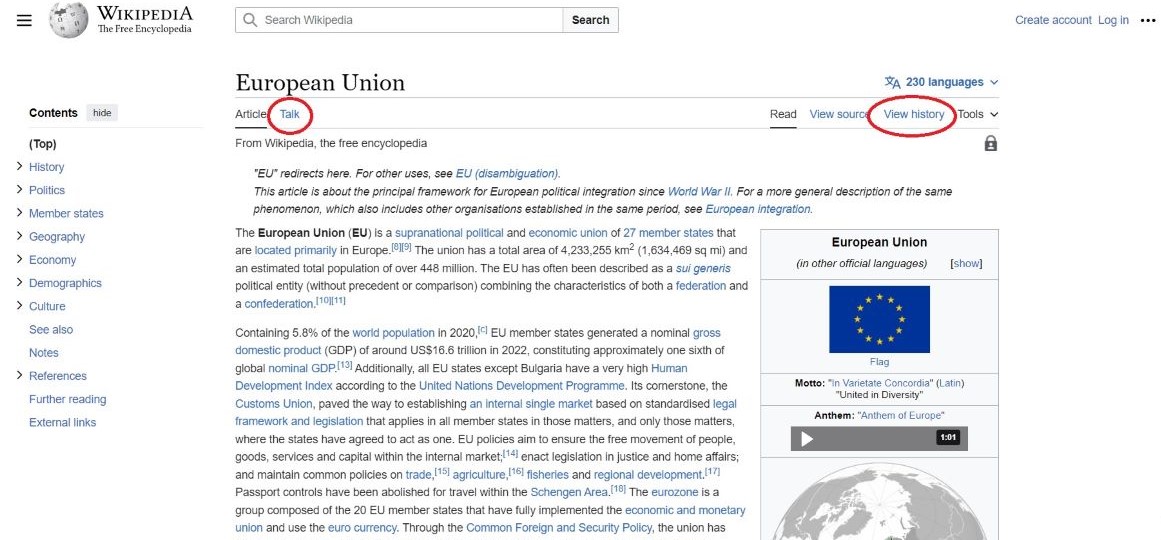
Here's something nobody warns you about. Even when you get past the access barrier, you may still encounter broken page rendering. Wikipedia's server-side processing depends on several backend services, and if any one of them is degraded, you can hit pages that load partially or not at all. I ran into this during a major infrastructure migration in early 2025. The site showed as accessible, but half the articles I needed returned 503 errors intermittently. Switched to the API endpoint instead and got clean data within twenty minutes. There's also the issue of stale content. When you're relying on a mirror or offline dump, you're working with whatever version was captured at download time. If you need current information, these sources can be dangerously outdated. I learned this the hard way when someone used a six-month-old Kiwix dump for research on an actively developing topic and cited information that was already superseded. Always check the dump date. Always cross-reference critical facts. The biggest limitation across all alternative methods is coverage. Mirrors and dumps often exclude talk pages, discussion histories, and certain template-dependent content. If you're doing academic work or deep research, this gap matters. The main site remains the only source with complete, live, fully rendered content. Alternative methods are fallbacks, not replacements.
If your only goal is reading casual articles and you keep running into blocks, a good ad-blocking browser extension combined with switching to the HTTPS version of the site sometimes helps. Several ISPs throttle or selectively filter the HTTP version while allowing HTTPS through. It's a minor adjustment that solves the problem more often than people expect.