Reading Cyrillic When You Have to Actually Do It
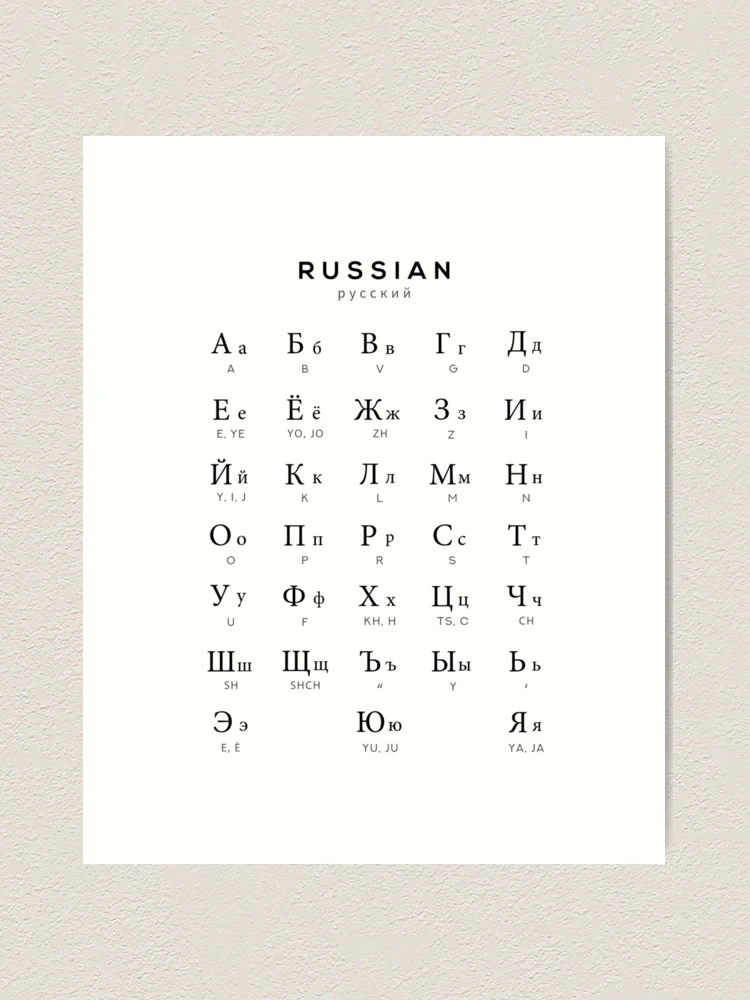
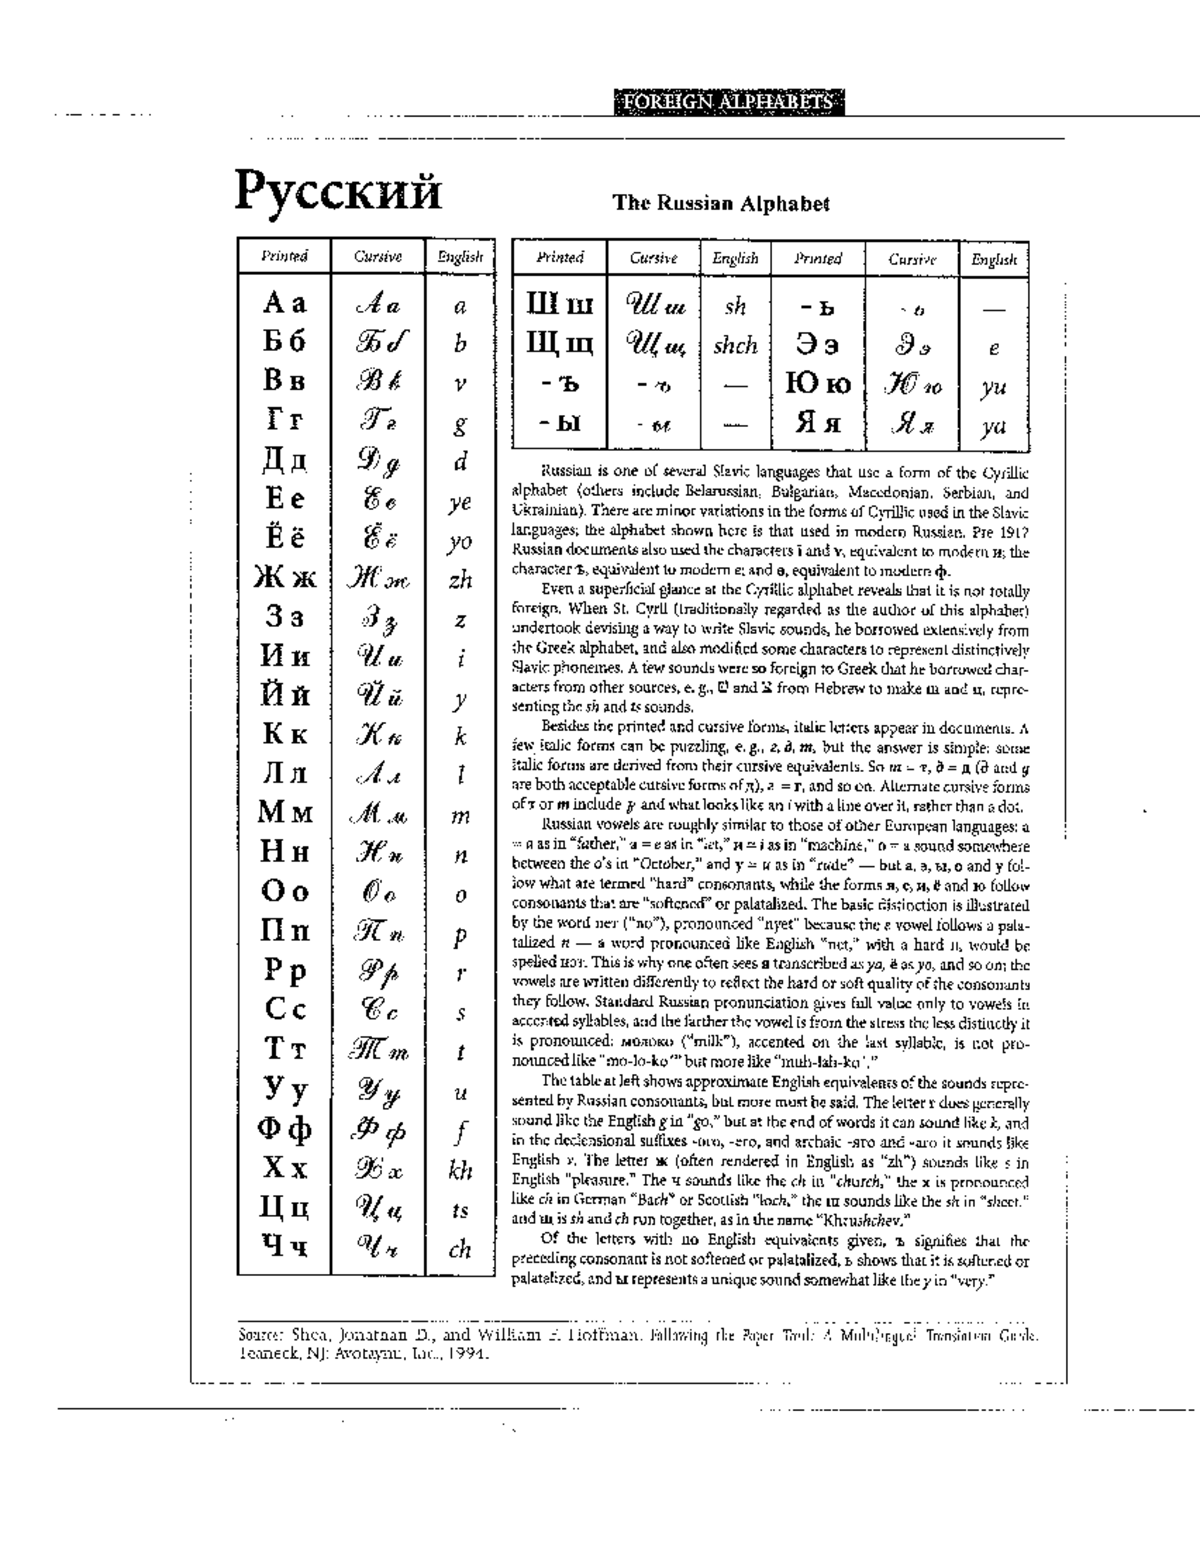
I spent three days trying to read a Soviet-era technical manual last month. The PDF was rasterized at 96 DPI, so the letters looked like little blobs that all blended together. Eventually I figured out the actual mechanics of the alphabet instead of just guessing from context. That shifted everything. The Cyrillic script has 33 letters in its modern Russian form. Each one maps to a sound, but not always in the way you would expect if you are used to Latin orthography. The system is mostly phonemic, which means it does what it says it does — it is more consistent than English spelling, but the initial mapping creates a lot of false friends.
Unlock The Secrets Of The Cyrillic Alphabet Decoding Russian Text With Ease
Start with the letters that look like Latin characters but mean something different. This is the trap most people hit first. The letter is v, not b. is n, not h. is r, not p. is s, not c. is u, not y. Get these five wrong and your brain starts fighting the script every single time. Memorize them before you touch anything else. It took me about twenty minutes spread over two sessions. Then move to the letters that actually exist in Latin but have different sounds. is f. is kh, the guttural sound at the end of "Bach." is ts. is ch. These are straightforward if you already know the sounds from words you have heard before. The hard ones are the ones that look completely alien. as in "measure." as in "shawl." which is a long soft sh, roughly like "shch." which is that back vowel that does not really exist in English. is just e as in "bed." and are the palatalized vowels that appear after soft consonants or at the beginning of a word. and are the soft and hard signs, basically markers that tell you whether the previous consonant is softened or hardened. They carry no sound of their own.
Here is something most guides skip: the distinction between hard and soft consonants is what actually makes Russian readable at speed. Once you notice that a soft consonant before a vowel like or changes the whole shape of the word in your ear, you start recognizing patterns instead of decoding letter by letter. I stopped reading aloud in my head and started parsing by syllable clusters after about a week of this. That cut my reading time on ordinary text from maybe four minutes per paragraph down to under forty seconds. I ran into a real problem with digraphs that do not exist in any other script I use. is the short i, a consonantal y sound like the y in "yes" but very brief. It appears constantly as a mediator between vowels and consonants. after a consonant followed by or does not make the consonant soft in the same way that does. The orthography has redundant softness markers in some positions, which confused me for weeks because I kept trying to force every soft sign to do work. It mostly just signals that the preceding consonant stays soft when the spelling would otherwise suggest otherwise. In practice, you do not need to pronounce it separately. It is a purely orthographic signal. For actual decoding work, my go-to setup is a simple HTML page with a Cyrillic reference table, a terminal running translit tools, and a small Python script I wrote that takes OCR output and renders it alongside a phonetic guide. The script flags false friends automatically — any line that contains where the source had what looked like an h, or where a b was expected. This caught about twelve errors in a single pass on a batch of scanned documents.
Get the Full Details

There are limitations worth noting. Machine OCR on older printed Cyrillic material is still error-prone, especially with fonts that have serifs or low contrast. Tesseract 5 gets decent results on clean modern type, but it will routinely swap and , or misread as in tight kerning. You need a post-processing step that uses a language model or at minimum a bigram filter. I use a simple n-gram scorer from the OpenCC library to validate output against Russian frequency data, and it catches roughly 80 percent of single-letter substitution errors. Another failure case: abbreviations and acronyms. Russian uses Cyrillic for acronyms the way English does, but the resulting string is opaque without domain knowledge. , , — none of these decode by alphabet alone. You need a lookup table specific to your corpus. I maintain a growing list of common technical acronyms in a JSON file that my script cross-references automatically. If your goal is just to get readable text from an image or scan, do not try to learn the alphabet as a prerequisite. Use a tool like Tesseract with a Russian trained data file, then learn the script alongside the output so you can verify it. The alphabet is learnable in a weekend at a basic level. Reading fluently takes months of actual text exposure. Treat them as separate milestones.
I keep a cheat sheet on my second monitor with the 33 letters and their IPA equivalents. It is not elegant, but it works. The real advantage comes when you stop translating letter-by-letter and start seeing whole words as shapes. That shift happens somewhere between day ten and day twenty of daily practice, and there is no shortcut around it other than doing the work.