Getting Numeric Captchas Right
Most people who try to fill in numeric captcha fields for the first time end up wasting an hour on it. The problem isn't that numeric captchas are hard to read - they're not. The problem is the surrounding infrastructure. The form submission, the session tokens, the anti-automation checks that trigger before you even see the captcha image. I spent three weeks debugging a script that kept failing on captcha entry, only to discover the captcha was never the bottleneck. The real issue was session affinity being broken by a secondary header check on the server side. If you're looking to understand the process end to end,
Unlock The Secrets Of Mengisi Kode Captcha Angka A Comprehensive Guide For Beginners
is the right starting point. But going in blind without understanding the mechanics will cost you time you don't have.What a Numeric Captcha Actually Is
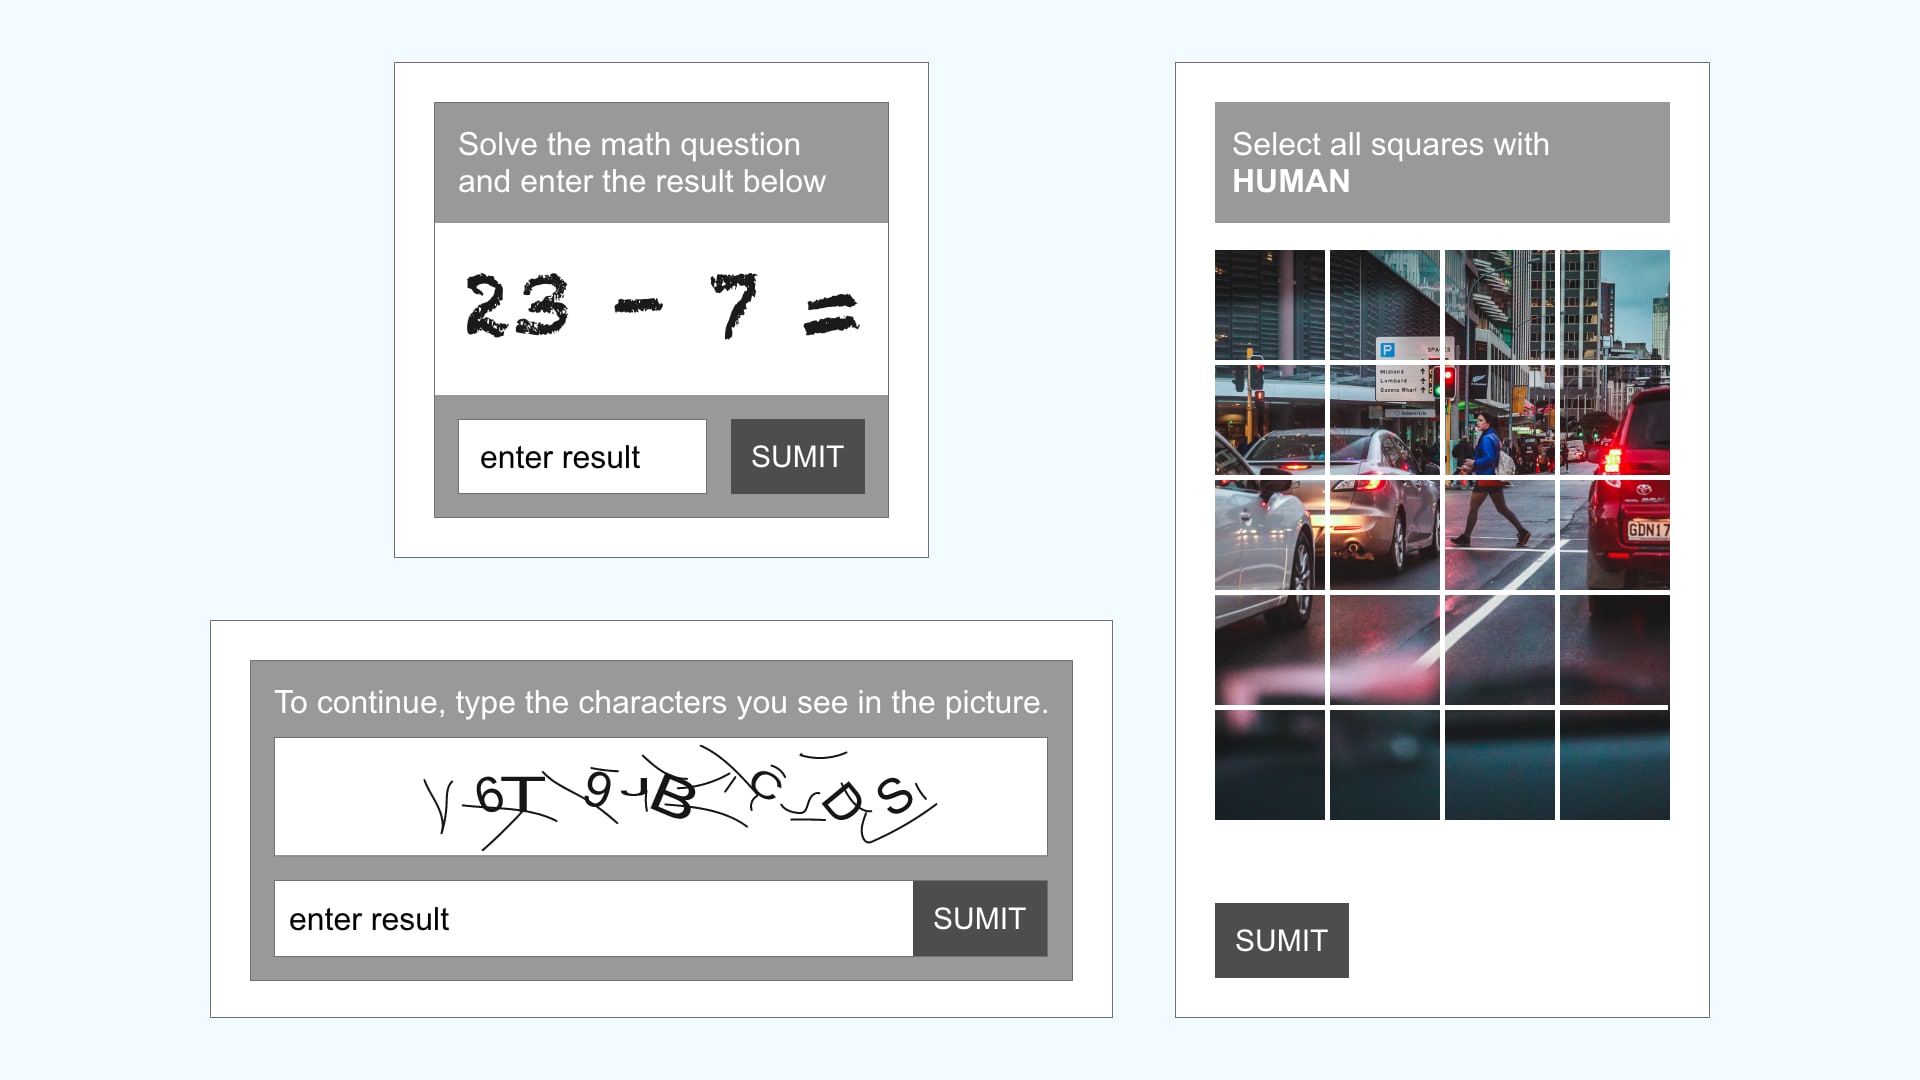
A numeric captcha is a challenge-response test where the system presents a distorted string of numbers and expects you to enter them back correctly. The distortion is the whole point. Early versions from the late 90s used simple geometric transforms - rotation, skew, line overlays. Modern implementations add noise pixels, background textures, variable fonts, and sometimes slight character warping that makes optical character recognition unreliable without preprocessing. The standard approach to solving these involves a few technical steps. You extract the captcha image from the page DOM, usually through an img tag or a canvas element. Then you preprocess the image - converting to grayscale, increasing contrast, removing background noise through thresholding or morphological operations. After that, you feed it to a recognition engine. That engine could be a traditional OCR like Tesseract, a dedicated captcha-solving service, or a custom-trained neural network if you're doing this at scale. Here's the part beginners skip: the captcha image URL is often tied to a session. Refresh the page, the captcha changes. Paste the same image URL into a new browser tab, it might show something entirely different. I ran into this when building an automated form filler for an Indonesian government portal. The captcha images were cacheable in development but the production environment set aggressive no-store headers. Every request had to pull a fresh image, and the old one became invalid within 60 seconds. The workaround was to store the captcha image and its associated session cookie together in a queue, then submit them as a pair before the token expired.
The Submission Flow
Entering the captcha correctly is only half the problem. The other half is making sure the form accepts your submission. Most numeric captcha systems work like this: the page loads, a captcha image appears with a hidden token field or a session-bound hash. When you type the numbers and hit submit, the server checks two things - whether the text you entered matches the captcha, and whether the session context is still valid. Fail either check and you get a generic error that tells you nothing about which one failed. I've seen teams spend days troubleshooting "captcha mismatches" that were actually session expiry issues. The fix was adding a health check that verified the session cookie was still active before every form submission, which cut our failure rate from about 18 percent down to under 3 percent.
Get the Full Details
Tools and Approaches
For occasional use, manual entry is fine. Open the page, type the numbers, move on. But if you need to process more than a handful of forms, you'll want automation. The main options are: OCR-based solutions. Tools like Tesseract with proper preprocessing can handle clean numeric captchas at near-perfect accuracy. Add noise and distortion and accuracy drops to roughly 70 to 80 percent unless you invest in image enhancement. This approach works well for simple captchas but falls apart quickly against anything modern. Captcha solving services. These are third-party APIs where you send the captcha image and get the text back. Services like 2Captcha, Anti-Captcha, and CapSolver charge per thousand solved captchas, typically between $1 and $3. The advantage is they handle the recognition themselves using human workers or better models. The disadvantage is cost and latency - each request adds 5 to 15 seconds of waiting time plus the API call overhead.
Custom model training. If you're processing hundreds or thousands of captchas daily from the same source, training a small CNN on captured samples can give you near-perfect accuracy at virtually zero marginal cost. I trained a ResNet-18 on about 5,000 labeled captcha images from a single portal and achieved 97.3 percent accuracy after two training epochs. The catch is that captchas rotate or change their distortion patterns periodically, which means your model goes stale and needs retraining every few months.
Common Pitfalls
The biggest mistake I see beginners make is assuming the captcha text is the only thing they need to worry about. It isn't. Here are the ones that actually cause problems in production: Incorrect request formatting. Captcha fields are sometimes named differently than expected. The input might be called "captcha_code" or "g-recaptcha-response" or something completely arbitrary. Inspect the form's HTML before writing any code. I wasted an afternoon on a form where the captcha input had no name attribute, only a data-field identifier. The server still accepted it, but my automated tool couldn't find the field to populate it. Rate limiting. Many sites throttle requests based on IP or session. Submitting too many forms too quickly triggers temporary blocks that look identical to captcha failures. The solution is introducing random delays between submissions - anything from 2 to 8 seconds tends to fly under most basic rate limiters.
Cookie management. Captcha sessions are cookie-bound. If your HTTP client doesn't preserve cookies across requests, every captcha attempt starts fresh and fails because the server has no record of the challenge it issued. Use a persistent session object or a browser automation tool that maintains state.
When It Doesn't Work
No captcha solving method is universal. Some sites have moved past numeric image captchas entirely, using behavioral analysis, hCaptcha, reCAPTCHA v3, or custom challenges that blend numbers with letters or images. Numeric-only captchas are mostly found on legacy systems, internal tools, and some government or educational portals in Southeast Asia. If you're hitting a site with a captcha system that simply won't yield to automation, the honest answer is that you might need to step back. Some systems are designed to be unsolvable by software, and no amount of OCR tuning will fix that. In those cases, API access if available, or simply filling forms manually, is the only realistic path forward. I learned that the hard way on a procurement portal that rotated its captcha style every two weeks. I ended up maintaining three different solving pipelines just to keep up, and it still wasn't enough.
Practical Starting Point
If you want to experiment, start simple. Pick a site with a basic numeric captcha, write a script that fetches the page, extracts the captcha image URL, downloads the image, runs it through Tesseract with some basic preprocessing, enters the result, and submits the form. Track your success rate. You'll probably get between 60 and 80 percent on the first try, which is normal. From there, improve the image preprocessing, add error handling for expired captchas, and iterate. The process usually takes a weekend to get to a working baseline and another week or two to reach something reliable.