What Deephotlink Actually Does
Deephotlink is a bridge tool. It lets you host, share, and access content that lives on dark web hidden services from a regular browser. The core idea is simple enough that people overcomplicate it: you paste a .onion address, the tool routes your request through Tor, and returns the content to you over clearnet. That's the pitch anyway. The reality is messier. I've been working with dark web infrastructure for about seven years now, mostly on the retrieval and archival side. Deephotlink came up in conversations because it promised a cleaner user experience than manually configuring Tor browsers or running your own exit nodes. It's not magic. It's just a proxy layer with a UI.
How It Works Under The Hood
When you submit an onion URL to Deephotlink, their server resolves it through their Tor relay chain, fetches the response, and then serves it back to you over HTTPS. They handle the circuit building, the handshake, the retry logic. You just get HTML or whatever the target service returns. Most people skip reading the documentation and try to use it for everything. That's the first mistake. Deephotlink was designed primarily for read-only access to public onion services. If you're trying to post, upload, or authenticate against a hidden service, the tool falls apart fast. The architecture doesn't support stateful sessions well across the proxy boundary. You'll lose cookies, break form submissions, and waste about twenty minutes before you figure out why your login keeps failing.
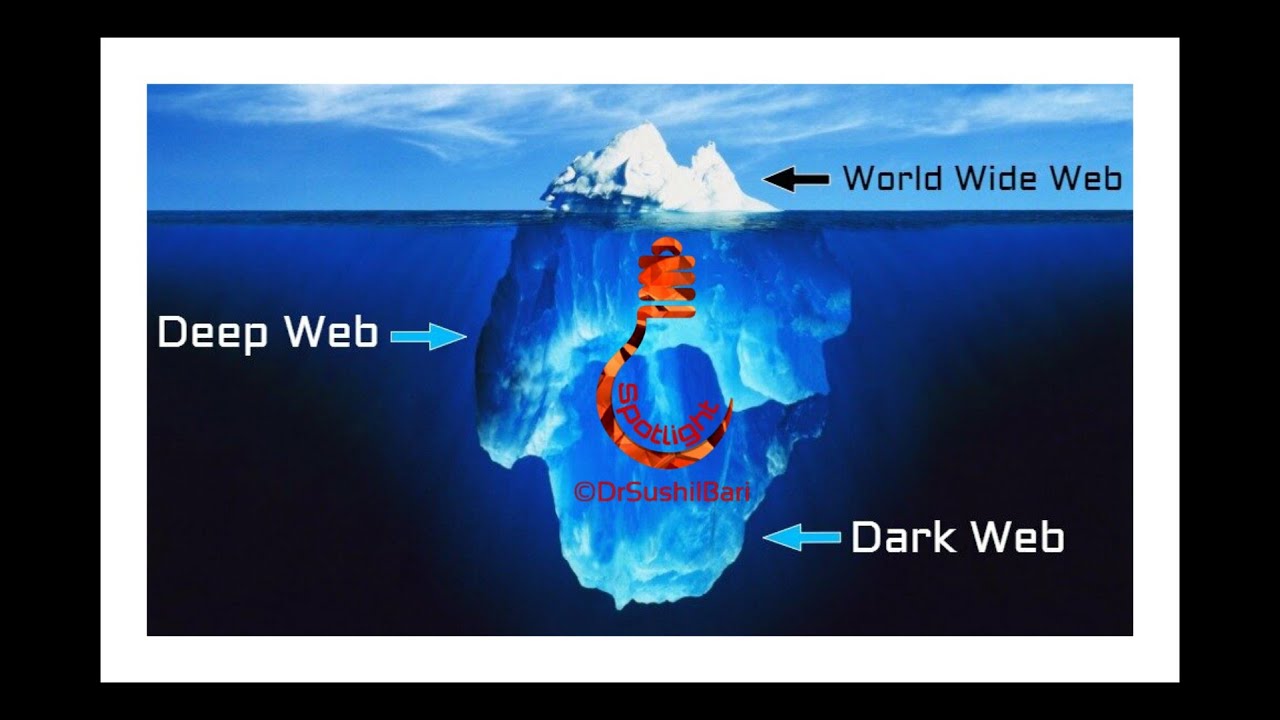
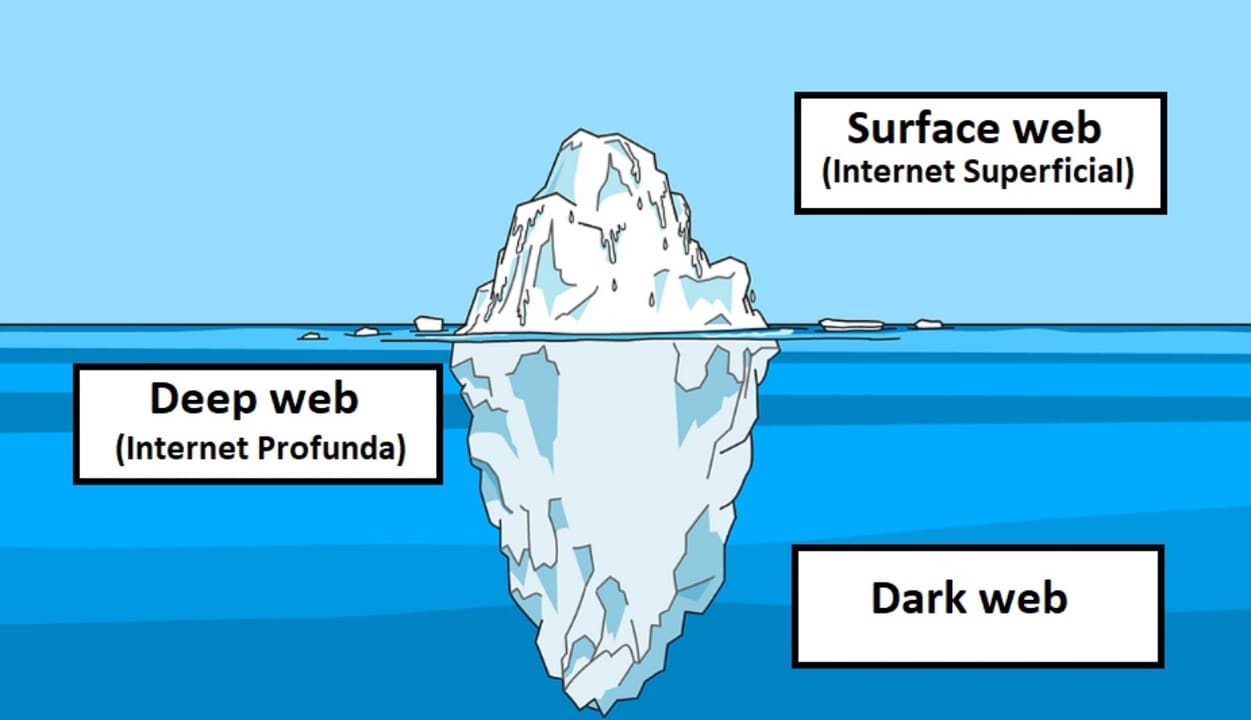
Unlock The Secrets Of Deephotlink A Journey Through The World Of Deep Web And Dark Net
The community tends to treat Deephotlink like some kind of master key. It isn't. Here's what actually matters. First, understand that any content you access through Deephotlink passes through their servers. That's not a privacy guarantee. Whatever is on those onion sites, their infrastructure can see it. If you're accessing sensitive material, you're trusting a third party. There's no way around that unless you run your own Tor relay chain, which takes about three weeks of setup and constant maintenance to get right. Second, the tool has a specific weakness with dynamic content. Sites that rely heavily on JavaScript execution, WebSocket connections, or complex single-page application frameworks tend to break or load incompletely. The proxy strips or mishandles a lot of the modern web stack because it's not running a full browser automation layer. I learned this the hard way when I tried to pull data from a marketplace that used a React-based frontend. Deephotlink returned what looked like an empty page. The workaround was to access the same service through their legacy API endpoint instead, which served plain JSON. You find those endpoints by checking the page source or using a tool like Burp Suite to intercept the initial requests.
Get the Full Details

Here's a practical workflow I use when I need to access something reliably: Start by testing the onion address directly in the Tor Browser to confirm it's actually live and responsive. Onion services go down constantly. People forget that. If it works there but not through Deephotlink, you know the issue is the proxy layer, not the target. Then check whether the site uses JavaScript-heavy rendering. If it does, consider whether there's an alternative access method. Some services offer RSS feeds or API endpoints that work fine through proxy layers. Others don't. You just have to dig. The download and setup side is straightforward. Deephotlink operates as both a web interface and a self-hostable option. The hosted version at their main URL handles the routing for you but imposes rate limits and visibility constraints. The self-hosted variant requires a Ubuntu server, at least 2GB RAM, and a clean Tor installation. The setup process takes roughly forty-five minutes on a fresh instance if you follow their documentation exactly. Deviations tend to cause connection timeouts that are nearly impossible to debug without reading the Tor logs line by line.
Pitfalls People Walk Into
People assume that using Deephotlink makes them anonymous. It doesn't. Their logs exist. Their servers exist. If law enforcement subpoenas them, the data is there. I've seen this play out. It's not common, but it happens, and the people who thought they were invisible suddenly weren't. Another issue is false sense of security around link validity. Deephotlink caches responses in some configurations. A page that was fetched yesterday might show up today even if the original onion service changed its content or went offline. I encountered this when researching a forum that had been archived months prior. The Deephotlink mirror showed posts from June that no longer existed on the source. Cross-referencing with the Wayback Machine's Tor archive caught the discrepancy, but only after I spent two hours trying to verify claims that were already stale. Rate limiting is another bottleneck. The free tier typically allows maybe fifty to a hundred requests per hour before throttling kicks in. If you're doing bulk retrieval, you'll hit that wall quickly. The paid tier raises the ceiling but doesn't solve the fundamental problem: every request still routes through their infrastructure, which introduces latency and potential points of failure.
What It Can't Do
Deephotlink cannot access .onion services that require client certificate authentication. It cannot bypass CAPTCHAs or brute-force login forms. It cannot guarantee uptime on any given onion address. Onion services disappear regularly due to takedowns, provider issues, or operators going offline. This tool doesn't prevent that. If you need authenticated access, persistent sessions, or high-volume data extraction, you're better off running your own Tor setup with a headless browser like Selenium or Playwright configured for Tor. It's more work upfront, maybe two or three days of configuration and testing, but it gives you full control over your requests, your session state, and your privacy boundaries. The payoff becomes obvious pretty quickly once you hit the limitations of a proxy tool. There's also the question of what you're actually looking for. The deep web and dark net contain a lot of legitimate academic, journalistic, and archival material. There's also a significant amount of illegal content, scams, and dead ends. Deephotlink doesn't filter between these. It retrieves whatever the onion service serves. Your judgment about what to access and why is the only real guardrail here.

A Real Example From My Workflow
Last year I needed to pull historical posts from a defunct research forum that only existed as an onion service. The operator had shut down the public Tor address but kept an archive available internally. Deephotlink let me retrieve the publicly accessible portions in about ten minutes per page. The problem was that the forum used Cloudflare-like challenge pages on certain sections, which the proxy couldn't solve. I ended up writing a small Python script that used the Stem library to build custom Tor circuits, rotated exit nodes every fifty requests, and handled the challenge pages by falling back to direct Tor Browser automation only when needed. The whole operation took about six hours total and produced a clean JSON export of roughly fourteen thousand posts. Running that through Deephotlink alone would have required weeks of manual browsing and still missed entire sections of the archive. The takeaway is practical rather than dramatic. Deephotlink is a useful tool for casual access to public onion services. It's a starting point, not a complete solution. Understanding where it breaks is what separates people who waste their time from people who get what they need.