Document Processing With Smartfind Express DPS
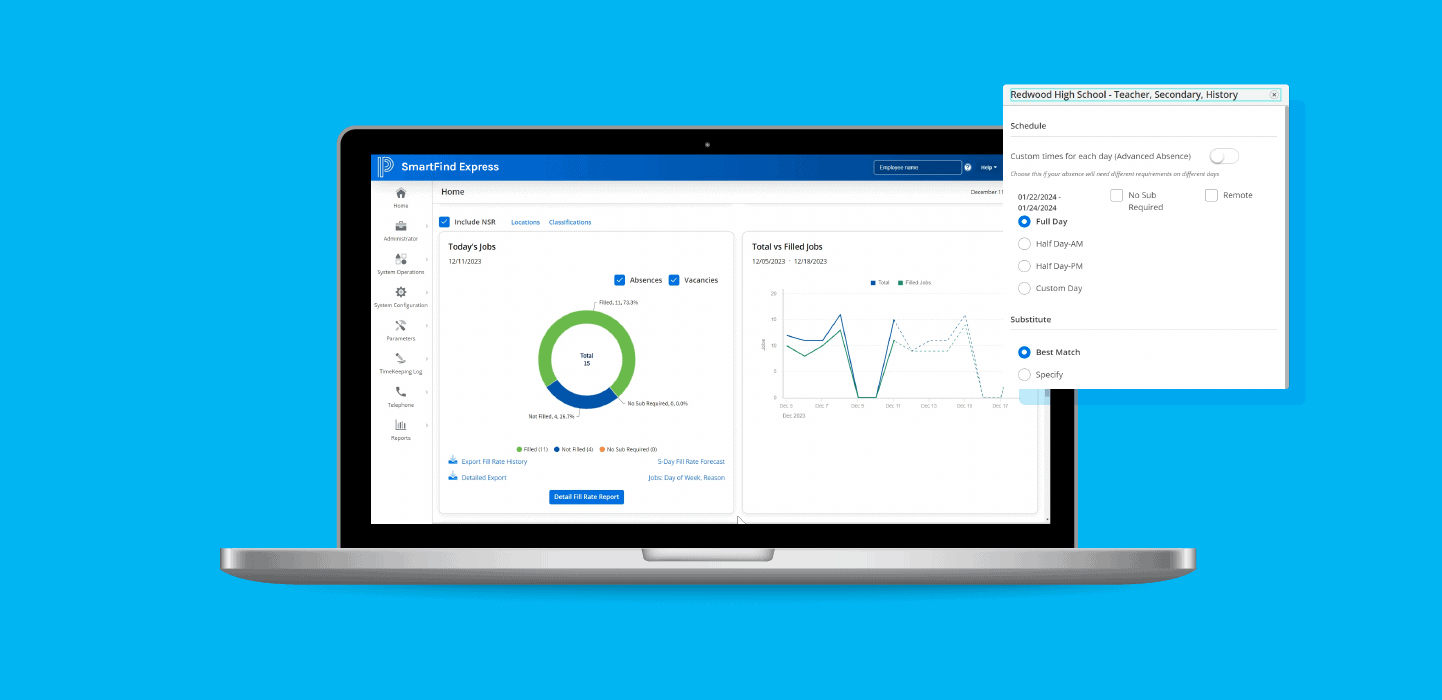
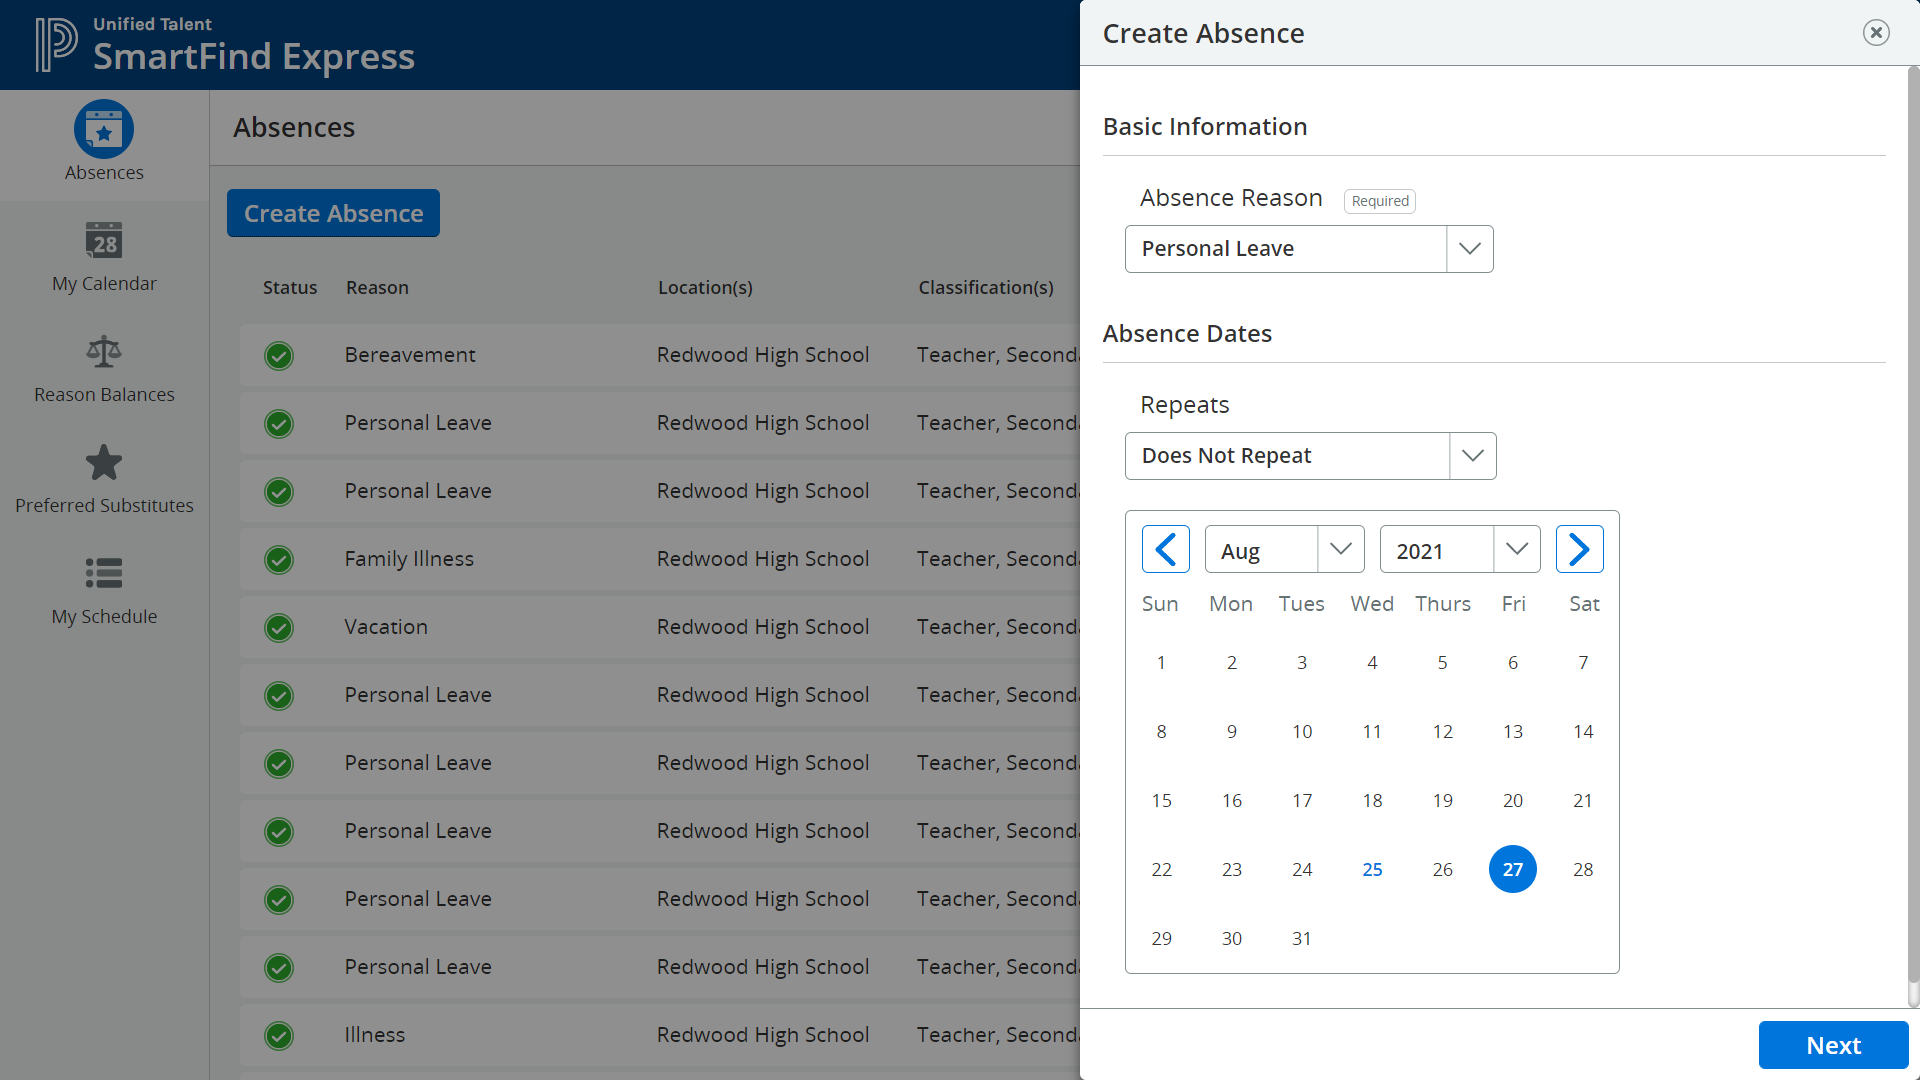
I have been running document management systems in enterprise environments for roughly twelve years now. Most of that time involved dealing with scanners that would jam at inopportune moments and software that promised automation but delivered none. When I first encountered Smartfind Express DPS, my expectations were low based on previous experiences with similar-sounding tools. The system handles document intake, classification, and retrieval in a way that actually works without constant manual intervention. Smartfind Express DPS processes scanned documents through optical character recognition and index fields automatically, then stores everything in a searchable database. The interface is functional rather than pretty, which is not a bad thing when you need reliability over aesthetics.
Getting Started With The System
You need to install the main application first. The installer runs about 200MB and takes roughly 15 minutes on a standard Windows machine. During installation, you will need to specify where your document repository lives. I recommend using a separate drive from your operating system. Document databases grow quickly, and mixing them with your OS slows everything down when things get busy. After installation, run the configuration wizard. It walks through database connection settings, user permissions, and scanning parameters. The default settings work for basic operations, but you should adjust the OCR language pack if you process non-English documents. The system supports multiple languages, but you must enable them during configuration or they will not appear later.
Understanding How The Software Actually Works
Smartfind Express DPS operates through a client-server architecture. You have a server component that manages the database and processing jobs, plus a client application that users interact with. The server listens on port 8080 by default, though you can change this during setup. Documents enter the system through three main pathways: direct scanning via TWAIN or WIA interfaces, file imports from network folders, or batch uploads through the web interface. Each document gets processed through an OCR pipeline that extracts text and builds an index. This indexing happens automatically in most configurations. I ran into a specific problem about two years ago that took me several days to resolve. We were processing a large volume of forms from a government contract, and the automated classification kept failing on a particular form subtype. The system would misclassify these documents as "general correspondence" instead of routing them to the correct category. The issue turned out to be that the training data for that form type was incomplete in our OCR model. I had to export the misclassified documents, manually tag them, then retrain that specific classification model. After reloading the updated model, accuracy improved from about 60 percent to nearly 95 percent on those forms.
Get the Full Details
The workaround involved using the batch editing tool in the admin console to select all misclassified documents, apply the correct classification tags in bulk, then run the retraining function. The retraining itself took about 45 minutes for roughly 500 documents, after which you need to restart the processing service for changes to take effect.
Configuration Options That Matter
The software offers several configuration areas that affect performance significantly. The first is your OCR confidence threshold. By default, the system sets this to 0.7, meaning any text recognition below 70 percent confidence gets flagged for manual review. I usually lower this to 0.6 for clean scans and raise it to 0.8 for handwritten documents. Getting this right reduces your review queue considerably. The second important setting involves auto-classification rules. You can create rule sets that sort documents based on keywords, sender names, or document types. These rules process in real-time as documents enter the system. I have seen setups where overly complex rule hierarchies cause the processing engine to slow down. Keep your rules simple and test them individually before combining them. Batch processing settings deserve attention too. The system allows you to schedule automatic document imports from designated folders. If you set these to run too frequently with large volumes, you can overwhelm the database during peak hours. I usually schedule batch imports during off-hours and space them at least two hours apart for large volumes exceeding 1000 documents per batch.
Performance Considerations And Limitations
The system handles roughly 200 to 300 pages per minute on moderate hardware with a dedicated server. This number drops significantly with high-resolution scans or when using advanced OCR features like handwriting recognition. If you process a lot of color documents, factor in additional storage since images are typically compressed to PDF/A format, which maintains quality but increases file sizes compared to standard PDFs. One limitation I encountered involves large-scale migration projects. Moving documents from legacy systems into Smartfind Express DPS requires careful planning. The import tools handle most standard formats, but proprietary formats from old document management systems often need conversion first. I spent a week converting documents from an obsolete imaging system using middleware before they could be imported properly. Another practical issue involves user license costs. The base license covers a limited number of concurrent users. If your organization grows beyond that threshold, you need additional licenses that add to operational costs. I have seen mid-size companies hit this wall unexpectedly, so budget for potential licensing upgrades from the start.

The software also requires regular maintenance. Database optimization routines need to run weekly if you process high volumes. These routines reclaim space from deleted documents and update statistics for faster searching. Skipping maintenance for more than two weeks typically results in noticeably slower search times.
Where The System Falls Short
Smartfind Express DPS is not designed for everything. It struggles with unstructured documents that lack clear text zones, such as photographs with embedded captions or forms with heavy graphical elements. For those use cases, you need specialized image processing tools or manual classification workflows. Integration with modern cloud services is limited compared to newer platforms. If your organization uses cloud-based collaboration tools extensively, you may need additional middleware or custom development to bridge the gap. The system does offer API access, but implementing that requires development resources you might not have. For organizations looking for a complete modern document management solution with mobile apps and advanced collaboration features, other platforms might serve better. Smartfind Express DPS excels at core document processing and retrieval, not at providing a full digital workplace ecosystem.
Practical Advice For Implementation
Start small when deploying this system. Begin with a single department or document type to understand how the software behaves in your environment before expanding. I usually recommend starting with 500 to 1000 documents to test the workflow end-to-end. Train your staff thoroughly on the classification rules and search functions. Users who understand how the indexing works can retrieve documents significantly faster than those who do not. A fifteen-minute training session on search operators and index field usage can reduce support calls by half within the first month. Maintain regular backups of your document database. The system includes backup utilities, but you should verify these backups actually restore correctly. I have seen organizations discover too late that their backup files were corrupted because they never tested the restoration process.