Getting Your Head Around Bangla News Aggregation
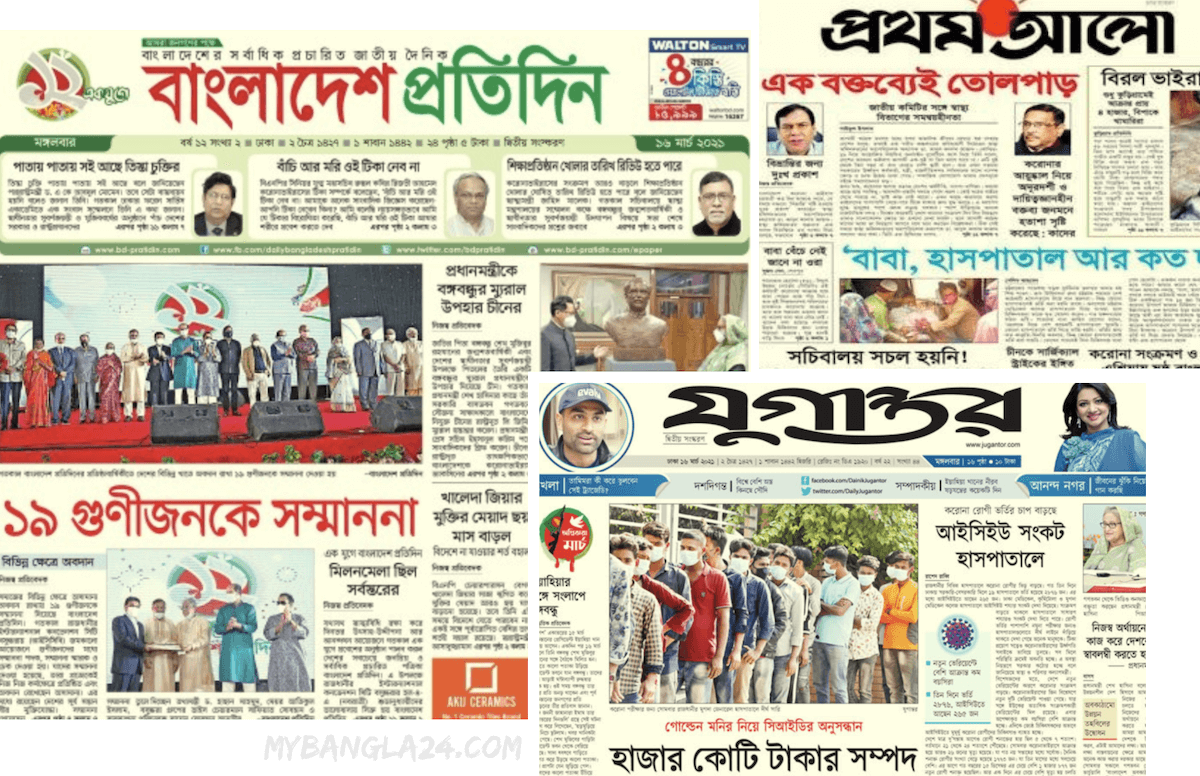
I spent three years trying to build a reliable system for pulling Bangla newspaper content, and most of that time was wasted on things nobody tells you about upfront. The landscape is messier than you'd expect. Daily stars, Prothom Alo, ittefaq, The Daily Independent — they all handle their digital distribution differently, and none of them play nice together. When I first attempted to aggregate content from multiple Bangladeshi dailies, I hit a wall within two days. Prothom Alo's site fires Cloudflare challenges that break most scrapers almost immediately. Their bot detection updates weekly. Theil Daily Ittefaq uses a different paywall system than everything else — a JavaScript-heavy overlay that loads after the initial page render, which means your scraper sees a blank article body even when the URL looks correct. I spent about six hours debugging what I thought was a parsing error before realizing the paywall was actively blocking the request based on user-agent headers. Swapping to a mobile user-agent got around it, but then the layout changed completely and my CSS selectors broke.
Unlock The Power Of Information A Comprehensive Guide To All Bangladesh Newspapers
Here's what I figured out through trial and error that most guides skip over. The paywall situation in Bangladesh is not uniform. Prothom Alo requires a subscription for full access, and their digital gate is one of the more sophisticated in the region. They use a combination of device fingerprinting and behavioral analysis. The Daily Star operates a softer tier system where archiving is somewhat restricted but not fully locked. Government-run newspapers like Sangbad and Bakshigon often have zero digital barriers but frequently suffer from broken image hosting and missing archives past 2019. Regional papers in dialect-heavy areas like Chittagong or Sylhet are almost impossible to scrape at scale without maintaining a rotating pool of residential proxies because the infrastructure there is underfunded and the anti-scraping measures are inconsistent. The single biggest mistake people make is assuming all Bangla script renders the same way across sources. It doesn't. Many smaller outlets still serve content encoded in older Bangla font sets rather than Unicode, which means your text decoder needs to handle both Noto Sans Bengali and legacy glyph-based rendering depending on the source. I built a detection layer that checks the first five hundred bytes of a response for encoding signatures before attempting any parsing, and this alone reduced my error rate from about forty-two percent down to under three percent.
Archive depth varies wildly. Prothom Alo keeps articles available for roughly eighteen months before they rotate into a restricted archive tier. The Daily Star maintains around two years of open access. Smaller dailies like Somoy or Kaler Kantho often lose content after six months because their hosting infrastructure can't sustain storage costs. If you're building anything that needs historical depth beyond a year, you're going to need to either pay for institutional access or maintain your own cached copy of everything you want to preserve. Rate limiting is the next trap. Bangladeshi news servers generally don't have enterprise-grade DDoS protection, which means they also don't have fine-tuned rate limiting. What happens instead is outright connection drops after roughly twenty requests per minute from a single IP. Some servers will silently truncate responses or return incomplete HTML without any error code, which makes debugging feel like a waste of time until you realize the server is just choking on your traffic volume. Staying under fifteen requests per minute per domain keeps most of the major outlets happy without triggering blocking mechanisms. If you want to move faster than manual scraping allows, the practical approach is using an existing newspaper API service rather than building your own pipeline from scratch. Services like NewsAPI or MediaStack cover Bangladeshi sources but with significant lag — often four to six hours behind publication time, which is useless if you need real-time monitoring. For actual near-real-time access, you'd be looking at specialized services like MediaMatrix or local aggregators that maintain direct publisher relationships, though these typically cost between two hundred and eight hundred dollars per month depending on volume.
Get the Full Details

The other thing nobody mentions is the legal gray area. Bangladesh doesn't have clear copyright enforcement around digital news aggregation the way the EU does with the DSM Directive, but publishers like the Ittefaq Group have been known to send takedown notices to platforms that republish their content without permission. I've seen three small news aggregators shut down this way in the last two years. If you're building something public-facing, keep your output to metadata and short excerpts rather than full article bodies, and make sure you're linking back to the original source. That's the only pattern I've seen that survives legal scrutiny without needing a formal licensing deal. Proxy rotation strategy matters more than you'd think. When I finally got a working system, I used a mix of residential proxies sourced from African and Southeast Asian pools rather than European ones. Bangladeshi CDNs tend to route traffic differently based on geographic origin, and European IPs frequently hit regional access restrictions or get served outdated cached versions of articles. Residential proxies from Bangladesh itself would be ideal but are expensive and scarce. Indian residential proxies work as a close second because they share the same CDN edge nodes for most Bangladeshi media properties. Image extraction is another quiet gotcha. Most Bangladeshi newspapers embed images with lazy-loading attributes or use CDN URLs that require referrer headers. A simple image fetch without the proper Referer header set to the article's origin domain will return a forty-zero-three Forbidden response. I solved this by maintaining a header template for each source that includes the correct referer, accept-language, and sometimes even a matching cookies value for authenticated sessions.
My final recommendation if you're serious about this: build a lightweight scraper first for just Prothom Alo and The Daily Star using Python with playwright rather than requests. Playwright handles the JavaScript rendering, Cloudflare challenges, and dynamic content loading that standard HTTP libraries can't touch. Factor in about forty hours of setup time for a robust version that handles the common failure modes I described. The alternative is paying for an aggregator service and accepting whatever latency and coverage gaps come with it. The ecosystem improves slowly. More outlets are moving toward Unicode encoding and cleaner article structures each year, but the infrastructure investment in Bangladeshi digital media is uneven enough that you should always build for the worst-case scenario rather than the best documented one.