How Reverse Image Search Actually Works In Practice
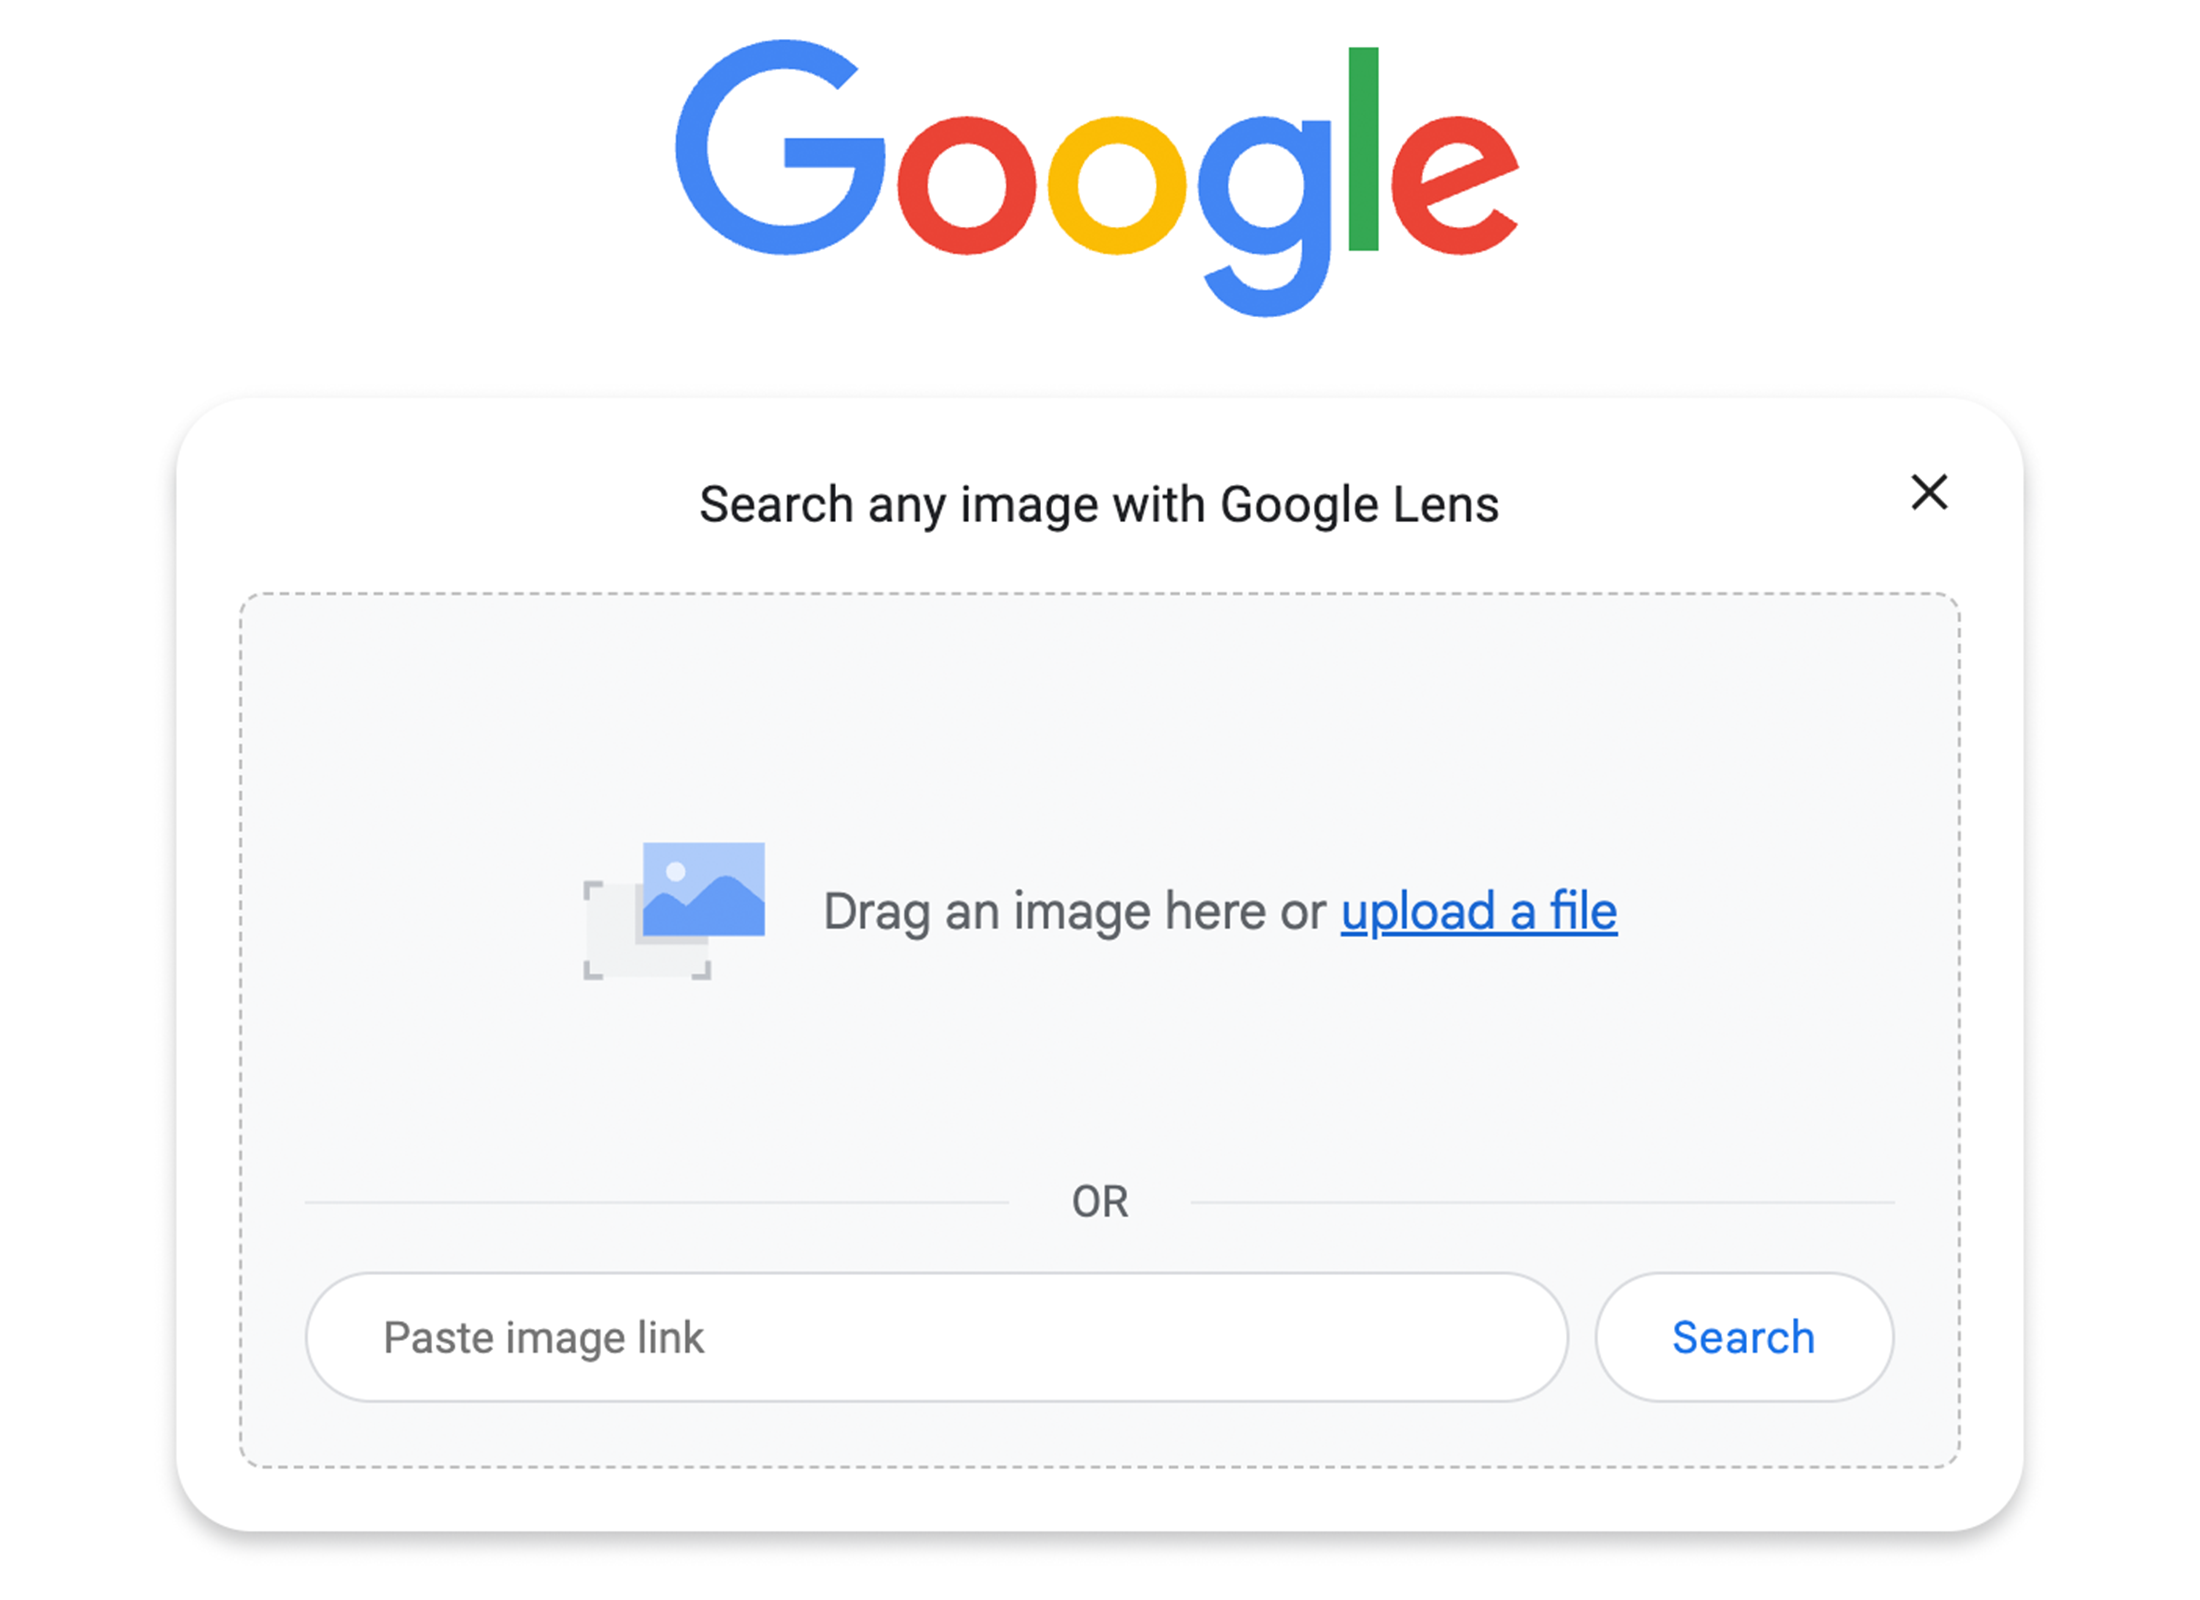
Google Images lets you upload a photo and find visually similar results or the pages where that image appears online. You do this by clicking the camera icon in the search bar, dragging your file in, or pasting an image URL. The system then processes the image through visual recognition models and returns matches. That's essentially the entire mechanism. Most people think it's more complicated than it actually is. The straightforward path is to go to images.google.com, click the camera icon, and either paste an image URL or upload a file from your computer. Google then shows you two tabs of results: Visually similar images and Pages that include matching images. The first tab finds pictures that look alike, regardless of source. The second tab finds where that exact image has been published online. These serve different purposes. One helps you track down the original source or find higher resolution versions. The other helps you discover derivative works, stock photo usage, or plagiarism cases. I've spent years using this for work involving image attribution and content verification. Let me share a specific situation that caught me off guard. I was tracking down the original photographer for an image that appeared on multiple websites with conflicting metadata. The reverse search returned a dozen results, but none pointed back to the actual source. The image had been mirrored so many times that the earliest indexed copy was still not the origin. My workaround was to take the highest resolution result, extract the EXIF data from the file itself, and then search using specific metadata values like GPS coordinates and camera model rather than relying solely on the visual match. That got me to the photographer's own website within twenty minutes. Google's image matching is good at finding similar-looking photos, but it struggles when an image has been cropped, filtered, or heavily compressed before it hit the web.
There are some things Google doesn't tell you about this tool that matter if you're doing anything beyond casual use. First, Google processes uploads at reduced resolution. If your image is larger than a few megapixels, Google typically scales it down before running the visual analysis. This means fine details that might distinguish between two similar images can get lost. If you're searching for a specific artwork or a photograph where subtle differences matter, the results will sometimes point you toward the wrong category entirely. Second, the visually similar results are not necessarily from the same subject. They're grouped by visual features, which means a photo of a dog might return images of other animals, textures, or objects that happen to share similar color patterns and shapes. It's not semantic search. It's pattern matching at scale. Another thing nobody mentions: Google's reverse image search does not work consistently across all image types. Logos, screenshots, and heavily processed images tend to produce unreliable results. Screenshots in particular are problematic because they contain UI elements that confuse the visual recognition engine. If you upload a screenshot of a webpage or an app interface, you'll often get results that are completely unrelated to the actual content you're trying to identify. The workaround here is to crop out any borders, toolbars, and windows before uploading. Keep only the image content itself. This small step dramatically improves accuracy. For finding the origin of an image, Google is a starting point, not an endpoint. If you need to verify whether a photo is authentic or trace where it first appeared, you should cross-reference results with other specialized tools. TinEye is worth using alongside Google because it indexes images differently and sometimes surfaces results Google misses. TinEye also provides exact match percentages, which helps you gauge how closely a result aligns with your upload. When I was investigating a case involving misattributed historical photographs, TinEye found an archive entry that Google completely overlooked. The Google results kept pointing to recent blog posts and social media shares, while TinEye connected directly to a museum digitization project from 2014. Both tools have their weaknesses. Google's strength is its massive index. TinEye's strength is its precision on exact duplicates. Using both together cuts your search time significantly compared to relying on either one alone.
There are limitations you need to accept upfront. Google Reverse Image Search cannot identify people in photos. It cannot read text inside images reliably for search purposes. It cannot tell you the location where a photo was taken unless that information was already published alongside the image online. If you're looking for metadata like shutter speed, aperture, or GPS coordinates, you need to extract that from the file directly using a tool like ExifTool before you upload anything. Google strips metadata from uploaded images for privacy reasons, so none of that information travels with your search. Sometimes the tool simply returns nothing useful. This happens most often with original content that has never been published on the open web, low-resolution profile pictures, or images that have been altered enough to fall outside Google's similarity thresholds. If you're getting zero or irrelevant results, try converting the image to a different format first. Google handles JPEG and PNG best. WebP files occasionally cause issues. Converting to standard JPEG format before uploading resolves this in most cases. You can also try uploading a cropped version focusing on the most distinctive part of the image rather than the full frame. The practical value of this tool depends entirely on what you're trying to accomplish. For checking whether an image is stolen or reused without permission, it works well enough for most cases. For deep provenance research on artwork or historical photography, you'll need to supplement it with specialized databases and archive searches. For identifying products in photos, it's moderately useful but often less accurate than dedicated product search engines. Understanding where the tool succeeds and where it breaks down saves you time and prevents false confidence in results that look convincing but aren't actually reliable.
Get the Full Details

If you're working with large volumes of images, be aware that Google imposes implicit rate limits. Upload too many images in rapid succession and you'll start getting CAPTCHA challenges or temporary blocks. This isn't documented anywhere, but it's a real constraint if you're building a workflow around repeated searches. Space your uploads out, use different devices or browsers if you need to process more than twenty or thirty images in a single session, and accept that batch processing through Google Images isn't really viable at scale. The bottom line is that Google Reverse Image Search is a free tool with real utility, but it has narrow blind spots that can waste your time if you don't know about them. Upload your image, check both result tabs, verify what you find against other sources when accuracy matters, and don't trust the first page of results as final. That's how I approach it now after enough failed searches to learn the pattern. The tool works when you use it correctly. It misleads when you assume it's smarter than it actually is.