Opening PDFs in Google Docs
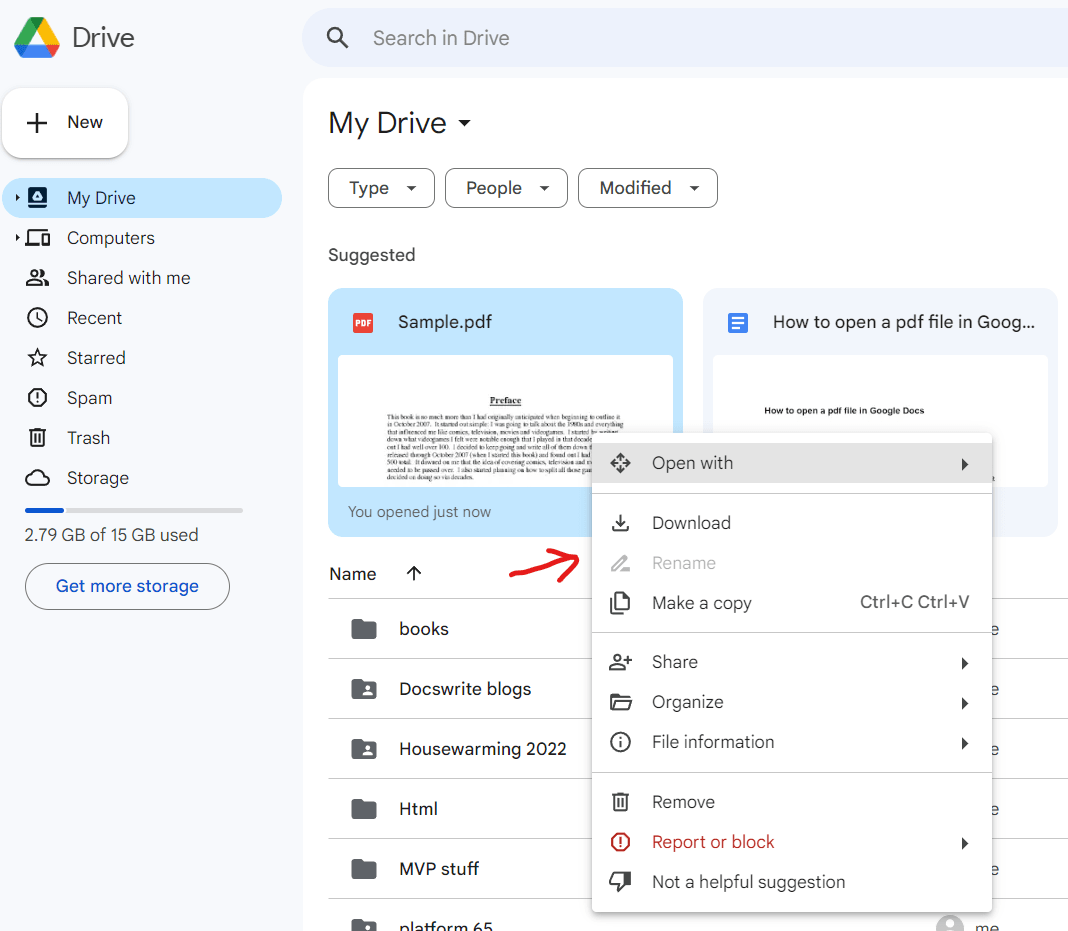
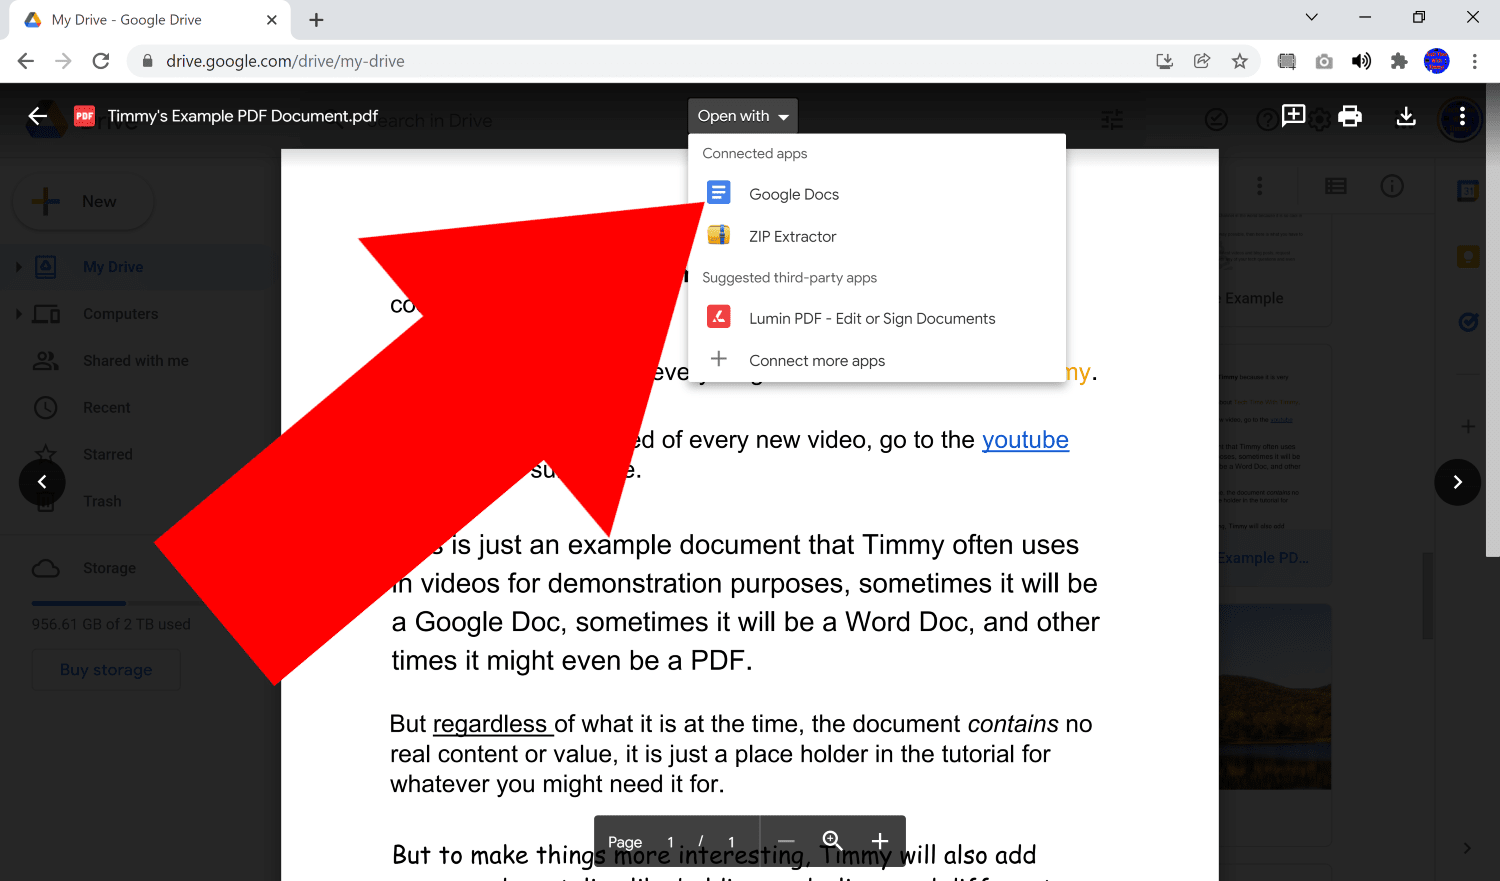
Google Docs won't natively open PDFs the way Word handles them. The file stays a PDF. What actually happens is that Google runs OCR on the document and creates a text-based copy you can edit. The visual layout comes back, but not perfectly. I spent a long time thinking this was a bug before I realized it's just how the platform works. The process itself is straightforward enough. You go to Google Drive, right-click the PDF, select Open with, and choose Google Docs. The system then processes the file, runs its optical character recognition engine, and spits out a new document. Usually takes about 10 to 30 seconds for a standard 10-page document. A 200-page contract might take two or three minutes, sometimes longer if the PDF has scanned images rather than embedded text.
Unlock The Power Of Google Docs How To Open A PDF In No Time
Here's the practical walkthrough. First, make sure your PDF is already in Google Drive. If it's on your desktop, drag it into the Drive window or click New, then File Upload. Once it's in Drive, right-click it. You should see "Open with" in the context menu. Click that, then click Google Docs. A new tab will open with the processed document. The text should be selectable. Images stay as images. Tables usually come through, though formatting gets messy if the original layout is complex. If you don't see "Open with Google Docs," the file might be corrupted or in a format Google doesn't recognize. I hit this once with a PDF exported from an old accounting system. The pages were basically images wrapped in PDF, and Google kept failing the import. What worked was converting the PDF to images first using a free tool called pdftoppm, then uploading those images individually. Google Docs handled image uploads fine and ran OCR on each one separately. It took longer, but it got through. Another thing most people don't realize: Google Docs has a hard limit on how large a file it'll process this way. Somewhere around 100 megabytes, it starts choking. I once tried to open a 140-megabyte scan of an old magazine and the document just stayed blank for five minutes before showing an error. Splitting the PDF into smaller chunks before uploading solved it.
What Actually Happens During the Conversion
When you open a PDF in Google Docs, the platform uses Google's OCR engine, the same one behind Google Lens and Google Books. It analyzes each page as a visual layer, identifies characters, and reconstructs them as editable text. This means the resulting document isn't really a PDF anymore. It's a Google Doc that contains text and images arranged to resemble the original layout. The quality depends entirely on the source PDF. If the PDF was generated from a digital source like Word or InDesign, the text layer is already embedded, and Google reads it directly. These convert almost perfectly. If the PDF is a scan of paper — a stamped receipt, a handwritten note, a photographed textbook page — then OCR does the heavy lifting, and the results are hit or miss. I've seen names like "Christopher" come back as "Christophsr" and dollar amounts flip completely wrong because the OCR couldn't distinguish between a 7 and a 1. Fonts don't carry over either. Google Docs replaces whatever font the PDF used with its own default typeface, usually Arial or a similar sans-serif. If the original used a monospaced font for a code block or a financial table, that alignment is gone. You'll need to fix it manually, which eats into whatever time you thought you were saving.
Get the Full Details

Pitfalls and What Doesn't Work
Hyphenated words at line breaks become mangled. Google's OCR doesn't always know whether a hyphen is part of the word or just a line-break indicator. Words like "state-of-the-art" can turn into "state of the art" or split across lines unpredictably. Long documents with lots of compound terms require manual cleanup afterward. Multicolumn layouts break. Newspapers, academic papers, brochures — anything with more than one column of text gets reordered. Google reads top to bottom, left to right, across columns. So a two-column newsletter becomes one long column in the output. You end up reformatting more than you edit. Password-protected PDFs don't open. Google Docs can't read encrypted files. If your PDF requires a password, you need to remove it first using a tool like Adobe Acrobat or a free online PDF unlocker, then upload the decrypted version to Drive. I learned this the hard way when a client sent me a locked contract and I spent twenty minutes troubleshooting before realizing the password was the actual problem.
Handwritten content is unreliable. Google's OCR can handle neat handwriting in some cases, but cursive, messy notes, or writing on lined paper tends to fail. I tried converting a supplier's handwritten delivery log once. Maybe 40 percent of the entries came through readable. The rest was garbage text. Scanning that by hand was faster than cleaning up the output. Vector graphics and embedded CAD drawings don't convert. If the PDF contains diagrams, blueprints, or illustrations drawn as vectors, those elements become static images in the Google Doc. You can't edit the lines or reshape the shapes. The text near them might be selectable, but the graphics are locked in place. For technical documents with lots of figures, this makes the output nearly useless for any real editing work.
Alternatives When Google Docs Falls Short
Adobe Acrobat is the obvious alternative if you have a license. It opens PDFs natively and preserves formatting far better than Google Docs. The export-to-Word feature in Acrobat is decent for most business documents. LibreOffice Draw handles PDF imports too, and it's free. It doesn't run OCR, so scanned documents won't be editable, but for digital PDFs the layout preservation is solid. For bulk conversions or documents with sensitive data, I've started using a local tool called Calibre with the PDF to DOCX plugin. It runs on my machine, keeps everything offline, and handles layout better than Google Docs for complex reports. The tradeoff is speed. Calibre takes longer to process each page, and the output sometimes needs more manual fixing than the Google Docs version. But it's worth it when you're dealing with contracts or technical manuals where accuracy matters. If the PDF is purely image-based and you need clean text, a dedicated OCR tool like ABBYY FineReader or EvenText gives much better results than Google's engine. I switched to EvenText for scanning old invoices because the Google output kept misreading numbers. EvenText got 95 percent accuracy on the same batch where Google was stuck around 70 percent.
Practical Workflow That Actually Works
Here's what I do now when I need to open a PDF in Google Docs. First, I check the file size. If it's over 100 megabytes, I split it into smaller PDFs using a free tool called PDFsam Basic. Then I verify the PDF isn't password-protected. If it is, I unlock it before uploading. Next, I look at the PDF quality. If it's a clean digital PDF — textSelectable, no blur — I upload and open it directly in Google Docs. If it's a scan or has poor quality, I run it through EvenText first and only use Google Docs for light editing afterward. For multicolumn documents, I accept that the formatting will be wrong and plan to spend 15 to 20 minutes reflowing the text manually. This approach usually gets me from a raw PDF to an editable Google Doc in under five minutes for simple files. Complex scans might take 15 to 20 minutes including the preprocessing step. Still faster than retyping everything by hand.