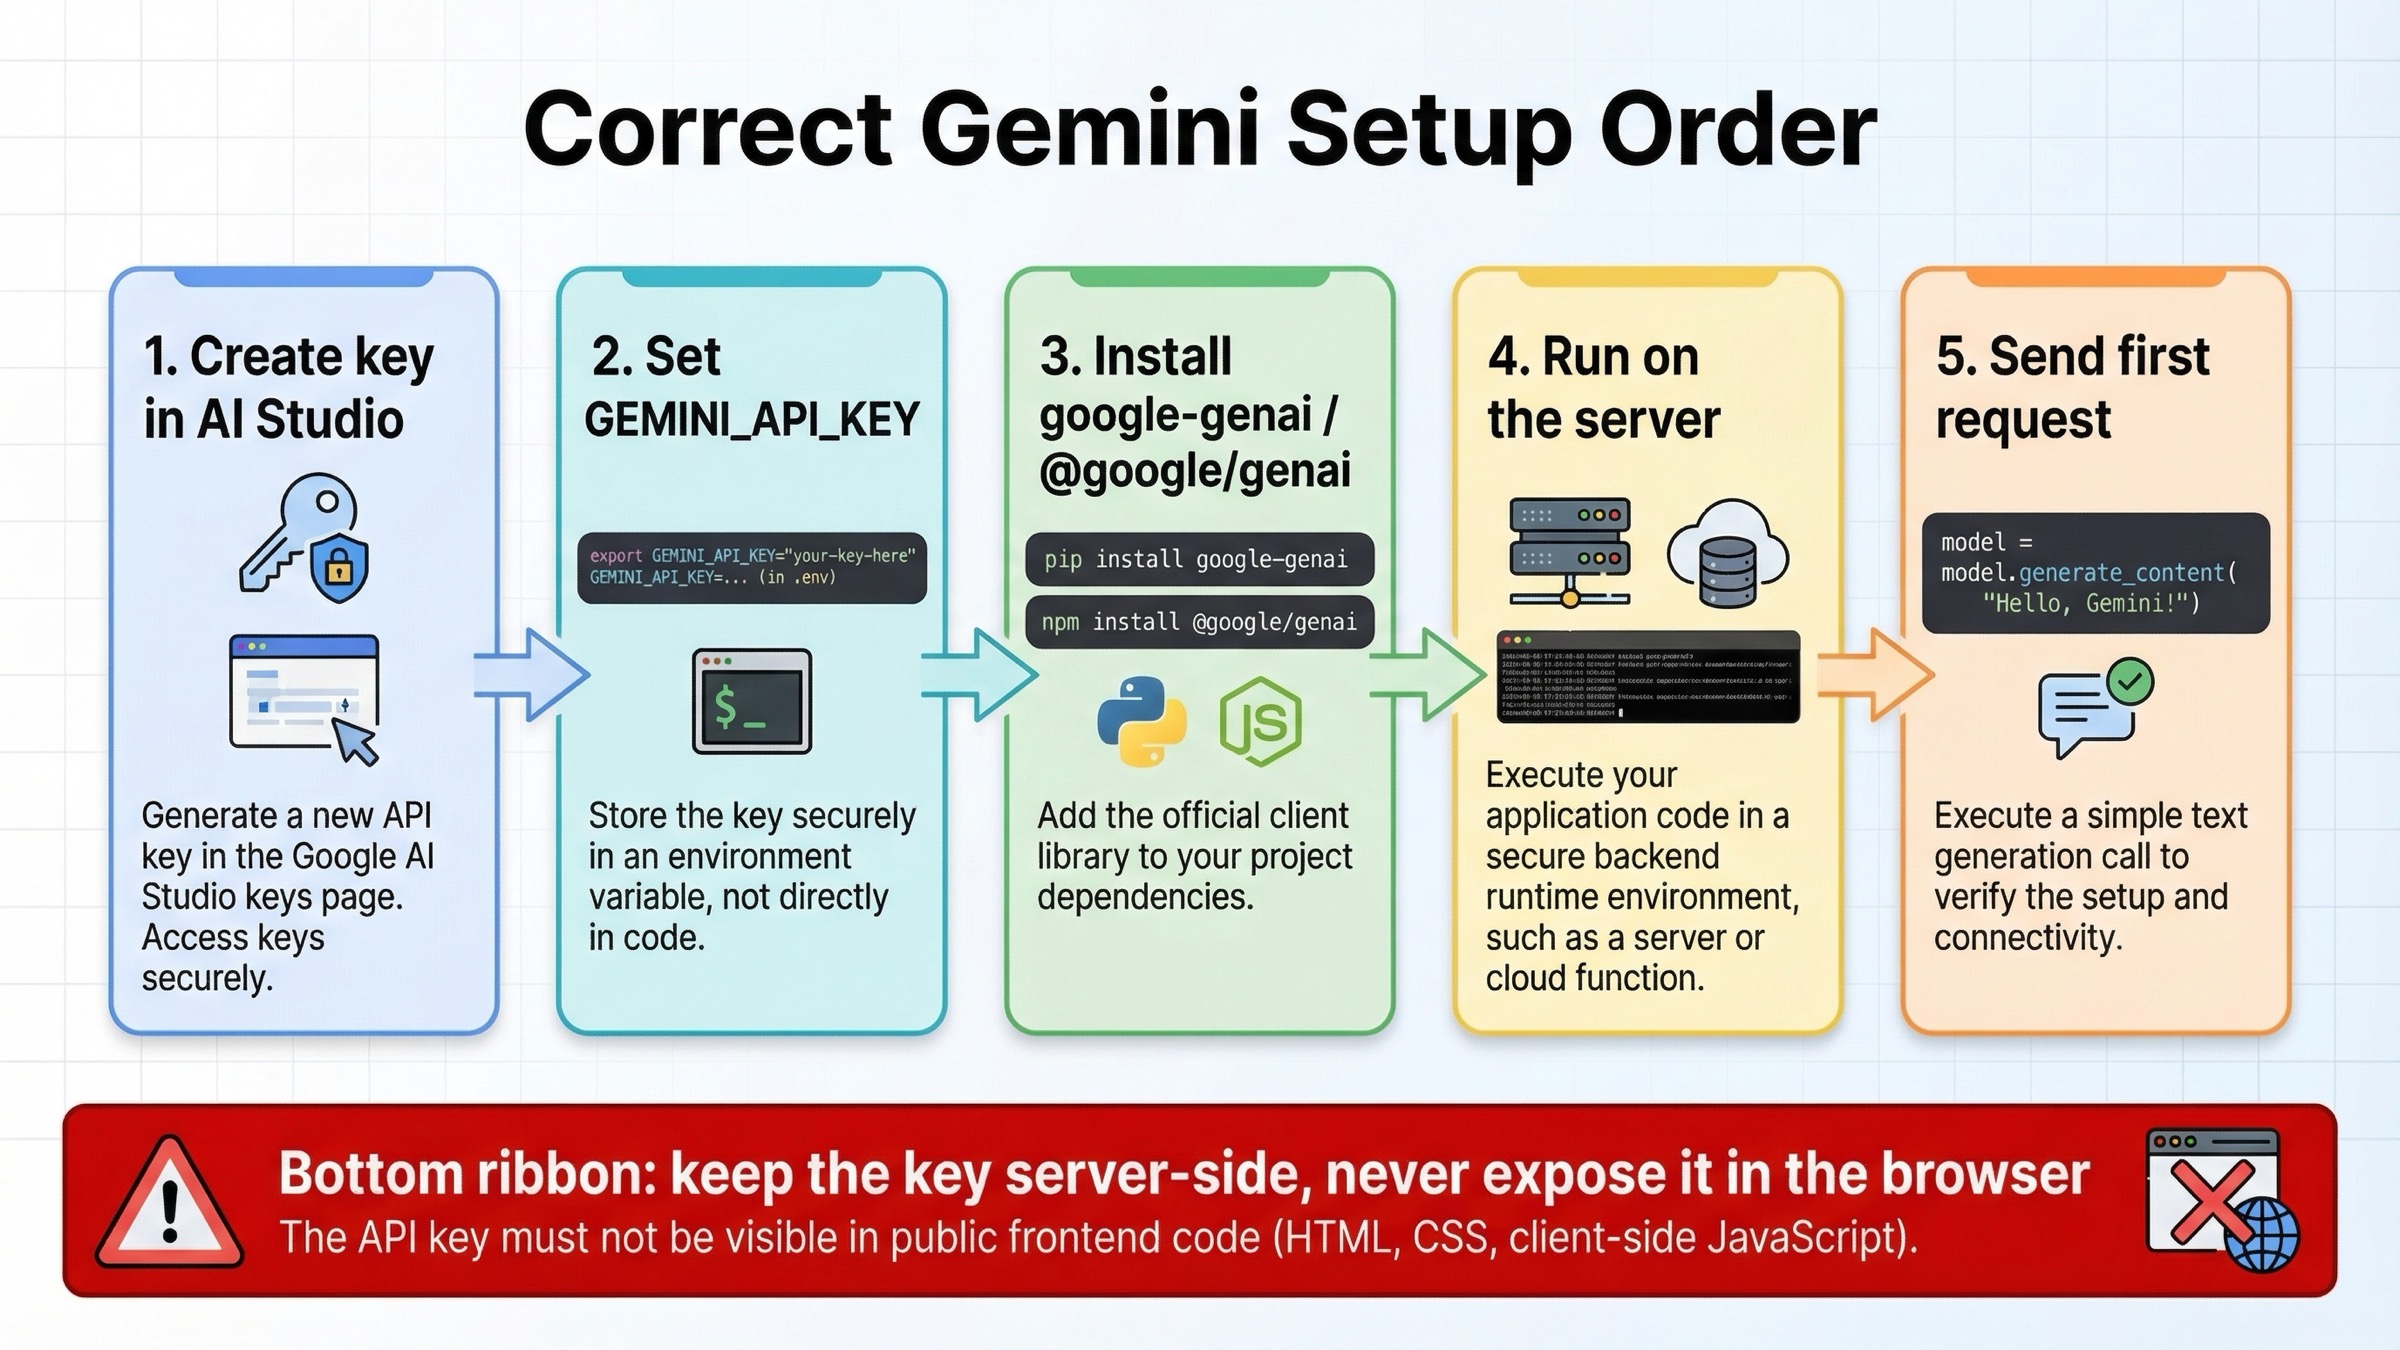
Setting Up Gemini API Access Without Losing Your Mind
I spent three days debugging authentication issues with the Gemini API because Google's documentation assumes you already know what you're doing. If you're reading this, you probably don't. Here's what actually works. The core issue with getting started is figuring out where the API key lives and how to pass it correctly. Google provides several endpoints, and the Python SDK handles most of the heavy lifting, but there are gotchas that aren't obvious until you hit them head-on. First, create a project in Google Cloud Console. Enable the Gemini API. Generate an API key. That part is straightforward. The part that trips people up is environment variable management. Don't hardcode your key. Use os.environ or a proper secrets manager. I learned this the hard way after pushing a commit with my key in plain text to a public GitHub repo. Git history cleanup takes longer than you'd expect.
Once you have the key, installation is just: pip install google-generativeai Then in your code:
import google.generativeai as genai
genai.configure(api_key=os.environ['GEMINI_API_KEY'])
That's it for basic access. The model you'll use most is gemini-pro for general tasks and gemini-pro-vision when you need image understanding. There's also a newer version that handles longer context windows, which matters more than people admit. Here's something the official docs don't emphasize enough: rate limits are per-project, not per-key. If you're running a production service with multiple users, your effective throughput is shared across everyone using the same project ID. I ran into this when my application suddenly started returning 429 errors at around 50 concurrent users. The workaround was splitting traffic across two separate projects with different API keys. It cost more, but it solved the throttling problem immediately.
Get the Full Details

For function calling, which is basically how you make the model interact with your own code, the JSON schema has to be precise. Loose typing breaks the API. I once spent four hours debugging why the model refused to call a function I had defined. The issue was a single property in the JSON schema missing a type declaration. The error message was completely unhelpful. It just said the function call failed without explaining why. Temperature and top_p settings behave differently than you might expect from other LLM APIs. The default temperature is 0.4, not 0.7. If you want creative outputs, bump it up. If you need deterministic behavior, drop it to 0.2 or below. The model is sensitive to these parameters in ways that aren't intuitive if you've only worked with other providers. Caching is another area where Google and other providers diverge. The Gemini API supports cached content through the contents parameter with a generate_content call. You can prefill a conversation with large blocks of text and then ask follow-up questions without re-sending the full context every time. This cuts latency significantly for multi-turn applications. But the cache has a maximum size, and exceeding it doesn't error gracefully. It just silently drops the oldest chunks. I discovered this when my chat application started producing nonsensical responses after about 20 turns. The model was responding to truncated context without any indication that truncation had occurred.
For streaming responses, the SDK provides a built-in iterator. Use it if you want to stream token-by-token to a frontend. The response object yields individual completion chunks, and each chunk contains text you can send directly to the client. This is how most real-time applications should work. Buffering entire responses before sending them creates unnecessary latency. One more thing that's worth knowing: the free tier gives you generous request limits, but it's not meant for production. The quota resets daily, and if you go over, you get soft-limited rather than blocked entirely. You'll still get responses, just slower. I used this behavior to my advantage during a beta testing phase. I ran load tests against the free tier to understand realistic performance ceilings before committing to a paid plan. If you need to integrate Gemini into an existing application, the cleanest approach is wrapping the API calls in your own abstraction layer. Don't scatter genai calls throughout your codebase. Build a simple client class that handles retries, rate limiting, and error parsing. The API will throw GoogleAPIError with details about what went wrong. Your wrapper should catch those, log them, and retry on transient failures like 5xx errors or timeout exceptions. Don't retry on authentication failures or malformed requests.
The documentation lives at developers.generativeai.google. The quickstart section is adequate for getting a basic call working. Everything beyond that requires reading the reference documentation and experimenting. There's no shortcut around understanding how the model actually processes your inputs. Spend time testing different prompt structures. The difference between a well-crafted prompt and a sloppy one is enormous with this model.