Getting From a Still Image to Actual Motion
You upload a PNG. You type a prompt describing the motion you want. You click generate and wait. Sometimes it works. Sometimes the model turns a portrait into someone breathing underwater. The free tools exist. They're just not great yet. That's the honest baseline. I spent about six weeks testing every free-tier image-to-video tool I could find when our marketing team needed product shots that actually moved. We had zero budget. I learned things the hard way.
Unlock The Power Of Free AI Image To Video Generators Online A Quick Guide
Here is how the actual process works when you stop reading the glossy landing pages and just try it. Pick your tool first. This matters more than anything else. Most people jump into the first result on Google and waste twenty minutes. The top free options right now are Kling AI, Runway Gen-3 Alpha (free tier with very limited credits), Luma Dream Machine, Pika Labs, and Haiper. Each one behaves completely differently. Kling handles complex motion better but has longer queues. Luma produces cleaner results on static subjects. Pika is decent for anime and illustration styles. The free credits refresh on different schedules. Kling gives you daily credits. Luma resets monthly. Figure this out before you upload anything because running out mid-sequence is annoying.
Your input image determines 80 percent of the output. A blurry phone photo of a coffee cup will not become a cinematic product shot. The model can only extrapolate from what it sees. Use high-resolution images with clear subject separation. Backgrounds should be simple. Faces need to be in focus. I learned this after wasting probably forty generations on a blurry reference photo of our office chair. The model kept inventing extra legs. The chair never had four legs in any output. Write prompts like you are directing a camera, not describing a scene.
Get the Full Details
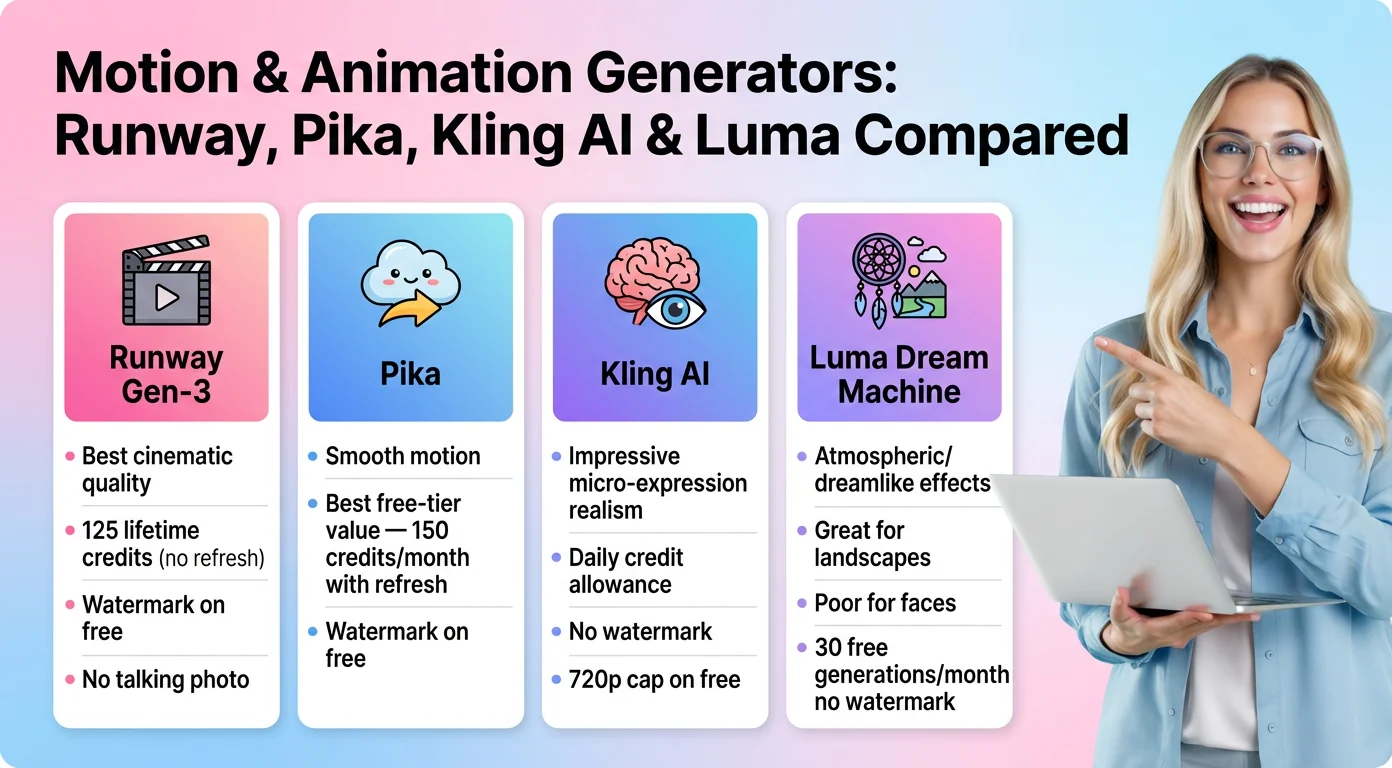
"A cat sitting on a wall" produces nothing interesting. "Slow push-in on a calico cat sitting on a brick wall, afternoon light, subtle wind in fur, shallow depth of field" gives the model actual direction. Include camera movement words. Pan left. Zoom in. Track shot. Static frame with subject motion only. The models understand these terms better than you would expect. But they also interpret them loosely. Test multiple variations. Generation settings on free tiers are severely locked. You will likely get 3 to 5 seconds of output. Resolution is usually capped at 720p or lower. You cannot control frame rate precisely. Some tools don't let you adjust motion strength at all. A few let you set a seed number for reproducibility, which is useful when you need to iterate on the same base image. Don't expect custom rendering parameters. The free experience is deliberately constrained.
What These Models Actually Do Under the Hood
Image-to-video generation uses a diffusion-based architecture with a pretrained image encoder and a temporal diffusion decoder. The model encodes your still image into a latent representation, then iteratively denoises a sequence of latent frames while conditioning each frame on the original image embedding. The result is a video where the first frame closely matches your input and subsequent frames introduce motion based on your text prompt and learned priors about physics and movement. The quality depends heavily on the training data. Models trained on high-quality cinematic footage produce more realistic motion than those trained on internet clips. Kling and Luma appear to have better training pipelines than most of the alternatives. That is why they consistently rank higher despite also being free.
A Specific Problem I Ran Into and How I Fixed It
I was generating a video of a product rotating on a turntable. The model kept making the product slide across the surface instead of spinning in place. This happened because the word "rotate" in my prompt was being interpreted as lateral movement rather than axis-based rotation. The fix was changing the prompt to "object spinning in place on a surface, 360 degree rotation, centered framing" and adding a negative prompt to exclude sliding motion. Kling allowed negative prompts. Most free tools do not. This was the one where investing five minutes in prompt engineering saved me an hour of rerolls. Another issue: facial consistency across frames. When generating videos of people, the face often morphs between shots. The workaround was using a lower motion strength setting and cropping tighter on the face. Less area for the model to distort. It is not a perfect solution but it reduces the problem significantly.
Things Nobody Tells You About Free AI Video Generators
Longer videos do not automatically mean better results. Some tools let you extend a generated clip by appending new frames. This usually degrades quality with each extension. The model loses coherence over time. A 3-second clip that works is better than a 10-second clip where the last 4 seconds look like a fever dream. Work with short segments. Combine them in an editor afterward if you need length. Watermarks are unavoidable on free tiers.
Every free generator I tested places a watermark somewhere in the frame. Usually a corner. Sometimes it animates. You can crop it out if the composition allows. You cannot remove it cleanly without the paid version. If you are using this for commercial work, factor in post-processing time or budget for paid credits. Queue times vary wildly. Free tiers share GPU capacity with paying users. During peak hours, a generation that should take thirty seconds can take eight minutes. Kling is particularly bad about this. Luma is slightly better but still slow. Pika tends to be faster since it runs through Discord. I learned to queue my generations during off-peak hours and walk away. Multitasking is the only way to manage free-tier latency.
Export formats are limited. Most tools output MP4 files. Some cap bitrate. If you need to import into After Effects or DaVinci Resolve for further work, the compression artifacts from the generator may compound with your own export settings. Consider exporting at the highest available quality even if it means larger files. Re-encoding degrades further.

When These Tools Actually Fail Completely
They fail on complex multi-object interactions. A person walking while holding an umbrella in rain will almost certainly break. The physics engine in these models is weak. They also struggle with text within scenes. If your image contains readable text and you add motion, the text usually distorts or disappears entirely. Do not use these tools for animated typography or subtitle effects. If you need reliable, production-ready output, the free tier will not get you there. Look at Runway Gen-3 paid plans, Pika Studio, or consider traditional methods like parallax layers in After Effects combined with optical flow. Those approaches require more manual work but produce consistent, controllable results. AI generation is a starting point, not a destination, for anything beyond personal or social media content.
Practical Workflow Recommendations
Generate multiple variations from the same image. Pick the best one. Extend only if necessary. Run the output through an upscaler if resolution is insufficient. Add sound design separately. The video itself will rarely be sufficient as a final deliverable. Free AI video generators are fast prototyping tools. They are not replacement pipelines. Treat them like that and you will save a lot of frustration.