Getting Data Into DBeaver Without Losing Your Mind
DBeaver is free and it works well for most day-to-day database work. The trick is knowing which import path to take, because DBeaver has several different ways to load data and they aren't interchangeable. Picking the wrong one will waste your time and sometimes corrupt your schema. I've been setting up databases and migrating data for over a decade, and I still see people use the SQL import dialog for CSV files like it's going to work. Download DBeaver from dbeaver.io. The Community Edition is free and covers everything most people need. Pick the version for your operating system and install it. That part is straightforward. Once it's running, connect to your target database first. File New Database Connection. Choose your database type, fill in the connection details, test it. You can't import anything without an active connection. I wasted about twenty minutes last month trying to import a MySQL dump into a connection I'd created but never actually tested. The import button was greyed out because the connection wasn't verified.
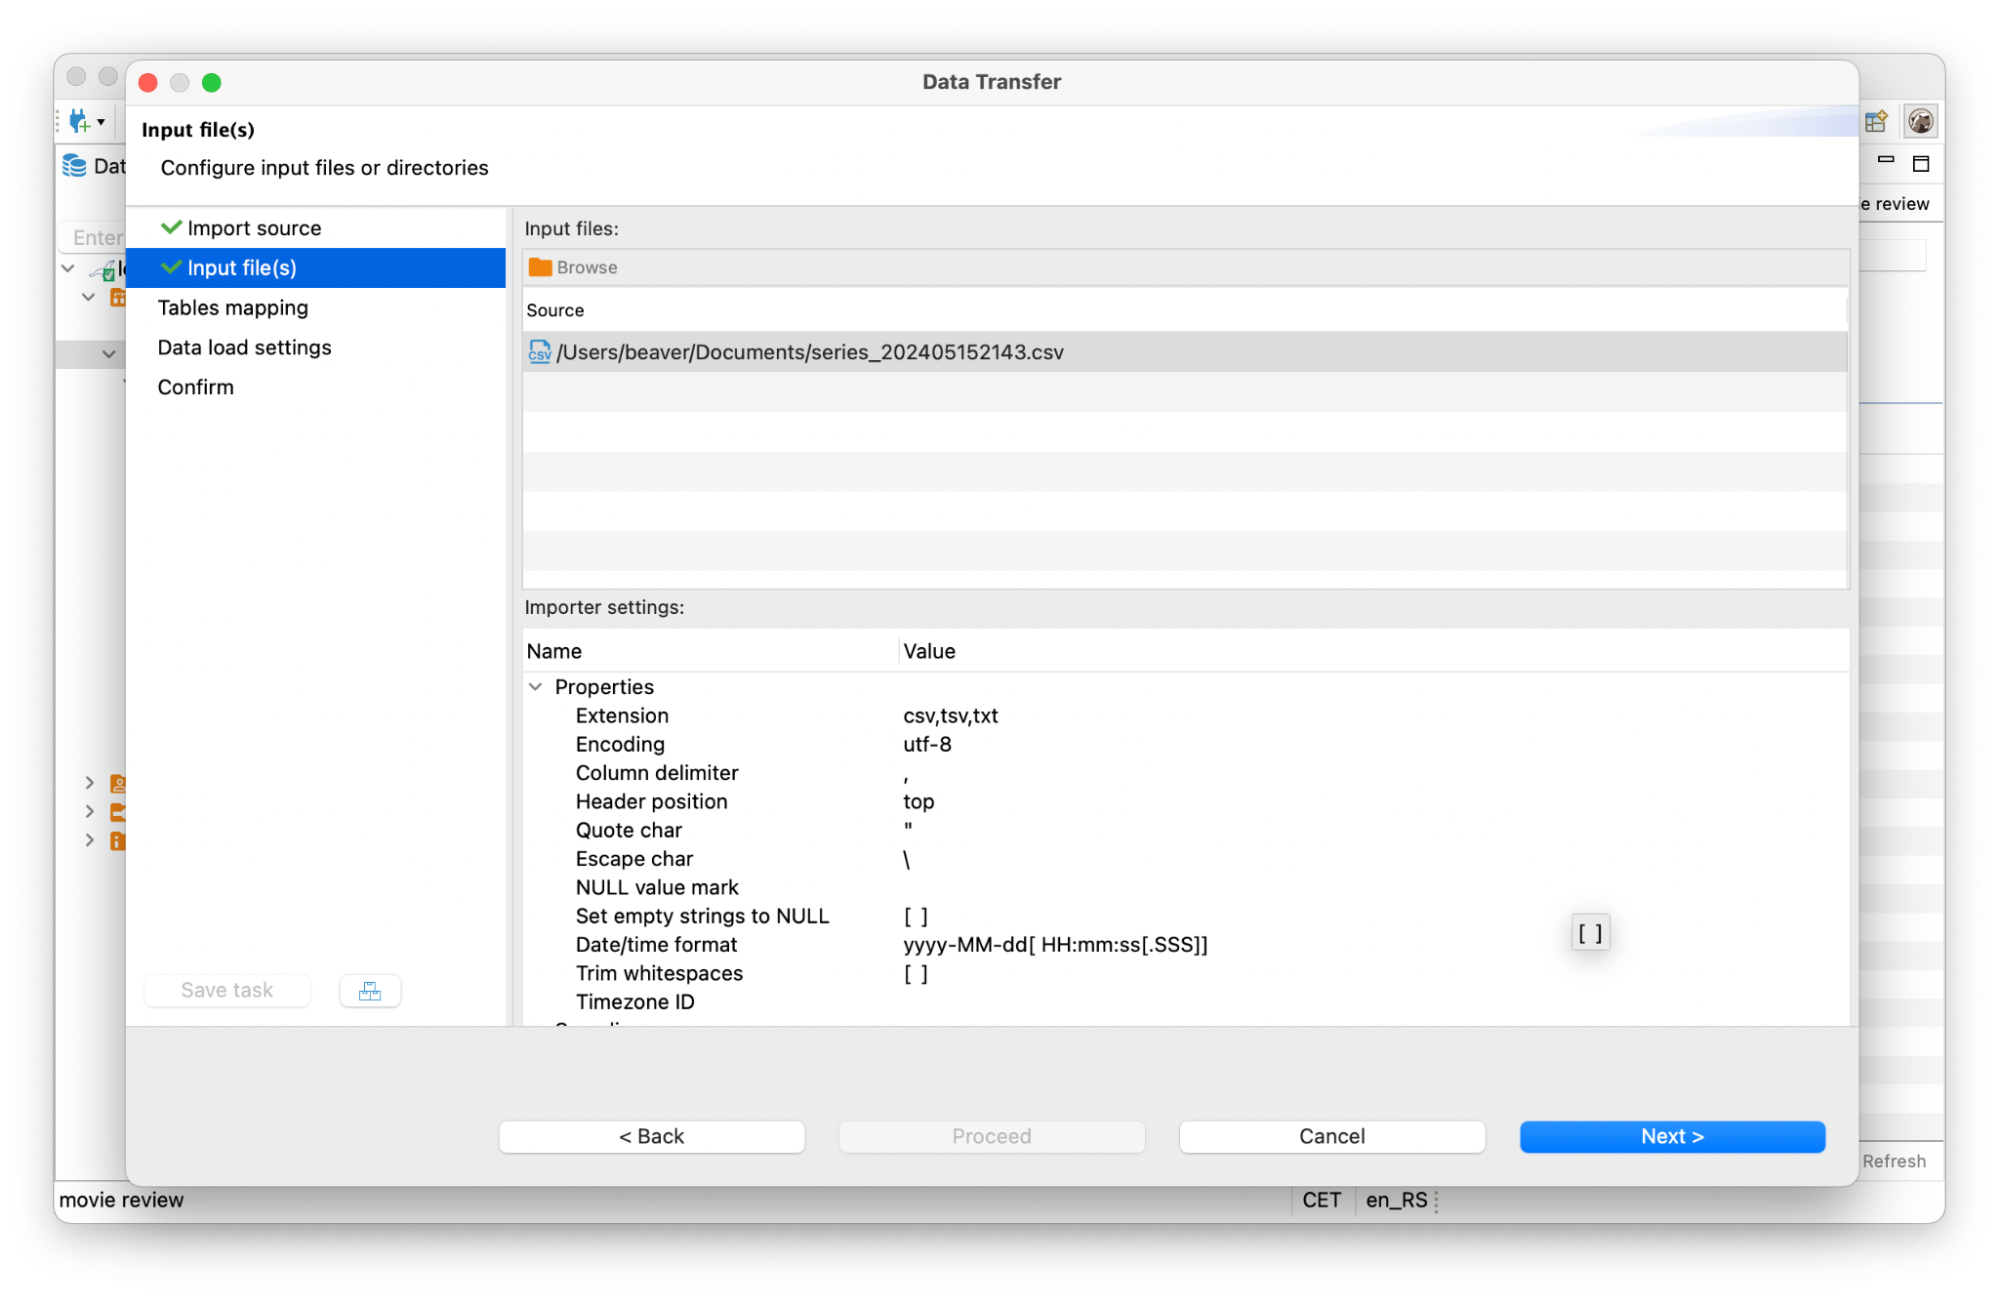
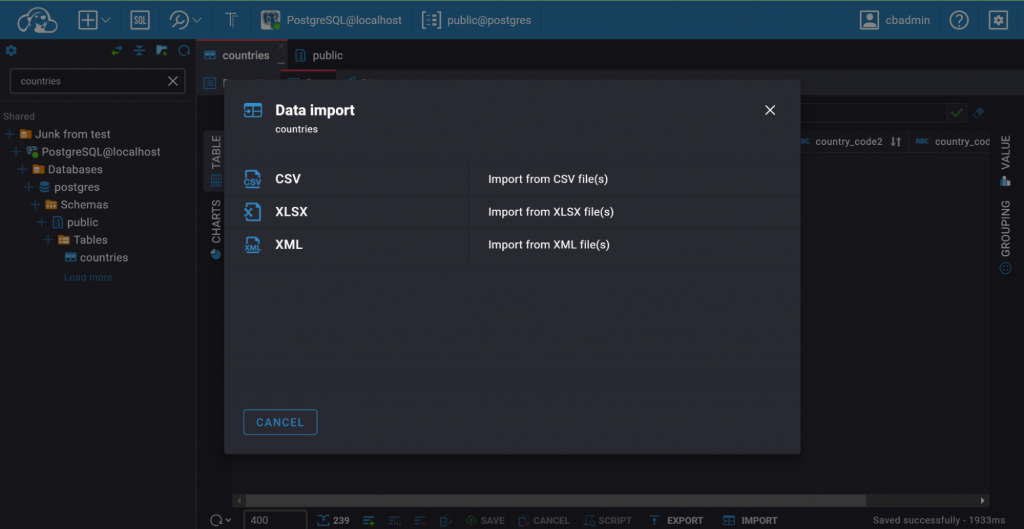
There are three main ways to bring data into DBeaver and each one serves a different purpose. The first is the SQL import for .sql files like database dumps. Right-click your database in the navigator. Tools SQL Import. Select the .sql file. DBeaver will parse the file and show you a preview before executing anything. This is useful for MySQL dumps, PostgreSQL scripts, and SQLite initialization files. The parser isn't perfect though. DBeaver sometimes chokes on stored procedures, triggers, or files that mix multiple statement types. When that happens, uncheck "Execute as single transaction" and split the import into smaller chunks. I learned that the hard way with a 400-megabyte WordPress dump that had custom MySQL functions mixed into the main body. The import failed halfway through every time until I pulled the function definitions into a separate file and imported them after the tables were loaded. The second method is the Table Import Wizard for structured data like CSV, TSV, Excel, or JSON files. Right-click the target table or create a new table first. Tools Import Data. The wizard walks through delimiter detection, column mapping, and data type assignment. This is where most people run into trouble. DBeaver will often guess the wrong data type for a column, especially dates stored as text. It might label a phone number field as numeric and strip leading zeros. Always review the column mapping screen before clicking finish. I imported a dataset last year and DBeaver converted all the postal codes to integers, wiping out the leading zeros. The data was recoverable but it cost me an afternoon of fixing.
The third approach is direct file copying for SQLite and some other embedded databases. If you have a .db or .sqlite file, you don't need the import wizard at all. Just place the file in your database folder and DBeaver can connect to it directly through the SQLite driver. This is the fastest path if you're working with exported database files rather than individual data dumps. The catch is that you can't always edit the connection properties afterward if the file has a non-standard encoding or uses extensions DBeaver doesn't recognize by default. Encoding issues are the silent killer of database imports. Most SQL dumps use UTF-8. Some older MySQL exports use latin1 or cp1252. If your import looks correct in the preview but the actual data comes through garbled, it's almost certainly an encoding mismatch. Set the file encoding in the SQL import settings before you start. For CSV files, check the encoding dropdown in the import wizard. I imported a Spanish legacy database recently and spent thirty minutes wondering why special characters looked like question marks before I realized the source file was encoded in ISO-8859-1, not UTF-8. Changing that one setting fixed everything instantly. Large file handling deserves its own mention. DBeaver's import tools will try to load the entire file into memory before processing. A 500-megabyte CSV will crash the application on most machines. I've seen it happen. For files larger than about 200 megabytes, split them first using a command line tool or a spreadsheet application, then import in batches of fifty thousand to a hundred thousand rows. The PostgreSQL and MySQL drivers in DBeaver also support batch insert configuration. In the connection properties, look for the batch size setting. Bumping it from the default of 1000 to 5000 or 10000 can cut import time significantly on large datasets. I reduced a 2-hour migration to about 25 minutes just by adjusting that one parameter on a PostgreSQL instance.
Get the Full Details
Foreign key constraints are another common source of frustration. If you're importing a dump file that references tables not yet created, DBeaver will fail on the constraint check. The workaround is to disable referential integrity checks before importing. In the connection properties, set the option to ignore foreign key violations or temporarily disable constraints. For MySQL specifically, you can add SET FOREIGN_KEY_CHECKS=0; at the top of your dump file before importing. For PostgreSQL, use the SET session_replication_role = 'replica'; equivalent. This isn't something to do casually. Only disable constraints when you're importing a full database dump where you know the dependency order doesn't matter because everything is being restored together. Schema conflicts come up more often than people expect. If you're importing into an existing database that already has tables with the same names, DBeaver gives you options. You can overwrite, skip, or append. Overwrite will drop and recreate the table. Skip leaves the existing table alone. Append tries to add rows to the existing structure, which fails if the column definitions don't match exactly. I always choose skip on the first pass and compare the schemas manually before deciding whether to overwrite. Rushing this step has cost me production data more times than I'm comfortable admitting. One thing DBeaver doesn't handle well is incremental imports. There's no built-in way to import only new or changed records. If you need to sync data from a source database on a regular schedule, DBeaver isn't the right tool. You'd be better off using something like AWS DMS, pgLoader for PostgreSQL migrations, or writing a custom script with Python and SQLAlchemy. DBeaver is designed for one-off imports and ad-hoc data loading, not ongoing replication. Trying to force it into a pipeline role will result in headaches and data inconsistencies.
The built-in database comparison feature is worth mentioning here as well. After you import data, you can use Tools Database Diff to compare your imported database against the source and verify that nothing got dropped or corrupted. It won't catch everything, but it'll flag missing tables, wrong row counts, and schema drift. I run this check after every import larger than a few thousand rows. Takes about two minutes and has saved me from deploying bad data twice this year alone. Performance varies considerably between database types. SQLite imports through DBeaver are generally fast for small to medium files under 100 megabytes because there's no network overhead. PostgreSQL handles bulk inserts reasonably well, especially with the batch size adjustment mentioned earlier. MySQL can be slow if you're using the InnoDB engine with many foreign keys because each insert triggers constraint checks. Turning off checks during import and re-enabling them after cuts MySQL import time dramatically on large datasets. If your import keeps failing for reasons you can't figure out, open the SQL editor and paste the contents of the file directly. Sometimes the import wizard's error handling is vague, but the SQL editor will show you the exact line that caused the failure. Line numbers in the error message usually point straight to the problematic statement. A missing semicolon, a truncated value, or an unexpected character will show up clearly this way.
DBeaver isn't the best tool for every import scenario. If you're moving terabytes of data, use dedicated ETL tools or database-specific utilities like mysqldump, pg_dump, or sqlite3 commands. DBeaver shines for mid-sized migrations, quick data exploration, and situations where you need a visual interface to understand what you're importing before committing to it. For routine database administration work, it's reliable and the free version covers most needs without requiring paid plugins or subscriptions.