Stem And Leaf Plots In SPSS: What They Actually Are And How To Use Them
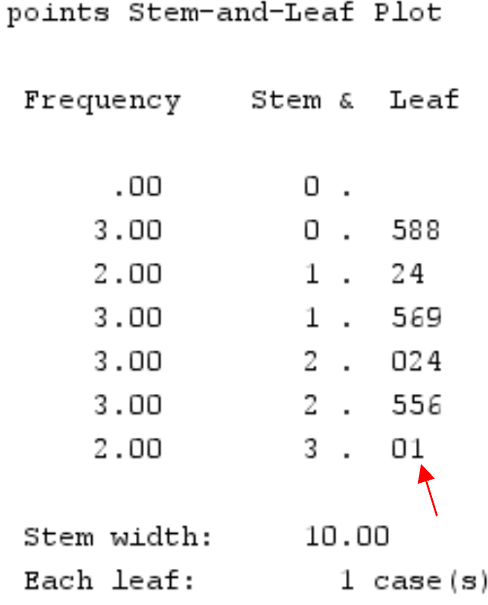
I've been working with SPSS for roughly twelve years, mostly doing quantitative analysis for academic research. I still run into people who either swear by stem and leaf plots or completely dismiss them. Both extremes are wrong. A stem and leaf plot is a way of displaying data that sits somewhere between a histogram and a raw data list. You split each value into a "stem" (usually the leading digit or digits) and a "leaf" (the trailing digit). It gives you the shape of a distribution while preserving individual data points. That's the whole concept. Nothing revolutionary about it.
Unlock The Power Of Data Visualization The Fascinating Story Of Stem And Leaf Plots In Spss
Getting one in SPSS is straightforward enough, but the defaults are almost never what you actually need. Go to Analyze > Descriptive Statistics > Frequencies, put your variable in the box, then click Charts. Select Stem-and-Leaf and make sure you check the box for Display Frequency Tables underneath. The output window will give you the plot plus a frequency table. SPSS calculates the stem width automatically based on your data's range, which means it sometimes picks something ridiculous for small datasets. Here's a practical problem I ran into recently. I was working with a dataset of about 87 observations measuring reaction times in milliseconds, ranging from 142 to 389. SPSS chose a stem width of 100, which meant every single data point landed in one of three stems: 1, 2, 3, or 4. The plot looked like a histogram with four bars and told you essentially nothing about the distribution within each range. I ended up writing a quick syntax command to override the default and use a stem width of 10 instead, which broke it into twelve stems and actually showed the bimodal pattern in the data. The syntax approach is faster once you get used to it. Something like this:
STEM AND LEAVES variable = reaction_time / CYCLE=10. That CYCLE keyword controls the stem width. Without it, SPSS guesses, and its guesses are unreliable for anything outside a standard normal distribution with a large N. One thing most beginners miss is that stem and leaf plots don't handle missing values gracefully in the output. If your variable has even a modest amount of system-missing data, SPSS will include those cases in the frequency table but won't show them in the plot itself. You might think your N is 200 when your actual stem and leaf is only showing 187. Always check your missing data before trusting what you see in the output window.
Get the Full Details

Another counter-intuitive detail: the leaves are always displayed in ascending order within each stem. This is useful if you're manually reading the plot, but it means you can't preserve the original sequence of your data. If you need to track which observations come from which time period or condition, a stem and leaf plot erases that information entirely. I learned that the hard way when I was trying to compare pre-intervention and post-intervention scores and realized I'd lost the grouping variable by the time the plot rendered. They work best for small to medium datasets, roughly under 500 observations. Beyond that, the plot becomes a wall of numbers that's harder to read than a histogram. A histogram with 20 or 30 bins will communicate the same distributional shape faster, and you can overlay a density curve on top of it. Stem and leaf plots start losing their advantage around N = 300 because there's simply too much data to parse visually. The real strength of the method is when you need to see individual values without generating a raw data dump. A researcher might glance at a stem and leaf plot and spot an outlier like 947 in a dataset where everything else clusters around 120 to 180. That kind of thing gets smoothed over in a histogram. You can also use the plot to check for zero-inflation or unusual gaps in continuous data, which is something I do regularly when validating survey scales before running factor analysis.
SPSS doesn't make it easy to customize the appearance much beyond the basic options. You can't change the leaf width independently from the stem width through the GUI. You can't add labels or annotations. If you need publication-quality output, you're better off exporting the data and using R or Python to render a cleaner version. I usually export the variable and write a simple script that generates a stem and leaf plot with proper formatting, because SPSS's native output looks like it came out of a 1990s textbook. The main limitation nobody talks about is that stem and leaf plots assume your data is roughly continuous or at least ordinal with enough granularity. If you're working with Likert scale data that only ranges from 1 to 5, the plot collapses into something useless because there aren't enough distinct values to create meaningful stems. I once spent twenty minutes trying to interpret a stem and leaf plot for a five-point agreement scale before realizing the exercise was pointless. A simple frequency table with percentages does the job faster and more honestly. So yes, the topic of Unlock The Power Of Data Visualization The Fascinating Story Of Stem And Leaf Plots In Spss has some genuine utility here and there, but it's not the kind of tool you reach for automatically. It's a descriptive statistics instrument, not a visualization centerpiece. Use it when you want to inspect the shape of a distribution alongside the actual values, and move on to something else when you don't. SPSS will generate it without complaint, but it won't necessarily give you a good one unless you intervene with syntax and a bit of experience.