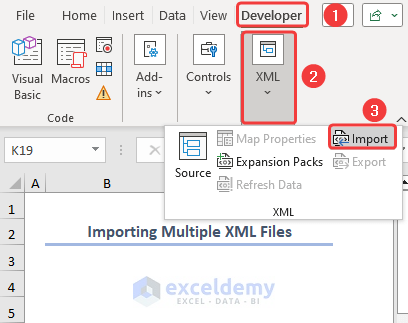
Excel can handle XML. It just doesn't make it obvious how.
Most people drag an XML file into Excel and get a flat, unreadable mess. That's because they're using the wrong import path. XML isn't a spreadsheet format, it's a structured document format, and Excel has two completely different engines for dealing with it. One is the old "From File" method under the Data tab, which parses XML as a flat table and strips away nesting. The other is Power Query, which respects the hierarchy and lets you expand elements the way you actually need them. Here's the part nobody tells you: if your XML file is over 50 megabytes, the traditional Get Data route in Excel will either hang your session or produce a truncated result. I ran into this with a client last year who had a 140-megabyte XML export from their ERP system. It was a purchase order dump with nested
The actual import process
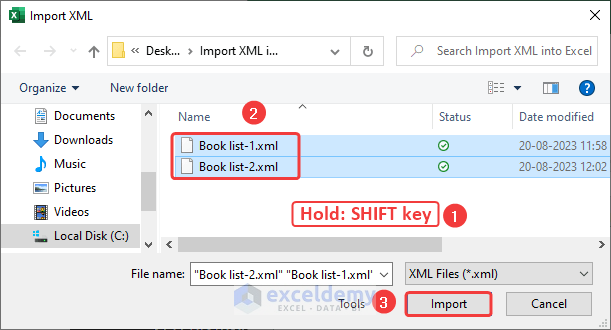
Open Excel. Go to the Data tab. Click Get Data, then From File, then From XML. Navigate to your file and select it. Excel opens the Navigator pane, which shows you the XML tree as a list of available tables. This is where most people stop and click Load, which gives them the first table in the file. That's almost never what you want. Instead, look at the right side of the Navigator. You'll see a Preview pane. Scroll through the tables until you find the one that matches your root element. If your XML has nested structures, you might see multiple tables listed. Click Transform Data to open Power Query Editor. From there you can expand columns by clicking the double-arrow icon in the column header. This is how you flatten nested XML without losing the parent-child relationships. When you expand a column, Power Query asks whether to expand to new rows or new columns. Expand to new rows if each parent record has multiple children and you want one row per child. Expand to new columns if you're pulling a fixed set of attributes from each nested element. Getting this wrong is the single most common mistake I see. It either duplicates your data across multiple rows or leaves you with null values scattered through columns.
What happens when things go wrong
XML schemas vary wildly. Some files use namespaced elements, which means every tag is prefixed like
Get the Full Details

Performance realities you should know about
Power Query is not infinite. Excel itself has a hard limit of roughly 1,048,576 rows per worksheet. Power Query can handle larger datasets in memory, but once you load the data back into a worksheet, you hit that ceiling. If your XML contains more than a million records, you need a different approach entirely. SQL Server Integration Services, Python with pandas, or even a database import followed by a linked table in Excel will serve you better. Even within the row limit, complex XML with deep nesting and many attributes can consume significant memory. A file that's 80 megabytes on disk might expand to several hundred megabytes in Power Query's internal model. If you're on a machine with 8 gigabytes of RAM or less, you'll likely see slowdowns or out-of-memory errors. Closing other applications before running the import helps, but it's not a substitute for having adequate resources.
A practical example
Let's say you have an XML file containing product catalogs. Each product has an ID, name, price, and a list of categories. The structure looks something like this: <product><id>12345</id><name>Widget</name><price>29.99</price><categories><category>Tools</category><category>Hardware</category></categories></product> Import this through Power Query. You'll get columns for id, name, price, and categories. The categories column will contain a record value. Click the expand icon on that column and choose the category field. Set it to expand to new rows. You now have one row per category per product, which is what you actually need for most reporting scenarios. If you had expanded to new columns instead, you'd get a max of however many categories the mapper detects in the first few records, and products with additional categories would be cut off.
When XML import isn't the right call
Sometimes the XML is so structurally irregular that Power Query can't map it cleanly. Files generated by dynamic systems that change their schema between exports are a common example. If the element structure varies from record to record, Excel will either skip the unexpected elements or create blank columns for them. In those cases, parsing the XML with a scripting language and outputting a clean CSV is faster than fighting with the mapper. A few lines of Python with the xml.etree.ElementTree library can extract whatever fields you need and write them to a well-structured CSV in under a minute, even for large files. There's also the question of refreshability. Power Query imports create a connection that can be refreshed when the source file changes. If you're working with a static XML file that won't update, the effort of setting up a Power Query connection is unnecessary overhead. Just copy the data or use a one-time import and be done with it.
Summary of what matters
Use Power Query, not the old XML mapper, for anything beyond trivial files. Check your file size before importing, and split large files if needed. Pay attention to namespaces and encoding issues early, because they compound as you build transformations. Know Excel's row limit and plan accordingly. And if the XML structure is too inconsistent, step outside Excel entirely and use a script to preprocess the data first.