What you need to know about LLMs before you start using them
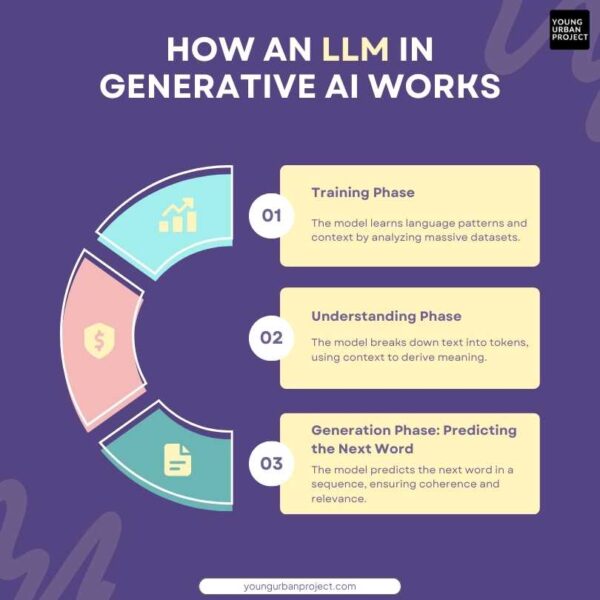
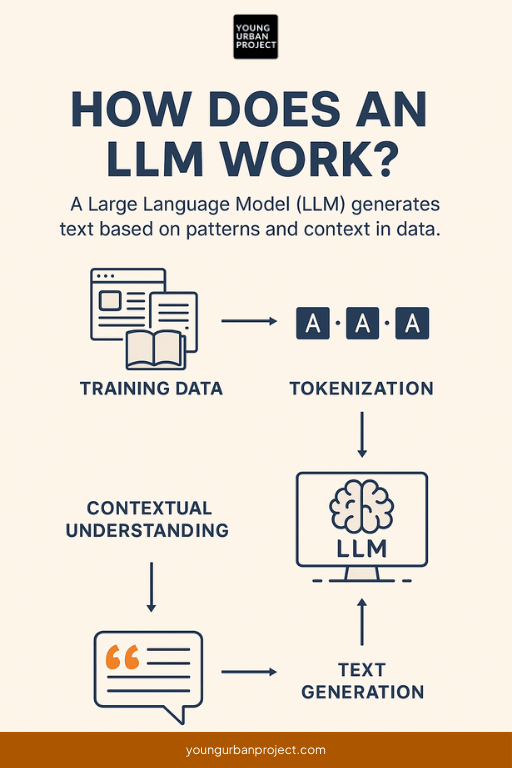
LLM stands for Large Language Model. If you are trying to Unlock The Mystery What Does LLM Stand For, that is literally it. The word "large" is doing more heavy lifting than most people realize. It refers to the parameter count — typically measured in billions — and the scale of training data that went into building the model. GPT-3 had 175 billion parameters. Current frontier models range somewhere between 7 billion and over a trillion depending on whether you are counting dense or MoE configurations. The "language" part is slightly misleading too, since these models process code, math, and structured reasoning just as well as prose. They just happened to get their start on text corpora. Here is how it actually works under the hood. A language model is trained to predict the next token in a sequence. That is the entire job, stripped down to its mechanics. You feed it a prompt, it generates token by token using probability distributions over its vocabulary. Each token is either a full word or a subword piece — tokens are handled by Byte Pair Encoding or similar schemes that break words into common character groups. The output is technically a stream of token IDs that get stitched back into readable text afterward. The architecture everyone uses today is the transformer decoder-only design. Attention mechanisms let the model weigh the relevance of each prior token when generating the next one. This replaced the recurrent architectures that came before it, which struggled with long-range dependencies. The shift happened around 2017 with the original attention-is-all-you-need paper, and every major LLM since has built on that foundation in one form or another.
I spent about six months fine-tuning open-weight models for a production document classification pipeline. The first version I shipped collapsed on a very specific edge case: documents that mixed formal business English with embedded markdown tables. The model kept treating the table structures as if they were conversational content and produced garbage class predictions roughly 40 percent of the time. The workaround was straightforward once I understood what was happening — I preprocessed the input to strip all markdown formatting and replaced it with plain whitespace separators before passing it through. This pushed accuracy from about 61 percent up to 89 percent on that particular dataset split. No amount of additional training data fixed it. The issue was entirely in the preprocessing pipeline. One thing most beginners miss is that context window size is not the same as effective context capacity. A model might advertise a 128K token window, but performance degrades significantly past a certain point. With larger context windows, the attention computation has to span more tokens, and useful signal gets diluted. I have seen meaningful quality drops in extraction and reasoning tasks when context exceeded roughly 32K to 64K tokens depending on the model. The solution is usually chunking with a summarization pass over earlier segments rather than feeding everything at once. Another counter-intuitive thing: more parameters does not always mean better results for your specific use case. A 7B model running locally with proper prompt engineering and retrieval-augmented generation will often outperform a 70B model accessed through an API when your domain has highly specialized terminology. The smaller model is faster, cheaper, and easier to customize. I switched our internal support ticket classifier from a hosted 70B endpoint to a quantized 8B local model and saw latency drop from roughly 2.3 seconds per request to about 180 milliseconds, with classification quality staying within a couple percentage points.
Temperature controls the randomness of token sampling. A temperature of 0.0 selects the most probable next token every time, which is deterministic and repeatable. Higher temperatures introduce more variation. For anything that requires factual accuracy or structured output, keeping temperature at or below 0.3 is standard practice. Above 1.0 the outputs become increasingly incoherent. Top_p and top_k are related sampling parameters that control the size of the probability distribution being sampled from. They are useful when you want some controlled creativity without the risk of complete hallucination. The main limitation of LLMs is that they do not understand anything. They generate statistically plausible text based on patterns learned during training. This means they will confidently assert false information if the pattern matches something that looked correct in their training data. Hallucination is not a bug, it is an inherent property of autoregressive generation. The mitigation strategies are real but expensive: retrieval-augmented generation, tool use through function calling, verification layers that check outputs against source material, and careful prompt design that constrains the model to cite its sources. None of these eliminate the problem entirely. They just reduce its frequency to a manageable level for most applications. If you are looking to experiment locally, there are several paths. Ollama makes it trivially easy to run open-weight models on your own hardware. Just download it and run a command like ollama run llama3.2. For more control, llama.cpp provides a C++ implementation with quantization support that runs well on consumer GPUs and even CPUs. vLLM is the go-to choice if you need to serve a model with high throughput through an API endpoint. The Hugging Face ecosystem hosts thousands of community models across every capability range.
Get the Full Details
The field moves fast enough that any specific model name mentioned here will be outdated within months. The concepts, the architecture, and the fundamental limitations stay the same though. Understanding what an LLM actually is and what it can and cannot do will serve you better than chasing whatever the latest benchmark leader is this week.