Why I Started Using ProxySQL on Google Cloud
ProxySQL is a database proxy that sits between your application and your MySQL-compatible database. It handles connection pooling, routing, query filtering, and failover. On Google Cloud, it runs alongside Cloud SQL or your own Compute Engine instances. I first deployed it about three years ago when my team was hitting connection limits on a secondary Read Replica under heavy read traffic. We were getting too many "Too many connections" errors and query timeouts. The basic setup is straightforward. You install ProxySQL on a VM, point it at your Cloud SQL instances, configure your routing rules, and then update your application connection strings to go through ProxySQL instead of connecting directly. What people don't always understand is how much configuration detail actually matters. The default config works for trivial workloads. Production traffic reveals the gaps quickly.
Unlock The Full Potential Of Your Database With Proxysql On Google Cloud
Getting value out of ProxySQL on GCP isn't just about installing it. It's about understanding how the proxy interacts with Cloud SQL's connection model. Cloud SQL has a maximum connection limit per instance, and that limit varies by machine type. A db-custom-2-7680 instance supports around 500 concurrent connections. Once you hit that ceiling, new connections queue or fail. ProxySQL sits in front and manages its own pool, typically capping out at fewer active connections to the backend while absorbing more from the application side. This is where the connection multiplexing advantage shows up. I run ProxySQL on Ubuntu instances in the same VPC as my Cloud SQL second-gen instances. You can also put it on Cloud Run with some limitations, but Compute Engine gives you more control over the network path and keeps latency predictable. The installation itself takes about ten minutes if you follow the official docs. The critical piece is the admin interface. ProxySQL exposes its configuration through a MySQL-compatible port on 127.0.0.1:6032. You log in with the default credentials admin:admin unless you change them during setup. I always change them. The production username and password live in the mysql_users table, not the admin credentials.
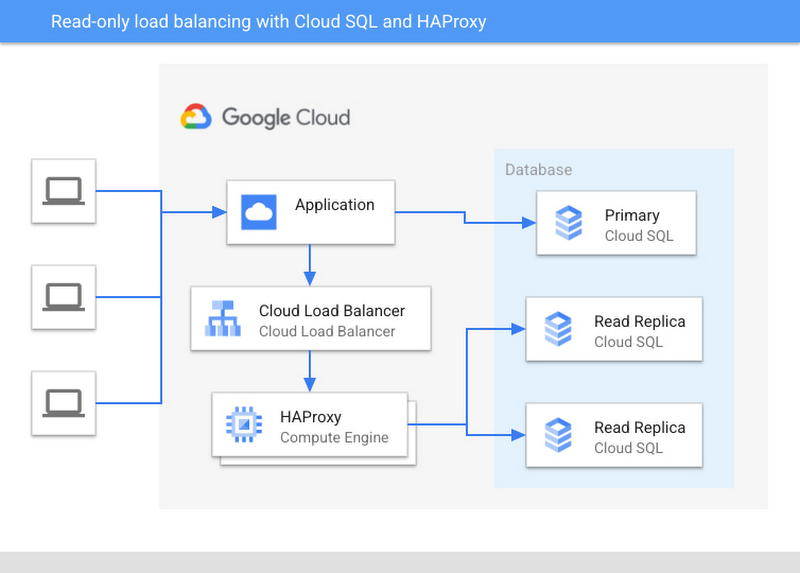
For routing to a primary and replica setup, the key tables are mysql_servers where you define your backends, mysql_replication_hostgroups for automatic read-write splitting, and mysql_query_rules for anything more granular. The replication hostgroups feature is useful because it automatically assigns SELECT queries to the read replica and writes to the primary based on server_group values. You set hostgroup_in for the primary and hostgroup_out for the replica.
Get the Full Details
Common Configuration Pitfalls
One thing that catches people off guard is how ProxySQL handles MySQL GTID-based replication tracking. If your Cloud SQL instance uses GTID mode, ProxySQL needs to read from the replica's binary logs or use the performance_schema to detect role changes. Cloud SQL doesn't expose binary logs the way a self-managed instance does. So the automatic failover detection through gtid_executed doesn't work the same way. I had to switch to manual hostgroup assignment with health checks instead of relying on the auto_failover feature. The health check interval is set in the monitor section of the configuration, typically every few seconds with a failure threshold of 2 to 3 checks. Another configuration detail that matters is the connect_timeout setting. The default is 1000 milliseconds. On GCP, if your ProxySQL instance and Cloud SQL are in different zones, you might see occasional connection timeouts during traffic spikes. I reduced it to 500 milliseconds and increased the reconnect_delay to compensate. The queries fail faster and ProxySQL retries sooner rather than holding connections open waiting. I ran into a specific issue recently that took me a couple of days to resolve. I had a high-traffic reporting query that was a JOIN across two tables on the read replica. ProxySQL was routing it correctly based on the query rule, but the query was taking longer than the connect_timeout on the backend side because of lock waits on the replica. The connection dropped, ProxySQL marked the server as unavailable, and then the entire read traffic shifted to the primary. This caused a cascade failure. The workaround was to set question_timeout at the ProxySQL level rather than relying on the MySQL server timeout. I set it to 30 seconds, which gave the query enough time without holding the connection indefinitely. I also added a separate query rule that routed that specific report query to a dedicated replica instance with higher resources.
Monitoring and Observability
ProxySQL exposes metrics through the stats schema. Tables like stats_mysql_connection_pool and stats_mysql_processlist give you visibility into active connections, latency per backend, and query distribution. I integrate this with Cloud Monitoring using a sidecar script that pushes the data at regular intervals. Without this integration, you're flying blind once something breaks. The mysql_query_rules_stats table is particularly useful. It shows hit counts and error rates per rule, which helps you validate that your routing logic is actually working as intended. I've seen cases where a misconfigured regex in a query rule silently sent all traffic to the primary because the pattern never matched, defeating the purpose of read-write splitting entirely. Regular review of this table prevents that from going unnoticed.
When ProxySQL Isn't the Right Choice
ProxySQL isn't universal. If your application has very few connections and low query volume, the overhead of managing a proxy layer isn't worth it. Cloud SQL's built-in connection pooling through connection limits and the Cloud SQL Auth Proxy handles simple cases fine. Also, if you're using Serverless SQL instances, ProxySQL adds an extra hop that increases latency for low-volume workloads. In those scenarios, you're better off optimizing your application-level connection handling directly. There's also the operational complexity angle. Every additional component in your stack introduces failure modes. ProxySQL itself can crash, get misconfigured, or suffer from memory leaks under extreme load. I've seen it consume over 2GB of RAM on a busy setup with thousands of concurrent connections. Monitoring the ProxySQL process itself becomes necessary. If you don't have the bandwidth for that, sticking with Cloud SQL's native features and scaling the database tier is the simpler path.