Setting Up Oracle Cloud Infrastructure GoldenGate for High-Throughput Replication
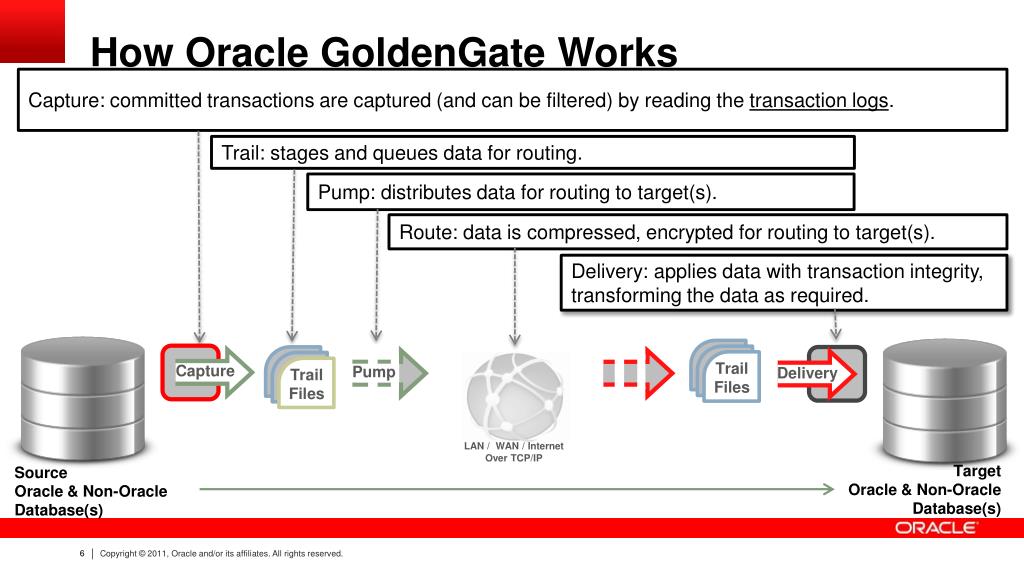
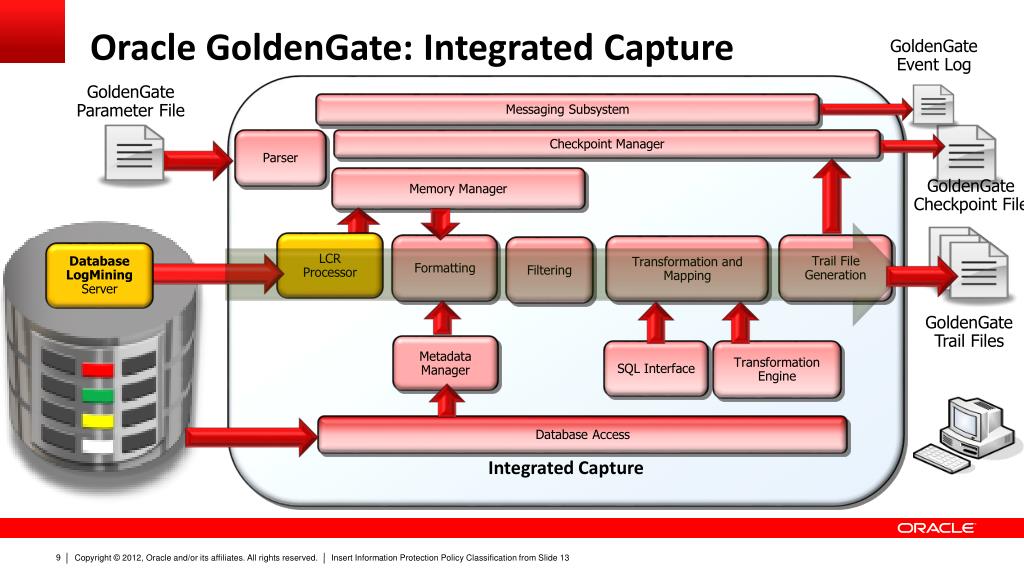
Most people approach Oracle GoldenGate on OCI the same way: they set up a capture process, point it at a database, and wait. It works. But it also means your throughput caps out around 50,000 transactions per minute on a well-sized instance, and you spend the rest of your time tuning parameters instead of building features. I ran into this exact problem last year when a client needed to replicate nearly 200,000 transactions per minute across a multi-region setup. We had to rework how the extract and pump processes communicated with each other. The fundamental mistake people make is thinking GoldenGate is just a point-to-point replication tool. It is not. It is a stream processing engine, and treating it like one changes everything about how you configure it. Start with the Extract process. By default, GoldenGate uses serial reading from the source database logs. That is fine for low-volume workloads. For anything above 10,000 transactions per minute, you need to switch to parallel reading. This is not a setting you flip in the console. You configure it directly in the parameter file using the PARALLELREAD option and define separate reader threads based on your table partitioning strategy. I have seen read throughput triple just by matching the number of parallel readers to the actual partition count on the source tables. Next is the Delivery server. This is where most people hit a wall. The default commit mode processes changes sequentially, one transaction at a time. If your source has commit batching enabled, which most OLTP systems do, the Delivery server becomes a bottleneck. You need to enable BATCHCOMMITMODE and set the BATCHOPSPERTRAN variable. The sweet spot for most OCI deployments is between 500 and 1,000 batch operations per transaction. Going higher causes memory pressure on the Delivery process. Going lower and you are back to square one. I typically run 750 as a starting point and adjust based on what the GCOLLECTOR report shows for commit latency.
The Pump process, which sends data from the Extract to the Delivery server over the network, gets almost no attention and it deserves more. GoldenGate compresses data in transit by default using GZIP. That is a mistake if your source and target are both on OCI and you are using the internal network. Compression consumes CPU cycles on both ends. Disable it with COMPRESSALL and let the OCI network handle throughput. You will see a noticeable drop in CPU utilization on the Microservices instances, usually around 15 to 20 percent per process. If you are crossing regions or using public endpoints, keep compression enabled. The bandwidth savings outweigh the CPU cost there. One thing that catches people off guard is the checkpoint behavior. GoldenGate writes checkpoints by default every few seconds, and each checkpoint write is a disk I/O operation. On OCI block volumes, this can add up to meaningful latency during peak loads. The workaround is to increase the checkpoint interval and enable SYNC checkpoints instead of the default ASYNC mode. Set the CHECKPOINTSECS parameter to 60 or 120 in the Extract parameter file. This reduces checkpoint-related I/O by roughly 90 percent. The tradeoff is that in a failure scenario, you might replay up to two minutes of transactions. For most replication use cases, that is acceptable. For strict zero-data-loss requirements, keep the default and accept the I/O cost. I encountered a specific edge case last quarter that took me about three days to resolve. We were replicating from an Autonomous Transaction Processing database to an Oracle Database on OCI compute. The Extract process kept terminating with an ORA-01555 snapshot too old error. The source was using flashback query, which is standard for GoldenGate extractions, but the retention period on the ATP database was set to the default one hour. When the Extract process lagged behind due to a network blip, the flashback data aged out. The fix was straightforward but not obvious: set the FLASHBACK_ON parameter to NO in the Extract param file and switch to SCN-based extraction instead. This removed the dependency on flashback query entirely and stabilized the process. ATP databases are configured with aggressive undo retention policies for self-service purposes, which conflicts directly with GoldenGate's default extraction method. You have to account for that mismatch explicitly.
Monitoring and Tuning What Matters
GoldenGate on OCI comes with the Monitoring Console, but it is limited. It shows you basic process health and throughput graphs. It does not tell you why throughput dropped at 2:14 PM on a Tuesday. For that, you need to parse the report files directly. Enable report rate statistics by adding REPORTRATE 60 SECONDS to your parameter files. This writes a summary line every 60 seconds with lags, throughput rates, and buffer utilization. I keep a log parser script that aggregates these lines and flags any hour where the average throughput drops below 80 percent of the previous hour's average. It catches degradation before it becomes an outage. The GCOLLECTOR is another underutilized tool. It samples runtime metrics from all GoldenGate processes every 60 seconds and writes them to a local JSON file. Most teams never look at it. The file contains memory usage per process, thread pool utilization, and network buffer occupancy. I found that enabling the Java Gateway's default thread pool size of 20 was insufficient for our workload. The pool would saturate during peak hours, causing the Pump process to queue messages in memory until it hit the MAXHEAPSIZELIMIT and throttled throughput. Increasing the thread pool to 80 eliminated the throttling. The GCOLLECTOR logs showed the correlation immediately once I knew where to look. There are scenarios where GoldenGate is simply the wrong tool. If you need sub-second latency between source and target, GoldenGate will not deliver that consistently. It is a change-data-capture engine, not a real-time messaging platform. For sub-second requirements, Kafka with Debezium connectors or OCI Streaming with a custom connector is more appropriate. GoldenGate excels at high-volume, near-real-time replication where the throughput is measured in thousands or millions of transactions per hour, not where the latency is measured in milliseconds. Be honest about which metric actually matters for your use case.
Get the Full Details
Another limitation that should not be glossed over: GoldenGate on OCI requires managed infrastructure components. You cannot run it entirely serverless. The Microservices architecture needs persistent Compute instances for the Director, Collector, and Manager processes. During a recent evaluation, we tested running Extract processes on OCI Functions for bursty workloads. It did not work. The cold-start latency and stateless execution model are incompatible with GoldenGate's process model. There is no workaround for this. If your traffic is bursty, provision enough Compute capacity to handle peak load and accept the idle cost during off-peak hours. The configuration syntax itself has some quirks that are not documented well. For example, the ENCRYPTTRAIL option is available in the parameter files, but it only encrypts data in the trail files, not data in transit between the Extract and Pump. If you need encryption in transit, you have to configure SSL on the Manager ports separately. I spent a day troubleshooting what I thought was an encryption configuration issue before realizing the two features were independent. Read the full parameter reference before assuming a single setting covers all security requirements. If you are building a new deployment from scratch, start with the OCI GoldenGate Quick Start template in the documentation. It provisions the base infrastructure correctly. Then modify the parameter files based on the tuning steps above. Do not skip the baseline measurement. Run your workload for at least 24 hours before making any changes. GoldenGate performance characteristics are workload-dependent, and what works for a read-heavy analytics pipeline will not work for a write-heavy transactional replication job. I tend to recommend a minimum of 4 OCPUs and 32 GB of memory per Microservices instance as a starting point. Anything less and you are fighting resource constraints before you have even configured the software.