Translating PDFs with Google Translate isn't as straightforward as you'd think
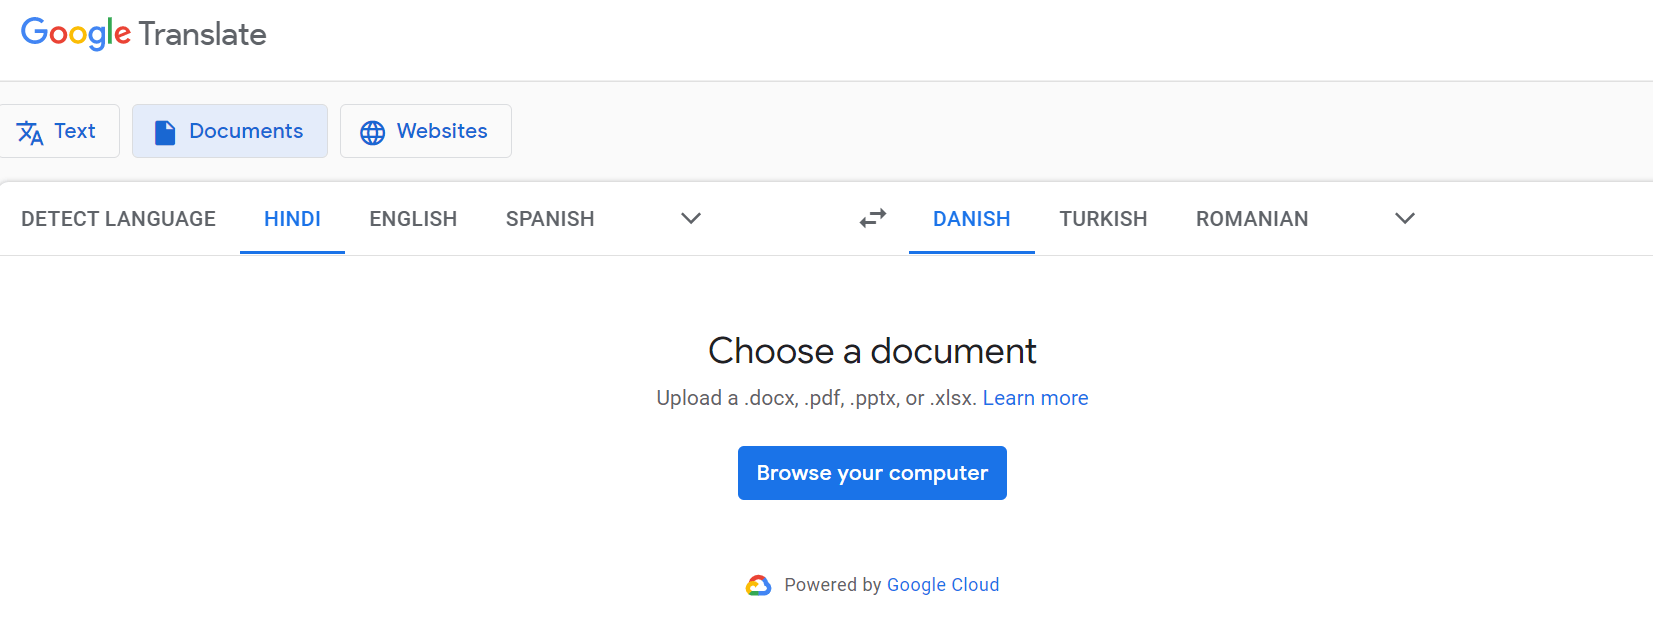
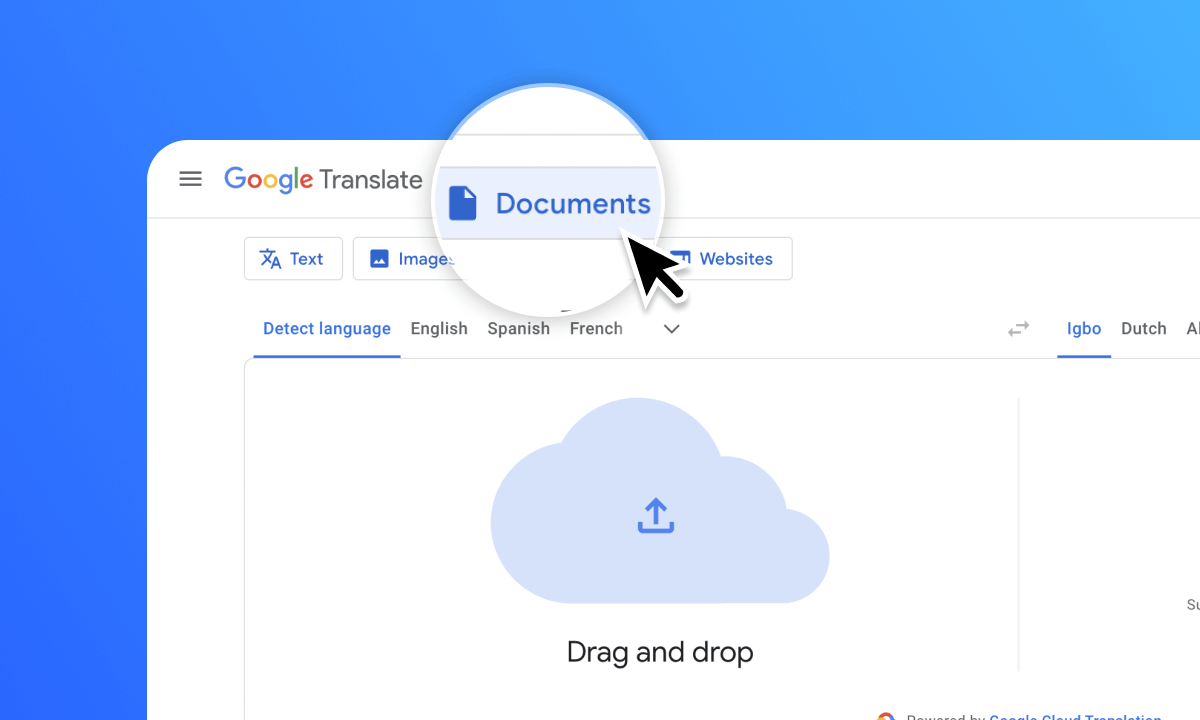
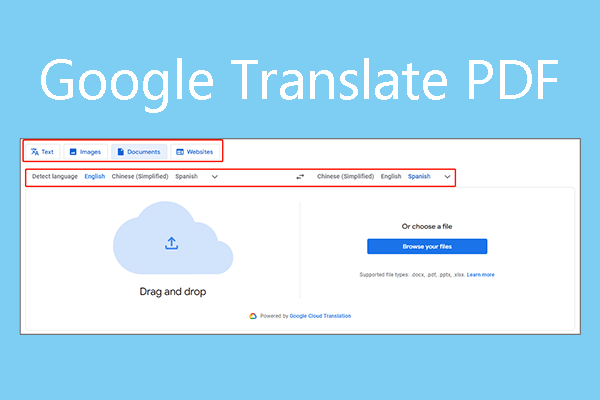
Google Translate can handle PDF files, but the output quality depends heavily on the document type, the source language pair, and whether the PDF is text-based or scanned. The tool itself is free to use at translate.google.com. You upload the file, pick a target language, and it returns a translated version you can download. That's the surface-level explanation. The reality is messier. To use it, go to the Google Translate website, click Documents on the left sidebar, drag and drop your PDF, select the source language (or leave it auto-detect), choose the target language, and hit Translate. It processes the file and offers a download link within seconds for most documents under about 10 megabytes. Files larger than that either time out or get rejected outright. The big catch most people don't anticipate is that Google Translate preserves the original layout but swaps only the visible text. Tables shift. Images stay put. If your PDF has mixed languages or right-to-left scripts like Arabic or Hebrew, the formatting often breaks. Characters overlap. Column widths collapse. I spent an afternoon translating a German technical manual into Japanese and ended up with three pages of unreadable garbage because the justified text alignment in the source got lost in translation. The workaround was to run the English translation first as an intermediate step, then translate from English to Japanese, which produced marginally better structural results.
Text vs. scanned PDFs matter more than anything else
A native PDF with selectable text translates cleanly because Google's OCR pipeline isn't involved. A scanned PDF—basically a gallery of images wrapped in a PDF shell—forces Google to run its optical character recognition before it can do anything. The quality drops noticeably. Numbers get misread. Accented characters vanish. Specialized terminology in engineering or legal documents frequently comes back wrong because Google Translate treats domain-specific terms as ordinary vocabulary. I once tried translating a scanned French invoice and Google interpreted a currency symbol as a random character, producing something like €5,2@ instead of €5,20. The workaround there was straightforward: download the translated PDF, spot-check critical numbers, and manually correct the output. Nobody expects automated translation to be financially accurate without a human review pass.
Language pair limitations you should know about
Not every language combination works well. High-resource pairs like English to Spanish, English to French, or English to German tend to produce decent results. Low-resource pairs like English to Swahili or Yoruba often read like machine-generated guesses. The quality gap between top-tier and bottom-tier language pairs can be the difference between a readable document and one that requires heavy rewriting. There's also the issue of script direction. When translating from a Latin-script language into Thai, Bengali, or other scripts that don't use spaces between words, Google Translate handles the conversion adequately for general content. But technical documentation with embedded code snippets or file paths often breaks because those segments shouldn't be translated at all and the model doesn't always respect that boundary.
Get the Full Details

Practical advice that actually helps
If your document contains important tables, run each table through the regular text translation box instead of uploading the full PDF. You get better control over formatting and can paste results back into a new document. For documents with images containing text, translate the text separately or accept that the image will remain untranslated. The tool does not translate text embedded inside photos or graphics. Google Translate also strips hyperlinks from the original PDF. Any clickable references, table of contents entries, or cross-references become dead after translation. If link integrity matters, you'll need to rebuild navigation elements manually or use a different tool designed for preserving document structure.
When to use something else
If you need translation quality close to professional standards, Google Translate is a starting point, not an endpoint. Tools like DeepL offer noticeably better accuracy for European language pairs, though they charge per document and don't support as wide a range of languages. For scanned PDFs requiring high accuracy, dedicated OCR software paired with a human translator is the only reliable route. Adobe Acrobat's own translation features produce comparable results to Google's approach but integrate better with existing workflows if you already subscribe to the Adobe ecosystem. The file size limitation is another real constraint. Anything over 10 MB gets rejected without exception. Large catalogs, manuals, or multi-page reports need to be split beforehand. I usually divide large PDFs using a free tool like PDFsam Basic, translate each section separately, then merge the translated files back together. It adds roughly twenty minutes to the process but prevents timeout failures on anything substantial. Bottom line, Google Translate handles basic PDF translation for general content reasonably well and costs nothing. It breaks down on technical documents, scanned files, complex layouts, and low-resource language pairs. Know what you're working with before you upload.