Reading the McDonald's Feedback Loop Like a Practicing Manager Would
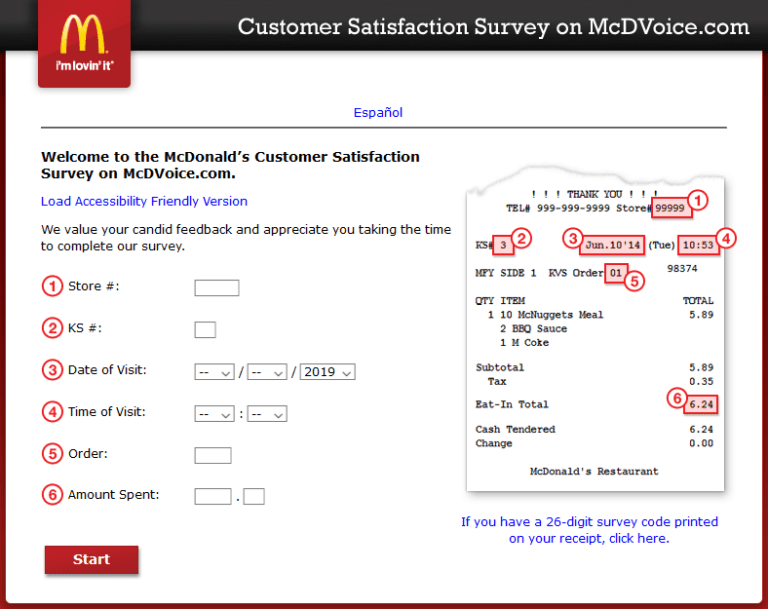
mcdvoice.com is a customer satisfaction survey platform operated by Qualtrics for McDonald's Corporation. It collects transaction-specific feedback from guests within 48 hours of a visit. Receipt data drives entry. A store receipt carries a unique 21-digit survey code that unlocks one completed survey per receipt. You do not get unlimited entries. You do not get to re-submit using the same code. The system validates receipt checksums against point-of-sale logs, and once a code is consumed, it is marked as used in the database. Most people who stumble onto this process are either corporate analysts aggregating data across regions, or franchise operators who want to turn survey responses into something actionable instead of just watching their overall score tick upward by 0.3 points next quarter. The difference between those two outcomes comes down to how you read the data. McDVoice does not surface open-ended commentary in bulk. It does not give you raw transcripts. What it gives you is structured categorical data tied to specific transaction attributes: order type, item count, time of day, device used, and a handful of Likert-scale dimensions around food quality, cleanliness, speed, and staff courtesy. The insight lives in the cross-tabulation, not in any single metric. I spent three years managing regional survey dashboards for a multi-unit operator, and the thing nobody tells you going in is that the survey response rate is heavily skewed. The people who take the survey are not representative of the total customer population. They tend to be either extremely satisfied or extremely frustrated. Neutral experiences get dropped. If you are running your business decisions off an unadjusted aggregate score, you are making decisions on a sample that systematically excludes the middle 60 percent of your traffic. That is a real problem. The workaround I used was to weight the monthly averages by transaction volume from the POS system for each store. Once I normalized the survey scores against actual foot traffic, the picture changed completely. Stores that looked good on paper actually had declining sentiment when measured per captured transaction. The unweighted dashboard was lying to me.
The Practical Workflow
Access the survey at mcdvoice.com and enter the survey code found on your receipt. Complete the questionnaire. After submission, you receive a PIN for a meal reward. That part is straightforward. The harder part is extracting operational value from what you submit, whether you are a customer giving feedback or a manager reviewing aggregated results. For managers, the workflow goes like this. Log into the McDVoice manager portal using your store credentials. Pull the weekly and monthly aggregated reports. Focus on the trend lines, not the single-week snapshots. A single week is noise. Look at rolling 4-week averages to smooth out weekend rushes, promotional spikes, and staffing anomalies. Cross-reference low-scoring dimensions with your labor schedule and your menu engineering data. If speed of service drops every Tuesday between 11:30 and 1:00, and your Tuesday lunch shift has two fewer team members than Wednesday, that is your answer. It is not a training problem. It is a scheduling problem dressed up as a service problem. There is a quirk in the survey design that catches people off guard. The order type question forces you to select one: drive-thru, counter, mobile order, or delivery. If your store sees a lot of hybrid behavior, like someone who orders on the app but picks up at the counter, the data gets noisy. I encountered this at a high-volume suburban location where mobile order pickup accounts for roughly 40 percent of transactions. The survey code still works, but the category mapping skews because the guest selects counter even though the order originated digitally. The workaround was to create a supplemental internal tracking log that recategorized those transactions manually based on the POS order type field. Without that correction, the mobile order experience scores looked artificially low compared to the drive-thru scores, which was backwards from what the operational reality actually showed.
What the Data Actually Shows You
The core scoring dimensions break down into food quality, temperature, accuracy, cleanliness, friendliness, and speed. Each is measured on a scale, usually four or five points. The aggregate score that McDonald's publishes internally is a composite, but the exact weighting is not public and varies by market. Do not obsess over the headline number. The useful signals are in the dimensional breakdowns and the open text fields when they are available. Open text is sparse in McDVoice. Most respondents do not write comments. When they do, the comments are usually about specific incidents: a missing item, a cold fry, a rude interaction. These are high-signal data points but low volume. I learned to track them separately rather than letting them get buried in the categorical averages. A cluster of three or four comments mentioning the same issue across different receipts in the same week is a real operational signal, even if the overall food quality score for that week only dipped by 0.1 points. Another counter-intuitive finding from my experience is that cleanliness scores are remarkably stable and rarely correlate with actual operational issues. Cleanliness is easy to improve in the short term through visible cleaning routines. It does not predict repeat visitation the way order accuracy and speed do. I once had a district manager pressure a store to improve its cleanliness score because it was slightly below the regional average. The store deep-cleaned for two weeks. The score moved up one point. Repeat visitation did not budge. Meanwhile, the same store had an accuracy problem that was dragging down the composite, and we ignored it because accuracy felt harder to fix. Accuracy was the real lever. Cleanliness was theater.
Get the Full Details

Common Pitfalls
The first pitfall is treating a single month of data as definitive. Survey scores fluctuate. Seasonal menus, local events, staffing changes, and even weather affect results. Use at least eight weeks of data before drawing conclusions. The second pitfall is comparing stores that serve different populations. A downtown lunch crowd has completely different expectations and behaviors than a suburban family destination. Cross-store comparisons only work when you control for store format and trade area demographics. The third pitfall is responding to every low score with training reminders. Most low scores are system problems, not people problems. Wrong orders come from misconfigured kitchen timers or broken ticket printers. Slow drive-thru times come from bottlenecking at the expeditor window, not from unfriendly cashiers. Fix the system first. Training is the last step, not the first. McDVoice has real limitations. It does not capture negative experiences that do not result in a survey response. A customer who gets a wrong order and swears never fills out the survey. They just leave and never come back. That churn is invisible in the data. It shows up later in declining same-store sales, but by then the root cause is already months old. If your store depends entirely on McDVoice feedback, you are flying blind on the most important segment: the people who are quietly defecting. The second limitation is recency bias. The survey asks about a specific visit. It does not track loyalty, lifetime value, or emotional attachment to the brand. A customer can rate a visit highly and still stop coming because of price, convenience, or competing options. McDVoice cannot tell you why. For that, you need transaction history analysis, loyalty program data, and competitive benchmarking. The survey is one input, not a strategy.
If you want deeper insight, supplement McDVoice with direct customer interviews, social media sentiment monitoring, and POS-level error tracking. One operator I worked with ran weekly 10-minute exit interviews at a single flagship store. The qualitative data from those conversations corrected half of the assumptions they had built from the survey dashboard. The cost was minimal. The insight was disproportionate.
Practical Takeaways
Read trends, not snapshots. Weight scores by transaction volume. Separate open-text comments from categorical averages. Cross-reference survey dimensions with operational data from your POS and labor scheduling system. Do not chase cleanliness scores at the expense of accuracy and speed. Validate survey findings with other data sources before changing store-level processes. And remember that the survey only captures people who choose to respond, which is a self-selected group with its own biases built in. The platform itself is functional. It is not elegant. The interface is dated. The reporting tools require patience. But the data is real and it is tied to real transactions. The operators who treat it like a report card instead of a diagnostic tool end up managing the metric instead of the business. The ones who dig into the cross-tabs and correct for sample bias end up with a usable map of what is actually happening in their stores. The difference is modest in theory and significant in practice.