Understanding the Tropical Savanna Climate (Köppen Aw and As)
The Köppen climate classification system designates tropical savanna as category Aw, with a secondary variant As for those rare cases where the dry season occurs during the hemisphere's summer months instead of winter. The distinction matters more than most people realize when you are actually trying to identify what type of savanna you are working with. What defines an Aw climate is straightforward on paper: every month averages above 18°C, and there is a pronounced dry season where the lowest-precipitation month receives less than 60 millimeters and also drops below the threshold of 100 minus one-seventh of total annual rainfall. But the moment you start looking at real station data, the definitions blur considerably. Many stations labeled Aw by automated systems actually show marginal or inconsistent dry seasons that barely clear the threshold, which means you need to understand how these classifications were originally constructed before applying them blindly. The original work by Köppen and later refinements by Geiger treated these climates as transition zones between tropical rainforest and arid regions. That framing turned out to be both accurate and limiting. These are not just intermediate states. They are stable, self-reinforcing climate regimes shaped by the seasonal migration of the Inter-Tropical Convergence Zone, continental moisture sources, and topographic effects that no simple formula captures.
Unleashing The Secrets Of The Tropical Savanna Climate And Beyond
If you are trying to classify climates or model precipitation patterns in these zones, the first thing you need to accept is that satellite-derived rainfall estimates are your starting point, not your answer. Instruments like CHIRPS and GPM give you decent coverage, but they consistently overestimate dry-season rainfall in savanna zones by 15 to 40 percent depending on the region. I spent about three weeks last year trying to reconcile CHIRPS data against ground station records across the Sudanian savanna belt from Senegal to Sudan, and the discrepancy was worst precisely in the dry months I needed most. The workaround was straightforward enough but tedious: cross-reference with GPM IMERG final run, apply a monthly bias correction derived from the closest 10 stations within a 200-kilometer radius, and only then treat the corrected grid as usable for seasonal analysis. Without that step, your dry-season duration estimates will be systematically too short. The second thing you need to understand is that the dry season in a tropical savanna is not simply a period of reduced rainfall. It is a period of intensified evapotranspiration stress caused by elevated solar radiation, persistent trade-wind flow, and often dust aerosol loading that suppresses convective development even when moisture is technically available. This is why vegetation responses in these zones are often decoupled from rainfall alone. Researchers who rely solely on precipitation totals without accounting for vapor pressure deficit end up mischaracterizing the growing season by several weeks.
Practical Identification and Data Sources
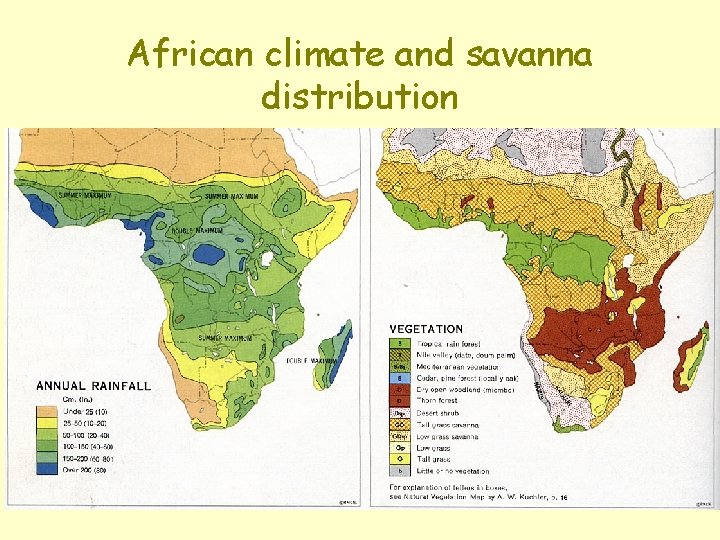
The global extent of tropical savanna climates covers roughly 14 to 18 percent of Earth's land surface, with the largest continuous stretches in sub-Saharan Africa, the Brazilian Cerrado, parts of northern Australia, and fragmented pockets in Central America and South Asia. If you are building a dataset, starting from the Beck et al. 2018 global climate classification at 1-kilometer resolution will save you considerable time compared to working from raw station data alone. Their classification uses a machine-learning approach trained on 321 reference stations and has proven more consistent than older global products, particularly in complex terrain where the original Köppen scheme tends to fragment unrealistically. For time-series work, the CRU TS 4.07 dataset remains the standard for gridded climate observations, though its 0.5-degree resolution smooths over important local variability in savanna regions where orographic and land-surface feedbacks matter. Pair it with ERA5-Land reanalysis if you need higher resolution down to 9 kilometers. The reanalysis captures soil moisture and vegetation dynamics better, but it inherits the same dry-season rainfall bias issues I mentioned earlier, so validation against ground data is still necessary for any published work.
Get the Full Details
Common Pitfalls in Savanna Climate Analysis
Beginners typically make the same mistakes repeatedly. The first is treating the Aw classification as homogeneous. A savanna in southern Mali with 900 millimeters of annual rain behaves fundamentally differently from one in northern Nigeria with 1200 millimeters, even though both are Aw. The vegetation structure, fire regimes, and hydrological response scale nonlinearly with total rainfall and with the ratio of wet-to-dry season precipitation. You should always stratify your analysis by annual rainfall amount and dry-season length rather than relying on the broad classification alone. The second mistake is assuming that temperature variability is unimportant in these climates. The diurnal temperature range in many savanna regions exceeds 15°C during the dry season, and this oscillation drives physiological stress in both natural and agricultural systems. Models that only use mean temperatures systematically underestimate drought impact in these zones. Including amplitude metrics like standard deviation of daily maximum and minimum temperatures improves predictive accuracy for crop yield and ecosystem response by a meaningful margin. A third issue that deserves more attention is the interaction between savanna climates and land-use change. Clearing forest for agriculture in these transition zones often pushes the local climate toward savanna-like conditions even where the broad classification does not change. This albedo and evapotranspiration feedback can be detected within a decade using satellite NDVI combined with near-surface temperature records, but it requires longitudinal analysis rather than snapshot classification. Single-year assessments miss this entirely.
Tools and Workflows That Actually Help
R-based climate classification libraries like climdex and climateR handle many of the mechanistic calculations, but they assume clean station data. If you are working with gridded datasets, the python package xclim built on xarray gives you the most flexibility for batch processing large climate grids. It includes built-in functions for dry-season identification, Aridity Index computation, and Köppen-Geiger classification at grid scale. For visualization, the ncview tool remains useful for quick interactive inspection of NetCDF climate fields, and Cartopy in Python handles the geographic projections cleanly when you need maps. If you are doing long-term trend analysis, the Sen's slope estimator available in the python-rankstats package pairs well with the Mann-Kendall test for trend significance, and together they handle the autocorrelation issues that commonly plague savanna rainfall time series. I typically run my classification pipeline in this order: download the raw NetCDF files, apply bias correction against station data for the calibration period, compute the Köppen classification at each grid cell, mask out non-Aw cells, then overlay with land-cover and topographic layers to identify subtypes. The whole process for a continental-scale analysis takes roughly 45 minutes on a standard machine once the pipeline is set up, compared to several days if you were doing it manually or starting from uncorrected data.
Where This Approach Falls Short
No single classification system captures everything. The Köppen scheme ignores soil type, which strongly influences how savanna soils respond to reduced rainfall. It also treats the dry season as purely precipitation-defined, whereas atmospheric circulation patterns like the West African monsoon withdrawal or the Indian monsoon retreat involve dynamic processes that precipitation alone does not reflect. If you need to study the mechanisms driving savanna climate variability rather than just mapping its boundaries, you will need to incorporate circulation indices like the Monsoon Trough position or the Southern Oscillation Index alongside precipitation data. For ecological applications specifically, the savanna biome is better characterized using functional-type classification based on plant traits and fire regime rather than climate classification alone. The Whittaker biome diagram, while decades old, still provides a more ecologically relevant framework when your question involves vegetation dynamics or carbon cycling. Mixing climate classification with biophysical data from MODIS and LAI products from the Global Land Surface Satellite dataset tends to produce the most robust results for ecosystem-oriented studies.