Weather Radar Access in Huntsville: What Actually Works
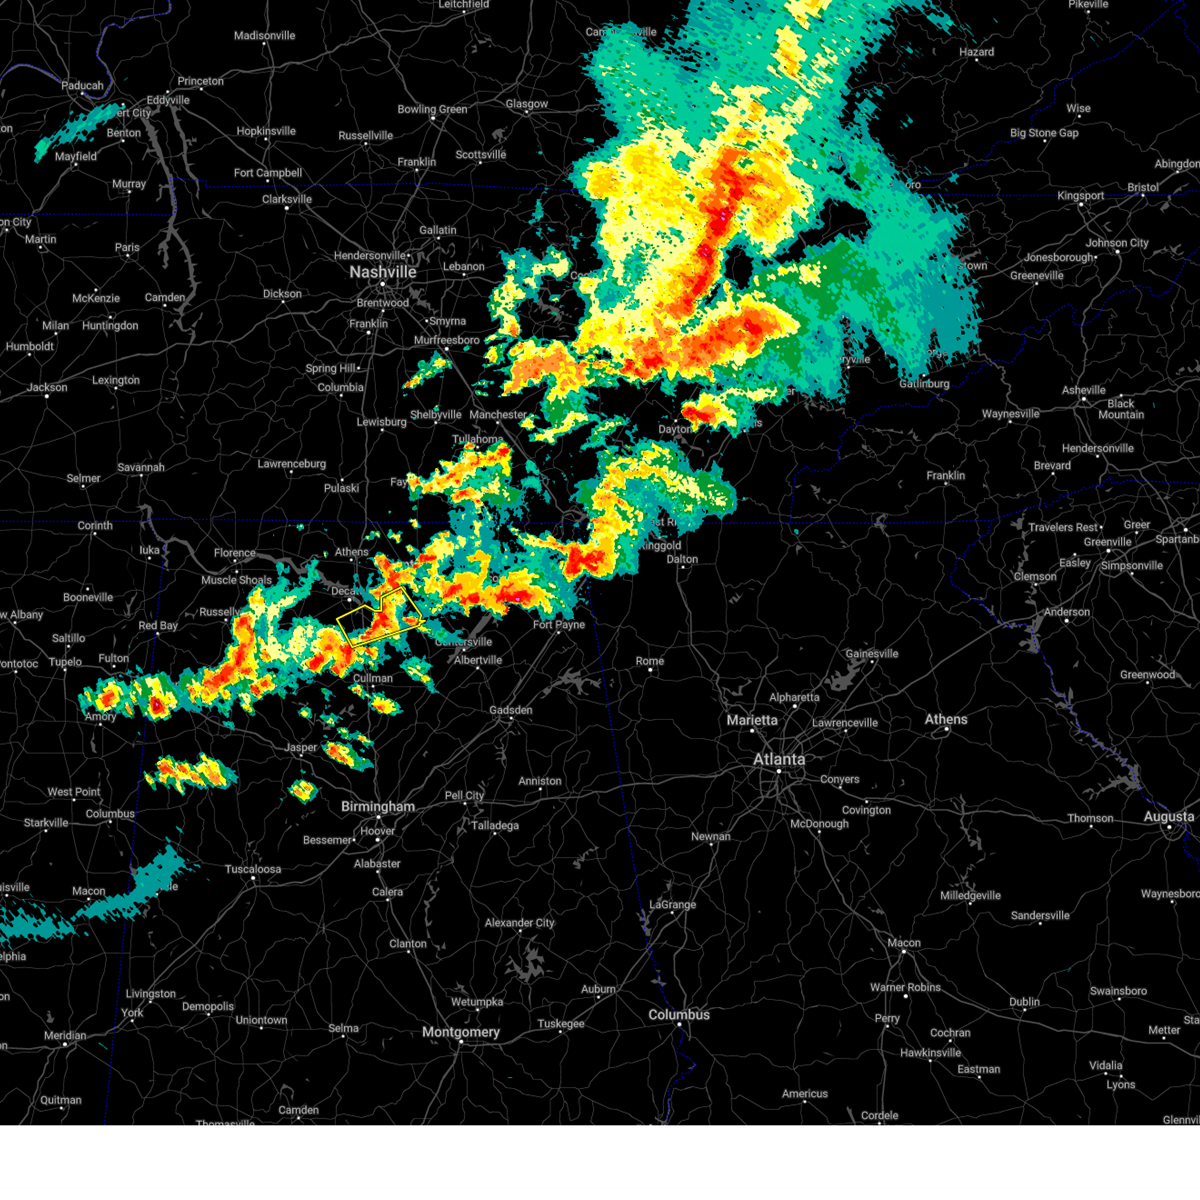
The weather radar situation in Huntsville is complicated by geography and infrastructure. You have the WSR-88D from the National Weather Service, research-grade S-band and C-band systems at nearby facilities, and a mess of proprietary data streams that don't talk to each other. I've spent years working with this stuff, mostly getting frustrated by format inconsistencies and missing elevation angles. Here is the honest breakdown. Huntsville sits in an area where multiple radar sites have overlapping coverage, which is technically a good thing but a nightmare for anyone trying to stitch together a clean composite. The primary NEXRAD site serving the area is located in Birmingham (KBMX), but the proximity to the NSSL facilities means research-grade data occasionally bleeds into public feeds with different timing. I learned this the hard way when I was trying to build a time-series of reflectivity values. The NSSL data was updating on a different cycle than the operational WSR-88D, and my composites were showing phantom storm cells that existed in neither dataset. The workaround was straightforward once I figured it out: pull both sources, check their metadata timestamps, and discard any volume scan that didn't fall within a 90-second window of the others. It adds maybe twenty minutes to the initial setup but saves hours of debugging later. The most commonly used data source is Level II NEXRAD from the AWS Open Data portal. You can pull it directly from s3.amazonaws.com/nexrad-level2. The files are laid out by date and product code. Product code VCP 12 is your standard severe weather mode, VCP 212 is the quiet mode with more frequent volume updates. If you're doing anything time-sensitive, VCP 212 is noticeably more responsive. The raw files are in formatted weather radar format, which is a binary standard that is not particularly friendly to parse without the right libraries. I use Python with the Py-ART package. It handles the decoding, gives you access to all the standard variables like reflectivity, velocity, and spectrum width, and it runs on anything from a laptop to a server. For casual use, the NWS radar viewer at radar.weather.gov is sufficient. For anything that requires programmatic access or customization, you need to go direct to the data.
Setting Up a Local Radar Processing Pipeline
The first decision is whether you want near-real-time data or historical archives. The AWS bucket keeps current and historical data, but the retention policy changed a few years ago. Older files get deleted after about a year, so if you need go-back capability, you need to start storing locally immediately. I maintain a NAS that holds about eight months of Level II data for the surrounding WSR-88D sites. Storage cost is roughly $40 a month for the capacity I use, which is peanuts compared to the value when you need to reconstruct a specific storm event from last winter. The processing pipeline itself is simple in concept and annoying in practice. Here is what I run: First, I check for new files every five minutes using a cron job. The NEXRAD data comes out in volume scans, and a full volume typically takes between three to ten minutes depending on the VCP. You do not want to process partial volumes. I wait until I have at least three elevation angles before running any analysis. This sounds conservative, but I once tried to estimate precipitation rates with only two elevations and got numbers that were completely wrong because the lower scan was picking up ground clutter and the higher scan was missing the storm core entirely.
Second, I decode the raw binary into georeferenced grids. Py-ART makes this almost painless. You point it at the file path and it returns a Cartopy-compatible grid with latitude, longitude, and altitude coordinates. From there you can do basic things like calculate rain rate using a Z-R relationship or generate cross-sections. The default Z-R relationship for stratiform rain is Z equals 300 times R to the 1.6 power. For convective, it is closer to Z equals 300 times R to the 1.4 power. Neither is perfect for Huntsville specifically, where you often get that mix of frontal and convective structure that makes rainfall estimation unreliable regardless of the formula you choose. I ended up just flagging areas where the reflectivity values were in transition zones and skipping those entirely rather than forcing a calculation. Third, I blend the data from multiple elevation angles into a plan position indicator. This is where most open-source tutorials stop and where everything falls apart if you are not careful. The standard approach is to take the highest quality data from each range gate across all elevations. Range gates farther from the radar have lower resolution because the beam spreads out. At Huntsville's distance from the KBMX radar, you are looking at beam heights of roughly 500 meters at 50 kilometers and 2000 meters at 100 kilometers. If you are tracking storms moving through the area, that beam height increase means your reflectivity measurements are sampling different parts of the storm at different ranges. I stopped trying to correct for this and instead just flagged the outer ranges as low confidence. It is easier than the alternative.
Get the Full Details
Common Problems and Specific Workarounds
The biggest issue I deal with regularly is beam blockage. Huntsville is close enough to the Birmingham radar that terrain interference is a real problem, especially in the southern and eastern quadrants. The NWS publishes beam blockage maps, but they are static and do not account for seasonal changes like heavy leaf cover. I ran into a situation where my precipitation estimates were consistently 15 to 20 percent too low in the southeast direction during late summer. After comparing against observed rainfall gauges from the National Weather Association network, I realized the blockage was seasonal. The workaround was to apply a correction factor based on month and quadrant. It is not elegant, but it works well enough that I have not bothered to build something more sophisticated. Another issue is velocity dealiasing. When you are watching a tornado or a strong mesocyclone, the Doppler velocity can exceed the Nyquist limit and wrap around. The standard dealiasing algorithms in Py-ART usually handle this, but not always. I had one case where a supercell near Decatur produced velocities that the algorithm could not resolve correctly, and the resulting velocity field looked like noise. I ended up just manually editing the affected gates and re-running the analysis. It took about ten minutes and saved me from drawing incorrect conclusions about storm rotation. For people who want a ready-to-use solution without building everything from scratch, there are a few options. The Weather Decision Technologies software is widely used in the broadcast and emergency management space, but it is expensive. The open-source alternatives are functional but require more technical comfort. If you just want to look at radar without any programming, the NWS radar viewer and the RadarScope app are the standard choices. RadarScope gives you more control over the display and can pull data directly from the NEXRAD feeds without any setup. It costs money, but it saves time if your goal is observation rather than analysis.
What This Approach Cannot Do
I want to be clear about the limitations. Level II NEXRAD data from the AWS portal has a latency of roughly five to fifteen minutes behind real time. That is acceptable for post-event analysis and moderate forecasting. It is not useful for warning decisions where every minute matters. If you need faster data, you are looking at either commercial sources or direct NWS feeds that require a formal agreement. The WSR-88D network also has known blind spots. North central Alabama, including parts of the Huntsville metropolitan area, generally has decent coverage from the Birmingham site, but the valley terrain can create shadow zones during low-elevation scans. You will miss light precipitation in those areas entirely. No amount of processing will recover data that was never detected. The spatial resolution is another constraint. Each grid cell in a standard PPI is roughly one kilometer at the radar site and grows larger with distance. By the time you are looking at data from the northern edge of Madison County, each pixel represents an area of several square kilometers. This means your rainfall estimates are averages over a large volume, not point measurements. If you need precision at the neighborhood level, you need to supplement the radar data with rain gauge networks or satellite estimates. The National Meteorological Center provides blended products that combine radar and satellite data, but those come with their own set of uncertainties and are generally less reliable than raw radar for short-term convection. If your interests are primarily educational or you want to build a project without diving into raw data processing, there are curated datasets available from NOAA and university research groups. The University of Alabama in Huntsville maintains some publicly accessible radar products, though the update frequency is not guaranteed. For most practical purposes, combining the AWS NEXRAD data with a simple Python pipeline gives you more flexibility than any pre-packaged solution. The initial learning curve is maybe a week if you already know Python, and significantly longer if you do not. But once it is running, the system is stable and requires minimal maintenance beyond occasional library updates and storage management.