Setting Up UI Automation Without Wasting Three Weeks on Fragile Scripts
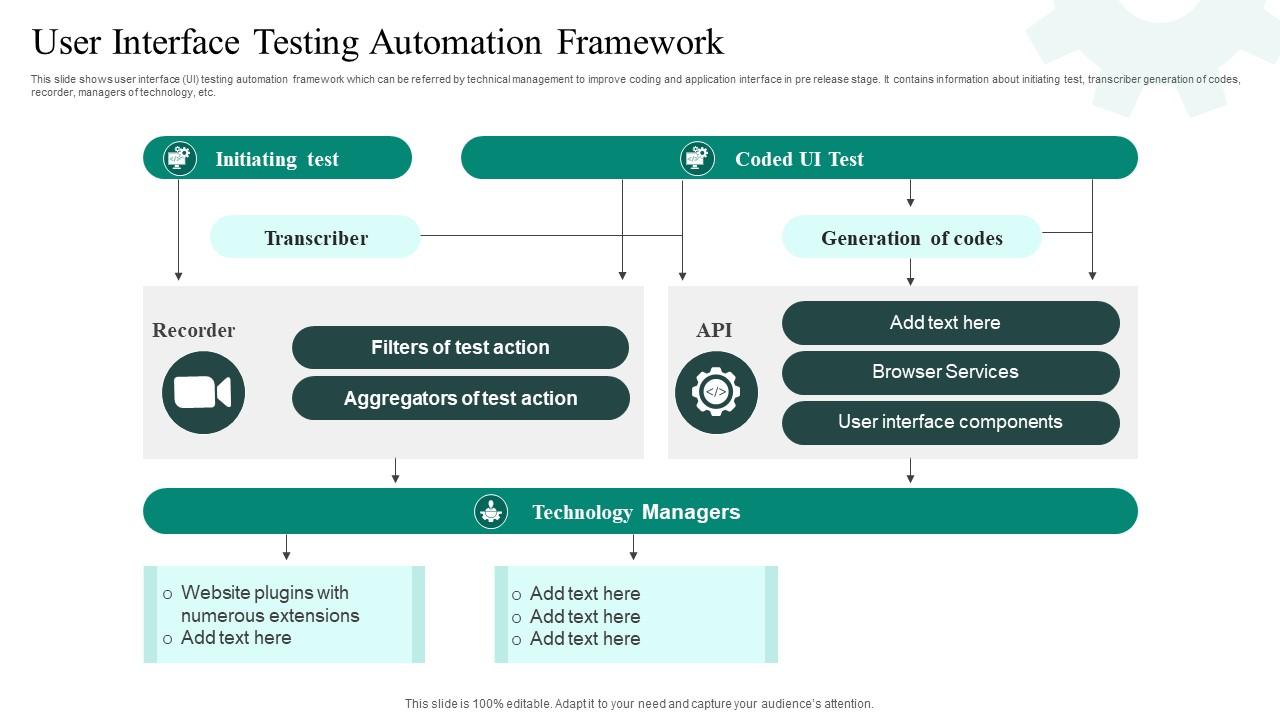
I spent about eight months in 2019 trying to build a reliable end-to-end UI automation suite for a React-based internal dashboard. We lost three testers to burnout before I figured out that the problem wasn't the tooling—it was our approach to element identification and flaky test data. That experience basically shaped everything I've done since with interface automation across three different companies. UI automation is fundamentally about making the browser or native application perform actions and assert outcomes without human hands involved. The tools have gotten better, but the core problem hasn't changed: you're asking a machine to interact with an interface designed for humans, and humans are forgiving while scripts are not. A single CSS class rename can take down an entire regression suite if you've tied your locators to it. The practical starting point is picking a framework that matches your tech stack and team's actual skill level, not the one that sounds impressive at a conference. Playwright handles modern web apps reasonably well because it supports auto-waiting, network interception, and works across Chromium, Firefox, and WebKit from a single API. Cypress is faster to set up for pure JavaScript projects but lacks multi-tab support and runs in the browser, which means it can't test things outside the DOM like file downloads or native OS dialogs. Selenium still has a place for cross-browser legacy testing, though the maintenance overhead is real.
Here's what most teams skip in the documentation. Before writing a single automated test, you need to establish locator strategy rules that your team actually follows. I recommend using test IDs—data-testid attributes in the HTML—as your primary locator. They don't break when designers refactor classes. If your developers won't add them, use accessible roles and labels, which are resilient to layout changes. Avoid XPath unless you genuinely need to traverse the DOM in a way that no other strategy covers. I've seen teams maintain 200-character XPath expressions that broke on every deployment. Structure your tests using the page object pattern or something like Playwright's page object model. Each page or component gets its own class or module that encapsulates interactions. Your test files should only contain assertions and high-level scenarios. When the login form changes, you update one file instead of forty scattered test cases. This matters more as your suite grows past fifty tests. Data management is where automation projects usually go sideways. I once had a test suite that failed intermittently because two parallel test runners were creating and deleting the same user accounts. The fix was implementing test isolation through unique email addresses per runner and cleaning up in afterEach blocks, plus using a dedicated test database that got truncated between runs. Never share production data for automated testing unless you've anonymized it properly. GDPR violations from leaked test data happen more often than you'd think.
Flakiness is the real killer. A test that passes 90% of the time is worse than useless—it erodes trust in the entire suite. Common sources include race conditions from missing waits, async operations that complete after your assertion fires, and environmental differences between CI and local machines. The solution is explicit waits on meaningful conditions rather than artificial sleep timers. Wait for the element to become clickable, wait for network idle, wait for the URL to change. These are deterministic. Waiting two seconds is not. CI integration needs careful tuning. Running UI tests on every commit is expensive. I'd suggest running the full suite on a schedule—nightly or every few hours—and running a smoke subset on pull requests. The smoke subset should cover critical paths: login, core workflow completion, and major error states. Full regression gets a dedicated pipeline with retry logic for known flaky tests. Most teams I've worked with either run UI tests too often and drown in false failures, or they stop trusting the results entirely and disable them. There are limits to what UI automation can solve. Unit and integration tests catch more bugs cheaper and faster. UI tests should cover workflows that matter to users, not implementation details. Don't automate the button click if you can assert the network request instead. The Pareto principle applies heavily here—twenty percent of your tests will cover eighty percent of user-critical paths, and the rest is noise.
Get the Full Details
Cost is another factor I should mention bluntly. A mature UI automation suite typically costs one to three developer-days per month to maintain, depending on complexity and frequency of UI changes. For small teams with limited release cycles, the ROI is questionable. Consider whether you'd be better served investing that time in manual exploratory testing or in building better observability into the application itself. The tools and resources are accessible. Playwright is available at playwright.dev and installs via npm, pip, or your package manager of choice. Cypress docs are at cypress.io with extensive examples. Selenium is at selenium.dev with language bindings for Java, Python, C#, and others. All three have active communities and reasonable documentation, though none of them will save you from poor test design. I've found that the teams who succeed with UI automation are the ones who treat it as infrastructure, not as a silver bullet. They write fewer tests, they invest in stable locators, they monitor flakiness rates religiously, and they're willing to kill tests that no longer provide value. The rest end up with a graveyard of green tests that don't actually catch anything.