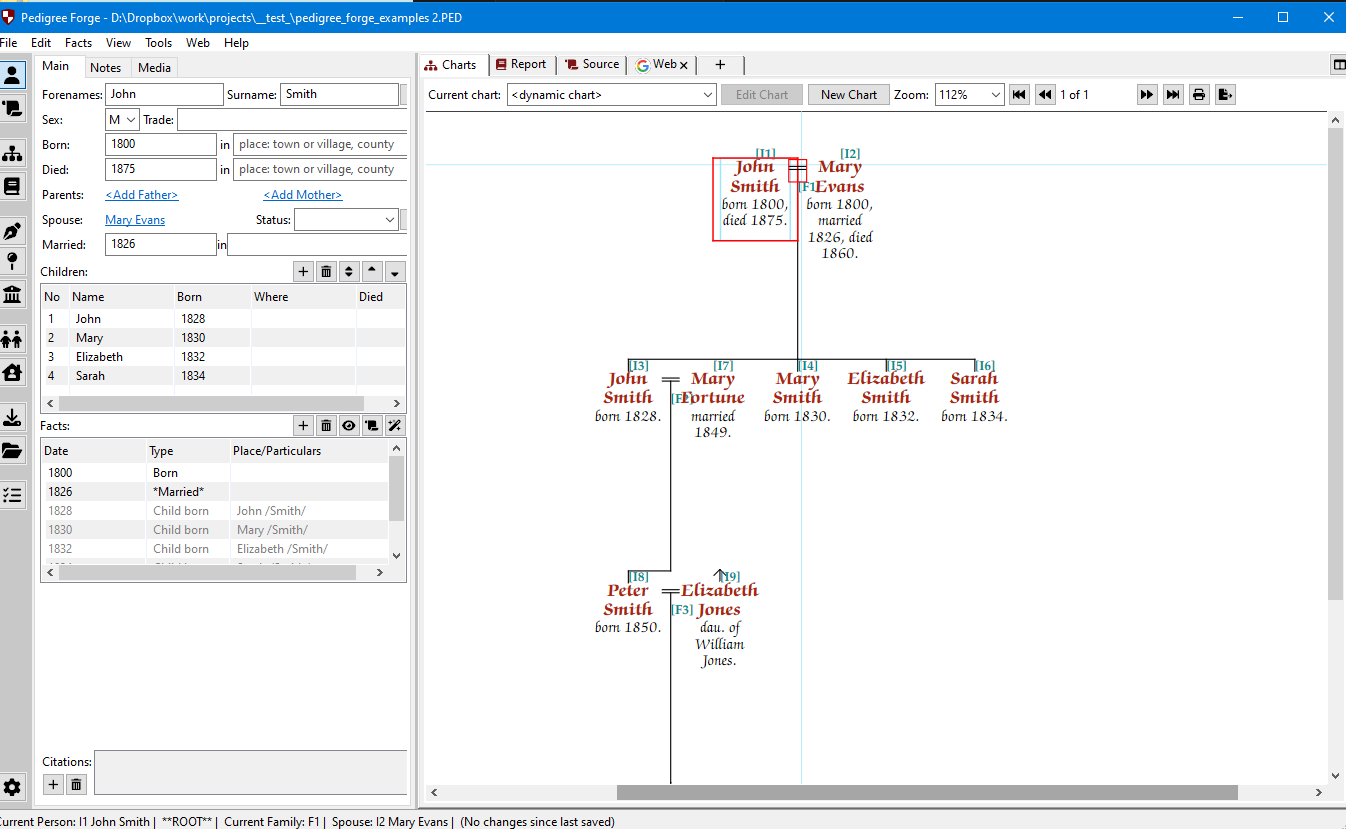
What A Pedigree Query Actually Does For Your Research
A pedigree query is a structured search that traces your ancestry line by line, pulling together records from multiple sources to build out your direct lineage. It isn't magic. It's a systematic way of querying databases, family trees, and historical records to find connections you might otherwise miss in a manual search. I started using pedigree queries seriously around 2014 when I hit a wall with my great-great-grandfather's lineage. The traditional approach of searching census records one at a time was eating days of my week with minimal results. A colleague at a genealogy conference recommended I switch to a structured pedigree query approach, and it changed how I work entirely. Within three weeks, I had connected three branches that had been dead ends for years. The basic mechanic is straightforward: you input what you know, the system matches it against databases and returns potential matches ranked by confidence. But the nuance is in the configuration. Most people run these queries too broadly and get overwhelmed with false positives, or too narrowly and miss the actual matches hiding in slightly misspelled records. The trick is finding the middle ground.
Unleashing The Power Of Pedigree Query The Ultimate Tool For Genealogists
To actually get value from a pedigree query, you need to understand how different tools handle matching logic. Some platforms use strict exact-match algorithms, while others employ fuzzy matching that accounts for common transcription errors in historical documents. I've found that combining both approaches in a single session usually pays off. Start with a loose query to cast a wide net, then refine using the results as new anchor points. Here's a practical workflow I use consistently. First, I enter all known data for a specific ancestor including alternate spellings of surnames and known variant first names. Then I run the query against the largest available database, sorting by likelihood score. I review the top twenty results manually before expanding to secondary databases. This usually takes about twenty to thirty minutes per ancestor, compared to the four or five hours I used to spend doing manual searches. The most useful feature in any pedigree query tool is the ability to set custom filters. Most people leave these on default, which means they're filtering for standard birth, marriage, and death records. But the interesting data is often in tax lists, land grants, military pension files, and church registries that default filters exclude. I set mine to include probate records and court documents as a standard practice. This single adjustment has surfaced connections that strict vital record searches never would have found.
I ran into a specific problem last year that highlights why query strategy matters. I was searching for a great-grandmother who appeared in records under two different first names. Her birth certificate listed her as Margaret but all subsequent records used Peggy. A standard pedigree query treated these as separate individuals and split her records across two profiles. I had to manually create a linked-identity flag in my research notes and run the query twice, once for each name variant, then merge the results. It added maybe fifteen minutes to that particular search but prevented a genuine research gap from forming. Tools that support name variant linking natively save you from having to do this manually, which is worth prioritizing when choosing a platform.
Get the Full Details
Common Mistakes That Waste Your Time
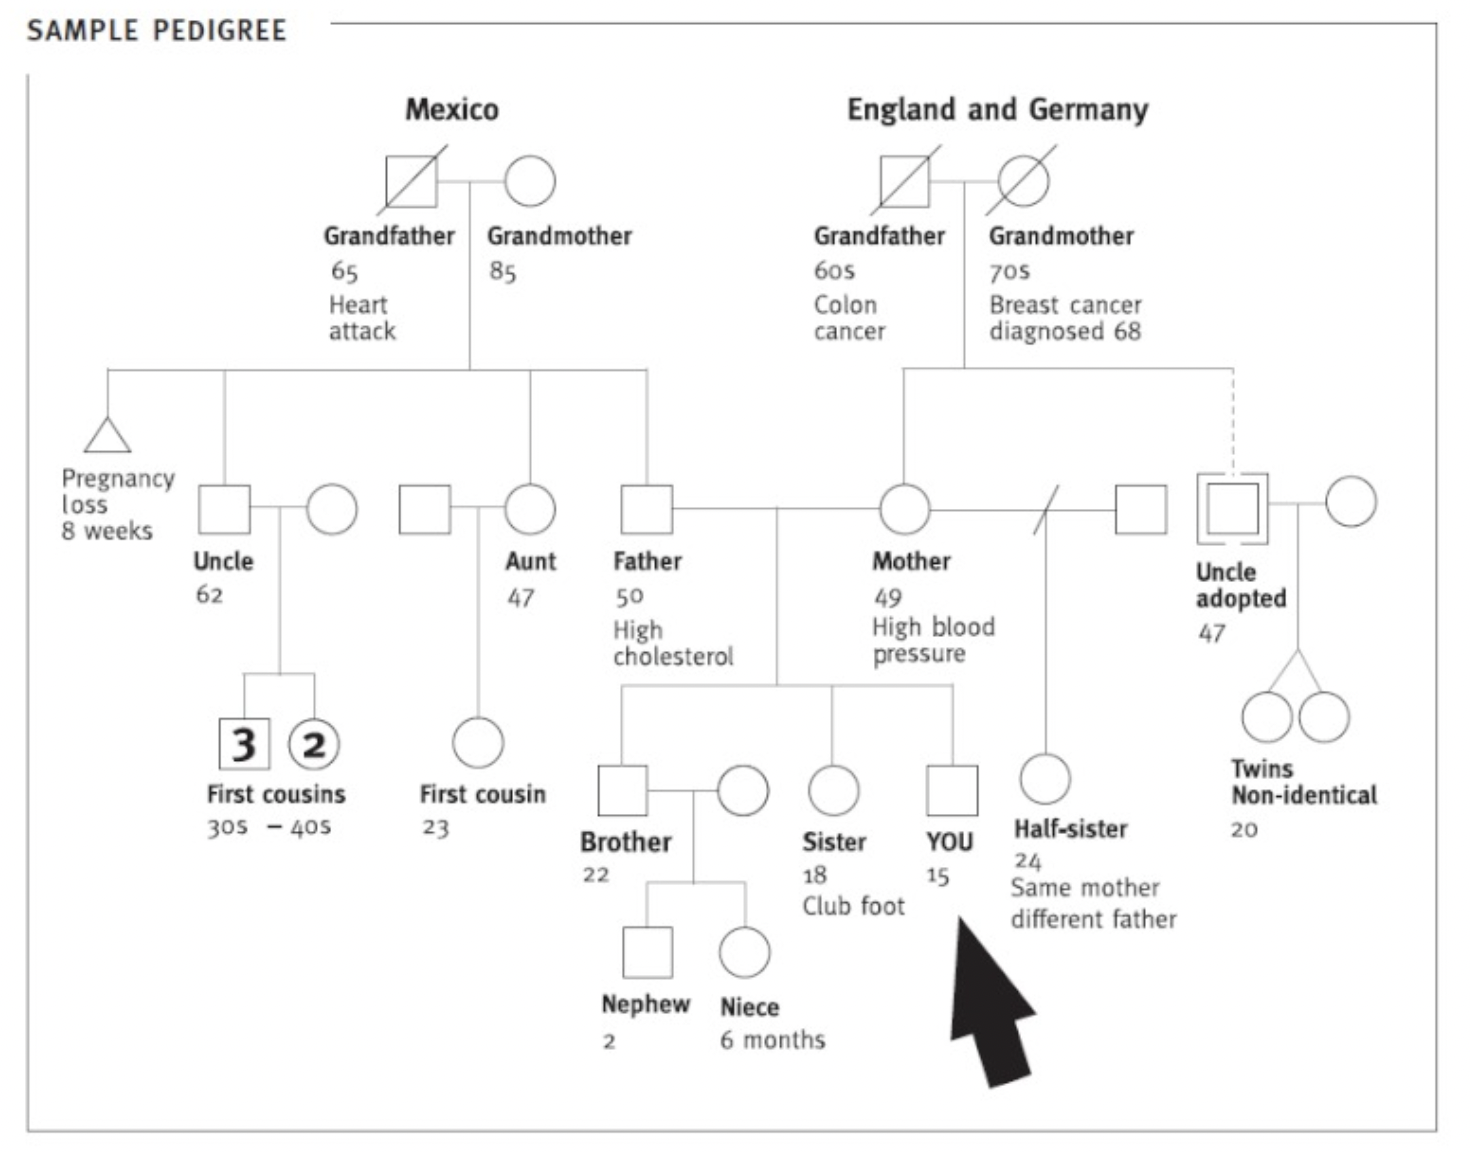
The biggest error I see beginners make is trusting the confidence score too much. These scores are mathematical approximations, not truth guarantees. A score of eighty percent might look solid until you realize the matching algorithm weighted surname frequency heavily, and that surname belongs to three thousand other families in the same region. Always verify matches against original source documents before committing them to your tree. Another mistake is running queries without cleaning your existing data first. If your current tree has inconsistent date formats, misspelled locations, or duplicate entries, the pedigree query will amplify those problems. I spend at least ten minutes auditing any ancestor profile before running a fresh query against it. It sounds like extra work but it prevents the garbage-in-garbage-out scenario that derails most research sessions. There's also a tendency to over-query. Running the same pedigree query repeatedly with minor variations doesn't compound results meaningfully after the third or fourth iteration. You're mostly re-finding the same matches in different orderings. Set a limit on iterations and move on to a different research strategy when you hit diminishing returns. The diminishing returns usually kick in within twelve to fifteen minutes of continuous querying on a single ancestor.
What These Tools Can't Do
Pedigree queries have real limitations that no amount of marketing will hide. They cannot interpret the meaning of a record. They can match a name and date to a document, but they can't tell you whether that document actually confirms a familial relationship or merely shows two people with the same name living in the same county at the same time. That interpretation step always requires human analysis. They also struggle with populations that are poorly digitized. If your ancestors lived in rural areas of Eastern Europe, parts of Africa, or indigenous communities in the Americas, the database coverage may simply not exist yet. I've seen tools claim millions of records but the actual subset relevant to your query might number in the hundreds. Being honest about what the available data can and cannot support is essential to avoiding frustration. Copyright and privacy restrictions also limit what pedigree queries can access. Some databases restrict record visibility based on the age of the event or the jurisdiction's privacy laws. A query might return a clean result for a 1920 census but show nothing for a 1940 record that isn't yet public. This isn't a flaw in the tool, it's a legal boundary you'll encounter consistently and need to plan around.
Picking A Platform That Fits Your Workflow
Not all pedigree query tools are equivalent. Some integrate directly with major genealogical databases and export results in GEDCOM format, which matters if you switch between platforms. Others offer superior mapping features that visualize migration patterns alongside your query results. A few specialize in DNA match integration, letting you cross-reference pedigree queries with genetic genealogy data in the same interface. I recommend testing any platform with a known ancestor first before committing. Pick someone you already have solid documentation for and run the query. Note how many verifiable matches appear, how the interface handles refinement, and whether the export options match your needs. This takes about twenty minutes and saves you from discovering incompatibility issues after you've invested weeks into a system. The platforms I've found most reliable support custom query building, allow side-by-side comparison of multiple results sets, and maintain regularly updated source citations. Features like automatic duplicate detection and merged record suggestions are nice but secondary. Core functionality that handles messy, incomplete data gracefully matters more than polished extras.
Integrating Queries Into A Broader Research Plan
A pedigree query works best when it's one component of a structured research plan, not a standalone solution. I schedule query sessions around specific research questions rather than running them opportunistically. For example, I might dedicate a two-hour block to resolving the paternal line of my third-great-grandfather using a pedigree query for the first hour and then spending the second hour examining original documents for any promising matches. This bounded approach prevents the session from expanding into an all-day rabbit hole that produces diminishing returns. Setting a time limit forces you to prioritize the highest-value actions and move on when the query path runs dry. Most productive query sessions last between forty-five minutes and an hour before fatigue starts causing careless mistakes in result evaluation. Documenting your query parameters is another habit worth adopting. Recording the exact search terms, date ranges, and filter settings you used allows you to reproduce successful queries and avoid repeating failed ones. I keep a simple spreadsheet tracking each ancestor, the query strategy applied, the number of results returned, and whether the outcomes proved useful. Six months later, that spreadsheet becomes a reference that saves hours of redundant experimentation.
The real power of pedigree queries emerges when you combine structured querying with careful source evaluation and a willingness to adapt your strategy when the data doesn't cooperate. No tool replaces the analytical work of connecting evidence, but a well-configured pedigree query can surface the raw material you need to do that work efficiently. Start with a clear question, run a focused query, verify the hits, and repeat until the lineage connects. The process is iterative and sometimes slow, but it consistently produces results that unstructured searching never does.