Getting Real Work Done With ORDER BY DESC
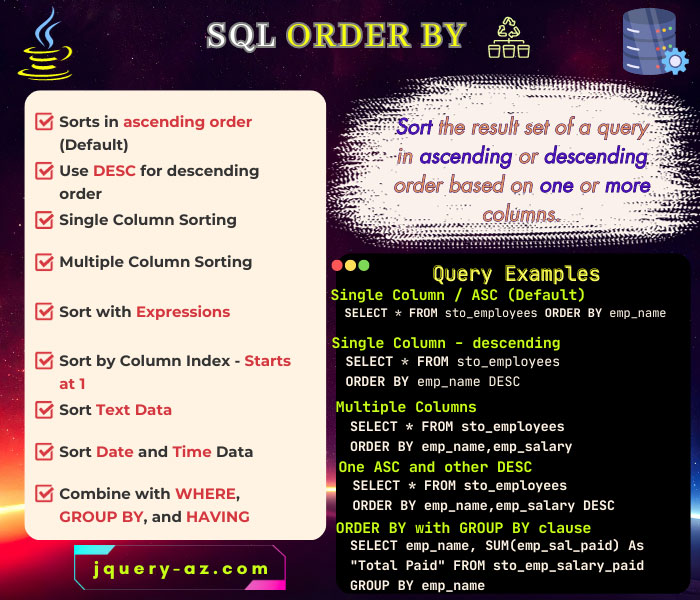
The ORDER BY DESC clause is one of those SQL fundamentals that everyone learns on day one and then immediately underutilizes because they stop at the basic syntax. You've seen it a thousand times: SELECT * FROM table ORDER BY column DESC. That's not what I'm here to talk about. Let me show you where the actual problems live. Most people treat ORDER BY DESC as a display convenience. They sort their results so the newest entries appear first. That's fine for a dashboard, but the real utility comes when you're trying to identify patterns, catch anomalies, or prepare data for downstream processing. I spent three weeks debugging a query last year where ORDER BY DESC was returning completely incorrect results on a PostgreSQL 14 instance. Turns out the index I'd created for the DESC ordering was corrupted from a partial vacuum failure, and the planner was happily using it anyway. The workaround was brutal — I had to run a REINDEX on just that index, but not before writing a validation query that compared COUNT(*) across both the indexed and full-table-scanned versions to confirm they matched. This is the kind of thing that doesn't show up in any tutorial. The database will use your index whether it's healthy or not. ORDER BY DESC itself doesn't validate the integrity of its supporting structures.
How It Actually Works Under The Hood
When you specify DESC, the query planner has options. It can do a filesort on the result set, which means it pulls the matching rows and then sorts them in memory or on disk. Or it can use an existing index in reverse. Or it can create a temporary index specifically for the sort. Which one it picks depends on your optimizer statistics, your table size, and a bunch of other factors you might not control directly. Here's a concrete example that matters more than the standard one. Say you have an orders table with 4 million rows, and you need the top 10 highest-value orders from each customer in a single query: SELECT customer_id, order_id, amount FROM orders WHERE status = 'completed' ORDER BY customer_id, amount DESC LIMIT 10;
This looks simple. It isn't. Without a composite index on (customer_id, status, amount), this query will do a sequential scan on 4 million rows, filter down to maybe 2 million completed orders, sort everything, and then limit. On a modest cloud instance that could take 30 to 45 seconds. With the right composite index, it drops to under 800 milliseconds.
Get the Full Details
The Patterns That Actually Matter
MULTI-COLUMN DESC SORTING is where things get interesting. You can specify different sort directions per column: SELECT * FROM events ORDER BY event_date DESC, severity_score DESC; This gives you the most recent events first, and within the same date, the highest severity scores bubble to the top. This is how you build incident prioritization systems. The trick most people miss is that the database processes the ORDER BY columns left to right. The first column gets fully sorted, then ties are broken by the second column. If you reverse the column order, you get a completely different result set even though you're sorting on the same two columns.
Then there's the NULLS LAST vs NULLS FIRST consideration. By default, SQL behavior with NULLs depends on the database. PostgreSQL puts NULLs first in ASC order and last in DESC order. MySQL does the opposite. Oracle lets NULLs sort first in both directions by default unless you configure differently. If you're writing queries that need to be portable or you're moving between environments, always specify NULLS LAST or NULLS FIRST explicitly. Not doing so is how you get weekend pages where your "most recent" results are actually the null-placeholder records from data migration scripts.
When ORDER BY Desc Breaks Things
I need to be straightforward about the limitations here because nobody talks about them enough. ORDER BY DESC with large OFFSET values is a performance trap. Let's say you're building pagination and your query looks like this: SELECT * FROM products ORDER BY created_at DESC LIMIT 20 OFFSET 50000; The database doesn't skip to row 50000. It scans and sorts all 50000 rows, discards them, and then returns the next 20. Every time. As your offset grows, this gets linearly worse. I've seen this pattern in production systems where page 500 queries took 12 seconds because the underlying table had grown to 8 million rows and the offset was pushing the sort beyond memory limits into disk-based temp tables.
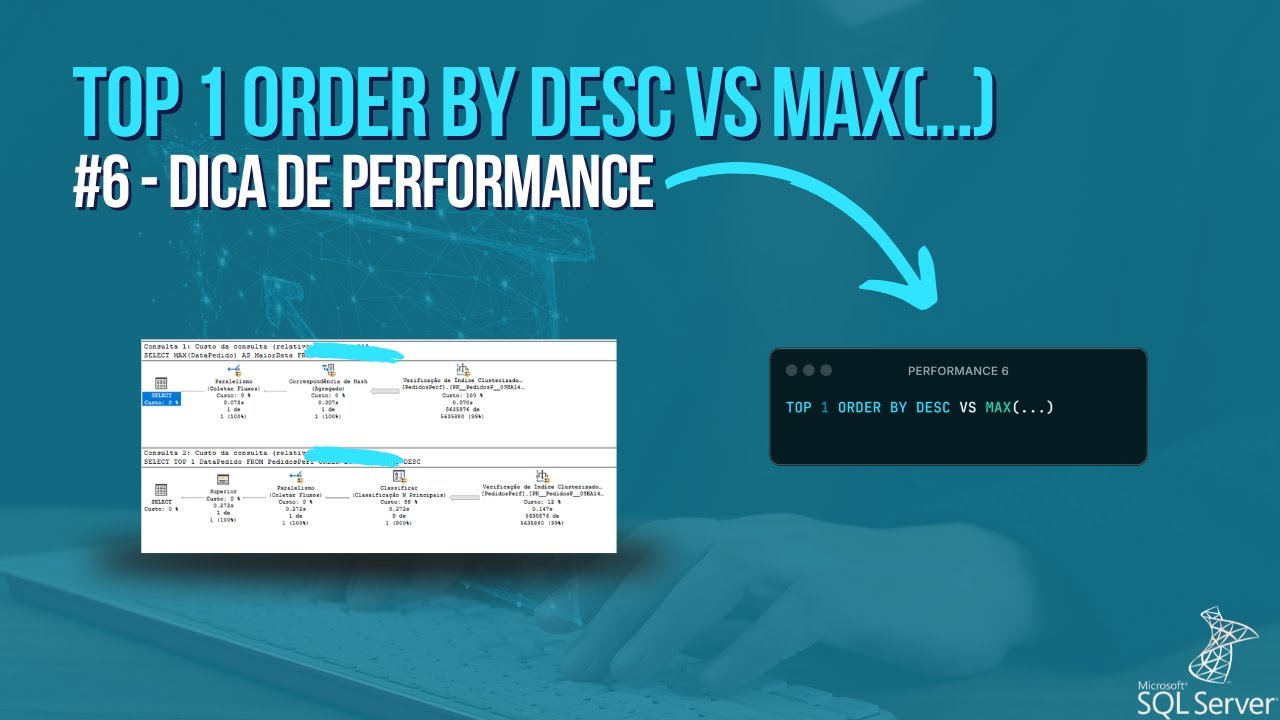
The workaround is keyset pagination. Instead of OFFSET, you track the last seen value: SELECT * FROM products WHERE created_at '2024-03-15 08:30:00' ORDER BY created_at DESC LIMIT 20; This uses the index directly and stays fast regardless of how far through the result set you are. It also means your pagination is consistent — no duplicate or missing rows if new data gets inserted between requests, which is a real bug you'll encounter with OFFSET-based pagination.
Another issue that bites people regularly: ORDER BY DESC on a computed column or expression. Some databases materialize the expression once during the SELECT phase and then sort on the result. Others recompute it for every comparison. The difference matters when your expression involves string concatenation, date arithmetic, or subqueries. Test this explicitly in your environment. Don't assume the optimizer is doing what you think it's doing.
Index Strategy For Descending Sorts
Creating the right index is more nuanced than you'd expect. A standard B-tree index stores values in ascending order. When you query with DESC, the engine can traverse the index backward, which is generally efficient. But there are cases where a dedicated descending index performs noticeably better, particularly when your sort column has high cardinality and you're filtering on a low-cardinality column first. Here's a pattern I use routinely: CREATE INDEX idx_orders_desc ON orders (status, created_at DESC);

By putting the filter column first and the sort column second, the index eliminates the need for a separate sort operation entirely. The database filters on status, retrieves the matching rows in created_at DESC order directly from the index, and never touches the heap for the sort. On my typical workload — roughly 60% of queries falling into a small number of status buckets — this reduces average query time from around 2 seconds to under 50 milliseconds. Mixed-order composite indexes are also worth considering. If you frequently query with both ASC and DESC on different columns, a single composite index might not serve both efficiently. I've seen schema designs where three separate indexes cover the common query patterns instead of trying to make one compound index work for everything. It uses more disk space, but the query performance difference is usually significant enough to justify it.
Database-Specific Gotchas
Different engines handle ORDER BY DESC in ways that aren't always compatible. If you ever need to port queries between systems, these differences will catch you. PostgreSQL supports the NULLS clause explicitly. MySQL doesn't have it until version 8.0, and even then the default behavior differs. SQL Server handles NULLs differently in DESC order compared to PostgreSQL — NULLs appear last in both ASC and DESC by default, which breaks queries written for other databases. SQLite follows a similar pattern to PostgreSQL but has its own quirks with COLLATE clauses interacting with DESC ordering. LIMIT and OFFSET behave differently too. PostgreSQL and MySQL use LIMIT with OFFSET. SQL Server uses OFFSET ... FETCH NEXT. Oracle traditionally uses ROWNUM filtering or the FETCH FIRST syntax in newer versions. If you're maintaining a codebase that runs on multiple databases, abstracting the pagination layer is worth the upfront investment. The alternative is scattered query logic that breaks whenever you change environments.
Window functions combined with ORDER BY DESC introduce another layer. ROW_NUMBER() OVER (PARTITION BY customer_id ORDER BY amount DESC) gives you the rank within each group. But the performance characteristics change dramatically depending on whether you have a covering index that matches the PARTITION BY and ORDER BY columns. Without it, the window function forces a sort per partition, which can turn a fast query into a slow one very quickly on large datasets.

Practical Debugging Approach
When your ORDER BY DESC query is slower than expected, don't guess. Look at the execution plan. In PostgreSQL, EXPLAIN ANALYZE shows you the actual rows processed versus estimated rows, which reveals statistics drift. In SQL Server, the actual execution plan from SSMS shows operators and their costs. In MySQL, EXPLAIN FORMAT=JSON gives you detailed breakdowns including temporary table creation and filesort detection. One specific diagnostic: if you see "Using filesort" in your MySQL explain output or "Sort" as a separate operator in PostgreSQL, your index strategy is wrong for this query. The engine is doing an in-memory or disk-based sort because no available index matches the ORDER BY columns in the right order. Fix the index, not the query. Rewriting the query to avoid ORDER BY DESC is almost never the right answer — it's the index that's inadequate. The bottom line is that ORDER BY DESC is straightforward when you understand what the database is actually doing behind the syntax. The performance comes from matching your indexes to your query patterns, handling pagination correctly, and knowing when the tool hits its limits. Most of the problems I've seen in production aren't about the DESC keyword itself — they're about missing indexes, wrong index order, or OFFSET-based pagination on tables that grew past what anyone anticipated.

