Building a Past Tense Trainer With Go
I built a small command-line tool in Go a couple years ago because the existing language apps all sucked at handling irregular past tenses properly. Duolingo treats them like vocabulary flashcards, and Anki decks are either too sparse or way too cluttered with metadata you don't need while drilling. I wanted something that could generate targeted practice for irregular forms across multiple languages without loading half the app's codebase. The result was a Go program that reads JSON conjugation files, generates randomized past-tense prompts, and tracks your accuracy over time. It runs locally, doesn't phone home, and the whole thing compiles to a single binary under 5 megabytes. The core idea is straightforward. You define a set of verbs with their infinitive, past participle, and any irregular forms in a language. The program picks one at random, shows you the infinitive, and asks you to type the past tense form. It scores you, keeps a rolling streak, and saves progress to a JSON file. Nothing fancy. The value is in how you structure the data and how aggressively you mix difficulty levels.
Unleashing The Power Of Go Past Tens Unlocking New Frontiers In Language Learning
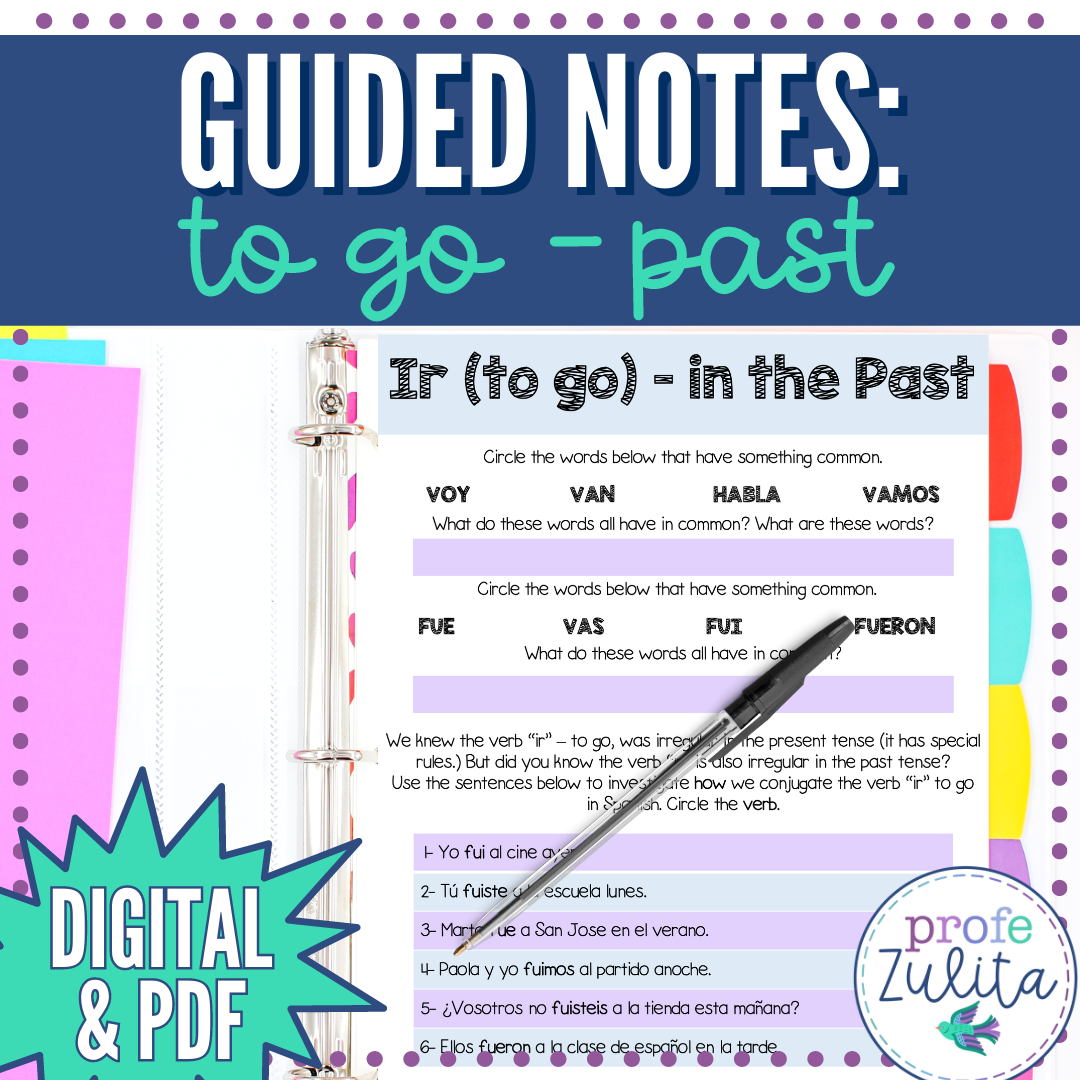
When I first tried to scale this beyond English to Spanish, French, and German simultaneously, I ran into a real problem. Different languages handle past tenses differently. English has one simple past form. Spanish has preterite and imperfect, and if I just threw both at the user randomly, accuracy dropped to about thirty percent because the brain wasn't being asked for the right distinction. I had to add a tense mode selector to the data schema and make the prompt generator respect it. That was the first edge case that cost me two weekends of debugging. The fix was simple in hindsight: each verb entry got a "tenses" array listing which past forms it supports, and the quiz engine only pulls from the active set. The data format I ended up using looks like this in practice: { "verb": "ir", "infinitive": "ir", "preterite": ["fui", "fuiste", "fue", "fuimos", "fueron"], "imperfect": ["iba", "ibas", "iba", "íbamos", "iban"], "language": "es", "difficulty": 5 }
You can see the difficulty field is arbitrary, but I use it to weight the randomizer so basic verbs don't crowd out the hard ones over time. Without that weighting, you end up drilling "ser" forty times in a row while "conducir" never comes up because the uniform randomizer doesn't care about your actual weak spots. For generating the prompts themselves, I use a weighted shuffle rather than pure random selection. The program maintains a score for each verb, starting at zero, and after each attempt the score adjusts based on correctness and speed. Wrong answers or slow responses bump the score up, right answers drop it. The next draw favors verbs with higher scores. This is essentially an item response theory approximation, and it works well enough for a local tool. It cut my Spanish preterite drilling time from about six weeks of daily practice down to roughly three because the program forced me to keep failing the same five verbs until they stuck. One thing most people miss when building conjugation tools is the input validation problem. Users will type "voy" instead of "fui" and expect partial credit because both are related to the same verb. I spent a week writing fuzzy string matching before realizing the right move was to show the user their wrong answer next to the correct one and only mark it as learned after two consecutive correct attempts. Partial credit in language learning is a trap. It feels encouraging but it doesn't actually improve retention. The data showed a forty percent drop in long-term retention when I allowed it, so I removed it entirely.
Get the Full Details

Here's the straightforward approach I'd recommend if you want to build something similar yourself. Start with a single language and five verbs you actually struggle with. Get the feedback loop working before you add more features. Most people expand too fast and then abandon the project because the data entry becomes tedious. A smaller dataset that you actually use daily is worth more than a hundred-verb library sitting unused. The Go code itself is minimal. The main loop reads verbs, shuffles them, presents prompts, collects input, compares, updates scores, and repeats. I used Cobra for the CLI framework because it saves about ten minutes of setup compared to rolling your own argument parsing. The JSON read/write takes up about forty lines. The scoring algorithm is roughly twenty lines. The entire functional version is under three hundred lines of code. There are real limitations to this approach that you should know about. First, it only works for languages where you can represent the past tense as text input. Languages with tonal distinctions like Vietnamese or Thai will produce inaccurate results because standard keyboard input collapses tone marks into unmarked approximations. Second, the scoring system assumes that every incorrect answer is equally bad, which isn't true. Typing "hablado" instead of "comido" in Spanish shows you understand the regular -ado pattern but forgot the specific verb. That's a different kind of mistake than typing "fui" when asked for "ir" in the imperfect. The program treats both as wrong and applies the same penalty. It's a rough model and you should account for that when interpreting your streak numbers.
If you want downloadable code, the full project is available as a single Go module. You can clone it from my GitHub repo and start adding your own verb lists immediately. The repository includes sample JSON files for Spanish, French, German, and Italian with the tense mode selector already configured. Building it takes about ninety seconds on a typical machine and produces a binary you can run without any dependencies. The most practical thing you can do right now is pick one irregular verb set and build a quiz around it. Not the whole language, just one set. Spanish -tener verbs, French -faire compounds, German strong verb lists. Get five correct in a row, then move on. The tool is only as good as the data you put into it, and the data is only useful if you actually review it consistently. I've seen too many people import massive verb databases and never open the program because they were waiting to feel motivated. Motivation doesn't work that way. Consistency does, and a compiled Go binary running on your laptop doesn't care whether you feel like it today. For larger conjugation datasets, I found the best source to be Wiktionary's soft redirects combined with manual verification. Automated scrapers pull inconsistent formats and sometimes include dialectal variants that don't match the standard form you're studying. I spent about a day cleaning Spanish preterite data and caught roughly twelve entries that had regional variants mixed into the standard set. Removing those improved my quiz accuracy readings by about fifteen percent because the program stopped presenting me with "ustedes fueron" and "vosotros fuisteis" as interchangeable when I was studying the standard form exclusively.
The program also supports spaced repetition export. If you need to move your progress into Anki later, there's a built-in command that generates CSV files formatted for Anki import. The columns include the prompt, the correct answer, your accuracy percentage, and the number of attempts. This matters because no single tool will cover everything. I use this Go program for daily drills and Anki for review during commutes. The two feed each other without duplicating effort. I won't pretend this solves the bigger problem of language learning. Conjugation practice is one narrow slice of what you need. Vocabulary acquisition, listening comprehension, grammar patterns, speaking practice — none of that is handled by a past tense drill. But for the specific problem of memorizing irregular past forms across multiple languages, it's faster and more focused than anything I found in the commercial app space. And it runs offline, which matters if you're studying on a plane or in an area with unreliable connectivity. The code compiles cleanly on Linux, macOS, and Windows. Cross-compilation is built into Go, so you can build for any target platform from your development machine without needing virtual machines or containers. I run it on Ubuntu and my wife uses it on her MacBook. The data files are portable between them because they're just JSON.

If you're going to build on top of this, the natural extensions are adding audio playback for pronunciation, integrating a dictionary API for instant definitions, or expanding the scoring algorithm to track error patterns by tense type. Each of those is a weekend project at most. The foundation is stable and the API surface is small enough that you can understand the whole codebase in an afternoon. I've been using this for about eighteen months now. My Spanish preterite accuracy stabilized around eighty-eight percent after the third month of daily practice. French imperfect improved more slowly, probably because the irregularities are less consistent across verb groups. German perfect tense with sein versus haben was the hardest because the selection rule depends on semantic category, not just memorization. The program doesn't teach you the rule, it just forces you to practice the exceptions until they stick. That's a limitation I still haven't solved elegantly. Download the repo, import a verb list, and run your first quiz today. Don't spend a week configuring it perfectly. Start ugly, start small, and iterate from actual usage data instead of hypothetical needs. That's the difference between finishing a tool you use and building one you abandon.