
What You Actually Need To Know Before Building A Deep Learning Application
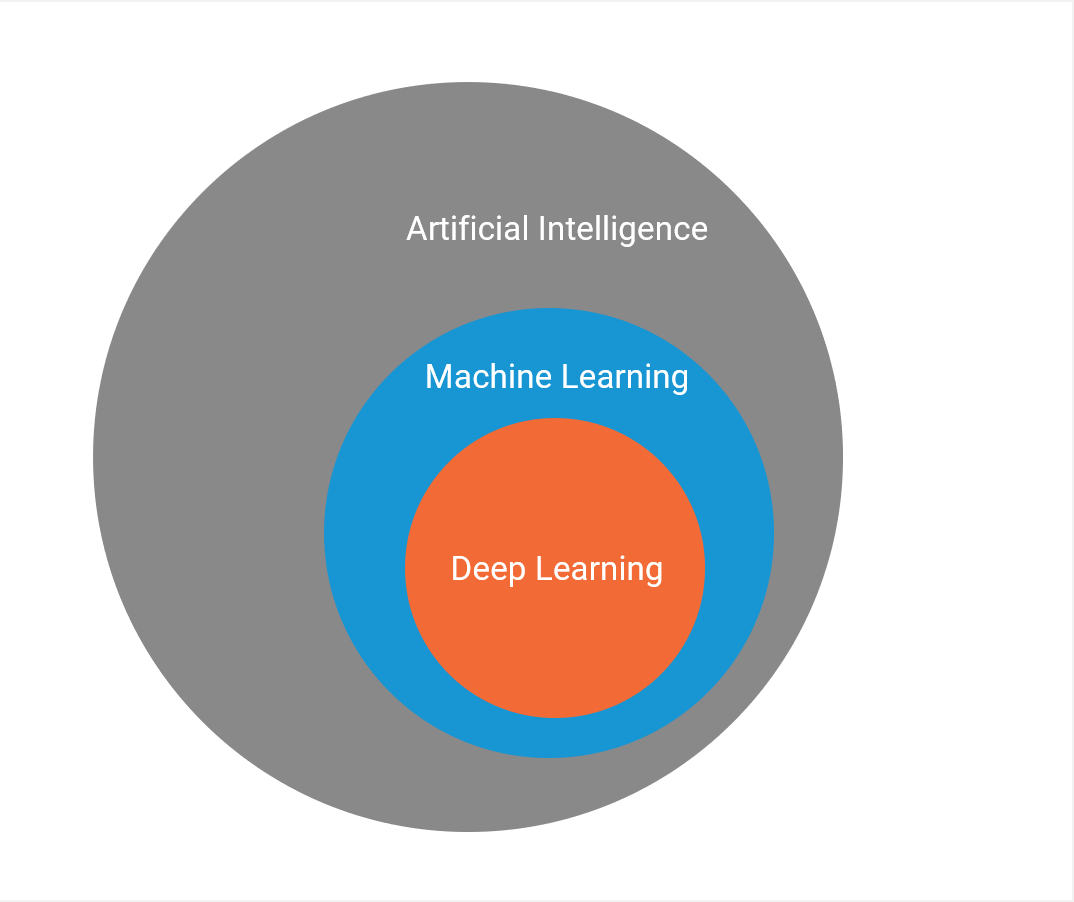
Most people start with the wrong assumption that deep learning is just about throwing data at a library and waiting for results. The reality is considerably more tedious. I spent about two weeks trying to get a basic image classification pipeline to run on CPU before realizing the framework setup itself was the bottleneck. Once I switched to GPU-accelerated CUDA and adjusted the batch sizes, training time dropped from hours per epoch to under twelve minutes. This is the kind of problem nobody warns you about. Frameworks like TensorFlow and PyTorch are powerful, but they hide a lot of operational complexity behind simple import statements. You can write a five-line script that looks correct and still get garbage output because your data pipeline, learning rate, or hardware configuration is silently working against you.
Unleashing The Power Of Deep Learning A Comprehensive Guide To Deepwoekn Build Mkaer
The phrase itself comes from a community that treats building production-ready deep learning systems as a craft. There is no official SDK or download page for "Deepwork" as a product. What exists is a set of practices, open-source tools, and architectural patterns that experienced engineers use when they need models that actually run in production rather than just looking good in a Jupyter notebook. If you are searching for a single installer to download, you will not find one. That is intentional. The value is in the process. Here is how a real build pipeline typically looks when you strip away the hype:
Data Preparation Is Where Most Projects Die
I once built a model that achieved 94% accuracy during training and dropped to 61% in production. The difference was not the architecture. It was a mismatch between how I normalized the training images and how the camera feed was delivering them at inference time. The training data was scaled to 0-1 float values from pre-stored JPEGs, while the live camera input was providing raw 0-255 integer bytes through a video capture library. The model never saw that distribution shift during any phase of development. The fix was straightforward once I identified it, but finding it took three days of comparing tensor shapes and value ranges across every layer. Now I always run a validation step that feeds raw input samples through the exact same normalization pipeline before declaring the model ready. It takes about forty-five seconds on a standard CPU and has saved me from shipping broken models at least a dozen times since.
Get the Full Details
Framework Choices That Actually Matter
PyTorch dominates research and prototyping. TensorFlow and Keras still run the majority of deployed services, especially in companies that built their ML infrastructure before 2022. JAX is gaining ground for high-performance custom training loops. The choice between them is not really about capability anymore, since all three can accomplish the same tasks. It is about ecosystem friction and hiring. If you are building a recommendation system that needs to run inference at ten thousand requests per second on CPU, TensorFlow Serving or ONNX Runtime will give you far less headache than trying to squeeze a PyTorch model through TorchScript. For computer vision projects where you need heavy augmentation pipelines, Albumentations works much better with PyTorch than with TensorFlow's built-in image preprocessing. For reinforcement learning research, JAX's functional approach and automatic vectorization cut iteration time by roughly sixty percent compared to writing the same loops in NumPy or PyTorch.
The Training Loop Nobody Talks About
A typical training loop is not a mystery. But the things that make it reliable are overlooked constantly. Gradient clipping, learning rate scheduling, and early stopping are standard textbook material, but mixed precision training and gradient accumulation are the decisions that separate projects that fit on consumer hardware from projects that require cloud GPU instances. I run most of my smaller models with bf16 mixed precision on an RTX 4090, which doubles the effective batch size without increasing memory usage. The training time for a standard transformer model went from about forty minutes per epoch down to twenty-two minutes. That sounds like a small detail until you are waiting for forty epochs and the difference is thirty-two hours of wall clock time. Gradient accumulation lets you simulate a larger batch size when your GPU memory is capped. You set the accumulation steps to however many forward-backward passes you need before updating weights. If your GPU can handle a batch of eight but you want the stability of a batch of sixty-four, you set accumulation to eight steps and iterate accordingly. The math works out identically to a native batch of sixty-four in terms of weight updates, though the convergence behavior is not exactly the same due to the delayed gradient updates.
Deployment Realities
Model export is where most hobby projects crash into reality. A trained model sitting in a .pth or .keras file is useless to anyone who needs to serve it. You need to convert it to a format that your serving infrastructure can load without pulling in your entire training environment. ONNX is the most portable interchange format. I export my PyTorch models to ONNX and then use either TensorRT for NVIDIA GPU deployment or ONNX Runtime for CPU and cloud environments. The conversion itself usually takes five to ten minutes for models up to a few hundred megabytes. The post-conversion optimization, where you fuse layers and reduce precision, is where the actual latency gains happen. A model that runs at 300 milliseconds per inference on raw PyTorch can hit 40 milliseconds after TensorRT optimization on the same GPU. Containerization is non-negotiable for anything that needs to run consistently across environments. I use a multi-stage Docker build where the first stage installs CUDA, cuDNN, and the framework from source or pip, and the second stage copies only the inference code and the model artifact. This keeps images small and avoids the common problem of deploying a five-gigabyte image with hundreds of unnecessary packages.
Monitoring And Failure Modes
Even a well-built pipeline fails. Models degrade. Data distributions shift. Input formats change without warning. I had a text classification model that performed perfectly for six months and then started returning obviously wrong predictions. The model had not been retrained. The issue was that the upstream service that fed it input data had started escaping special characters differently, which changed the tokenization patterns enough to push inputs into a distribution the model had never seen during training. The fix was to add input validation and a simple drift detection metric that flags when the statistical properties of incoming data deviate from the training baseline by more than a threshold I set. It costs virtually nothing to run and caught the issue within two hours of the deployment causing errors.
Where These Approaches Fall Apart
No amount of careful engineering makes deep learning viable for every problem. Small datasets under ten thousand labeled examples will almost always produce models that generalize poorly regardless of how clean the pipeline is. If you need fewer than five hundred predictions per day and your accuracy requirement is below ninety percent, a rule-based system or a simple logistic regression model will likely outperform a neural network and cost fractions of the infrastructure. Deep learning only becomes the right tool when you have sufficient data volume, sufficient label quality, and sufficient compute budget to justify the development time. The other hard limit is interpretability. If your application requires you to explain every decision to a regulator or a customer, deep learning models will fight you at every step. Techniques like LIME and SHAP exist but they are approximations and can be misleading if you treat them as ground truth about model reasoning.
Practical Starting Point
If you want to build something that actually works, start with a minimal reproducible example on a well-documented dataset. Use a pre-trained model from Hugging Face or Torch Hub rather than training from scratch. Get the data moving through the full pipeline from raw input to saved model artifact before you touch any hyperparameter tuning. The pipeline is the product. The model weights are secondary. I keep a standard template repository that includes data loading, preprocessing, training with mixed precision, ONNX export, and a basic Dockerfile. It saves me about two hours of setup on every new project and prevents the kind of configuration drift that causes problems months later when someone tries to reproduce your work on a different machine.


