What You Actually Need to Know Before Opening This Guide
Most people treat SoC architecture like it is some kind of black art. It is not. It is a bunch of tradeoffs layered on top of other tradeoffs. You pick your bottlenecks. Usually you end up with three or four of them depending on whether you are optimizing for power, area, or latency, and you have to live with every single one. I spent about six years working on mobile SoCs before moving into automotive applications. The core problems never really changed, just the constraints did. What used to be acceptable in a phone chip is now required in a car chip because the safety case changes the entire schedule. This guide skips the marketing and explains what actually matters when you are trying to build something that works in silicon.
Unleashing The Next Wave Of Innovation A Comprehensive Guide To Soc Architecture
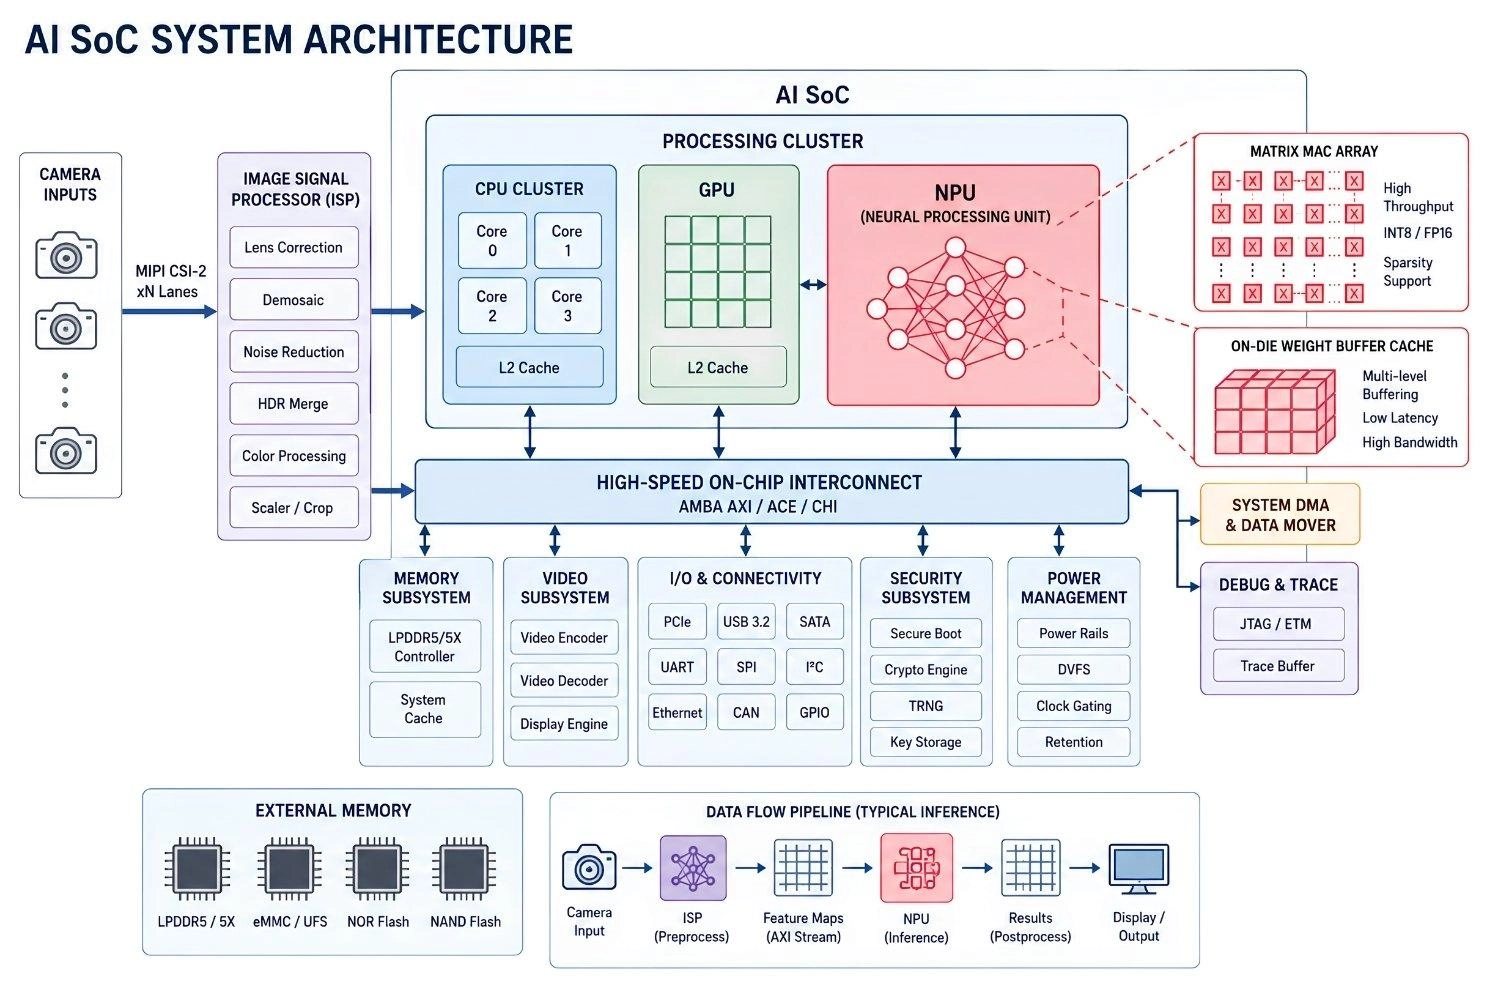
That phrase shows up everywhere now because the industry is genuinely at a transition point. The easy gains from Moore's Law are basically gone. You cannot just shrink transistors and expect performance to scale anymore. The innovation has to come from architecture, from how you arrange the components on the die and how they talk to each other. That is what this guide covers. Everyone wants to talk about the cores. They do not want to talk about the interconnect. The interconnect is where your design goes to die. I had a project once where we had perfectly good cores, decent memory controllers, and then the AXI interconnect became so congested that our worst-case latency spiked to 400 cycles. The benchmark numbers looked fine on paper because the benchmarks do not stress the interconnect the way real workloads do. You need to model your NoC or bus matrix before you commit to any core configuration. Not after. Before. Use a cycle-accurate simulator if you have the resources, or at minimum a bandwidth-proportional model. I usually run a quick estimation with a tool like SystemC-based traffic generators to see where the hot spots form. This typically takes about two days of setup time but saves you months of debug later. The alternative is watching your tapeout miss timing because the L2 cache could not feed the cores fast enough and you had no idea why until the RTL was done.
Memory Hierarchy Decisions Will Define Your Chip
The memory hierarchy is where most budget gets consumed and where most performance leaks happen. You need to think about this in layers, and you need to understand the bandwidth requirements at each layer before you assign cache sizes. Start with the register file and L1 cache. These are private to each core or cluster. Then move to L2, which is often shared within a cluster. Then L3 or system-level cache, which is shared across the entire die. Then main memory, whether that is LPDDR5, HBM, or something else. Each layer has a different access time, capacity, and power profile. The trick is matching the data flow to the right layer. One thing most designers get wrong is the L3 cache size assumption. Everyone wants to make it big. Big caches reduce miss rates but they also increase access latency and power. I learned this the hard way on a GPU-oriented SoC where we put a 32MB L3 in and the access latency went from 40 cycles to 120 cycles under certain traffic patterns. The throughput tanked because threads were waiting on cache lines that took forever to retrieve. We ended up splitting it into two 16MB banks and the performance came back. Bank configuration matters more than total capacity in many cases.
Get the Full Details
Heterogeneous Computing Is Not Just Throwing Different Cores Together
You will see a lot of documentation that treats heterogeneous computing as a simple matter of putting ARM cores next to an NPU and calling it done. It is not that simple. The scheduling problem is genuinely hard. You have to decide which workload runs on which processor, and if you get that wrong you waste more energy than you save. The kernel scheduler is your first stop. Linux has some support for big.LITTLE type arrangements but it is not great at making fine-grained decisions. I spent weeks tuning the energy model parameters in the scheduler for a project where we had a mix of A78 cores and a RISC-V based control cluster. The default policy would push everything to the big cores because it thought they were more efficient per task. They were not. The small cores handled the same workload at half the power because the big cores had to run at higher frequencies to manage their thermal envelope. Once I tuned the energy model correctly, we saw about 30 percent improvement in battery life for typical workloads. For NPUs and accelerators, the question is always how to get data to them efficiently. DMA engines are your friend here. Setting up a proper scatter-gather DMA pipeline means the processor does not sit idle waiting for data movement. I recommend designing your DMA controllers with hardware priority queues so that high-priority data streams do not get blocked by bulk transfers. This is especially important for video pipelines where you have multiple resolution streams competing for bandwidth.
Predictable Power Delivery Is A Real Engineering Challenge
Power integrity is not just a physical design problem. It starts at the architecture level. When you design a power gating strategy, you need to account for state save and restore overhead. I worked on a chip where we power gated entire clusters between tasks and saved maybe 5 milliwatts per cluster but spent 2 milliseconds restoring state. The recovery time wiped out whatever benefit you got and introduced latency spikes that broke real-time guarantees. For latency-sensitive workloads, partial power gating is often better than full retention mode shutdown. The DVFS (Dynamic Voltage Frequency Scaling) implementation also needs careful thought. You cannot simply scale voltage and frequency independently. There are minimum voltage corners at each frequency, and the relationships are not linear. I use a look-up table approach stored in the power management firmware. It is not elegant but it works. You define the operating points, validate them against your timing signoff data, and then the firmware interpolates between them at runtime. This approach typically adds about 50 microseconds of transition overhead per frequency change, which is acceptable for most workloads but terrible for interrupt-driven tasks.
Security Peripherals Are Not Optional
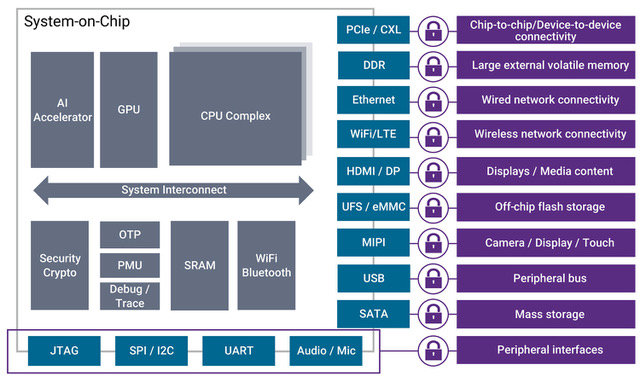
Every SoC today needs a secure boot chain, a trusted execution environment, and hardware-rooted key storage. This is not a luxury feature. If you ship a chip without these, you are vulnerable to reverse engineering, firmware tampering, and side-channel attacks. The ARM TrustZone architecture is the standard approach, but implementing it correctly requires understanding the memory protection unit configuration and the privilege level boundaries. One common mistake is assuming that a security perimeter around the TEE means the TEE is secure. It does not. The hypervisor or the OP-TEE monitor has access to everything in the system. If there is a bug in the monitor code, the entire security model collapses. I have seen this happen in production. A buffer overflow in the monitor allowed an attacker to escalate from a normal-world application to monitor privileges, and from there to access the secure world's memory. The fix required a full architectural review and a redesign of the monitor interface. Budget extra time for security code review. It will take twice as long as you think.

Verification Takes Longer Than You Think
I need to be blunt about this. Verification usually takes three to five times longer than the initial architecture design phase. Most teams underestimate this by a factor of two at minimum. The complexity comes from the interaction between blocks, not from any single block working incorrectly in isolation. UVM (Universal Verification Methodology) is the standard, but it is not a silver bullet. You need a mix of constrained random verification, functional coverage, and formal verification for critical paths. I usually allocate about 40 percent of verification time to UVM testbench development, 35 percent to test execution and debug, and 25 percent to formal verification of memory controllers and interconnect protocols. The formal verification part catches issues that simulation misses, particularly around deadlock conditions in the NoC and FIFO overflow scenarios. Emulation and prototyping on FPGA should be reserved for final validation. Using them earlier in the development cycle is possible but expensive. A full-system emulation run can take weeks to set up and requires a significant amount of RTL to be ready first. If your RTL is still changing, you are wasting time retargeting the emulation platform. Wait until the RTL is stable and your testcases are written before committing to emulation.
Realistic Performance Estimates Come From Real Workloads
Synthetic benchmarks lie. They show you the best case performance under ideal conditions. Your actual users will not run synthetic benchmarks. They will run applications with unpredictable memory access patterns, bursty compute demands, and varying thread counts. You need to instrument your chip with performance counters early in the design phase so you can capture real-world metrics during testing. I always recommend running a small set of representative applications through your emulator or FPGA prototype. These do not need to be full production applications. Even simple benchmarks like Stream for memory bandwidth, LINPACK for floating point performance, and a custom workload that mirrors your target application profile will give you much better data than any generic benchmark suite. Collecting this data typically takes one to two weeks of emulation time but gives you confidence that your architecture will perform as expected in the field. The gap between simulated performance and silicon performance is usually 10 to 20 percent due to parasitics, timing margins, and corner cases that simulation does not capture. Plan for that. If your architecture targets 2 teraops in simulation, expect around 1.6 to 1.8 teraops from silicon. Anything less means you have a verification or design issue to investigate.
Cost Management Throughout The Design Flow
Die size is money. Every square millimeter costs you in mask sets, yield loss, and packaging. I have seen projects blow their budget because the initial floorplan was too optimistic about how efficiently the blocks would pack. The placement and routing tool always needs more area than you expect. Plan for a 15 to 25 percent overhead over your theoretical minimum die size. Yield modeling should be part of your architectural exploration. A larger die has lower yield. If you are targeting high-volume production, consider whether splitting functionality across multiple chips in a package (chiplet approach) makes sense. The interconnect complexity increases but your yield per die improves. This tradeoff becomes favorable when your monolithic die exceeds roughly 400mm squared depending on the process node and your target defect density. For most consumer SoCs, this is not an issue yet, but it is worth understanding for future projects. IP licensing costs can also bite you. Sophisticated IP blocks from major vendors come with significant upfront fees and per-unit royalties. I have seen IP costs account for 20 to 30 percent of the total project budget on complex SoCs. Negotiate hard on this. Some vendors are willing to reduce fees for high-volume commitments. Open-source IP like the RISC-V cores is an alternative but factor in the verification cost. Verifying open-source IP to the same quality standard as commercial IP can take several months of engineering time.
Common Pitfalls That Waste Time And Money
Here are the mistakes I see most often, and they are all fixable if you catch them early. Underestimating cooling requirements. A chip that works at room temperature in simulation may fail in a sealed enclosure at 85 degrees Celsius ambient. Thermal modeling should be part of your architecture signoff, not an afterthought. I recommend using computational fluid dynamics simulation for the package-level thermal analysis once the floorplan is locked. Ignoring clock domain crossing issues. Multi-clock designs require careful CDC analysis. I have seen metastability failures in production chips because the CDC check was run too late in the flow. Run CDC analysis early and often. Integrate it into your synthesis flow so that violations are caught before layout.
Over-optimizing for a single workload. It is tempting to design your architecture around the performance characteristics of one key application. But markets change. Product lifecycles extend. Design for flexibility where the cost is low. Adding a programmable coprocessor that you can configure later is often cheaper than redesigning the entire data path. Neglecting debug infrastructure. JTAG interfaces, trace buffers, and logic analyzers are essential for post-silicon validation. I usually allocate about 5 percent of gate count to debug infrastructure. It sounds like a lot but skipping it will cost you weeks of debugging time later. A proper ETM (Embedded Trace Macrocell) setup can reduce post-silicon bringup time from months to weeks for complex multi-core systems.
Where This Approach Falls Short
This methodology assumes you have access to a modern process node with mature IP availability. If you are working with older nodes or foundries with limited PDK support, many of these recommendations need adaptation. The timing closure strategies, for example, are significantly more difficult on legacy processes where DRC rules are less forgiving and design rule kits are outdated. The cost model also breaks down for low-volume or specialized applications. The verification investment I described is justifiable for consumer volumes in the millions. For industrial or medical applications with volumes in the thousands, a simpler architecture with less verification coverage may be more appropriate. Do not apply high-volume methodologies to low-volume projects. You will waste resources that could be better spent on application-specific optimization. Finally, this guide focuses on general-purpose SoCs. Specialized accelerators for AI inference, signal processing, or cryptographic operations have different design considerations that are not fully covered here. If your application requires significant custom hardware acceleration, you should invest additional time in algorithm-hardware co-design before committing to a floorplan.