The Program Counter and General Purpose Registers: What Actually Matters
The program counter is one of the most misunderstood pieces of a CPU. People treat it like it's just some pointer that gets incremented, and then move on. It's not that simple, and if you're doing anything past writing assembly for a class project, the simplification will hurt you. Let me walk through how these registers actually behave in practice, the things documentation rarely mentions, and where people tend to break things.
Unleashing The Hidden Power Of Program Counter A Comprehensive Guide To The General Purpose Register
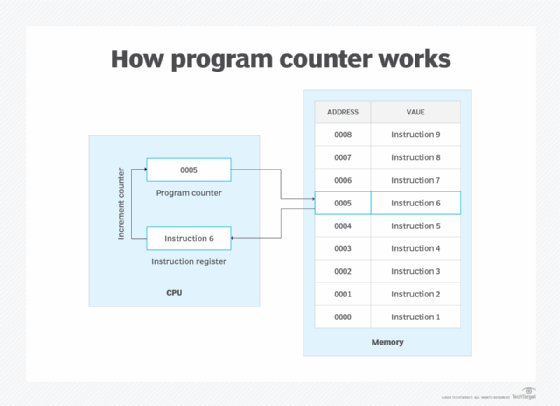
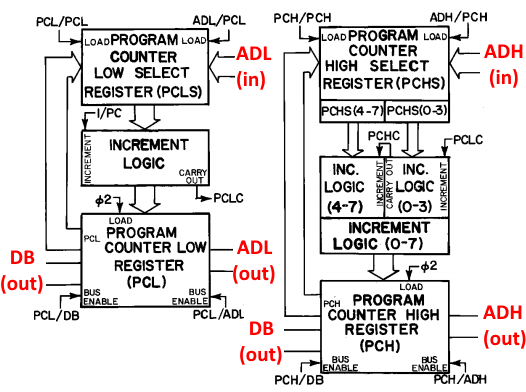
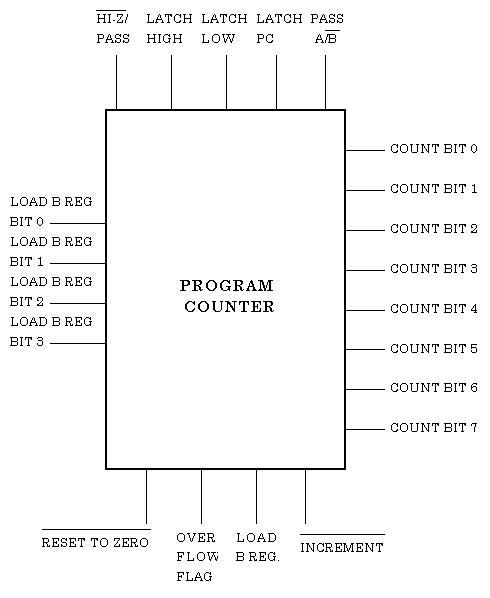
The program counter (PC), sometimes called the instruction pointer (RIP/EIP depending on architecture), holds the address of the next instruction to execute. That's the textbook definition. The thing nobody emphasizes enough is that the PC is not a general purpose register. You cannot use it as a data variable. You cannot load values into it directly on most architectures without going through a jump or call instruction. This distinction matters more than beginners realize. General purpose registers are where you actually do work. On x86-64, you have rax, rbx, rcx, rdx, rsi, rdi, r8-r15, plus rsp and rbp. On ARM, you have x0-x30 with x0-x7 typically used for argument passing and return values in ABIs, and x18 being reserved. MIPS gives you $zero (hardwired to 0), $at (assembly temporary), $v0-$v1 (values), $a0-$a3 (arguments), $t0-$t7 (temporaries), and $s0-$s11 (saved registers). Each architecture organizes this differently, but the pattern is consistent: some registers have calling convention responsibilities, and everyone needs scratch registers for intermediate calculations. Here is the part that trips people up repeatedly: the PC advances automatically with every instruction fetch, but conditional branches make that advancement non-linear. When a branch is taken, the PC gets overwritten with a new address. On modern processors with out-of-order execution, the CPU may speculatively fetch instructions ahead of the actual PC value. This means the PC you see in a debugger at a breakpoint is not necessarily where the pipeline started fetching from. That distinction matters for performance debugging and almost never gets explained in introductory material.
I ran into a specific issue last year working on a bootloader for an ARM Cortex-M3. The PC behaves slightly differently on this architecture because of the Thumb instruction set. The least significant bit of the PC is always 1 when executing Thumb code, indicating the instruction set state. When I was writing code that jumped between ARM and Thumb states, I kept getting HardFault exceptions because my immediate values didn't account for this LSB. The workaround was straightforward once I understood it: use BX (branch and exchange) instructions instead of direct B (branch) when switching instruction sets, and make sure your linker script properly separates the code regions. This saved me about two days of debugging that should have been obvious from reading the ARM architecture reference manual more carefully. General purpose registers serve a different purpose entirely. They hold the actual data your program manipulates. There is no inherent meaning to most of them from the hardware perspective, which is why they are called general purpose. But the operating system and ABI conventions layer meaning on top of that raw capability. When you compile C code, the compiler decides which register holds which variable based on optimization level, register pressure, and the calling convention. At -O0 you might see every variable in a separate register because nothing is being optimized. At -O3 the compiler is aggressively reusing registers and may spill values to the stack even for things that technically fit in registers. A counter-intuitive insight about general purpose registers that most tutorials skip: the reason you have so many of them is not primarily to hold more variables simultaneously. It is to reduce memory traffic. Every time you can keep a value in a register instead of loading or storing it to RAM, you save hundreds or thousands of cycles depending on whether that RAM is L1 cache, L2, main memory, or swap. This is why register allocation is one of the most important problems in compiler design. A good register allocator can make a program significantly faster without changing any logic.
Get the Full Details
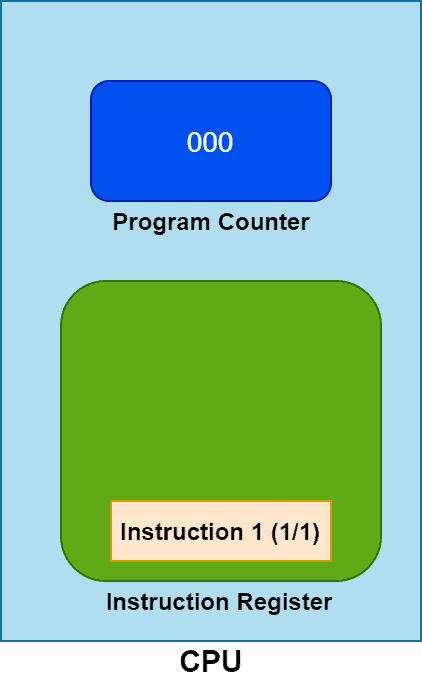
Another thing people miss about the PC: it is not just a sequential counter. Pipelined processors execute multiple instructions in overlapping stages, and the PC can be ahead of where the instruction stream actually commits. This is why exception handling on modern CPUs involves unwinding the pipeline, not just jumping to an error handler. The PC value at the moment of an exception may point to an instruction that has already been fetched and partially decoded but not yet completed its execution. If you are writing low-level exception handlers or implementing custom context switching, you need to understand this, because simply saving and restoring the PC is not enough to guarantee correct program state. On x86-64 specifically, there is a quirk with the RIP-relative addressing mode that most beginners overlook. When you write something like mov rax, [rip + 0x1234], the offset is calculated relative to the PC value at the next instruction, not the current one. This means the assembler and linker handle the addressing correctly, but if you are manually patching machine code or computing addresses at runtime, you need to account for the fact that the PC has already advanced by the length of the current instruction. I have seen this cause off-by-4 errors in shellcode and binary patching tools, and it is frustratingly easy to miss because the assembly source looks completely correct. For general purpose registers, the calling convention is where theory meets practice. On Linux x86-64, the System V ABI specifies that rdi, rsi, rdx, rcx, r8, and r9 hold the first six integer or pointer arguments. Anything beyond that goes on the stack. Return values come back in rax. The compiler generates prologue and epilogue code that saves and restores callee-saved registers like rbx, rbp, and r12-r15. If you are writing inline assembly or interfacing between languages with different ABI expectations, ignoring these conventions will produce subtle bugs that are extremely difficult to diagnose. The program will appear to work sometimes and fail randomly, usually under conditions where the compiler happens to choose a different register allocation strategy.
There is a practical technique that many developers find useful when debugging register-related issues: compile with -fno-omit-frame-pointer and use objdump -S on the resulting binary. This gives you the assembly alongside the source, and with frame pointers enabled, the stack frame layout becomes much more predictable. You can see exactly which register holds which value at each instruction, and you can trace how the compiler manages register pressure across function boundaries. It is not a substitute for understanding the architecture, but it is an effective way to bridge the gap between high-level code and what the CPU actually executes. One area where the PC and general purpose registers interact in non-obvious ways is indirect branch prediction. When your code does a jump through a register, like jmp rax, the CPU has to predict where that register points based on historical data. If the register value changes unpredictably, branch prediction fails frequently, and you can see measurable performance degradation. This is relevant for switch statements with sparse cases, hash table lookups, and any code that uses function pointers in a loop. The fix is usually to restructure the code so that branch patterns are more predictable, not to optimize around the registers themselves. The limitations of relying solely on general purpose registers are worth stating plainly. On constrained architectures like 8-bit microcontrollers, you might have only two or four general purpose registers. In those environments, register allocation is not a compiler optimization problem, it is a survival problem. Everything that does not fit in a register goes to RAM, and RAM access dominates execution time. This is why embedded C programmers often use the restrict keyword and declare variables with careful attention to scope, to help the compiler keep values in registers. On a modern desktop CPU with 16 or more general purpose registers, this level of care is unnecessary for most applications, but the underlying principle remains the same.
When working with the PC in contexts like JIT compilation or dynamic code generation, you will encounter a problem that is rarely discussed outside of systems programming circles: instruction cache coherence. On many architectures, including x86-64, the instruction and data caches are effectively coherent, so you can generate code at runtime and execute it immediately. On ARM and some other architectures, you need to explicitly flush the data cache and invalidate the instruction cache after writing code to memory. Failing to do this results in code that appears to execute the old instructions or causes unpredictable behavior. I spent several hours tracking down this issue in a JIT compiler for a custom scripting language before realizing that the generated code was sitting in the data cache and the CPU was fetching stale instructions from the instruction cache. For most people reading this, the practical takeaway is straightforward. Understand that the program counter controls execution flow and is subject to branch prediction and pipeline behavior. Understand that general purpose registers are where computation happens and that the ABI conventions determine how they are used across function calls. Use debugging tools to observe actual register usage rather than guessing. And when you encounter unexpected behavior, check the architecture manual for the specific processor you are targeting, because the details vary more than most tutorials admit.