Workday Adaptive Planning REST API: What You Actually Need to Know Before You Start Building
Workday Adaptive Planning offers a REST API that lets you pull data out, push data in, and automate reporting without logging into the application every time. It is not an exotic interface. It follows standard HTTP conventions, uses OAuth 2.0 for authentication, and returns JSON payloads. Most integrations I have seen are reasonably straightforward. The frustrating ones come later. The authentication flow requires you to register a client application through the Adaptive Planning admin console, obtain a client ID and secret, and then exchange those credentials for an access token. The token endpoint is /oauth2/token and the typical response gives you a bearer token valid for 30 minutes by default. You will be refreshing tokens constantly if you are running anything beyond a quick script. I usually cache the token in a local file with a TTL of about 24 minutes so my processes do not hit edge cases around token expiry during long batch runs.
Unleashing New Heights A Deep Dive Into Workday Adaptive Planning Rest API
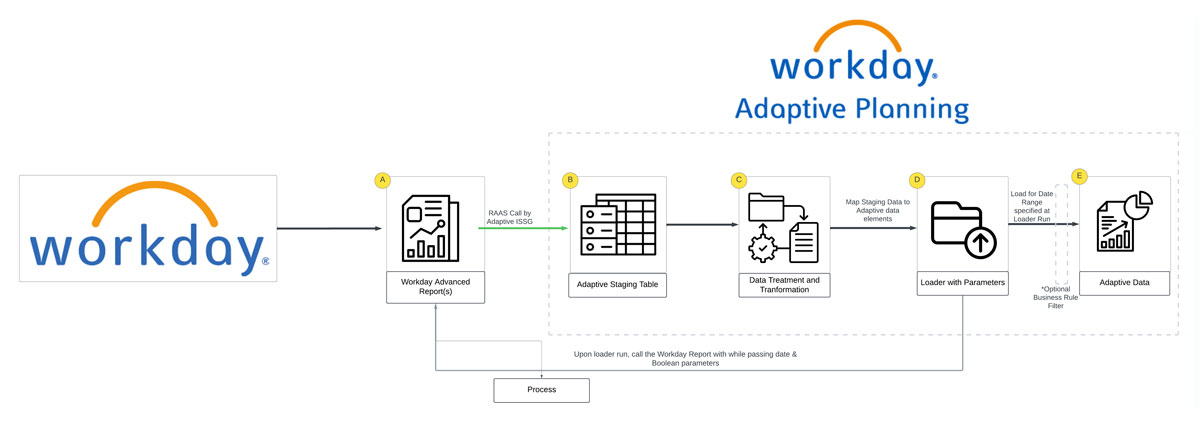
The API has two main categories of endpoints. There are the standard CRUD-style operations for entities like dimensions, members, scenarios, versions, and the data itself. Then there are the reporting endpoints, which include the get report method, the query dimension method, and the execute scheduled task method. The reporting endpoints are where most people get stuck because the request payloads look deceptively simple but behave unpredictably when you add filtering or pagination. Data reads go through the /rest/reports/instances endpoint. You submit a JSON body that specifies the report definition name, the scenario, the version, and any filters. The system returns a report instance ID, and you poll for completion using the same endpoint. This is asynchronous. Even a small financial model might take 30 to 90 seconds to generate if you are pulling full entity hierarchies. I once had a junior analyst write a loop that checked every 500 milliseconds and hit the rate limit within an hour. The fix was raising the interval to 3 seconds and adding exponential backoff after a 429 response. Adaptive Planning throttles at around 100 concurrent requests per tenant before it starts returning errors. Writing data back uses a different pattern. You call /rest/data/write with a payload containing the cell updates, and the system queues them for processing. Unlike some other planning platforms, Adaptive Planning does not give you synchronous confirmation that your data landed correctly. The response tells you the write was accepted into the queue, not that the cube processed it. If you need to verify a write succeeded, you have to read the affected cells back after a delay or use the validate endpoint before submitting the actual write. The validate endpoint checks permissions and structure without committing changes, which saved my team from a whole class of silent failures where a write appeared successful but actually rejected individual cells due to security restrictions.
One thing the documentation does not make clear is how the API handles locked periods. If a user has a period locked in the application, the API respects that lock entirely. Your write will fail with a specific error code indicating the period is locked. I learned this after a script accidentally pushed adjustments into a month that two controllers had already closed. The error message was not aggressive, but the rejection was real and immediate. The workaround was to check the lock status via the dimension endpoint before submitting any writes, which adds roughly two seconds per batch but prevents the embarrassing situation of trying to roll back committed data that is sitting inside a locked period. Pagination is another area that trips people up. The API uses a cursor-based approach, not offset-based. You pass a page size parameter and the response includes a next cursor string. If you switch to offset-based pagination thinking it will work like a traditional REST API, you will get unexpected duplicate rows or missing rows depending on how the underlying query engine processes the request. The recommended page size for production integrations is 500 records. Anything higher tends to cause timeout issues on complex reports, and anything lower makes the integration unbearably slow because of the round trip overhead. Security-wise, the API enforces the same user-level permissions that exist in the application. If a user cannot see a dimension member in the UI, the API will not return it either. There is no way to bypass that through the API. Some organizations set up service accounts with broad permissions for integration purposes, but this is a double-edged sword. A compromised service account with admin-level access can read or write any data in the tenant. I always recommend scoping the service account to the minimum dimensions, scenarios, and versions required, and auditing the API access logs quarterly. Adaptive Planning provides access logs under the administration section, but they only retain about 90 days of detail by default unless you have a separate logging integration in place.
Get the Full Details
The bulk of my frustration with this API has been around the inconsistency of error messages across endpoints. The report execution endpoint returns detailed JSON errors with specific codes when something goes wrong, like invalid filter syntax or missing required members. But the data write endpoint sometimes returns a generic success response even when individual cells were silently rejected. The only reliable way to catch these is to validate first, then compare the number of written cells against the number of input cells. If the count differs, you have silent rejections happening and you need to dig into the validate response to find out which cells failed and why. For people who want to experiment, Workday provides a documentation portal and a sample API console available through the Adaptive Planning application itself. Go to Administration, then API Tools, and you will find a built-in interface where you can test endpoints without writing any code. I use this constantly when I am trying to figure out the exact shape of a request payload. It is faster than debugging from a script and shows you the response structure directly. Rate limits are the most commonly misunderstood constraint. The published guidance says 100 concurrent requests, but in practice, heavy report generation can consume more internal resources than the concurrency limit alone would suggest. A single large report with 50,000 data points can tie up backend resources for a prolonged period, effectively reducing your available concurrency for other requests. If your integration includes multiple heavy reports running in parallel, you will feel the impact well before hitting the stated limit. Spreading report generation across off-peak hours and staggering the requests by at least five seconds between each one usually resolves this without requiring any architectural changes.
If your use case involves high-frequency writes or near real-time synchronization, the REST API is not the best tool. The write throughput tops out at around 5,000 cells per minute for typical configurations, and complex models with many interdependent dimensions will perform worse. In those scenarios, the CSV import process or the data load utility is more reliable, even though it requires a manual upload step. I have run both approaches side by side and the API consistently takes longer than expected for large datasets because of the validation and queuing overhead, even when the network latency is negligible. The integration with Workday HCM and Financials is another area where people overestimate what the API can do. Adaptive Planning can reference data from those systems through configured data sources, but the API does not expose the underlying sync jobs directly. You can trigger a data refresh through the API using the execute task endpoint, but the refresh schedule itself is managed in the application. If you need tighter coupling between Adaptive Planning and the source systems, you are better off configuring that at the integration layer rather than trying to orchestrate it through API calls alone. There is no SDK provided by Workday, which is a disappointment for developers who want something more structured than raw HTTP calls. Most teams end up wrapping the API in a thin client library of their own, which is not difficult but adds maintenance burden. The API itself is stable enough that library code does not need frequent updates, but the lack of an official package means you are responsible for handling token refresh, retry logic, pagination, and error classification yourself. A basic Python client with these features took my team about two weeks to build properly, including the edge case handling for rate limits and locked periods.
The API supports Webhooks for certain events, but the event coverage is limited compared to other enterprise platforms. You get notifications for report completion and data write acknowledgment, but you do not get granular events like dimension member creation or permission changes. If your integration depends on reacting to those kinds of changes, you will need to poll periodically or monitor the audit logs separately. The polling approach is simpler to implement but adds unnecessary load if the events you care about are rare. Overall, the Workday Adaptive Planning REST API is functional and follows modern standards. It is not elegant, and it has quirks that only become apparent under real workload conditions. The documentation covers the happy path well, but the failure modes and performance characteristics are things you learn by breaking things in a sandbox environment first. Do not take a production integration directly from the docs without testing token expiry handling, rate limit behavior, and write validation in a non-production tenant. The fixes are cheaper there than after you have pushed incorrect data into a live financial model.