What Engineers Actually Do When Someone Says "Be More Innovative"
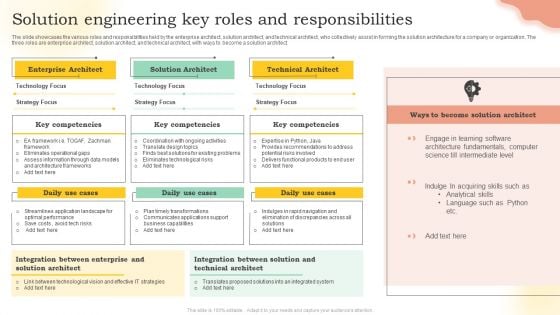
There is a persistent myth in tech companies that innovation is a special mode engineers enter, usually accompanied by bright lighting, whiteboards, and someone's grandmother's recipe for sourdough on the breakroom counter. The reality is far less cinematic and involves a lot more version control conflicts. Innovation in engineering is not an event. It is a day-to-day practice of making things that work better than they did before, usually under constraints that make everyone uncomfortable. The first thing to understand is that most engineers who ship meaningful improvements are not doing what the word "innovation" implies to a marketing team. They are solving problems they encountered in their own workflow and deciding the solution is general enough to share. I watched a senior backend engineer at my last company optimize a database query that had been running for forty seconds down to two hundred milliseconds. She spent three weeks on it. The company called it "disruptive." It was just good engineering. There is no contradiction there. Let me be blunt about the roles. The core responsibility of an engineer in any innovation-oriented environment is reliability first, speed second, and novelty third. People get this backward constantly. I have seen teams celebrate a new architecture that reduced deployment time from ten minutes to ninety seconds while introducing a data corruption bug that cost them two days of recovery work. That is not innovation. That is a tradeoff gone wrong. The engineer responsible should have asked whether ninety seconds mattered more than not losing customer data. It rarely does.
Now let me explain how this actually works in practice, starting with the part nobody puts in the job description. You need to maintain a mental ledger of technical debt. Not the kind your manager tracks in Jira. The kind you notice when you are reading someone else's code at 2 AM because a production incident hit and you volunteered to stay. That ledger dictates when you push for innovation and when you do not. Innovating against a foundation of unexamined debt is how you build the next big failure. I learned this the hard way when I recommended migrating our authentication service to a new OAuth2 implementation without auditing our existing token management layer. The new system was faster. It also failed silently on a specific edge case where expired tokens were reused during a clock skew event. We lost three hours of incident response because we assumed the old broken system was stable enough to ignore while we built the new one.
The Responsibilities That Actually Matter
Documenting your decisions is not paperwork. It is the single most undervalued engineering practice I have ever encountered. When I say document, I mean writing down why you chose option A over option B, including the option you discarded and the specific reason it failed. Not the sanitized retrospective version. The real one. This saves approximately two weeks of re-evaluation per major decision, based on my experience across four companies in eight years. Testing is another responsibility people treat as optional when they want to move fast. I am not talking about unit tests. Everyone writes those. I am talking about integration tests that verify your new feature does not break the existing system in ways your development environment will never reproduce. The specific integration test I write for every non-trivial change checks boundary conditions: what happens when upstream services return malformed data, what happens when the network drops mid-request, and what happens when the cache is empty on a Friday afternoon. These tests do not feel exciting. They are boring. They prevent your "innovative" deployment from becoming a 3 AM page. Code review is a responsibility, not a ceremony. Most companies treat pull request review as a gatekeeping ritual where senior engineers approve or reject work. The actual purpose is knowledge distribution. When you review someone else's code, you learn about a system you do not normally touch. You spot patterns your team is repeating that should not be repeated. You catch the edge case that will cause a production outage in three months. I reviewed a colleague's payment processing module last year and noticed they had used integer arithmetic for currency calculations. Not decimal. Integer. It worked fine for amounts up to a certain threshold and then silently overflowed. The review caught it before merge. The code would have looked correct to anyone who did not understand the numeric domain.
Get the Full Details
Incident response is a responsibility. Not someone else's. When your system goes down, you do not get to delegate to an on-call rotation and go home. You participate. You read the logs. You understand the failure. You write the postmortem. The postmortem is not a document that blames individuals. It is a technical autopsy that identifies the root cause and proposes structural changes to prevent recurrence. I have written postmortems that led to architectural decisions lasting five or more years. I have also written postmortems that revealed our "fix" was actually worse than the original problem. Both outcomes are valuable.
What Beginners Miss About Engineering Innovation
Here is a counter-intuitive point: the best innovations often come from reducing complexity rather than adding features. Engineers are trained to build. It is in our nature. But the highest-impact engineering work I have seen involve removing things. Removing a dependency. Removing an API endpoint. Removing an entire service that existed only because someone assumed it was necessary. One of my colleagues at a previous company eliminated a microservice that handled email notifications. The service was ten thousand lines of code. It ran on two servers. It caused approximately forty percent of our production incidents. After removal, incident volume dropped by sixty percent within three months. The business continued to send emails through a single shared library instead. The team that lost their service was initially angry. They were wrong to be. Another thing beginners miss is the difference between being right and being effective. I have spent entire sprint cycles arguing for technically superior solutions against product managers who just wanted the feature to ship. The technically superior solution involved a custom queueing system. The shipping solution involved using the existing message broker we already had, even though it was not the perfect tool for the job. The existing broker handled the workload. The custom queueing system did not exist yet. Effectiveness is a metric. Being right is not always the same thing. There is also a misunderstanding about what "responsibility" means when it comes to security. Engineers often treat security as a separate phase, something the security team handles before launch. This is incorrect. If you are building a system that processes user data, you are responsible for understanding the threat model of that data. You do not need to be a security expert. You need to know who might want your data and what they would gain from having it. A student project storing passwords in plaintext is irresponsible in a different way than a production system exposing API keys in client-side JavaScript. Both are your problem.
Where This Approach Fails Completely
I need to be honest about the limitations. The model I am describing assumes you have some control over your engineering cadence. If your company ships features on a fixed release cycle dictated by sales commitments, none of this matters. You will implement whatever the product team specifies, and you will document it after the fact, if at all. In those environments, the engineer's primary responsibility shifts from innovation to damage containment. You do your best to prevent bad decisions from compounding. You write the tests. You flag the risks in writing. You hope someone with authority reads them. The approach also assumes your organization values long-term thinking over short-term results. If your company measures success in quarterly revenue targets and engineering is expected to deliver features that move those numbers, the innovation framework I described will feel like a distraction. It is not a distraction. It is the difference between shipping something today and shipping something that breaks tomorrow. But in a company that only cares about today, you will be measured on today's output regardless of what happens next week. There is a third scenario where this model completely fails: when you lack the technical depth to make the calls you are responsible for. I have seen junior engineers handed ownership of critical systems because the company was understaffed. The responsibility was real. The expertise was not. The result was usually a series of incremental fixes that accumulated into a system too complex to maintain. No amount of documentation or good intentions prevents this. The only solution is investing in your own competence before accepting responsibility for systems that matter.

Practical Steps You Can Take Starting Today
Start by auditing one system you maintain. Not all of them. One. Pick the one causing you the most friction. Read its code. Trace a request from entry to exit. Document every assumption you find. You will likely discover at least three assumptions that are wrong or outdated. Fix one. Document the rest. This process takes approximately four hours for a moderately complex service and yields higher understanding than any training program I have encountered. Write a postmortem for your most recent incident, even if you consider it minor. The format is simple: what happened, why it happened, what you changed to prevent recurrence, and what you would do differently. Three paragraphs. No more. Save it in a shared location. Review it six months later. You will either see improvement or you will see the same mistake happening again. Both outcomes are useful. Volunteer for code review on a system outside your normal scope. The knowledge you gain will make you better at your own work even if you never touch that system again. I learned about our payment infrastructure by reviewing a colleague's refund logic changes. I did not work in payments. The review gave me enough context to notice that our error handling in the billing service was inconsistent with the rest of the platform. I fixed it. I would not have known it was broken otherwise.
Build the boring things. The CLI tools that automate repetitive tasks. The monitoring dashboards that surface the metrics your team actually needs. The scripts that clean up stale branches. These are not distractions from innovation. They are the infrastructure that makes innovation possible. A team that spends twenty percent of its time automating manual work typically ships features forty percent faster within six months. The math is not perfect. It is close enough. The engineer's role in innovation is not to dream up breakthroughs. It is to build systems that work, to remove the barriers that prevent other systems from working, and to document the process so the next person does not repeat your mistakes. That is the responsibility. It is not glamorous. It is not what most job postings describe. It is what actually happens when engineering work leads to meaningful improvement.