Website Loading Speed Is The Thing Everyone Talks About But Almost No One Gets Right
I have spent more years than I care to admit chasing millisecond improvements on client sites, and the general pattern never changes. People obsess over the wrong layer, run the same five tools, and get confused when the numbers do not move. Here is how actual website speed measurement and optimization work, what breaks, and what you should do about it.
Unleash The Power Of Speed How Fast Is Your Website Explained
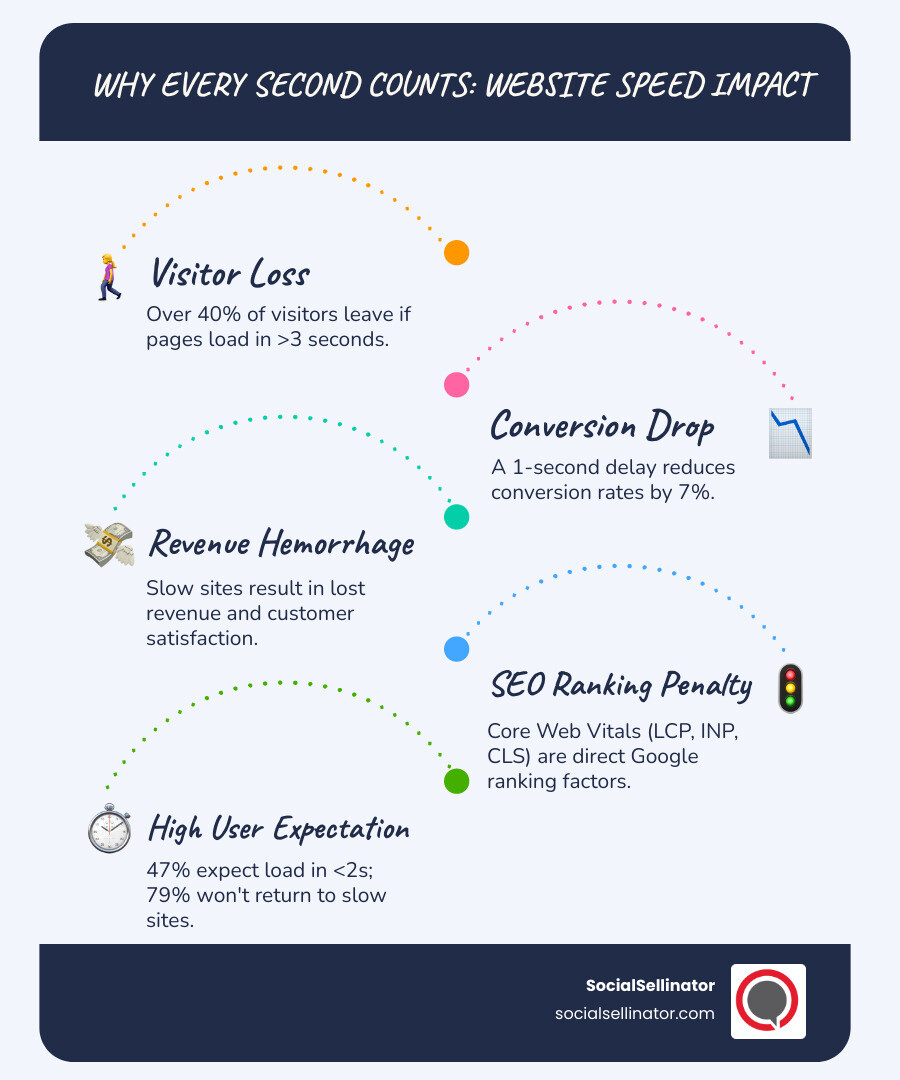
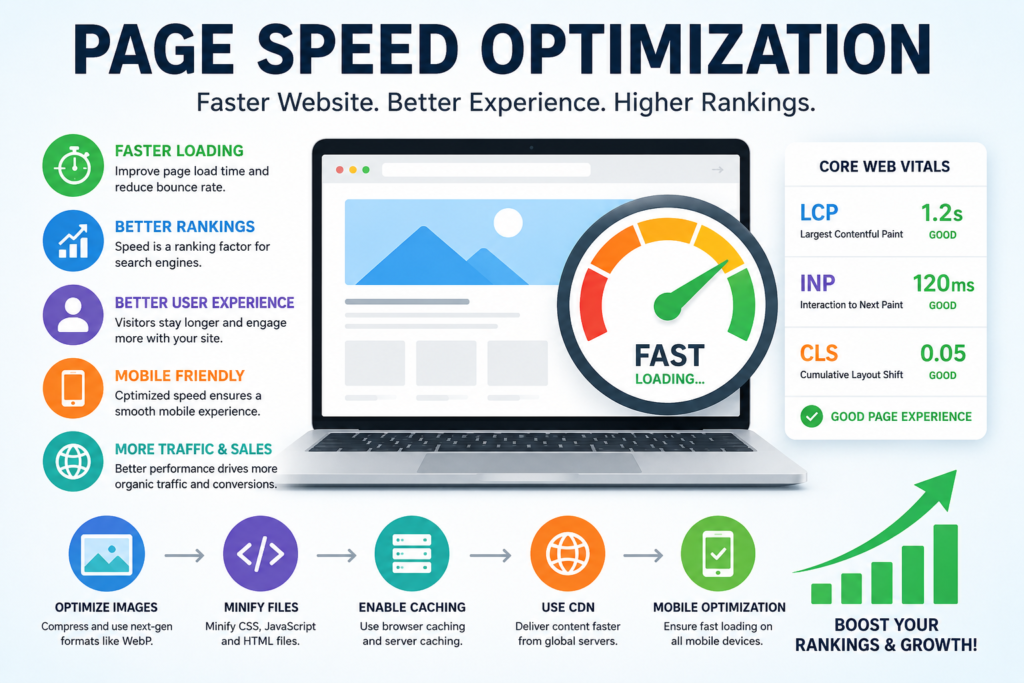
Let me start with the part most tutorials skip. Page speed is not one number. It is a cluster of Core Web Vitals metrics plus several underlying measurements that together describe how your site performs in the wild. LCP tells you when the largest visible element finished rendering. FID or INP measures how long the page is unresponsive after a user tap or click. CLS tells you whether layout elements jump around while content loads. These are the three you should stop ignoring. The problem is that these metrics come from very different parts of the page lifecycle. LCP is about rendering. INP is about JavaScript execution and main thread blocking. CLS is about CSS layout and image/video dimensions. Optimizing one without looking at the others usually creates a new problem.
The Tools You Actually Need
Chrome DevTools Performance tab. Lighthouse. WebPageTest. GTmetrix if you need to share results with people who do not know how to look at a waterfall. Field data from Chrome UX Report or the PageSpeed Insights API for real-user metrics. That is it. Everything else is noise. I used to run all of them in parallel and pretend the variance proved something. It did not. Here is what actually helped me settle on a single source of truth: field data first, synthetic second. Chrome UX Report gives you the measurements people actually experienced. Synthetic tests like Lighthouse are useful for reproducible debugging, but they simulate a phone on a throttled connection inside a data center, which is nowhere close to what a user in Mumbai or Sao Paulo is dealing with.
Get the Full Details
Where Speed Problems Actually Come From
There are three categories, and they behave completely differently. Category one is network. Big files. Too many requests. No caching. This is the easy category. You identify it with a waterfall view, you compress assets, you enable compression, you set cache headers, and you are done. Category two is render blocking. CSS and JavaScript loaded in the wrong order, large stylesheets that block paint, synchronous scripts that halt parsing. This is the medium difficulty category. Defer non-critical JS. Async where you can. Inline critical CSS or load it asynchronously. Use display swap for fonts instead of hiding text while they load.
Category three is the hard one. JavaScript execution cost. Framework overhead. Inefficient re-renders. Third-party scripts that do not clean up after themselves. This is where most sites die. You can have perfect caching and zero render-blocking resources and still tank your INP because a single library is running a layout recalculation on every scroll event.
A Real Example From Recent Work
Last quarter I audited a headless commerce site that scored 94 on Lighthouse desktop and 31 on mobile. The desktop score was a lie. The mobile score matched reality. Field data showed an INP of 680 milliseconds, which is deep into the poor range. The issue was not images. It was not large CSS. It was a single analytics tracking script that was doing synchronous DOM reads on every route change, combined with a client-side routing library that triggered full React re-renders instead of targeted state updates. The fix was not dramatic. We switched the analytics payload to sendBeacon so it ran asynchronously without blocking the main thread. We replaced the full-page client router with a lighter setup that only re-rendered the changed subtree. We also set up route-level code splitting so each page only loaded its own dependencies. INP dropped to 140 milliseconds within two weeks of deployment, based on field data. Lighthouse jumped to 72 on mobile. Not magic. Just identifying the right category of problem.
Common Pitfalls That Waste Time
People compress images until they look like a watercolor painting and then move on without checking whether the image dimensions were actually set in the HTML. If width and height attributes are missing, the browser has to do a layout shift when the image loads, which creates CLS. That shift will ruin your experience score even if the file is tiny. Another one is aggressively deferring JavaScript and then wondering why interactive elements are broken. Defer and async are not the same thing. A deferred script runs after HTML parsing completes but in order. An async script runs whenever it finishes downloading, potentially before parsing is done. If your script depends on DOM elements being present, async will break it randomly depending on network conditions.
What Most Optimization Guides Leave Out
Server response time matters more than most people admit. If your Time to First Byte is 800 milliseconds because your backend is slow or your CDN cache is cold, no amount of image optimization will save your mobile score. Cold CDN caches on newly deployed or rarely visited pages can add over a second to TTFB. Warm them up with a preheat strategy or accept that the first visitor will always pay that penalty. Another thing nobody talks about enough is the difference between local dev performance and production performance. Your site might run fine on localhost with a fast machine and no network throttling. That does not mean anything. Test on a device that matches your target audience, over a realistic connection. I set up a consistent testing routine using a mid-range Android phone on 4G with Chrome DevTools throttle set to Slow 4G. The numbers from that setup correlate much better with actual user complaints than any dashboard score.
Practical Steps If You Want To Start Today
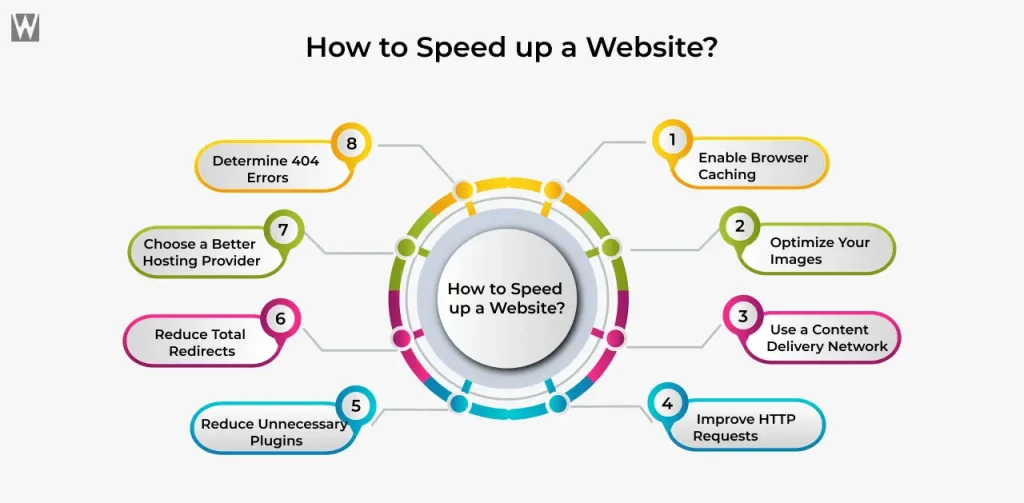
Run a Lighthouse audit on your mobile profile. Look at the specific items flagged, not the overall score. Check whether the largest contentful paint element is an image, a heading, or a video. That tells you which category to focus on. Inspect the biggest scripts in your waterfall. If any third-party script is larger than 150 kilobytes uncompressed, investigate alternatives. Audit your font loading strategy. Self-hosted fonts with font-display: swap are usually better than pulling from a CDN without a fallback plan. Set explicit image dimensions on every image tag. Enable Brotli compression on your server if it is not already on. Brotli typically achieves 15 to 20 percent better compression than Gzip on text-based assets, and the CPU cost difference is negligible on modern servers. Check your cache headers. A common mistake is setting short max-age values on assets that never change, like versioned CSS and JS files. Those should have a long cache duration with content-hash filenames so browsers can cache them indefinitely. Static assets that never change should be cached for a year with immutable flags. Pages and API responses need short or no-cache headers. Mixing these up is an easy way to create either stale content or excessive network requests.
When Optimization Stops Helping
There is a point where further optimization yields diminishing returns that are not worth the engineering effort. If your LCP is already under 2.5 seconds on field data and your INP is under 200 milliseconds, you are in acceptable territory for most use cases. Pushing from 1.8 seconds to 1.4 seconds might look good on a dashboard but will not move business metrics. The exception is e-commerce and performance-critical apps where every hundred milliseconds correlates with conversion rate changes. In those cases the math justifies the effort. For most other sites, it does not. Sometimes the best optimization is architectural. Moving from a monolithic bundle to code-split routes. Replacing a heavy framework with something lighter for content-heavy pages. Choosing a simpler templating approach instead of a full client-side framework for static marketing pages. I made this call on a company blog that was built as a React app with server-side rendering. The page weight was over 2.4 megabytes before compression. Switching to a static site generator cut the initial load to under 400 kilobytes and eliminated the JavaScript parsing overhead entirely. The SEO traffic improved because the pages rendered faster for crawlers too.
Monitoring After You Fix Things
Set up real-user monitoring if you can. Sentry, Cloudflare Web Vitals, or the Chrome UX Report API can give you ongoing field data. Synthetic tests should be scheduled weekly at minimum. If you do not monitor continuously, you will not notice when a new deployment or a third-party script update breaks something you spent weeks fixing. I lost three months of gains once because a marketing team added a popup widget without realizing it was injecting two synchronous scripts and a massive tracking library onto every page. The regression was invisible in local testing and only caught by the monitoring alert.
The Bottom Line
Website speed is a systems problem, not a single trick. You need to understand where time is being spent, measure it correctly, and treat optimization as an ongoing process rather than a one-time task. The tools exist. The methods are well documented. Most sites are not optimized because the work is unglamorous and requires patience rather than a quick fix. That is fine. The results speak for themselves when you actually ship them.