Writing JSON Files in Python
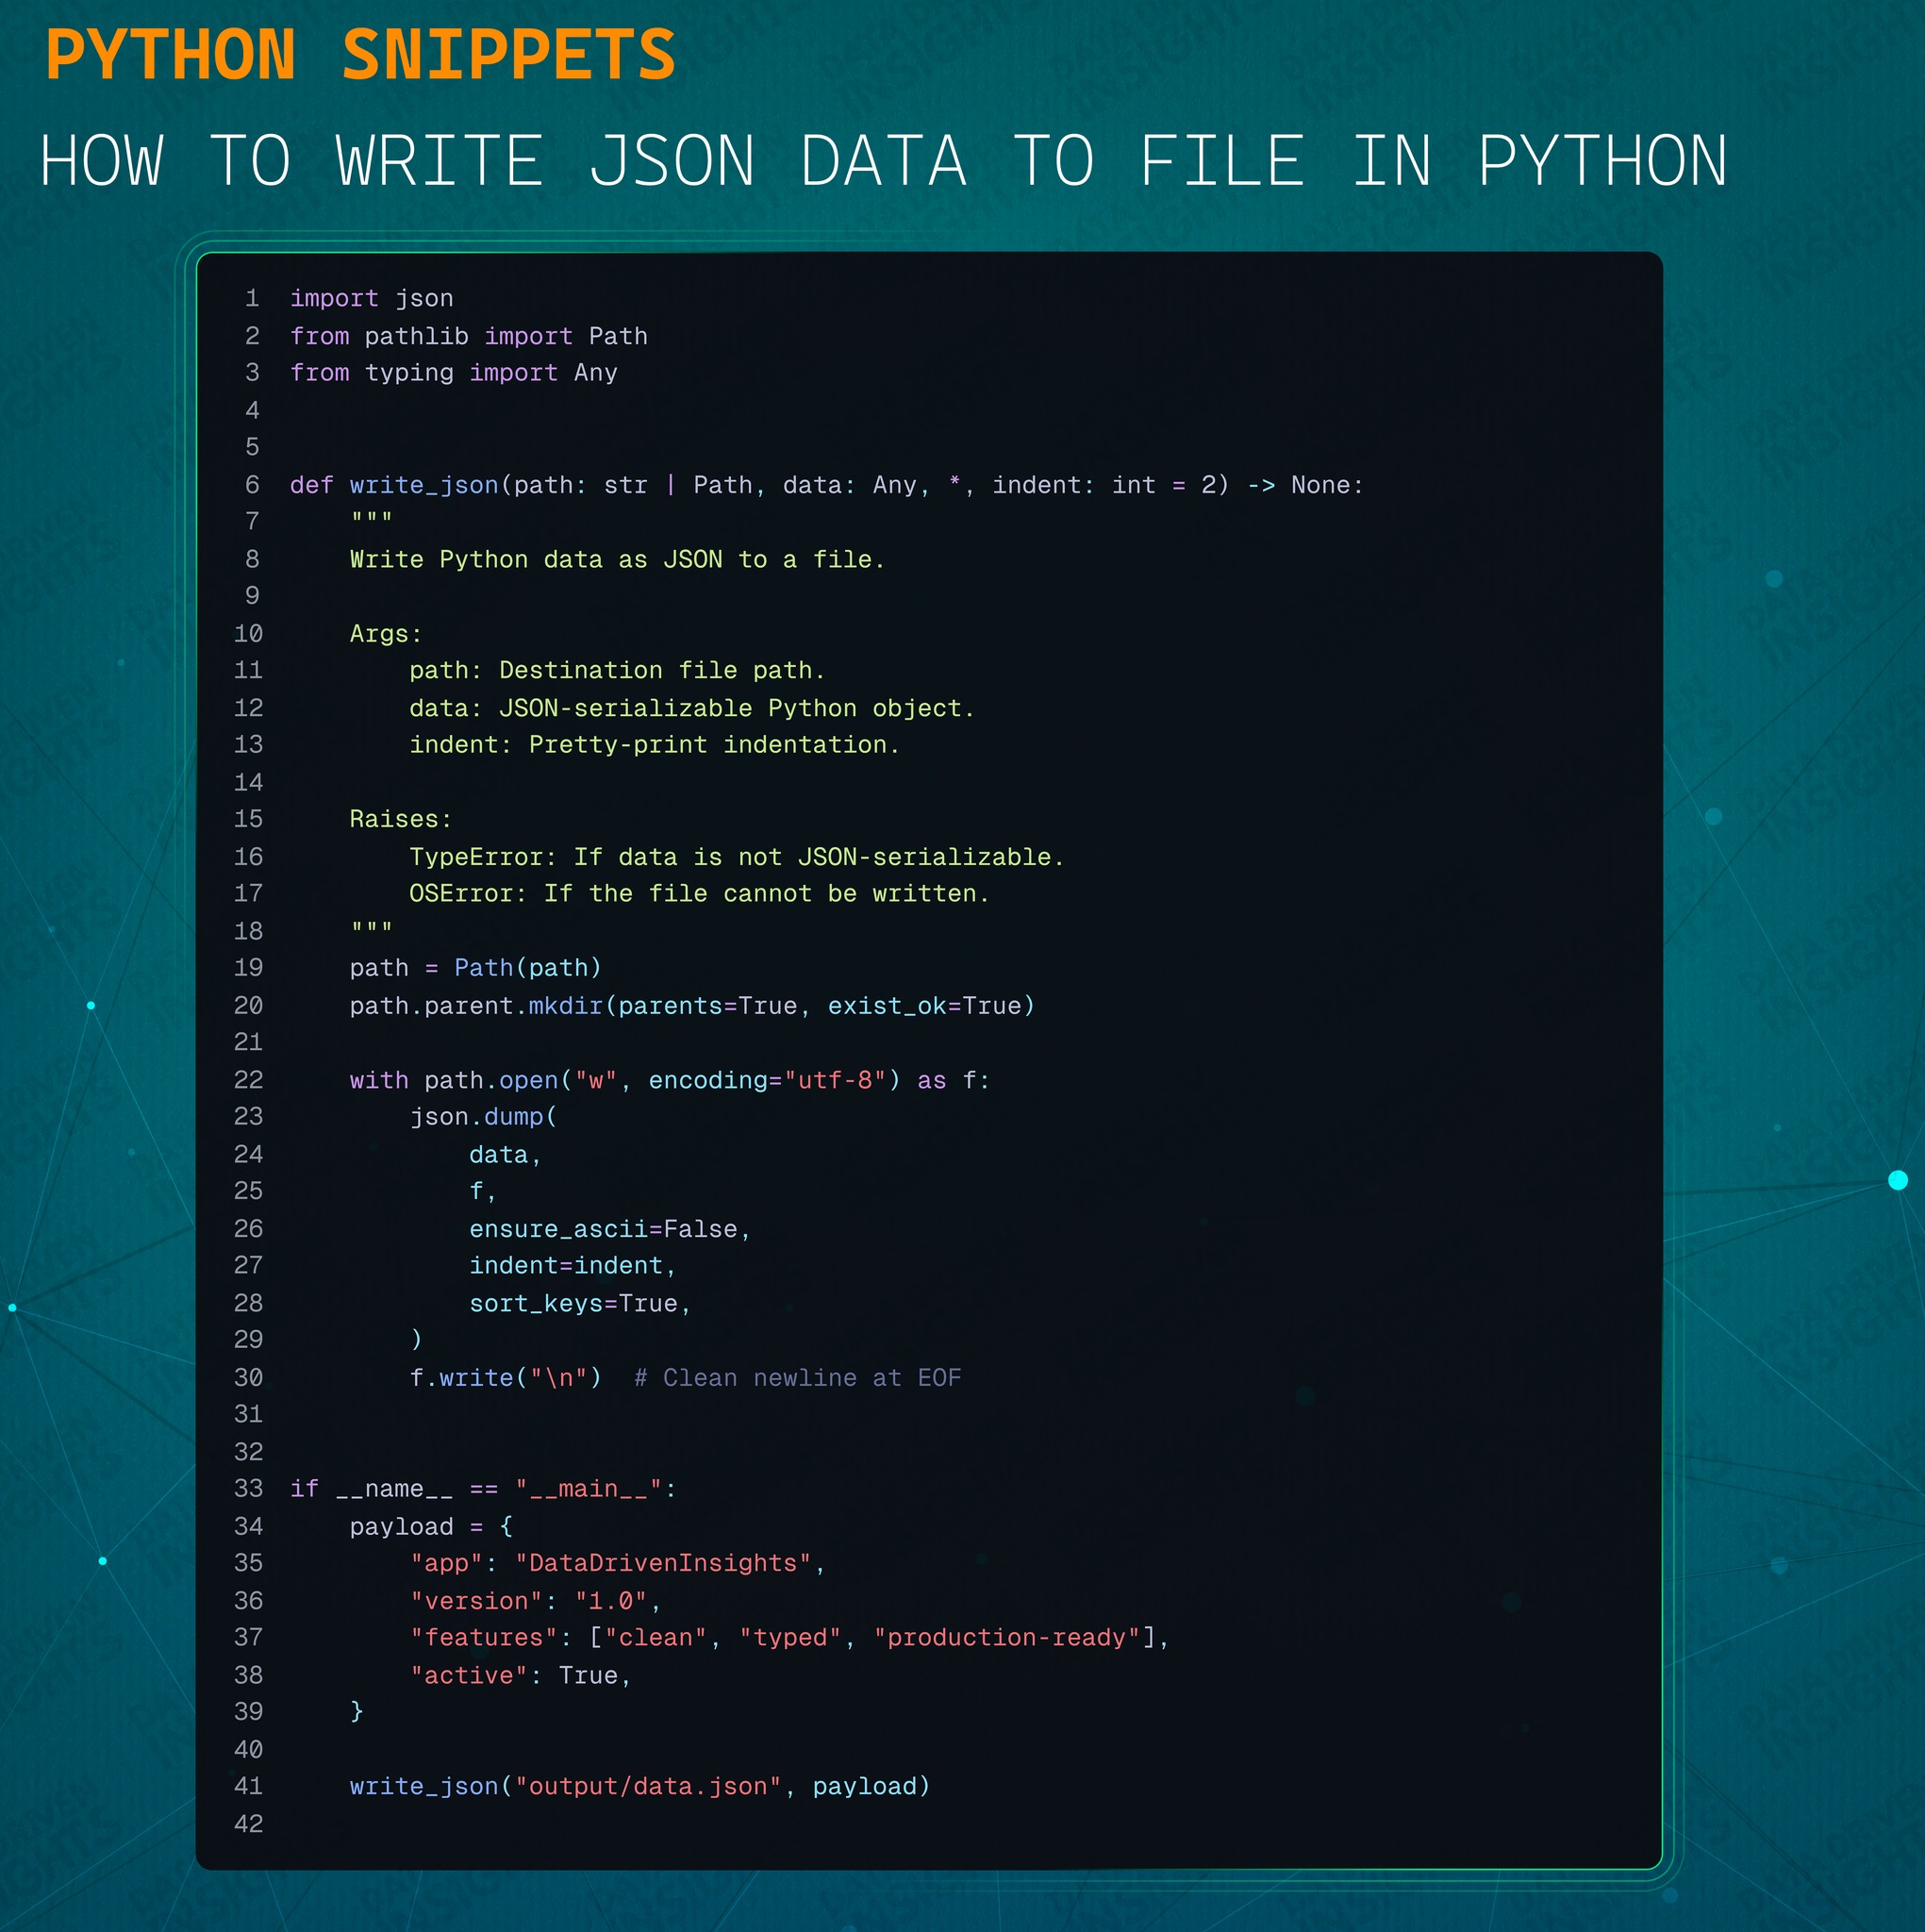
Most people learn about the json module early on and never go deeper than a basic dump. That leaves them writing brittle scripts that break whenever someone adds a special character or tries to store a custom object. The module itself is straightforward, but the things that trip people up are rarely documented clearly. Here is the basic pattern you will use every single time: That works fine until it does not. The indent parameter controls readability. Four spaces is standard. Two spaces saves disk space but makes large files harder to scan. Pick one and stick with it across your project, otherwise your diffs will look like garbage.
I ran into a real problem last year where a script was generating JSON files that looked perfectly valid in the editor, but downstream parsers were choking. The issue turned out to be ensure_ascii=True by default. My data contained emoji and non-Latin characters, and the library was escaping everything to unicode sequences. The output was technically correct JSON, but it made the files three times larger and unreadable for anyone who wanted to inspect them by hand. I switched to ensure_ascii=False and the problem went away immediately. There are defaults you should consciously override every time. encode is another one. If you are working with non-ASCII text in Python 3, leaving the default can produce unexpected results depending on how the string was originally created. Setting it to UTF-8 explicitly removes any ambiguity.
Common Pitfalls
One thing beginners consistently miss is that json.dump does not validate your data types upfront. It will happily start writing to a file, then raise a TypeError halfway through when it hits something it cannot serialize. If you are working with large datasets, this means you have wasted time generating the entire structure only to watch it fail at the end. A practical workaround is to run json.dumps on a smaller sample first, or wrap the dump call in a try-except block:
Get the Full Details

try:
    with open("output.json", "w") as f:
        json.dump(data, f, indent=4, ensure_ascii=False)
except TypeError as e:
    print(f"Serialization failed: {e}")
Another pitfall is the sort_keys parameter. People often set it without realizing it forces alphabetical ordering on every key at every nesting level. That is fine for configs and schemas, but it can make debugging harder when you want to see data in insertion order. Python 3.7+ preserves dict insertion order, and json.dump respects that unless you tell it otherwise. There is also a performance consideration that almost nobody mentions. json.dump is fast enough for most uses, but if you are processing millions of records, it becomes a bottleneck. In those cases you are better off using orjson or ujson, which are significantly faster drop-in replacements. They have slightly different APIs, so test thoroughly before swapping them into production code.
Reading Back What You Wrote
Saving the file is only half the equation. Loading it back requires json.load with the same file handle pattern: The decoder automatically handles type conversion. Numbers become ints or floats. Boolean values become Python bools. Null values become None. This is generally reliable, but there is one edge case that catches people out. Very large integers that exceed 2^53 can lose precision during deserialization because JSON itself does not distinguish between integer and float types at that scale. If you are working with financial data or IDs larger than that threshold, store them as strings instead. A real-world example of this cost me about two hours of debugging on a project last year. The data looked correct when printed, but arithmetic operations were producing wrong results downstream. Tracking it down revealed that the JSON encoder had silently converted a large integer to a float, and the loss of precision happened during the read cycle, not the write cycle. Storing those values as strings in the original dict fixed everything.
When JSON Is Not The Right Choice
JSON is not a universal solution. It has no support for binary data without base64 encoding, which inflates file size by roughly thirty-three percent. If your application deals with images, audio, or serialized protocol buffers, JSON adds unnecessary overhead. Use it for configuration, API payloads, and text-heavy data. For everything else, consider MessagePack or Protocol Buffers depending on your constraints. There is also the schema problem. JSON has no built-in schema validation. You can store anything in a JSON file, which means a typo in a key name will not raise an error. It will just create a new unexpected key in your dictionary. I have seen this cause production bugs where a developer misspelled a configuration field and the application silently fell back to defaults without any warning. Pairing your JSON workflows with a validation library like Pydantic or jsonschema catches these issues early and prevents them from reaching the point where they cause damage. The json module itself is part of the standard library, so no installation is required. You can start using it immediately in any Python environment. For most projects, the built-in module is perfectly adequate. The goal is to understand its limitations so you do not run into the problems I just described.