Getting IBM Cloud Pak for Data Running Without Losing Your Mind
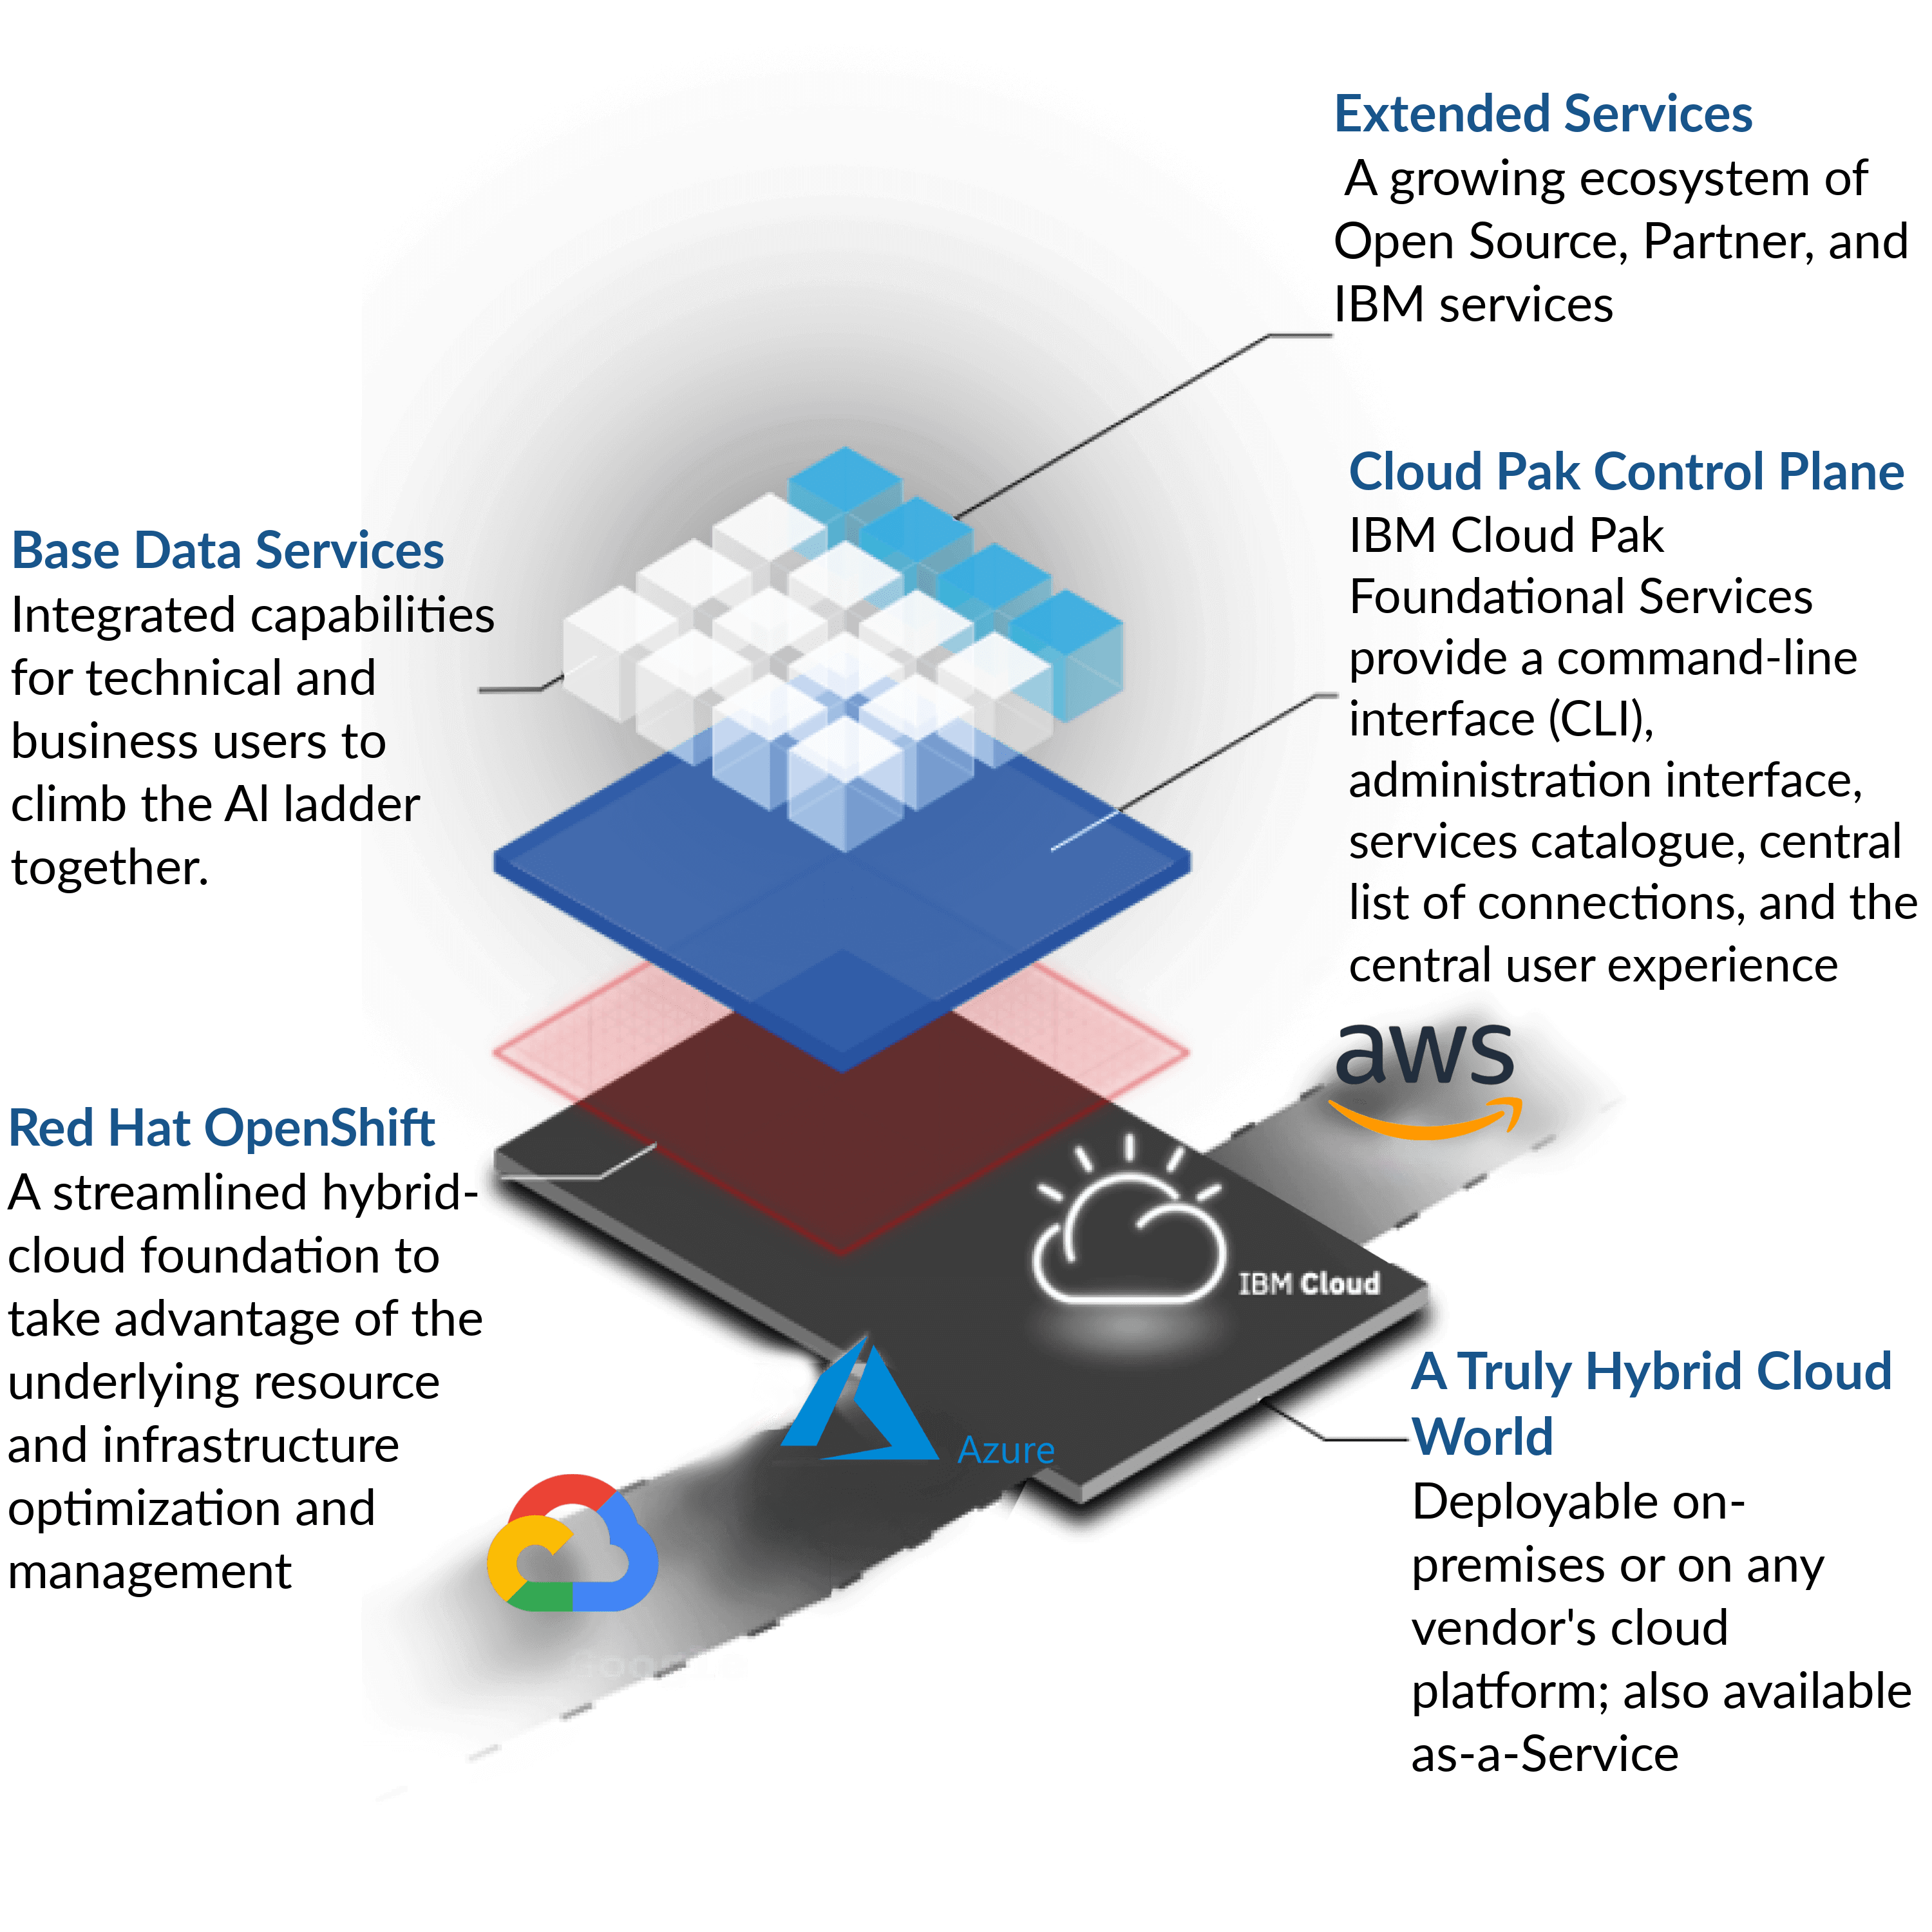
Cloud Pak for Data is an IBM containerized platform that bundles data ingestion, transformation, governance, and machine learning tools into a single Kubernetes environment. It sits on top of OpenShift and packages tools like IBM Data Stage, Db2, Watson Studio, and information governance into pre-configured containers you deploy as services. The platform is meant to replace juggling a dozen disconnected point solutions with something you can operate from one web interface. Here is what the deployment actually looks like on a fresh OpenShift cluster. You install the IBM Cloud Pak foundational services first, then install the Cloud Pak for Data operator through the OperatorHub. After that, you provision a secrets manager, create a namespace, and install the Cloud Pak for Data instance. The installer handles pulling container images from the IBM Entitled Registry, provisioning persistent volumes, and bootstrapping the internal services. It typically takes between 30 and 90 minutes depending on cluster size and network throughput, but the initial bootstrap is the part where most installations stall because of misconfigured image pull secrets or insufficient persistent storage classes.
Unleash The Power Of Aipowered Data Management With Ibm Cloud Pak For Data Start Your Free Trial Today
The platform does offer a free trial environment through IBM's website, though the trial has restrictions compared to a full on-premises deployment. The trial version runs in IBM's cloud infrastructure and gives you access to the main services with limited compute and storage. If you want to evaluate it yourself, the entry point is ibm.com/cloudpak for data. There is no download link for the trial since it is a managed service, but the full product can be pulled from your organization's entitlement registry once you have a valid license key. One thing nobody tells you about the trial is that it limits certain enterprise features like LDAP integration and advanced governance workflows. You will get a functional experience of the data orchestration and Watson Studio parts, but if you are testing this for an actual production migration, the trial will not fully represent what your implementation looks like. I ran a proof of concept through the trial and had to rebuild the governance rules separately when we moved to our own OpenShift cluster because the configuration did not export cleanly between environments. The AI capabilities in this platform come primarily through Watson Orchestrate and the integrated machine learning pipelines in Watson Studio. Watson Orchestrate connects data workflows to large language model actions, allowing you to trigger AI processing inside data pipelines without writing custom code. The AI-assisted data profiling feature automatically analyzes your datasets and suggests column-level classifications, quality rules, and anomaly detection thresholds. This is genuinely useful during the initial data discovery phase, but it is not a substitute for manual review because the automated classifications often mislabel columns in complex schemas.
I spent about two weeks troubleshooting why the AI profiler kept flagging standard financial reporting columns as sensitive data when they were clearly not. The issue came down to how the training data for the classifier interacted with our particular column naming conventions. I resolved it by creating custom taxonomy rules in the governance dashboard and overriding the automated classifications, which took roughly 40 minutes once I figured out where the override controls lived. The platform documentation does not make the override workflow obvious, so expect some time spent poking around the UI to find the right settings.
How the Platform Actually Works Under the Hood
Each service in Cloud Pak for Data runs as its own container pod within the same namespace. The services communicate through internal API endpoints and share a common identity layer managed by the underlying foundational services. This means you do not need to configure separate authentication for each tool, but it also means every service depends on the health of the foundational layer. When the secrets manager or IAM component experiences latency, all the services slow down together. I have seen this happen during peak usage windows when multiple teams ran large data flows simultaneously, and the entire platform became sluggish for about twenty minutes until the load decreased.Get the Full Details
Data pipelines in this platform use a drag-and-drop interface in Data Stage or Watson Orchestrate to define ETL and data movement logic. The pipelines run on scheduled triggers or can be triggered manually through the API. Each pipeline execution creates its own containerized runtime environment, which adds overhead but ensures consistent behavior across environments. A typical data transformation pipeline that moves data from a PostgreSQL database, applies column mappings, enriches records through a REST API call, and loads the result into a warehouse table takes roughly eight to fifteen minutes to execute depending on dataset size and the number of enrichment calls. This is slower than a bare-metal Spark job running the same logic, but the tradeoff is the governance tracking and audit trail that comes automatically.
Where This Platform Falls Short
The honest problems with Cloud Pak for Data start with infrastructure requirements. A production deployment needs a properly sized OpenShift cluster with at least three worker nodes, each with a minimum of 16 CPU cores and 64 gigabytes of RAM. Storage is the bigger issue. The platform requires persistent volumes for every major service, and those volumes need to be provisioned with the right storage class before installation or the installer will fail partway through. I once watched an installation stall at the 70 percent mark because the storage operator was misconfigured, and by that point I had already spent two hours debugging network connectivity issues that turned out to be irrelevant. The fix was restarting the installer after correcting the storage class, which added another hour to the timeline.Another limitation is the learning curve for teams that are not already familiar with Kubernetes and OpenShift concepts. The platform abstracts a lot of complexity away from the average data analyst, but the deployment and maintenance side requires someone who understands container orchestration, persistent volume management, and RBAC policies. If your team does not have that expertise, you will either need to hire for it or rely heavily on IBM services, which increases cost significantly. I worked with a team that attempted a self-managed deployment without Kubernetes experience and ended up spending six weeks just getting past the initial setup phase, which included multiple failed installations and a lot of time reading documentation that did not match their specific OpenShift version. The AI-powered features, while functional, are not as sophisticated as standalone AI tools for data management. Watson Orchestrate is useful for simple automation and connecting disparate data sources, but it lacks the fine-grained control that dedicated orchestration tools like Apache Airflow provide for complex workflow dependencies. The machine learning pipeline builder in Watson Studio is decent for quick model development, but teams doing serious model operations will find themselves hitting limitations with custom container support, model versioning, and deployment automation. I moved our most complex ML workflows to a separate Kubernetes cluster with dedicated MLOps tooling because Cloud Pak for Data could not handle the model retraining frequency we needed without constant resource contention. Cost is another factor that gets underestimated. The licensing model for Cloud Pak for Data is based on processor value units, and the total cost includes both the software license and the infrastructure required to run it. For a mid-size deployment with five to ten concurrent users, you are looking at significant infrastructure investment on top of the software cost. The free trial does not reflect this reality because it runs on IBM's infrastructure with no cost to you during the evaluation period. When you translate the trial experience to your own environment, the budget impact is much more immediate and tangible.
If your organization is already invested in the IBM ecosystem and uses OpenShift extensively, Cloud Pak for Data makes sense as a consolidated platform. If you are evaluating it from a greenfield position with a heterogeneous technology stack, it might be worth considering lighter alternatives like open-source tools on Kubernetes, or even a managed cloud data platform, before committing to the full IBM implementation. The platform works well when it fits your existing infrastructure and team skills, but it is not a universal solution for every data management challenge.