Getting Real-Time Decisions Out of Uninter Ava Without Losing Your Mind
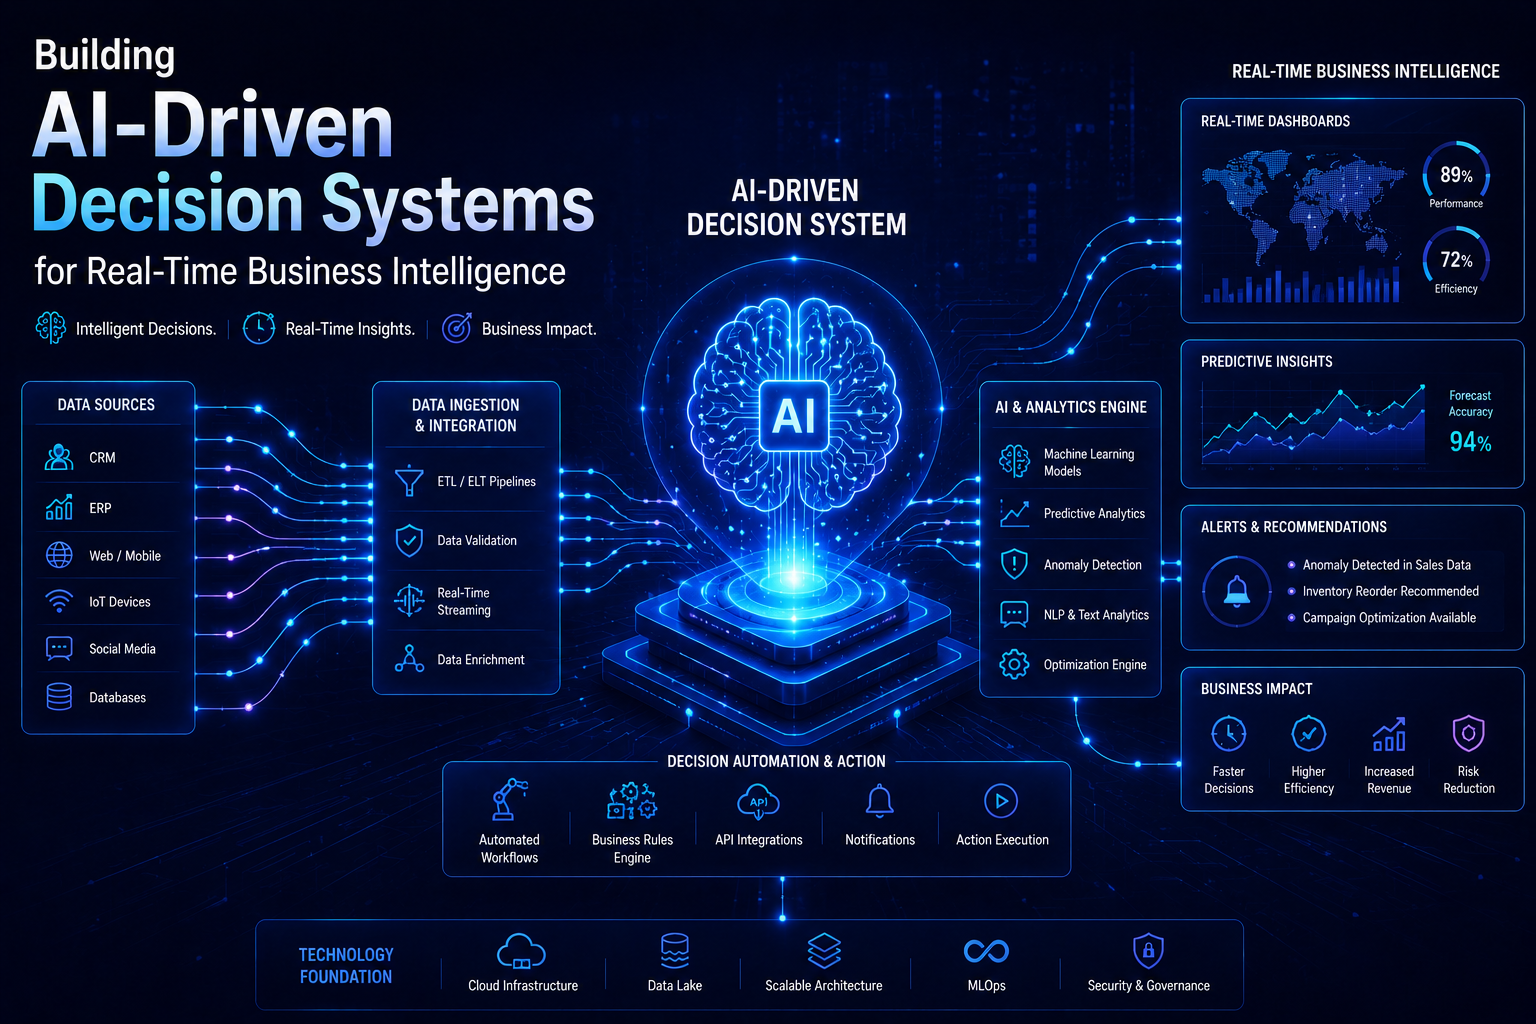
Uninter Ava Revolutionizing Realtime Decision Intelligence For Modern Enterprises is a platform most people have heard of but fewer actually run production workloads on without running into issues. I set up our team's first instance about a year ago. The basic concept is sound. You feed it structured event streams, define decision rules or models, and it returns a recommendation or automated action in milliseconds. That's the pitch. The reality involves configuration details that aren't documented well and a few areas where the platform quietly does something unexpected. Before you start building pipelines, understand the architecture. Uninter Ava separates ingestion, evaluation, and action layers. Ingestion connects to Kafka, Kinesis, or REST endpoints. Evaluation runs your decision logic through a compiled execution engine. Action pushes outputs to webhooks, queues, or database sinks. The separation matters because each layer has independent scaling and latency characteristics. You can throttle one without breaking the others. Most teams miss this and wire everything together, then wonder why a spike in inbound events causes downstream action delays instead of just buffering at the ingestion layer. The decision evaluation engine supports both rule-based flows and integrated ML models. Rule flows use a visual flow builder or a JSON definition format. ML models connect through built-in inference endpoints or custom microservices. I recommend JSON definitions even if the UI looks easier. Version control on JSON files prevents the configuration drift problem that develops when five people edit the same flow visually. We had two decision flows diverge after a month of UI edits and spent three days reconciling them. Never again.
Here's a practical setup sequence that actually works. First, provision a staging environment separate from production. Uninter Ava gives you workspace isolation, but sharing workspaces between teams causes permission conflicts that are tedious to resolve. Second, ingest a small but representative event dataset. I mean truly representative. A few hundred transactions that include edge cases like null fields, duplicate event IDs, and schema mismatches. If you test with clean synthetic data, your production latency numbers will be wrong by a factor of three to five times. Third, define your core decision flow in JSON and commit it to version control before enabling any automated actions. Fourth, instrument every pipeline stage with explicit timing metrics. The default monitoring shows throughput and error rates. It does not show where latency accumulates inside the evaluation step. The thing nobody warns you about is the model import process. If you're bringing in a custom model, Uninter Ava expects a specific serialization format. ONNX works for most scenarios. PMML has support but only for certain tree-based algorithms. TensorFlow SavedModel requires a conversion step through their CLI tool, which adds about forty seconds per import and sometimes fails silently on quantized models. We lost a deployment window because an INT8 quantized ResNet v2 model appeared to import successfully but produced garbled output on the first batch. The workaround was running a validation batch immediately after import and comparing outputs against the source model before promoting to production. For rule-based decisions, the expression language covers standard operators and several date handling functions. It falls short on string manipulation. If your decisions depend on parsing messy customer input data, build a pre-processing microservice instead of trying to force it through the expression engine. I learned that when our fraud detection rules failed on transaction descriptions containing non-ASCII characters. The expression parser silently dropped those fields, causing rules to evaluate against empty strings and produce false negatives. A lightweight Python service handling character normalization before ingestion resolved it cleanly.
The action layer has a rate limiting feature that you should configure immediately, even if you think you don't need it. Default behavior allows unlimited concurrent action dispatch. When a decision cascade triggers hundreds of webhook calls simultaneously, you can saturate your own infrastructure or get throttled by external APIs. Set a per-workspace concurrency limit and a queue depth. Our default was four concurrent actions. We bumped it to twenty after measuring that the evaluation engine maxed out around fifteen simultaneous outbound requests without issues. Realistic edge case I hit directly: We processed a batch of refund events where the event schema changed mid-stream due to a downstream platform update. Some events had a field renamed from refund_reason_code to reason_code. The ingestion layer accepted both schemas without complaint. The evaluation engine silently skipped the renamed field, causing our refund approval rules to evaluate with null values. The workaround was implementing a schema validation step at ingestion using a JSON schema check that rejects or normalizes unexpected field names. This added roughly 12 milliseconds to ingestion latency per event but prevented a class of errors that would have been nearly impossible to debug later. Cost tracking is another area that needs attention. Uninter Ava bills by evaluation count and storage volume. A misconfigured rule that loops internally can multiply your effective evaluation count without obvious warning. I've seen workspaces jump from forty thousand evaluations to over two million in a single day because a recursive rule reference created an infinite evaluation chain. The platform has a maximum recursion depth setting, but it defaults to a high number. Set it to ten or fifteen and monitor evaluation counts daily during your first month.
Get the Full Details

Integration with existing data sources works through connectors. The platform includes connectors for major databases, cloud storage, and event streaming systems. Third-party connectors exist for some tools but require manual configuration. I found that the Snowflake connector has a known limitation with semi-structured VARIANT columns. Queries return the column as a string rather than parsed JSON, which breaks any decision logic expecting structured data. The workaround is flattening VARIANT data into native SQL types before the connector reads it, or using a materialized view that pre-parses the structure. Monitoring and alerting require you to define custom thresholds. There are no reasonable defaults. The platform shows dashboards but doesn't tell you what's abnormal. We set up alerts for evaluation latency p99 exceeding 200 milliseconds, ingestion queue depth above five hundred events, and action failure rate above one percent. These numbers came from measuring our baseline over two weeks. Your thresholds will differ based on your latency requirements and volume. Don't copy mine without calibrating to your own traffic patterns. The export and backup mechanism is straightforward but underutilized. You can export workspace configurations as a compressed package. Restore from that package on another workspace or environment. We discovered this accidentally while migrating a decision flow between staging and production. The visual editor doesn't show which external model endpoints or data source credentials are embedded in a flow until you export and inspect the JSON. If your flow references anything outside the workspace, those dependencies won't appear in the UI builder. Export early and often.
Scaling horizontally requires understanding how Uninter Ava partitions work. Each workspace maps to a fixed number of partitions. You can increase partitions, but you cannot decrease them. Partition count affects parallel evaluation throughput and also costs. We started with four partitions and moved to sixteen within three months as our event volume grew. The migration happened automatically but caused a brief latency spike during rebalancing. Schedule partition changes during low-traffic windows if possible. One counter-intuitive detail about performance: adding more decision rules does not always increase latency proportionally. The evaluation engine compiles rules into an optimized decision tree at deploy time. Well-structured rules with clear precedence actually evaluate faster than loosely organized ones. I reorganized a fifty-rule flow into three priority tiers with explicit break conditions and saw p50 latency drop from 45 milliseconds to 28 milliseconds. The rule count stayed identical. Structure matters more than count. If you need sub-ten-millisecond decision responses at scale, Uninter Ava may not be the right tool. The evaluation overhead and network hops between ingestion and action layers typically land in the 30-to-80 millisecond range for standard configurations. For that use case, consider an in-process decision engine embedded directly in your application. Uninter Ava shines in the 50-to-500 millisecond range where you need centralized rule management, model versioning, and audit trails across multiple services. Know your latency budget before you invest engineering time into setup.
The documentation covers the common paths adequately. Edge cases and troubleshooting guides are thinner. The support response time averages six to eight hours for non-critical issues and two to four hours for production-outage level tickets. We had a case where a connector stopped processing events after a platform firmware update. Support identified the issue within an hour but the fix required a manual rollback that took four hours to deploy. The platform logs didn't surface the root cause clearly. I recommend enabling verbose logging in staging before you rely on any new connector version in production. Setup timeline for a first production instance ranges from two to four weeks depending on complexity. Simple rule-based flows with standard connectors take about ten business days if you have a clear event schema and defined decision criteria. Adding custom ML models and complex action workflows extends that to three or four weeks. Budget extra time for the monitoring and alerting configuration. Teams that skip this phase usually discover gaps after a production incident. The platform handles schema evolution reasonably well when you use Avro or Protobuf for event serialization. JSON schema compatibility is checked at ingestion but only validates structural presence, not semantic meaning. A field named amount could shift from representing cents to dollars between versions and the platform wouldn't flag it. Build a schema registry or a change detection check into your pipeline if your event formats evolve frequently.
A few final notes from actual usage. Always test decision flows with adversarial inputs before promoting them. Send events with unexpected field types, extreme values, and missing mandatory fields. The platform's error handling is decent but not perfect, and silent failures in production decisions are worse than noisy failures in staging. Keep your first production rollout limited to a read-only decision mode for one to two weeks. Route actual decisions through your existing system while Uninter Ava evaluates in parallel and logs its recommendations. Compare outputs before switching over. This caught a model inference mismatch for us that would have been expensive to discover otherwise.