Sample Size Basics For People Who Actually Run Studies
I spent about a week last year debugging a clinical trial analysis where the primary endpoint looked statistically significant at first glance, then completely fell apart once we accounted for the actual sample distribution across sites. The sponsor had calculated N based on an assumption of uniform enrollment. The reality was six sites with 150 patients each and two with 12. That imbalance killed the power calculation. We caught it late. It cost us three weeks and a lot of credibility with the data monitoring committee. This is one of those things that sounds straightforward in a textbook and then becomes a mess in practice. Understanding Sample Size Why Big N Vs Little N Determines The Fate Of Your Data comes down to recognizing that sample size isn't just a number you throw into a formula. It's the difference between a result that holds up and one that collapses under scrutiny.
The Mechanics Of N
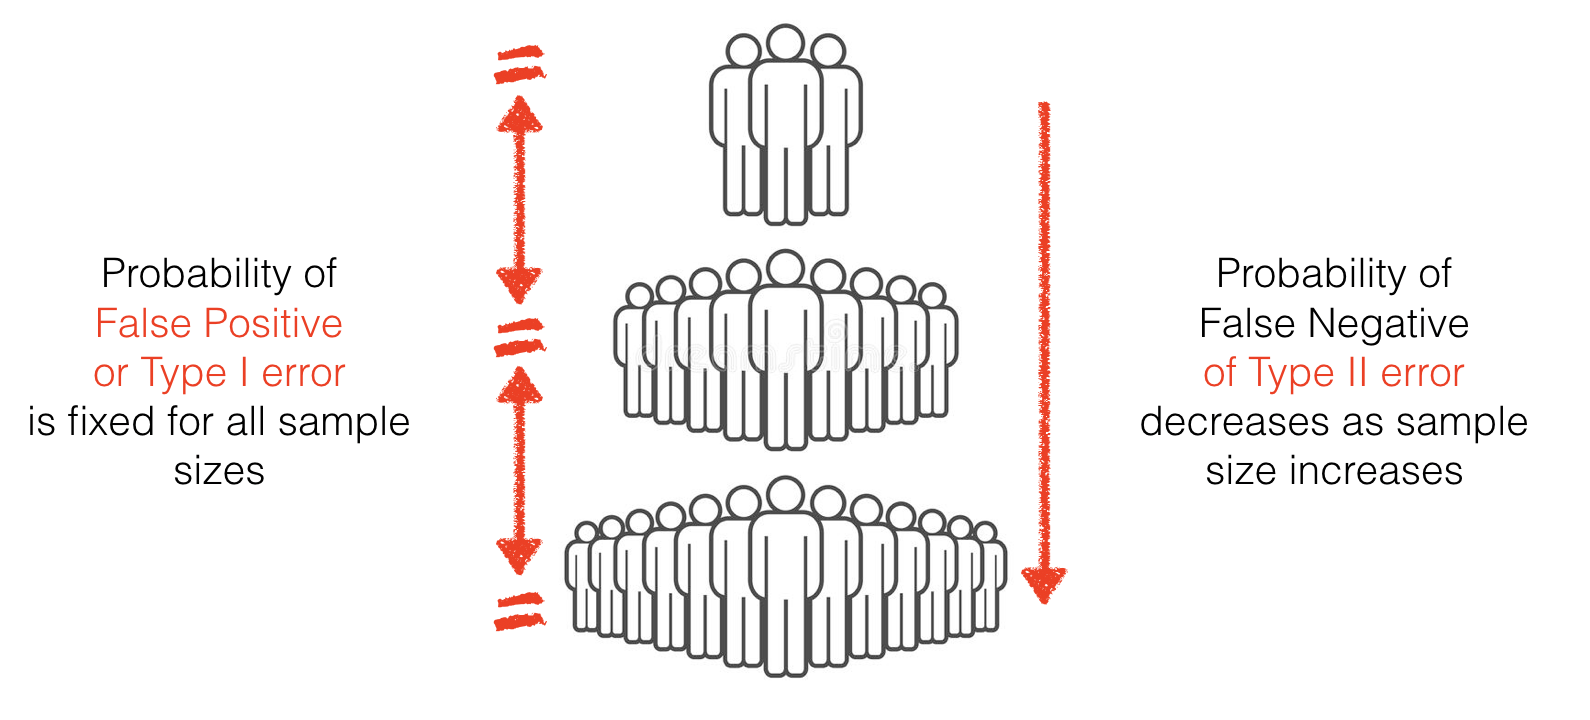
Sample size determines your statistical power, which is the probability of detecting a true effect if one actually exists. Power below 80 percent is considered inadequate in most regulated industries. Most beginners miss that power depends on effect size, variance, significance threshold, and sample size all working together. Change any one of them and the whole calculation shifts. When N is too small, you risk a type II error, meaning you fail to detect a real difference. That is the most common failure mode I see. A pharmaceutical company ran a Phase II study with 60 patients per arm for a rare oncology indication. The observed effect size was clinically meaningful, but the confidence interval spanned from benefit to harm. The result was technically not significant. They did not stop the program, but they also could not proceed with the Phase III without renegotiating the protocol and increasing N substantially.
Big N Isn't Automatically Better
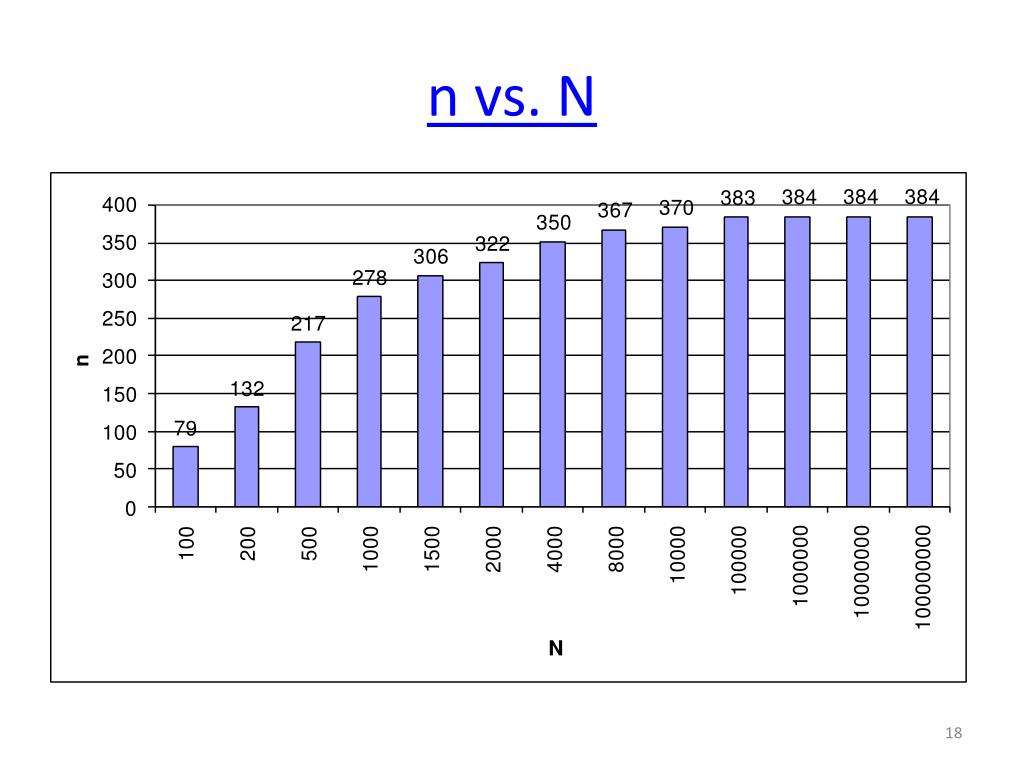
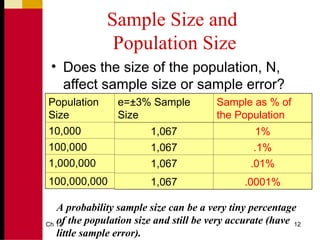
There is a practical reason not to simply recruit as many people as possible. Larger samples increase the precision of your estimate, but precision is not the same as importance. With enough subjects, even trivial differences become statistically significant. I reviewed a digital health intervention trial with nearly 4,000 participants where the treatment group improved their daily step count by an average of 23 steps per day compared to the control group. The p-value was less than 0.01. Clinically, twenty three steps is essentially nothing. The study was overpowered for the question it was trying to answer. This overpowered scenario is more common than people admit, particularly in web analytics and A/B testing. Running an experiment until you hit statistical significance with millions of visitors will almost always produce a significant result for minor friction changes that have no meaningful business impact. The fix is to set a minimum detectable effect size before you launch the test and use that to calculate your required N, not the other way around.
Get the Full Details
How I Handle Uneven Distributions In Practice
My usual approach when dealing with clustered or stratified data is to calculate the design effect first. If your sample is clustered, like patients within hospitals or users within regions, the effective sample size drops below the raw count. The formula is 1 plus the average cluster size minus one times the intracluster correlation coefficient. An ICC of 0.05 with clusters averaging 30 units reduces your effective N by roughly a third. I adjust the target N upward to compensate before recruitment begins rather than trying to retrofit the analysis afterward. I also use simulation-based power calculations instead of relying purely on closed-form formulas whenever the design deviates from standard assumptions. Closed-form methods assume normality and equal variance, which rarely hold in real data. I wrote a small Python script that generates synthetic datasets matching the observed variance structure, runs the intended analysis on each, and estimates power empirically. It takes about ten minutes to set up and gives a more realistic answer than G*Power for complex designs.
Common Mistakes That Break Your Study
Post-hoc power analysis is one of the biggest errors I encounter. Computing power after the study is complete using the observed effect size is circular and produces misleading numbers. If your result was not significant, post-hoc power will always be low regardless of whether the study was adequately designed. Report confidence intervals instead. They communicate the same information without the mathematical redundancy. Another mistake is ignoring attrition in the initial calculation. Dropout rates in longitudinal studies regularly range from fifteen to thirty percent depending on the population. If your calculated N is 200 per arm and you expect twenty percent dropout, you need to enroll 250 per arm to retain the planned effective sample size. I build attrition into the enrollment target from the start and monitor it against a predefined range. If dropout exceeds expectations mid-study, I escalate early rather than waiting until the end to discover underpowering.
When Small N Can Still Work
Small sample sizes are acceptable in certain contexts. Rare disease trials, pilot studies, and exploratory research often operate with limited N by necessity. The key is to frame the question appropriately and use methods designed for small samples. Bayesian approaches with informative priors can extract more signal from limited data than frequentist methods. Exact tests like Fisher's exact test or permutation tests avoid the asymptotic approximations that break down at low N. I worked on a quality improvement project in a ICU with only eighteen patients over six months. The sample was too small for traditional hypothesis testing, so we used a control chart approach with Shewhart limits based on the observed variance. The analysis was descriptive but defensible, and the hospital infection prevention team used the results to justify a staffing change that reduced central line infections by forty percent over the following year. The lesson was not that small N is useless. It is that you need the right analytical framework for the constraint you are operating under.
Calculating N Without Guesswork
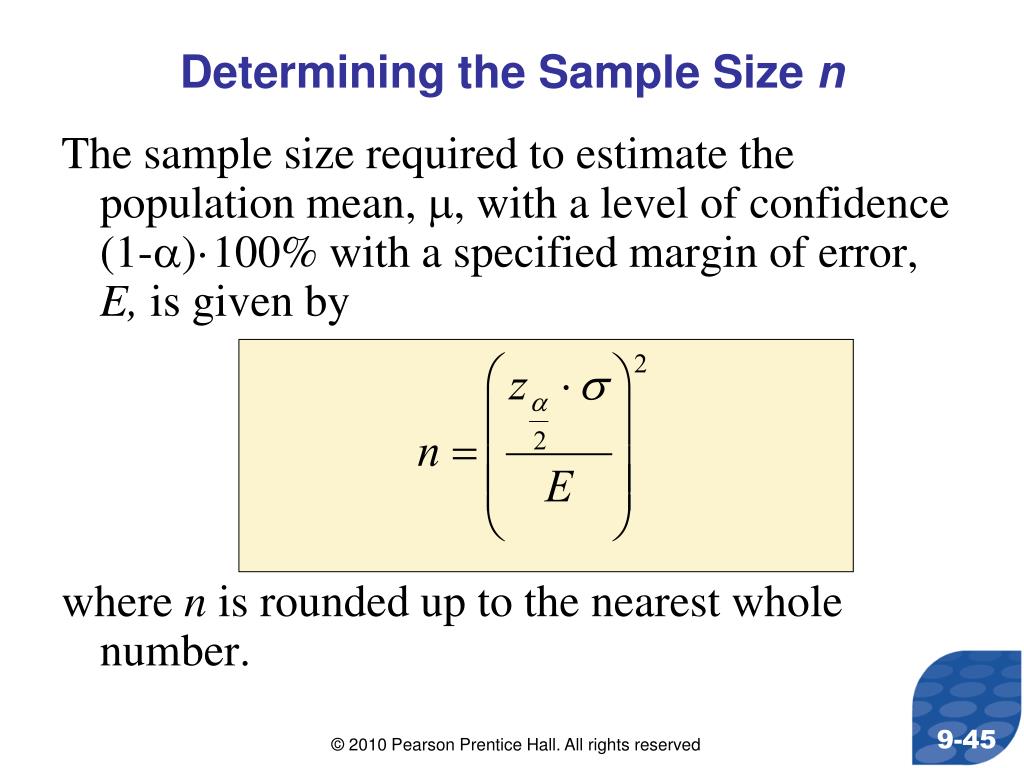
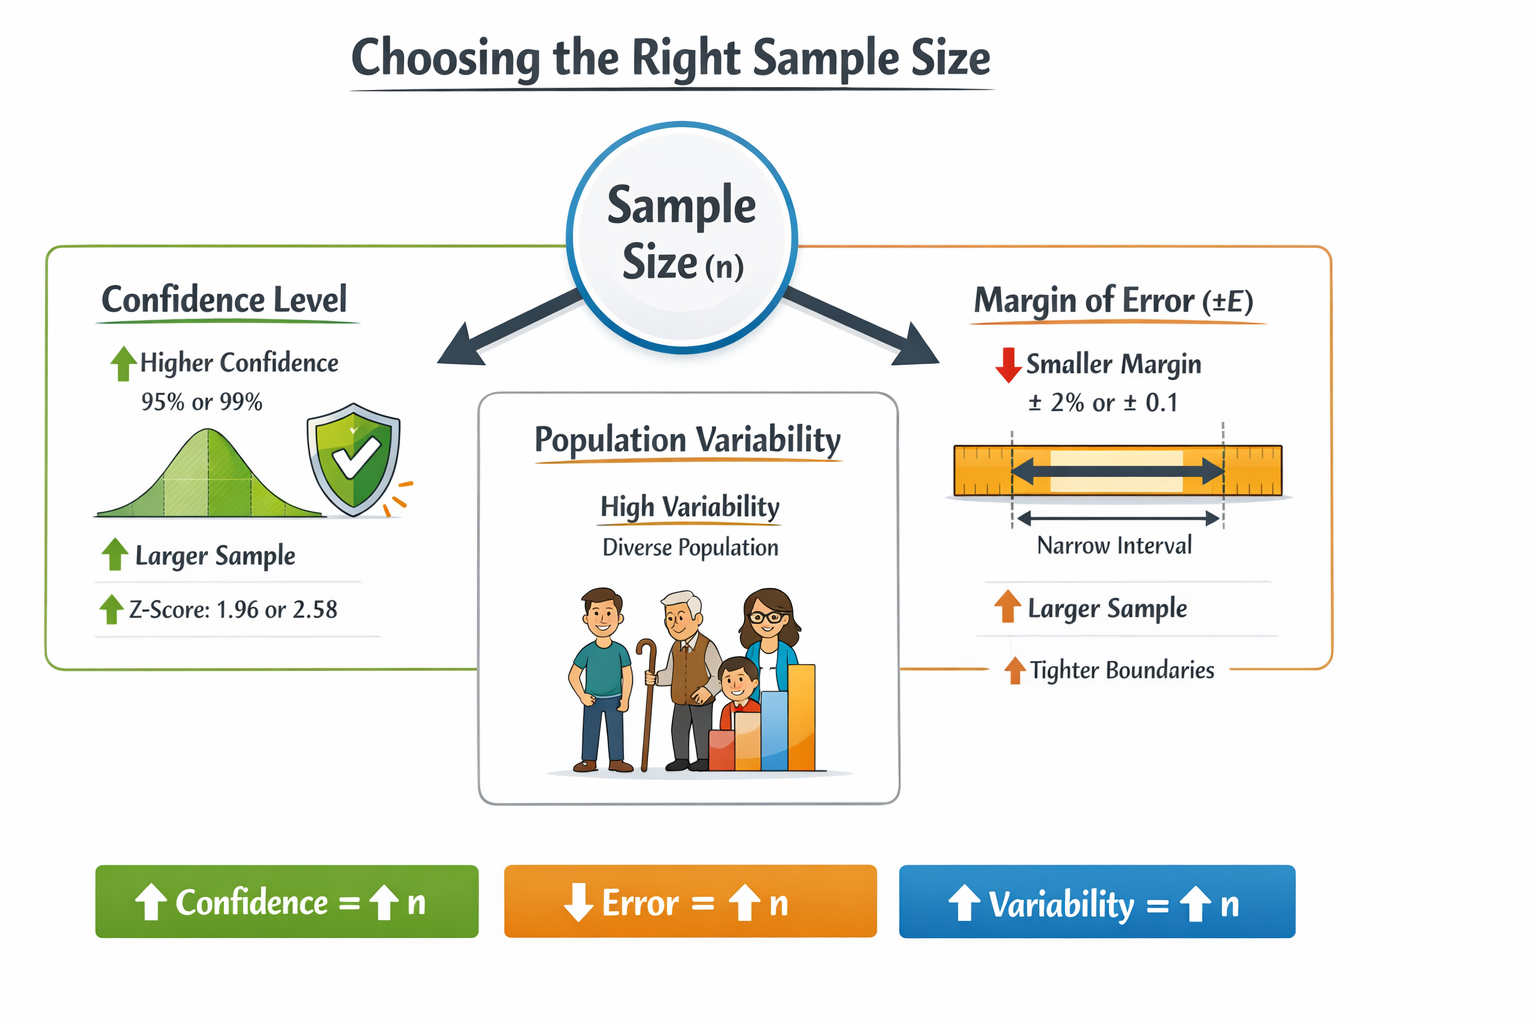
The standard formula for comparing two means is derived from the normal approximation. You need the significance level, usually 0.05 two-sided, the desired power, usually 0.80, the expected difference between groups, and the pooled standard deviation. Plug those into a calculator and you get a per-group sample size. For proportions, the formula is similar but uses the binomial variance structure. For survival analysis, the required number of events, not patients, drives the calculation. If your study expects a median survival of twenty four months in the control arm and eighteen months in the treatment arm with a one-year follow-up, you may need significantly more patients than the event-based formula alone suggests because not everyone will experience the endpoint during the observation window. I always calculate both the event requirement and the patient enrollment requirement separately and use the larger of the two. Software options include G*Power for standard designs, PASS for comprehensive industrial applications, nQuery for regulatory submissions, and R packages like pwr and longpower for custom calculations. Excel-based calculators exist but should be treated with caution because they often omit design effects and continuity corrections that matter in real-world applications.
Bottom Line On Sample Size Decisions
Understanding Sample Size Why Big N Vs Little N Determines The Fate Of Your Data is fundamentally about matching your analytical method to your design constraints before you collect any data. A well-justified small N with appropriate methods is better than an oversized study with the wrong analytical framework. The most reliable studies are the ones where the sample size calculation is documented, assumptions are stated explicitly, and sensitivity analyses show how the conclusion changes under alternative scenarios. Without that documentation, reviewers and auditors will assume you picked a number out of thin air, and they will be right to doubt the results.