What These Terms Actually Mean
You are probably seeing these words thrown together in a job description, a sysadmin forum, or a confused interview question. They are not a single product or platform. They sit at different layers of the stack and interact with each other only indirectly. Getting clear on that is the first step. OS is the operating system. Linux, usually. It sits at the bottom and manages memory, CPU scheduling, device drivers, and file systems. Everything else here runs on top of it. Couchbase Server is a distributed NoSQL database. It stores data in memory and on disk, shards it across nodes, and speaks its own binary protocol over TCP. It does not use SCSI directly. What matters for Couchbase is how the OS and storage layer beneath it behave under load.
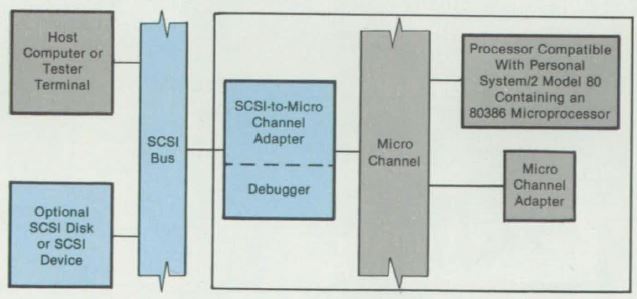
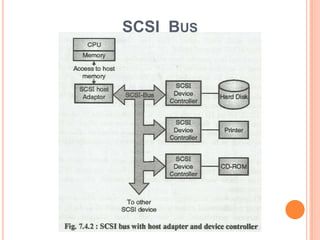
SCSI is Small Computer System Interface. It is a set of standards for how computers talk to storage devices and peripheral hardware. Think RAID controllers, tape libraries, SAN connections, and NVMe-over-Fabrics (which is actually SCSI commands wrapped in a different transport). SCSI bus is the physical or logical pathway that carries SCSI signals between the host and devices. In practice today this is rarely an actual parallel cable bus. It is usually SCSI encapsulated inside something else: SAS cables inside a server, iSCSI over Ethernet, FC (Fibre Channel) with SCSI payloads, or NVMe-oF carrying SCSI commands. The term "SCISC" does not appear in mainstream storage literature. Most likely it is either a typo for SCSI, a confusion with SCSI, or a niche term from a specific vendor's documentation. Treat it as a red flag if you see it repeated without context. If someone insists it is a real distinct acronym, ask them to show the spec. You will likely find they are mixing terms.
How They Intersect in Practice
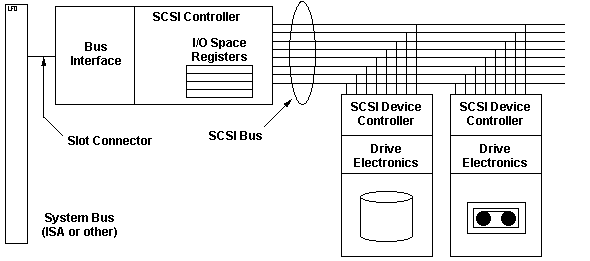
Couchbase does not have a SCSI dependency. But your data files live on block devices. Those block devices are presented to the OS through some form of SCSI abstraction. That is the connection. On Linux, every disk you see as /dev/sdX or /dev/nvmeXnY is exposed through the SCSI subsystem. The kernel's libata and sd driver stacks implement SCSI command sets for SATA and SAS drives. NVMe drives also sit behind a SCSI-compatible interface for compatibility layers. When Couchbase writes a data file, it issues POSIX syscalls. Those translate into block I/O, which eventually becomes SCSI commands going out over whatever bus connects your disk to the host. So the chain is: Couchbase writes data, OS page cache handles it, VFS pushes to block layer, SCSI stack generates commands, and those commands travel over SAS, iSCSI, FC, or another transport to the storage array.
Get the Full Details

I once spent an afternoon tracking down slow Couchbase persist-to-disk latency on a node that looked fine on paper. The server had 16 disks in a RAID HBA. The problem was the HBA firmware was sending SCSI commands with aggressive queue depth limits set to 1 per queue. Couchbase was single-threaded on that node because of how we sized it, so the storage never saw enough parallelism to saturate the array. We increased the per-queue depth to 32, disabled certain power-saving modes in the HBA, and adjusted the iorate and vm.dirty_ratio kernel parameters. Persist times dropped from around 140 ms to about 22 ms on average. Not a Couchbase setting. Not a SCSI configuration in any direct way. Just the stack working as it does.
iSCSI vs Direct-Attach: What Changes
If your Couchbase nodes are pointing at LUNs over iSCSI, you are running SCSI commands inside TCP packets. That adds overhead. Not catastrophic overhead, but real. Typical numbers I have seen: direct NVMe on a good controller will give you sub-millisecond random write latency under load. iSCSI over 10 GbE with decent offload can hit 0.3 to 0.8 ms. Over 1 GbE it is usually unacceptable for production Couchbase. Over 25 GbE it approaches SAS direct-attach performance. The counter-intuitive part is that SCSI overhead is not the main problem with iSCSI. The main problem is interrupt coalescing, CPU steal time in virtualized environments, and the fact that modern NIC offloads do not always play nicely with multiple queues. I have seen a properly tuned iSCSI setup outperform a misconfigured direct SAS connection because the HBA was doing something dumb with scatter-gather.
Common Pitfalls
People assume SCSI gives them control they do not actually have. You can tune queue depths, set read-ahead values, adjust scheduler policies, and change I/O priorities. But the actual discipline of your storage array matters more than any of that. If the backend is writing to spinning disks with a weak cache, no amount of SCSI parameter tweaking will save your Couchbase persist times. Another thing beginners miss: SCSI timeouts. When a SAN path fails over, you will see SCSI I/O errors in dmesg. Couchbase will mark vBuckets as unavailable until the paths recover. The OS will retry commands based on /sys/block/sdX/device/timeout. Setting that too low causes unnecessary bucket errors. Setting it too high means you wait seconds before failing over. Default is usually 30 seconds, which is fine for most arrays but can feel like an eternity when you are watching a couchbase-cli status report. There is also the matter of NVMe versus SCSI naming. Modern kernels prefer /dev/nvme device names. Some older scripts and storage tools still expect /dev/sd names. If you migrate a Couchbase cluster from SAS to NVMe and forget to update your mount options, udev rules, or persistent naming, things break in annoying ways. I learned this the hard way when a node came back from maintenance with its data drive renamed and Couchbase refused to start because the path was missing.
What You Can Actually Tune
For a Couchbase node on Linux, here is what tends to move the needle: You will typically encounter all of this in infrastructure reviews, performance troubleshooting, or migration planning. Someone is trying to understand why a Couchbase cluster is slow and looking at every layer from the application down to the physical bus. That is reasonable. The mistake is treating SCSI as the bottleneck without confirming it first. More often the bottleneck is memory pressure, network congestion, or query plan issues inside Couchbase itself. SCSI is usually healthy until it is catastrophically not. Check the easy stuff first. Look at iostat -x 1, check wait in top, look at Couchbase bucket stats, review network error counters, and only then dig into SCSI parameters if the evidence points there.
There is no single tool or download that ties these concepts together because they are not a product. They are layers. Understanding how they connect is mostly about knowing where to look when something performs badly and having enough context to know which layer is actually responsible.