The thing most people get wrong about ln
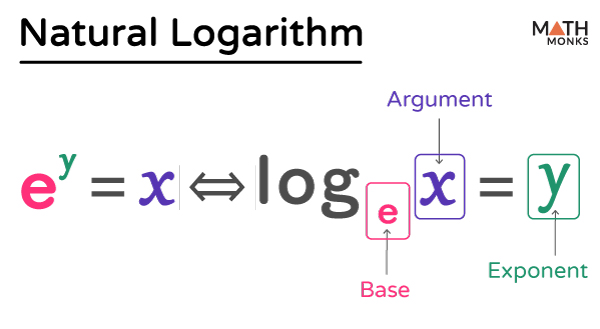
I've seen people treat the natural logarithm like it's some advanced calculus trick you only use in college. It's not. It shows up everywhere and understanding it takes about fifteen minutes if you start from the right angle. Most textbooks introduce ln by talking about Napier or Jacob Bernoulli and compound interest formulas from the 1600s. That's interesting. It won't help you actually use ln. Here's what actually matters: ln(x) is the inverse of e^x. That's it. e is approximately 2.71828, and it's the base rate of continuous growth. ln tells you how much time you need to reach a certain level of growth, given continuous compounding. If you have e raised to some power and you want to find that power, you take the natural log. If you have a natural log and you want to get back to the original number, you exponentiate with e. That reciprocal relationship is the entire operating system. Everything else is just applying it.
Understanding Ln The Natural Logarithm Explained
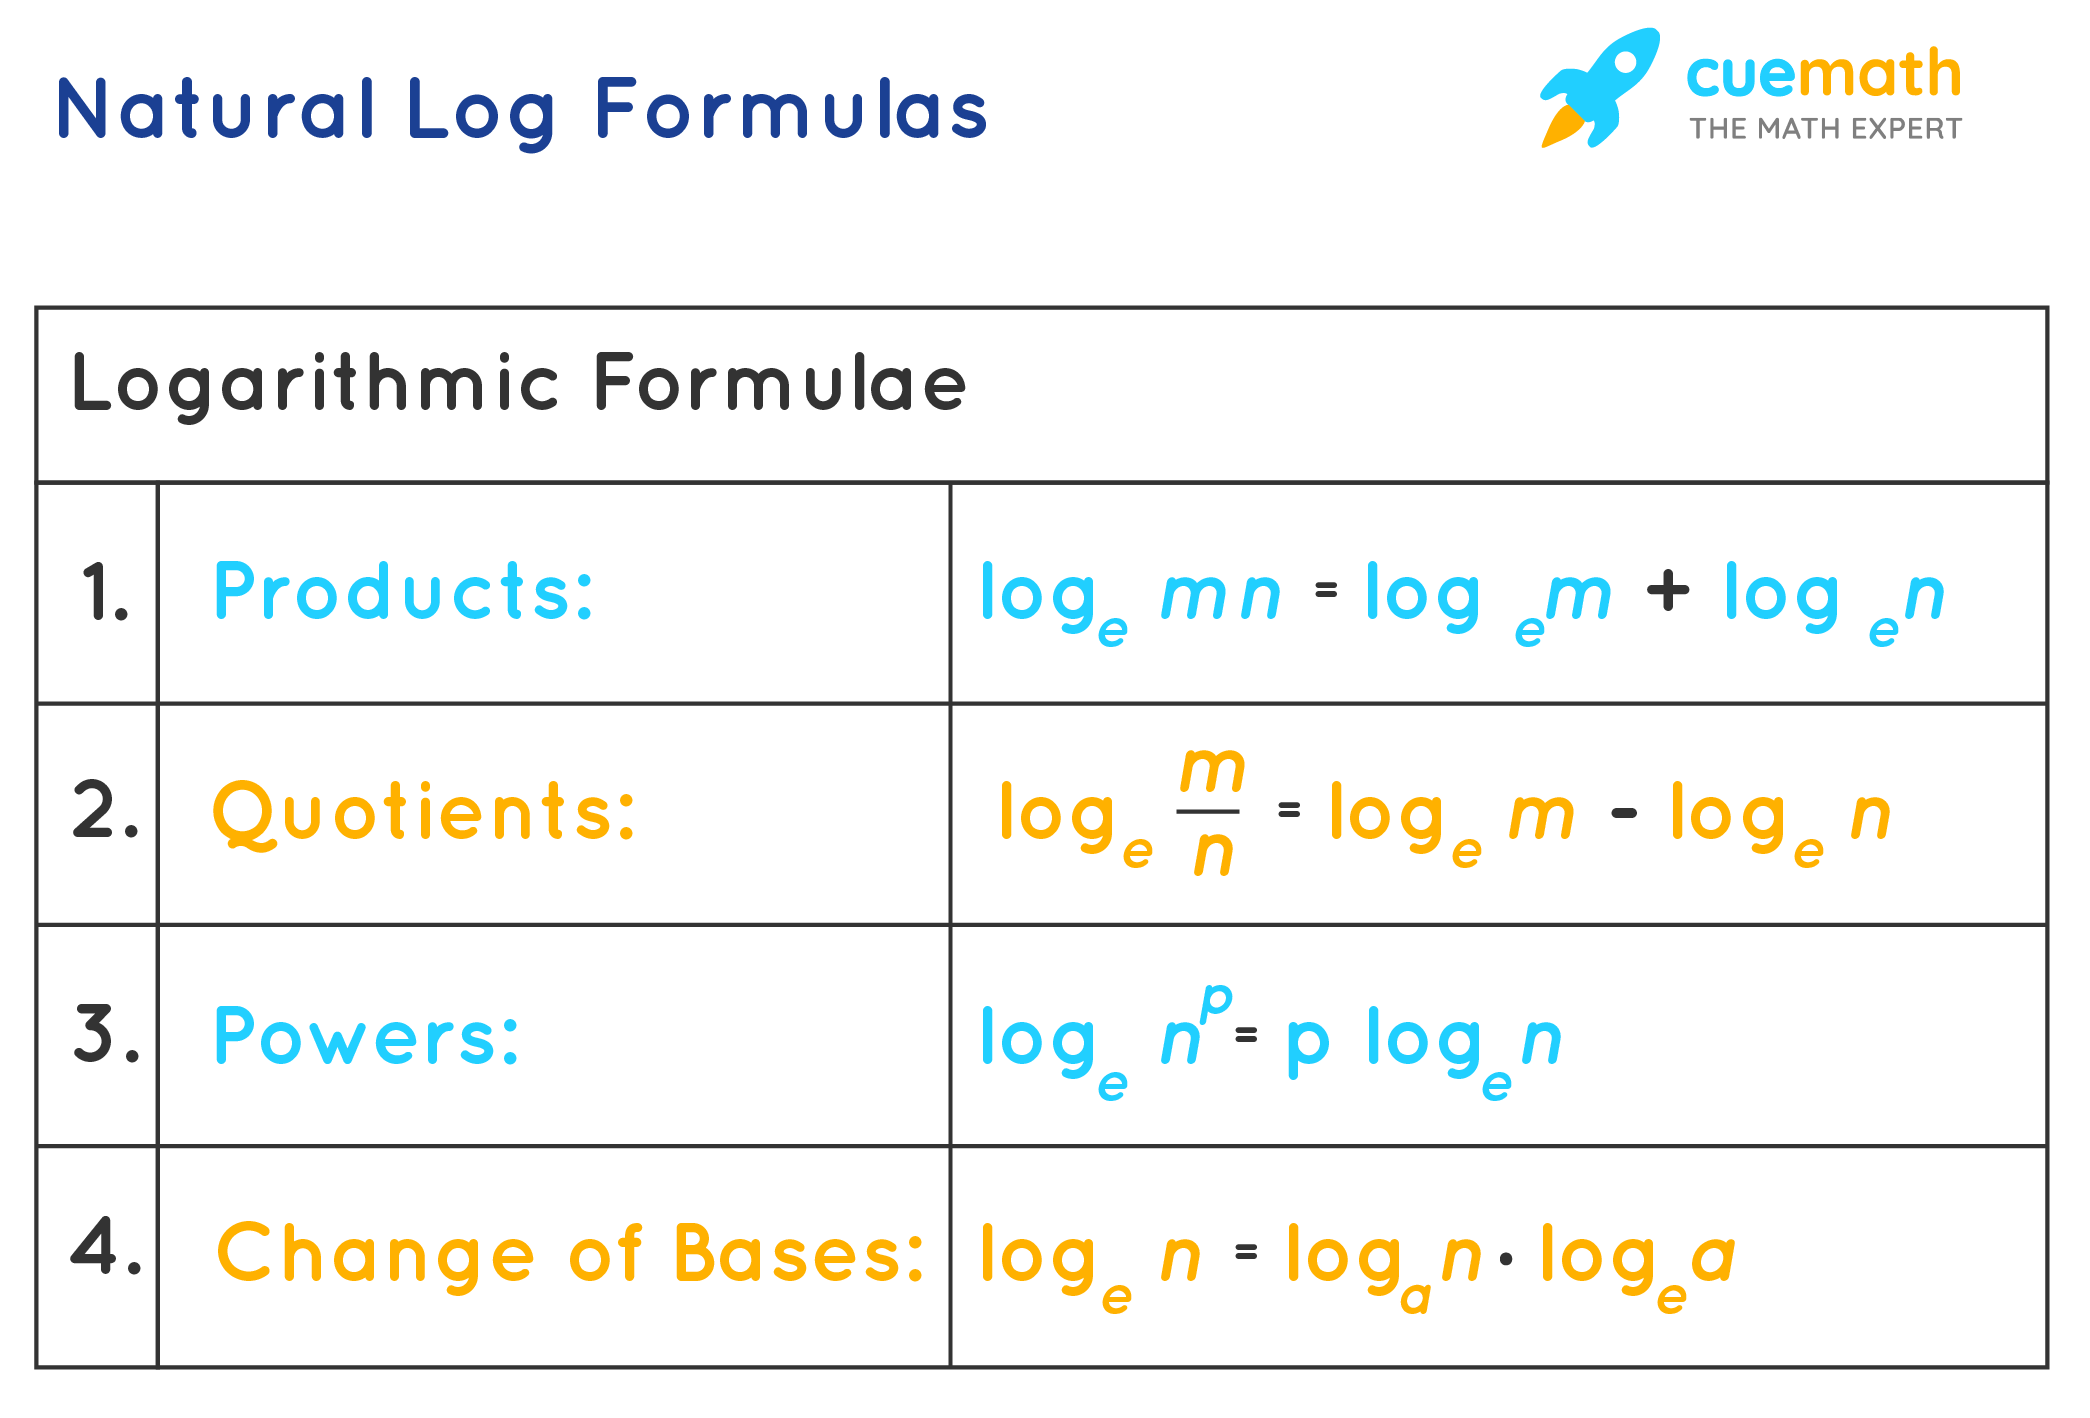
Let me walk through how this actually works in practice, because the textbook examples rarely match real situations. The key properties you need to know are: ln(ab) = ln(a) + ln(b), ln(a/b) = ln(a) - ln(b), and ln(a^b) = b*ln(a). These aren't arbitrary rules. They're direct consequences of ln being the inverse of exponential growth. Here's a practical example. You're looking at a population that grows continuously at 5% per year. You want to know when it doubles. The equation is e^(0.05t) = 2. Take ln of both sides: 0.05t = ln(2). Therefore t = ln(2)/0.05. That's about 13.86 years. No need for a calculator app if you know ln(2) 0.693.
This same pattern appears in radioactive decay, capacitor discharge, pharmacokinetics, and finance. The structure is always: exponential relationship, solve for the variable in the exponent, apply ln to both sides.
Get the Full Details

Where it gets tricky
I ran into a specific edge case last year while modeling a cooling curve for a batch process. I had data that followed a ln(t) relationship rather than an exponential one. My instinct was to force an exponential fit, which gave a terrible R-squared. The workaround was recognizing that ln(t) linearizes when you're dealing with log-normal distributions in time-to-failure analysis. I plotted the data against ln(time) on the x-axis and got a clean straight line. That single transformation made the whole model usable. Another common mistake: people forget that ln is only defined for positive real numbers. ln(0) is undefined. ln of a negative number brings you into complex analysis territory, which is fine if you're doing signal processing, but it's not going to help you solve a basic algebra problem. I've seen students divide by ln(negative number) and get confused when their answer doesn't make sense. Check your domain before you calculate. There's also the approximation trap. For values close to 1, ln(x) x - 1. This is the first-order Taylor approximation and it's useful for quick mental math. ln(1.05) is roughly 0.05. The error at 0.05 is about 0.0013, so it's pretty accurate for small values. But if you use it for ln(2), you get 1 instead of 0.693. That's a massive error. Know when the approximation breaks down.
How calculators and code handle it
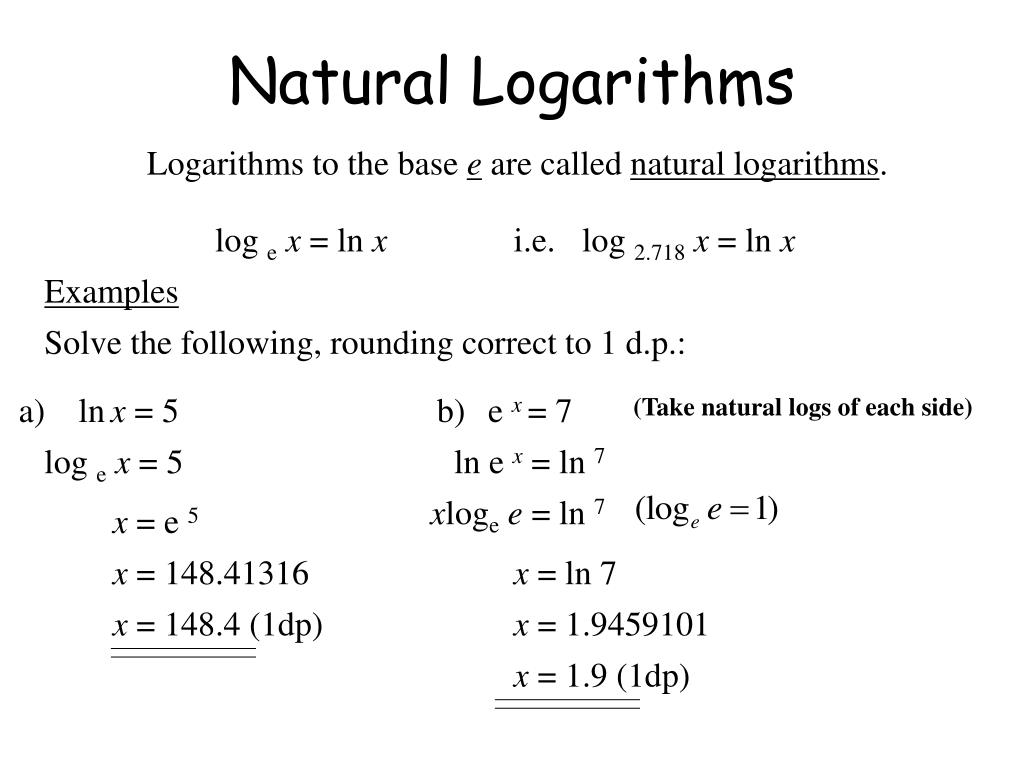
Most programming languages give you ln through a function called log(). This is confusing because in mathematics log without a base usually means log base 10. In Python, math.log() is the natural logarithm. math.log10() is base 10. In Excel, =LN() is natural log and =LOG() without a second argument is also natural log, but =LOG(number, base) lets you specify the base. This inconsistency has cost me more debugging time than I care to admit. If you're implementing ln yourself, the standard approach is the CORDIC algorithm or a polynomial approximation like the one used in glibc's libm. For most practical purposes, you don't need to know the implementation details. You just need to trust that the result is accurate to about 15 decimal places on a modern machine. One thing that catches people out: ln(e) = 1 exactly. ln(1) = 0 exactly. These are the anchor points. If your calculation gives you anything close to these for e and 1, something is wrong with your input or your function call.
Common pitfalls and what to do instead
Don't confuse ln(x^2) with 2*ln(x). They're not always the same. ln(x^2) is defined for negative x, but 2*ln(x) is not, because ln(x) requires x > 0. The correct identity is ln(x^2) = 2*ln|x|. This matters when you're simplifying expressions for integration or solving equations. Miss the absolute value and you lose half your solutions. Another issue: change of base. If you need log base 2 and your calculator only does natural log or base 10, the conversion is log_b(x) = ln(x)/ln(b). This is straightforward but easy to mess up when you're doing it under time pressure. Write out the formula explicitly instead of trying to do it in your head. The biggest limitation of relying on ln for modeling is that real-world data is noisy. A clean ln transformation assumes your error structure is multiplicative, not additive. If your residuals show a pattern after log-transforming, the model isn't capturing something fundamental about the process. No amount of ln manipulation will fix that. You need to reconsider the underlying mechanism.
Quick reference for the values you'll actually use
ln(1) = 0. ln(2) 0.693. ln(e) = 1. ln(10) 2.303. ln(0.5) -0.693. ln(100) 4.605. These come up constantly. Memorizing them saves time. Everything else you can derive from these five numbers using the product and quotient rules. That's basically how you work with ln. It's not magic. It's just the inverse of continuous growth, and once you see it that way, all the formulas fall into place.