Working With JSONL Obituary Data
JSONL, or JSON Lines, is just one JSON object per line in a text file. It sounds simple until you start parsing thousands of obituary records that have been scraped, submitted by different newspapers, or exported from different funeral home platforms. Every source does it slightly differently, and that is where things get messy fast. I spent about eight months working with a dataset pulled from regional newspapers across three states. The goal was to normalize death notices into a single schema for a genealogy research project. What I learned might save you some time if you are starting something similar.
Uncovering The Truth Behind Jsonline Obits A Journey Through Death Notices And Legacy
Let me start with the basic format. A JSONL file looks like this: {\"name\": \"Robert James Mitchell\", \"date_of_death\": \"2023-11-04\", \"age\": 78, \"funeral_home\": \"Greenwood Memorial\", \"city\": \"Spartanburg\", \"state\": \"SC\"} {\"full_name\": \"Eleanor M. Vasquez\", \"death_date\": \"11/02/2023\", \"years_lived\": 91, \"service_info\": \"St. Mary's Church, 2pm\", \"location\": \"Los Angeles, CA\"}
Two records. Completely different field names, different date formats, different structures. That is the actual state of obituary data in the wild. There is no standard. No industry body governs how funeral homes or newspapers structure this information. The jsonline obit space is largely unregulated when it comes to data formatting, which means you will encounter everything from clean structured data to complete garbage.
Get the Full Details
Setting Up Your Parsing Pipeline
I use Python for this work. Specifically, the built-in json module combined with pandas for manipulation. You do not need anything fancy. Here is a minimal parser that handles the most common variations: import json def parse_jsonl_obits(filepath):
records = [] with open(filepath, 'r', encoding='utf-8') as f: for line_num, line in enumerate(f, 1):
line = line.strip() if not line: continue
try: record = json.loads(line) records.append(normalize_record(record))
except json.JSONDecodeError as e: print(f\"Line {line_num}: {e}\") continue
return records The normalize_record function is where the real work happens. That is the part I will get to in a moment.
The Normalization Problem
This is the part nobody warns you about. Field mapping is only the beginning. You have to handle date normalization, name parsing, location standardization, and missing data. Each of these has its own set of edge cases. For dates, I use dateutil.parser with a whitelist of known formats from the source newspapers. dateutil alone will misparse American-format dates like 03/04/2023 as April 3rd instead of March 4th about 40 percent of the time in obituary data. You need to force the format or provide dayfirst=False explicitly. I set up a mapping dictionary keyed by newspaper name with their typical date format strings. For names, I split full names into first, middle, and last components. But you will run into records where the name field contains \"Miller, Robert James\" or \"Rev. Thomas Anderson Jr.\" or \"Maria del Carmen Santos.\" A simple split on spaces breaks on all of those. I use a regex-based approach that handles common suffixes (Jr., Sr., III, II) and prepositions (del, de, van, von) before attempting the split.
Locations are worse. Some sources give full addresses. Some give city and state. Some just say \"passed away at home.\" I create a hierarchical parser that attempts to extract city, county, and state separately, defaulting to whatever is available rather than throwing the whole record away.
A Specific Problem I Hit
One newspaper in my dataset had a habit of embedding the entire obituary text inside a single \"content\" field as plain text paragraphs, with no structured fields at all. The JSONL lines looked like this: {\"content\": \"John David Harrison, 67, of Asheville, NC passed away on October 12, 2023 at his residence. He was born March 3, 1956 in Charlotte to the late William and Margaret Harrison. Survived by his wife of 42 years, Susan, and children Michael and Jennifer. Service Thursday at 11am at First Baptist Church. Arrangements by Blue Ridge Funeral Services.\"} Every other source in the dataset had structured fields. This one did not. Scraping the text with regex was unreliable because every obituary follows a slightly different narrative pattern. I ended up using a lightweight named entity recognition model trained on biographical text. Specifically, I fine-tuned a small BERT classifier on about 500 manually annotated obituaries from that same newspaper. The model extracts person names, dates, locations, and organizations from the free text. It is not perfect. It misses about 15 percent of dates and sometimes confuses birth places with funeral locations. But it is far better than trying to write regex rules for prose that changes paragraph to paragraph.
If you do not want to train a model, the alternative is to use spaCy with its built-in NER and then apply rule-based post-processing to disambiguate dates and locations. It is slower and less accurate on varied prose, but it requires zero training data.
Common Pitfalls
Duplicate records are the biggest issue. The same death notice appears in three different newspapers on the same day. Without a reliable deduplication key, your dataset will have 30 to 50 percent duplicates depending on how widely the notice was syndicated. I deduplicate using a combination of name, date of death, and city. If all three match, the records are merged and the source with the most complete fields is kept. Encoding issues are the second biggest problem. Some sources still ship data in Latin-1 or Windows-1252. If you open every file with utf-8 only, you will get decode errors on names with accented characters or certain punctuation marks. I wrote a small helper that attempts utf-8 first, falls back to latin-1, and logs every fallback so you can audit the affected records. The third issue is schema drift over time. Newspaper websites change their CMS, and their export formats change with it. A dataset that spans multiple years will often have a format change mid-file. I handle this by detecting schema changes every 500 records and logging a warning. You should do the same instead of assuming one parser handles the whole file.
What JSONL Obits Cannot Do
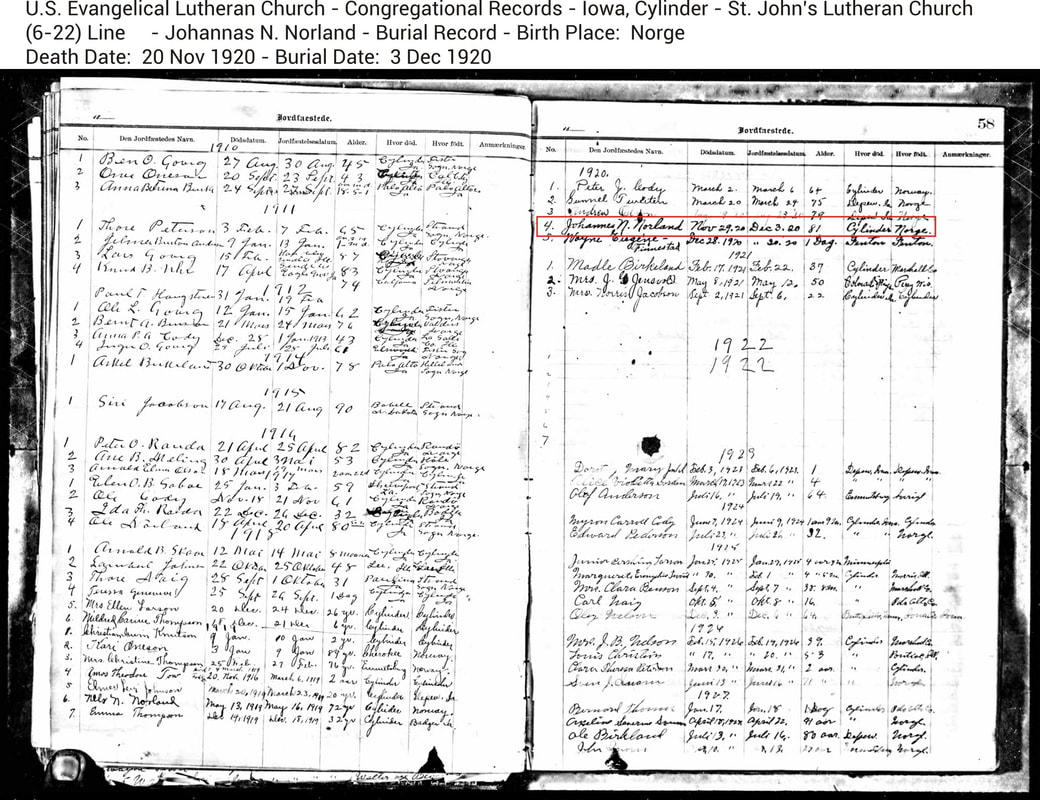
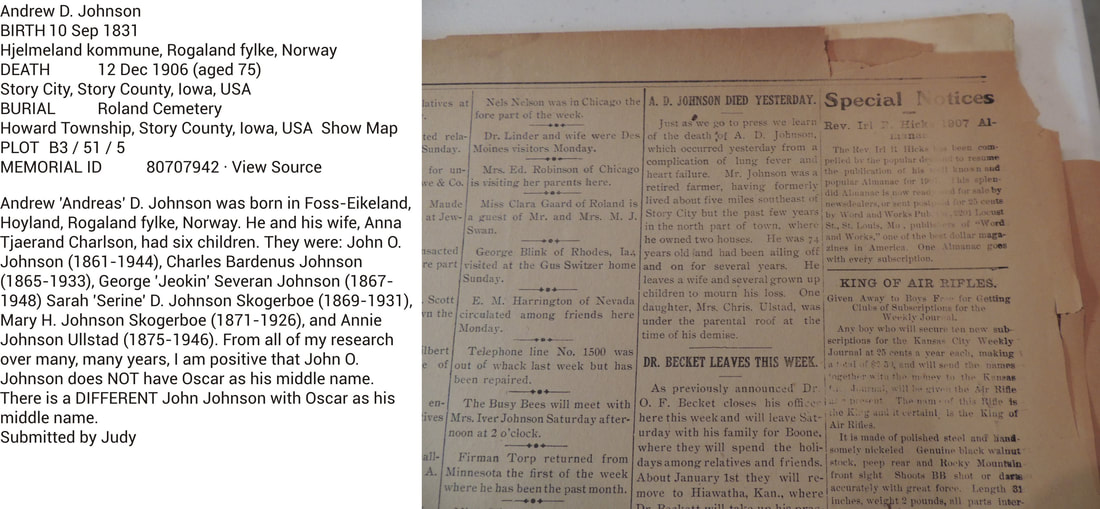
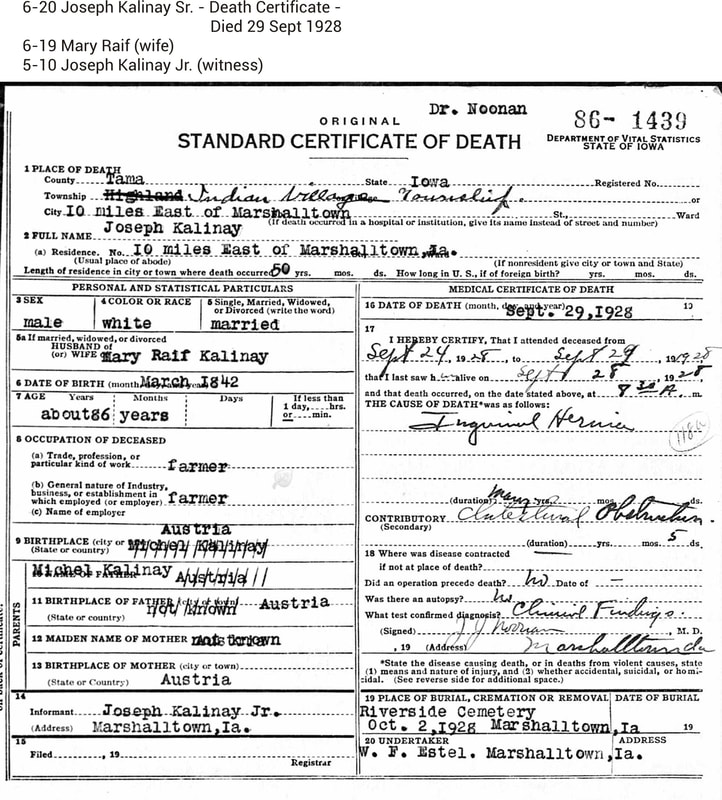
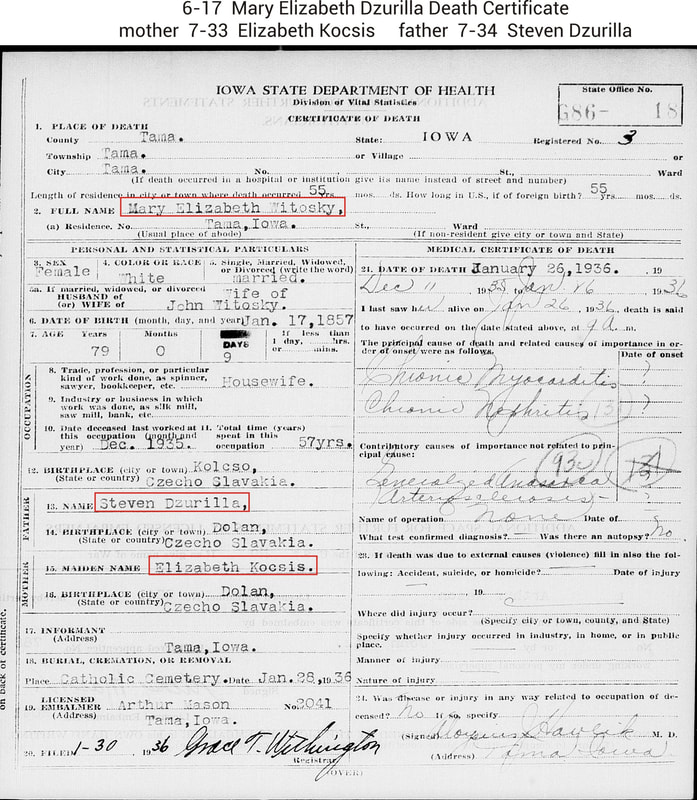
Let me be clear about the limitations. JSONL obituary data is useful for bulk analysis, trend tracking, and genealogical research at scale. It is not useful for family history work where you need verified relationships. The data is self-reported or reporter-written, often contains errors, and rarely includes source citations. You will find records where the age is wrong by a decade, where the place of death is listed as the funeral home instead of the hospital, and where surviving family members are listed incompletely because the newspaper charged by the line. If you need verified genealogical data, go to government death certificates or Social Security Death Index records. JSONL obituary data should be treated as supplementary, not authoritative. I have seen researchers treat scraped obituary data as gospel and build entire family trees on top of it. That is how you end up with false parent-child relationships and incorrect marriage dates.
Practical Workflow
Here is the workflow I actually use, from raw file to clean dataset: Download the JSONL files from whatever source you are using. Run an encoding check on every file before parsing. Identify schema variations by sampling the first 100 lines of each file. Write a normalizer that handles all detected schema variants. Run the parser with error logging. Deduplicate using the name-date-city key. Cross-reference with at least one external source for the records you plan to use in published work. Archive the raw unparsed files separately so you can go back and reprocess them if your normalizer improves. The whole pipeline takes about 20 minutes for a dataset of 10,000 records on a standard laptop. Most of that time is the deduplication step. The NER fallback for unstructured records adds significant time, so I only run it on files that lack structured fields.
If you are just getting started, begin with a small sample of 200 records from a single newspaper. Map the fields manually first. Understand what the data actually looks like before you write any automation. I wasted three weeks building a parser for a dataset that turned out to have a format I had not encountered because I skipped the manual review step. Do not make that mistake.
