Comparing PDFs isn't as simple as you'd think
Most people open two PDFs side by side and start scanning for differences. That works fine if the files are short and the changes are obvious. It breaks down completely when you're dealing with a 200-page contract where someone changed one clause on page 147 and re-exported it with slightly different metadata. You'll spend hours going through that and you'll probably miss it anyway. The reason is basic but not obvious to everyone: PDFs are not structured documents the way Word files are. They're more like instructions for rendering a page. Every character has a position, a font, a size, and a transform matrix. Two PDFs can look identical on screen but contain completely different internal object streams. Or they can look slightly different because of a rounding error in how the text was repositioned during export, even though nothing meaningful changed.
Uncovering The Secrets Of Compare Two PDFs A Comprehensive Guide
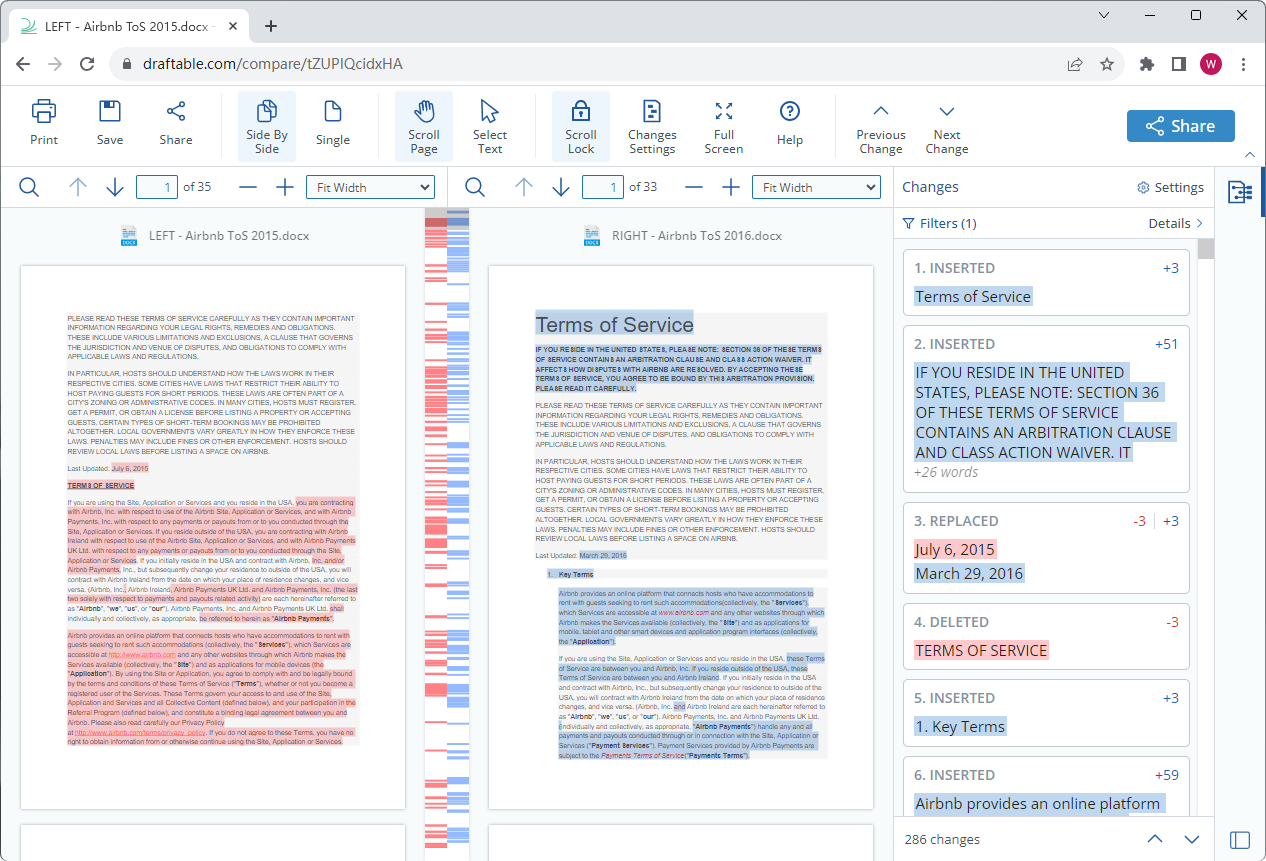
Here's what the actual process looks like when you do it properly. You start by understanding which layer you need to compare. There are three distinct layers in any PDF, and they rarely align in useful ways. Layer one is the raw bytes and object stream. This is the actual data inside the PDF file. Every object, every cross-reference table entry, every encoded stream gets hashed or compared token by token. This catches structural changes that are invisible on screen, like modified author metadata, changed page dimensions, or reorganized object IDs. Tools like pdftk or diffpdf work at this level. The problem is that PDFs are notoriously non-deterministic. Two PDFs generated from the same source by the same software at the same time will often have different internal structures because object IDs shift, timestamps change, and the compression algorithm may encode things slightly differently. Byte-level comparison produces a lot of false positives here. Layer two is the rendered page content. This is what you actually see. Text positions, images, vector graphics, color values, font substitutions. A visual diff compares pages pixel by pixel or vector by vector. This is where most professional comparison tools operate. Adobe Acrobat's built-in compare feature, as well as alternatives like PDFxChange and PDF Inspector, render both documents and highlight differences in color-coded overlays. The advantage is that what you see is what actually matters to a human reader. The disadvantage is that pixel-level diffs are noisy. Anti-aliasing differences, font rasterization variations between operating systems, and even slight JPEG recompression can make two semantically identical pages look different in a visual comparison.
Layer three is the logical content structure. This is the text extraction and semantic comparison layer. You pull the text out of both PDFs and run a diff algorithm like unified diff or LCS (Longest Common Subsequence). This catches actual content changes but completely ignores layout, images, and formatting. For legal documents this is usually what you actually want, but it fails on anything that relies heavily on tables, columns, or mixed media layouts because the text extraction order depends on how the PDF was constructed, not on how a human would read it. The right approach depends entirely on what you're comparing. If you're checking version control on a technical manual, you want layer three plus layer two combined. If you're auditing a contract for tampering, layer one is essential because someone could have removed a clause and restructured the document to preserve the word count and page layout while changing the actual text positions just enough to bypass a naive visual diff. I ran into this exact problem about two years ago when I was reviewing supplier agreements for a procurement project. Someone had taken an original PDF and replaced it with a nearly identical version. The visual diff tool showed almost nothing because the changes were buried inside table cells that had been reformatted with slightly different spacing and a different implicit line-break algorithm. The rendered page looked the same at a glance. But when I extracted the raw text and ran a character-level comparison on the CSV-style data inside the tables, I found three line items where the unit prices had been shifted by decimal places. The visual diff missed it because the table rendering engine normalized the whitespace differently in the two versions. The workaround was to convert both PDFs to plain text with a fixed-width monospace extraction, then run a custom diff script that flagged any numeric field changes regardless of surrounding layout shifts. That took about ten minutes once I had the script ready, versus the several hours it would have taken to do that manually.
Get the Full Details
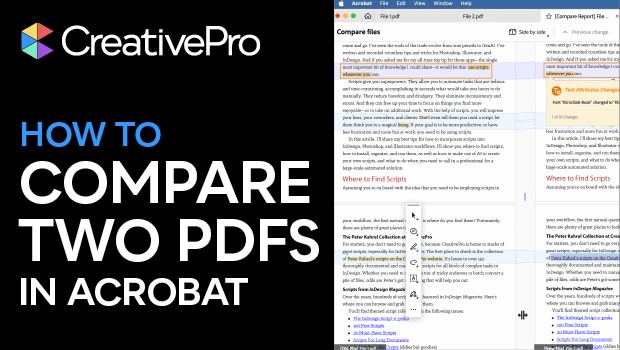
For most people doing this on their own, here's the practical stack. Start with a dedicated PDF comparison tool rather than trying to do this by hand. Adobe Acrobat Pro has a compare files feature that combines visual and content diffs. It's not free but it's the industry standard for a reason. If you're on a budget, diffpdf is a solid open-source option that works at the structural level and produces clean side-by-side outputs. For programmatic workflows, the Python library pdfplumber paired with difflib gives you enough control to build a custom comparison pipeline, though it requires actual coding knowledge. There are important limitations you should know about before you trust any tool blindly. Visual PDF comparison tools struggle with scanned documents. If your PDF is an image rather than real text, the diff engine is comparing pixels, not content. Two scans of the same page from different printers or at different resolutions will show hundreds of false difference markers. In that case you need OCR first, run the text extraction, then compare the OCR output. That adds a step and introduces its own errors, especially with low-quality scans or documents that contain handwritten notes. Another common failure mode is form fields and annotations. Many PDFs contain interactive elements like fillable fields, signatures, highlight annotations, or comments. A standard comparison will often treat these as part of the document content and flag them as differences even when the underlying page text hasn't changed. You need a tool that can isolate and ignore annotation layers, or you'll spend time investigating false alarms created by someone highlighting a sentence in blue instead of actually editing it.
Compression is another quiet source of problems. PDFs use FlateDecode, JPEG, and other compression methods internally. When a tool re-saves or re-renders a PDF, the compressed streams may look completely different in a byte-level comparison even though the decompressed output is identical. Always verify that your comparison tool decompresses before comparing, not just reads the raw compressed stream. For security-critical comparisons where you need to prove a document hasn't been altered, layer one analysis is insufficient on its own because the object stream can be reconstructed without changing any visible content. The only reliable check there is to verify the digital signature, if one exists. An altered PDF with a valid digital signature is either impossible or immediately detectable depending on what portion was modified. If the document lacks a digital signature and you need forensic-grade confidence, you're looking at a much more expensive process involving expert review and possibly litigation support tools, not a software download. Here's a quick workflow that covers most real-world cases without overcomplicating things. Export both PDFs from their source applications so they're in a neutral, stable format. Run a text extraction diff first using a tool like pdftotext piped into diff. This catches the obvious content changes in about thirty seconds for a typical document. Then run the visual comparison in your chosen tool to catch layout shifts, missing images, or formatting changes that text extraction misses. Cross-reference the results. If the text diff shows changes but the visual diff doesn't, the changes might be in metadata or invisible formatting. If the visual diff shows differences but the text diff doesn't, you're probably looking at image replacements or font substitutions. Handle each category separately rather than letting one tool's output dominate your analysis.
File size matters more than people expect. A 500-page PDF with embedded fonts and high-resolution images can take minutes to render in a comparison tool. Some tools will simply time out or produce incomplete results on very large files. If you're working with massive documents, consider splitting them into logical sections first, comparing each section individually, then correlating the results. This is faster than waiting for a single monolithic comparison to finish and easier to track down where specific differences live. The bottom line is that comparing PDFs well requires understanding which layer of the document you're actually concerned with. Most tools default to visual comparison because it's the easiest to implement and the most intuitive to interpret. That's also why they miss the things that matter most in professional settings. Taking the time to run both a structural and a content-level comparison on important documents will catch issues that a single-pass visual diff simply cannot see.