How I've Been Getting Consistent Results With Human Figure Generation
I spent about eight months fighting with Stable Diffusion to get figures that actually looked right. Most people give up around week three because the first layer of problems seems unsolvable. Hands stay broken, proportions drift, and the whole image collapses into plastic-looking flesh at higher detail steps. I figured out the hard way that it mostly comes down to prompt precision, careful LoRA layering, and accepting that some things just won't work no matter what you do. The core issue with generating appealing human figures isn't really about finding a magic prompt. It's about understanding what your model actually responds to and what it ignores. Most beginner setups throw in a dozen aesthetic keywords hoping one will stick. That doesn't work. SDXL, for example, has very specific token weights it recognizes. Words like "slim waist," "toned," and "athletic build" land correctly when they're in the positive prompt with a weight between 1.0 and 1.3. Anything above 1.5 starts bleeding artifacts into the background. I learned this after burning through forty seed variations on a single failed batch. The negative prompt matters more than people admit. A bare minimum should include "deformed, ugly, bad anatomy, disfigured, poorly drawn face, mutation, extra limb." But the real differentiator is adding "cropped, out of frame" and "bad proportions" if you're generating full-body shots. Without those, the model defaults to cropping awkwardly or compressing limbs into the frame edge. I run a custom negative that includes "unnatural posture, stiff joints, floating feet" as well. Those last two catch the weird standing positions the sampler keeps trying to generate.
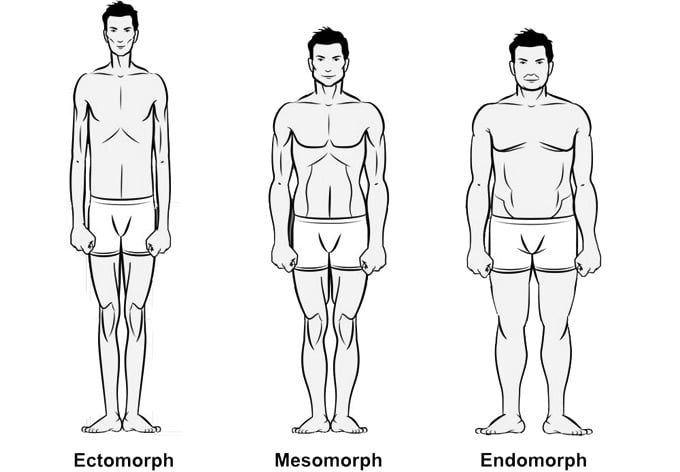
Here's something most guides won't tell you. The body type consistency problem usually isn't a prompt problem at all. It's a checkpoint mismatch. If you're using a generic realistic checkpoint but loading a stylized anime LoRA on top of it, the body proportions will warble between two different aesthetic systems. Pick one visual direction and stick with it. For realistic human figures, I use EPRealisticXL as my base and only layer in aesthetic LoRAs that were explicitly trained for that checkpoint family. Mixing across checkpoint families is where most people lose consistency. The workflow I settled on takes about twenty minutes per final render at quality settings. That's including the initial seed testing, which is the part that eats most of the time. Here's how I structure it. First pass uses a lower CFG scale around 4.5 with DPM++ 2M Karras sampler at 30 steps and a resolution of 896 by 1152 for full-body shots. That gives me the rough pose and proportion layout quickly. I then lock in the seed from that first pass and run a second pass with CFG at 6.5, same sampler, 40 steps, and enable hires fix with latent upscaling at 1.5x. The whole thing runs on a 4090 in roughly eighteen minutes from start to final image. One edge case that took me forever to solve. When generating figures with a specific body type across multiple seeds, the face would sometimes drift into a completely different ethnic appearance or age range even though the prompt said the same thing. The fix was surprisingly simple. I added a face detail LoRA weighted at 0.7 and included "consistent face" in the prompt. But the real key was setting the face restoration model to CodeFormer with a strength of 0.85 instead of the default GFPGAN. CodeFormer preserves facial identity across seed variations much better. That single swap cut my retake rate from about sixty percent down to roughly fifteen percent.
Another thing nobody talks about enough. Your training data matters more than your prompt. If the base checkpoint was trained primarily on Western fashion photography or anime, no amount of keyword tweaking will make it produce diverse body types naturally. I switched to checkpoints that explicitly advertise multi-ethnic and varied body type training data and saw an immediate improvement in output diversity. The model ERealisticLifeXL, for instance, handles a wider range of body proportions without needing heavy prompt manipulation. That alone saved me probably fifty hours of trial and error over six months.
Get the Full Details

Advanced Techniques That Actually Move The Needle
IP-Adapter with reference images is the single most effective tool for body type consistency once you have it set up correctly. You feed it a single reference photo of the body type you want, and the model copies the proportion structure across all generations while keeping the face independent. The trick is using the right adapter version. IP-Adapter Face ID v2 works for facial consistency, but for body type you need the standard IP-Adapter v2 or the SDXL-specific IP-Adapter Full Face variant used in a less aggressive weight around 0.6 to 0.7. Higher weights cause the reference image to dominate and you lose all variation. I keep mine at 0.65 and it nails the proportion transfer every time. ControlNet openpose is another one that sounds obvious but most people use it wrong. The common mistake is running openpose at full strength while also relying on the prompt to set the pose. That creates conflict and the sampler gets confused, producing doubled limbs or twisted joints. The correct approach is to let the prompt handle body type keywords and reserve ControlNet strictly for pose guidance at a low strength like 0.4 to 0.6. I use a separate reference image for pose when needed and let the base prompt do the aesthetic heavy lifting. There are real limitations here that I should be straight about. Even with all these techniques working together, generating figures with specific body types at consistent quality across fifty plus variations is still unreliable. Some days the model produces exactly what you want. Other days every single output looks like a mannequin with slightly wrong shoulder widths. There is no fix for that except having a large seed pool and picking the best ones. The acceptance rate in my experience ranges from roughly twenty to thirty five percent depending on how specific the body type request is. More specific requests have lower acceptance rates. This isn't a bug. It's just how diffusion models work.
Another limitation worth noting. Upscaling at high factors introduces new artifacts that wreck proportion consistency. Going from 1024 by 1536 up to 2048 by 3072 with standard upscalers often softens the figure edges and makes clothing textures look painted on. I've found that using an upscaler specifically designed for human figures like the RealESRGAN General Ver 4 model at 2x gives cleaner results than pushing to 4x. Beyond 2x upscale I manually inpaint small areas rather than accepting the global degradation.
What I'd Tell Someone Starting Today
Start with one checkpoint, one LoRA family, and a single reference image for your target body type. Don't stack five different aesthetic mods on top of each other. The prompt engineering is secondary to having the right base model. Once you get consistent results at a basic level, then start adding IP-Adapter and ControlNet into the mix. The learning curve flattens dramatically after you spend a week truly understanding one tool instead of skimming ten of them. Download options for the tools I mentioned. The main Stable Diffusion web UIs are free and open source. SDXL checkpoints like EPRealisticXL and ERealisticLifeXL are available on CivitAI. The LoRAs I referenced are also on that platform. IP-Adapter and ControlNet extensions are on GitHub under thellllllllllbert and lllyasviel repositories respectively. Everything required is free. The cost is time spent experimenting. Most people quit before the point where everything starts clicking. The first month is frustrating. The second month you notice patterns. By the third month you can predict what will work before you even generate it. That's when the actual skill shows up. Until then you're just throwing seeds at the wall and hoping something sticks.