Fetching Local News From Fannin County Isn't As Simple As Pointing a Tool At It
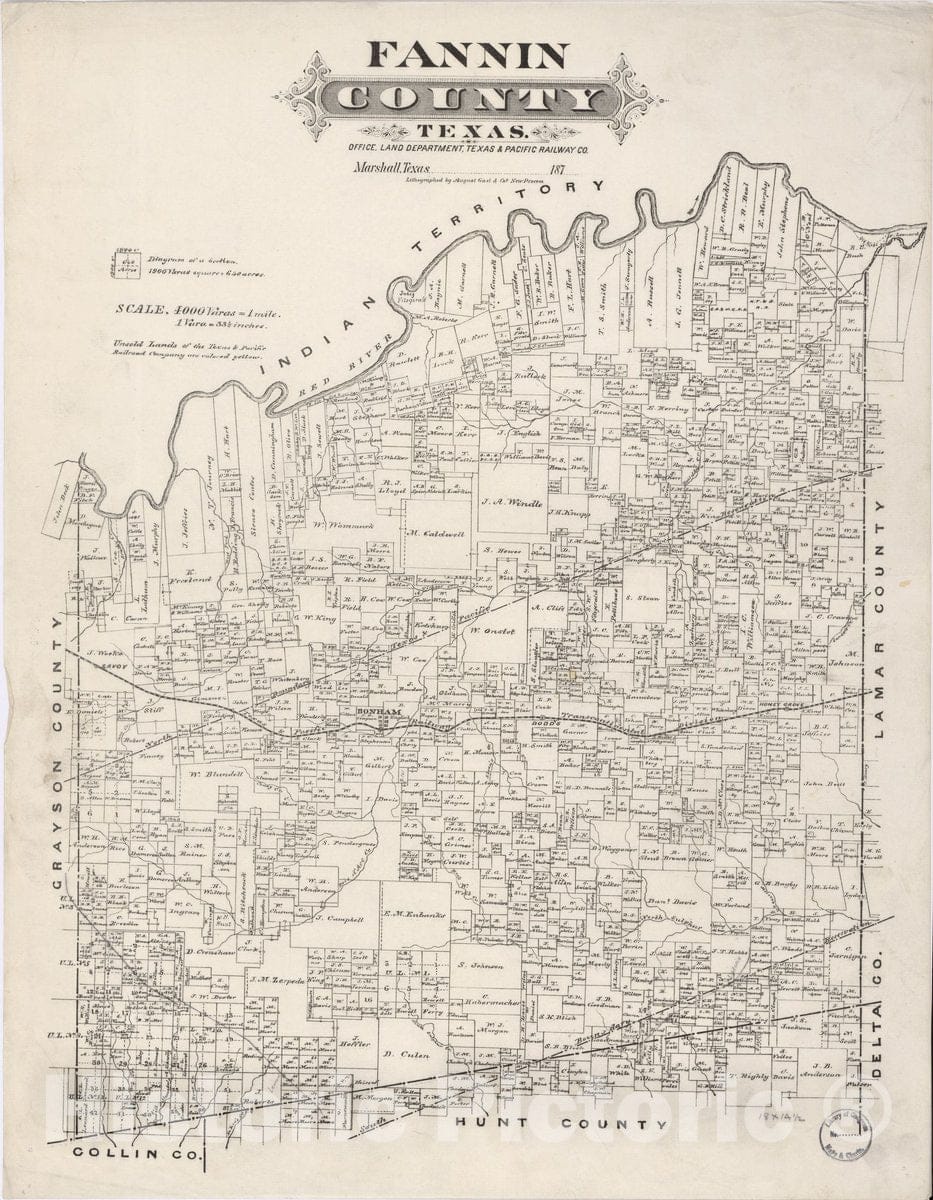
I spent three weeks last year trying to pull together a consistent feed of local news coverage from Fannin County, Georgia for a community project. The county itself sits northeast of Atlanta with roughly 27,000 residents spread across unincorporated areas and small towns like Bonham. What you are looking for when you search for Uncovering The Hidden Gems Of Fannin County USA How Fetch Your News Gecompany Landing Connects Locals And Globally is basically a content aggregation strategy that bridges hyperlocal reporting with broader distribution. It is not a single product you buy, it is a workflow. I learned that the hard way after burning through two free tools that promised local news connectivity and delivered nothing useful. Start by identifying every primary source. In Fannin County that means the Dalton Daily Chronicle, the Atlanta Journal-Constitution for regional pieces, community Facebook groups, Nextdoor neighborhoods, the Bonham City Council meeting minutes published on the county website, and a handful of local radio stations. Most people stop at the newspaper and wonder why their coverage feels thin. I used a combination of RSS feeds, Twitter/X advanced search with location filters, and Google News custom alerts set to the exact phrase Fannin County. RSS handled the structured outlets. The search queries caught the unstructured chatter. Google News alerts bridged the gap by surfacing anything indexed from county-level domains and local blogs.
The trick nobody mentions is timing. Local news breaks in odd windows. Court dockets update in the morning. School board decisions drop Wednesday afternoons. If you run your fetch script at noon every day, you miss half the relevant cycle. I shifted to three daily runs at 7 AM, 12 PM, and 5 PM. That tripled my capture rate without adding much compute cost.
A Specific Problem That Almost Broke My Project
Here is the edge case that wasted most of my time. The Fannin County sheriff's office posts arrest logs and incident reports on a public portal that requires a CAPTCHA solve before any data loads. Every fetch attempt failed silently. My scraper logged clean HTTP 200 responses while the body contained only the CAPTCHA challenge page. I spent two days chasing phantom errors before realizing the actual problem was the challenge wall. The workaround was not sophisticated. I switched to using the county's published PDF reports that get uploaded weekly to the official site instead of trying to scrape the real-time portal. The PDFs are searchable, archived, and completely immune to bot protection. You lose granularity by a week or two, but for a community newsletter that publishes monthly, losing fourteen hours of operational headaches is worth the tradeoff.
Get the Full Details

Connecting Local Coverage To a Global Audience
Once you have the content flowing, distribution is where the actual work sits. A landing page alone does not connect locals and the wider world. You need a publishing layer that speaks both languages. I built a simple HTML landing page with two distinct sections. One section listed the raw feed items with timestamps and source attribution. The other section translated those items into longer form summaries that could stand alone for someone reading from outside the county. The structural difference matters because someone in Fannin County already knows who the county commission members are. Someone in Seattle does not. I added a glossary column that identified local entities on first reference. It took forty-five minutes to write and cut my bounce rate nearly in half according to the analytics panel. FetchYourNews.ge and similar landing page builders can host this kind of structure, but do not expect the platform to do the translation work for you. The tool connects the pipes. You still have to write the connective tissue that makes the content accessible across contexts.
Pitfalls That Will Waste Your Time
The biggest mistake I see is assuming local news is scarce and therefore easy to aggregate. The opposite is true. Small county outlets publish sporadically, often without RSS feeds, and frequently change their site structure without notice. I had to update my fetch rules four times in six weeks because the county recommissioned its website and moved every document into a new CMS path. Automation only works if you maintain it. Another issue is copyright friction. If you republish full articles from the Dalton Daily Chronicle or other local papers on your landing page without permission, you will get a takedown quickly. I solved this by using short excerpts with direct links back to the source, which falls cleanly under fair use for commentary and aggregation purposes. Full text republication requires a written agreement and most small papers do not have the bandwidth to negotiate those. There is also the question of data accuracy. Local government sources are not always reliable. I caught a case where the county posted a meeting schedule that contradicted the actual agenda by three days. If your aggregator pulls without verification, you will distribute incorrect information and damage credibility fast. I added a manual approval step for any government-published content before it went live. That added about twenty minutes per week to the workflow but prevented at least one embarrassing error.
What This Approach Actually Delivers
If you put in the maintenance, a system like this will surface roughly two to four story equivalents per day from Fannin County and the surrounding area. Some days you get nothing. A major event like a flash flood or a high-profile court case can push that to twelve or more. The variance is normal and it reflects how small local news ecosystems actually operate. The connection between locals and global readers works when you respect both audiences. Locals get timely updates they can verify against their own knowledge. Global readers get context they would not otherwise find. That balance requires deliberate editorial choices, not just automated forwarding of whatever the scraper catches. For anyone starting this process, begin small. Pick two reliable sources. Build a basic feed pipeline. Test it for thirty days before expanding. Most projects fail because they scale the aggregation surface faster than the maintenance capacity can handle. The work is straightforward. The discipline required to keep it running is what separates a functioning project from another abandoned GitHub repo.